
Curriculum-Based Self-Training Makes Better Few-Shot Learners for Data-to-Text Generation
Proceedings of the Thirty-First International Joint Conference on Artificial Intelligence. Main Track. Pages 4178-4184.
https://doi.org/10.24963/ijcai.2022/580
Keywords
- Natural Language Processing: Language Generation
- Natural Language Processing: Language Models
Abstract
Despite the success of text-to-text pre-trained models in various natural language generation (NLG) tasks, the generation performance is largely restricted by the number of labeled data in downstream tasks, particularly in data-to-text generation tasks. Existing works mostly utilize abundant unlabeled structured data to conduct unsupervised pre-training for task adaption, which fail to model the complex relationship between source structured data and target texts. Thus, we introduce self-training as a better few-shot learner than task-adaptive pre-training, which explicitly captures this relationship via pseudo-labeled data generated by the pre-trained model. To alleviate the side-effect of low-quality pseudo-labeled data during self-training, we propose a novel method called Curriculum-Based Self-Training (CBST) to effectively leverage unlabeled data in a rearranged order determined by the difficulty of text generation. Experimental results show that our method can outperform fine-tuning and task-adaptive pre-training methods, and achieve state-of-the-art performance in the few-shot setting of data-to-text generation.
- [Banerjee and Lavie, 2005] Satanjeev Banerjee and Alon Lavie. METEOR: an automatic metric for MT evaluation with improved correlation with human judgments. In Sum- marization@ACL 2005, pages 65-72, 2005.
- [Bengio et al., 2009] Yoshua Bengio, Jérôme Louradour, Ronan Collobert, and Jason Weston. Curriculum learning. In ICML, volume 382, pages 41-48, 2009.
- [Chen et al., 2020a] Wenhu Chen, Yu Su, Xifeng Yan, and William Yang Wang. KGPT: knowledge-grounded pre- training for data-to-text generation. In EMNLP, 2020.
- [Chen et al., 2020b] Zhiyu Chen, Harini Eavani, Wenhu Chen, Yinyin Liu, and William Yang Wang. Few-shot NLG with pre-trained language model. In ACL, 2020.
- [Du et al., 2021] Jingfei Du, Edouard Grave, Beliz Gunel, Vishrav Chaudhary, Onur Celebi, Michael Auli, Veselin Stoyanov, and Alexis Conneau. Self-training improves pre-training for natural language understanding. In NAACL-HLT, pages 5408-5418, 2021.
- [Fleiss, 1971] J. Fleiss. Measuring nominal scale agreement among many raters. Psychological Bulletin, 1971.
- [Gehrmann et al., 2018] Sebastian Gehrmann, Falcon Z. Dai, Henry Elder, and Alexander M. Rush. End-to-end content and plan selection for data-to-text generation. In INLG, pages 46-56, 2018.
- [Gong et al., 2020] Heng Gong, Yawei Sun, Xiaocheng Feng, Bing Qin, Wei Bi, Xiaojiang Liu, and Ting Liu. Tablegpt: Few-shot table-to-text generation with table structure reconstruction and content matching. In COL- ING, pages 1978-1988, 2020.
- [Gururangan et al., 2020] Suchin Gururangan, Ana Maraso- vic, Swabha Swayamdipta, Kyle Lo, Iz Beltagy, Doug Downey, and Noah A. Smith. Don't stop pretraining: Adapt language models to domains and tasks. In ACL, pages 8342-8360, 2020.
- [He et al., 2020] Junxian He, Jiatao Gu, Jiajun Shen, and Marc'Aurelio Ranzato. Revisiting self-training for neural sequence generation. In ICLR, 2020.
- [Hoyle et al., 2021] Alexander Miserlis Hoyle, Ana Maraso- vic, and Noah A. Smith. Promoting graph awareness in linearized graph-to-text generation. In Findings of ACL/IJCNLP, pages 944-956, 2021.
- [Jia et al., 2019] Robin Jia, Aditi Raghunathan, Kerem Göksel, and Percy Liang. Certified robustness to adver- sarial word substitutions. In EMNLP-IJCNLP, 2019.
- [Jin et al., 2020] Zhijing Jin, Qipeng Guo, Xipeng Qiu, and Zheng Zhang. Genwiki: A dataset of 1.3 million content- sharing text and graphs for unsupervised graph-to-text generation. In COLING, pages 2398-2409, 2020.
- [Kale and Rastogi, 2020] Mihir Kale and Abhinav Rastogi. Text-to-text pre-training for data-to-text tasks. In INLG, pages 97-102, 2020.
- [Ke et al., 2021] Pei Ke, Haozhe Ji, Yu Ran, Xin Cui, Liwei Wang, Linfeng Song, Xiaoyan Zhu, and Minlie Huang. JointGT: Graph-text joint representation learning for text generation from knowledge graphs. In Findings of ACL- IJCNLP, pages 2526-2538, 2021.
- [Lebret et al., 2016] Rémi Lebret, David Grangier, and Michael Auli. Neural text generation from structured data with application to the biography domain. In EMNLP, pages 1203-1213, 2016.
- [Lewis et al., 2020] Mike Lewis, Yinhan Liu, Naman Goyal, Marjan Ghazvininejad, Abdelrahman Mohamed, Omer Levy, Veselin Stoyanov, and Luke Zettlemoyer. BART: denoising sequence-to-sequence pre-training for natural language generation, translation, and comprehension. In ACL, pages 7871-7880, 2020.
- [Lin, 2004] Chin-Yew Lin. Rouge: A package for automatic evaluation of summaries. In Text summarization branches out, pages 74-81, 2004.
- [Papineni et al., 2002] Kishore Papineni, Salim Roukos, Todd Ward, and Wei-Jing Zhu. Bleu: a method for au- tomatic evaluation of machine translation. In ACL, 2002.
- [Raffel et al., 2020] Colin Raffel, Noam Shazeer, Adam Roberts, Katherine Lee, Sharan Narang, Michael Matena, Yanqi Zhou, Wei Li, and Peter J. Liu. Exploring the limits of transfer learning with a unified text-to-text transformer. J. Mach. Learn. Res., 21:140:1-140:67, 2020.
- [Ribeiro et al., 2020a] Leonardo F. R. Ribeiro, Martin Schmitt, Hinrich Schütze, and Iryna Gurevych. Investi- gating pretrained language models for graph-to-text gen- eration. CoRR, abs/2007.08426, 2020.
- [Ribeiro et al., 2020b] Leonardo F. R. Ribeiro, Yue Zhang, Claire Gardent, and Iryna Gurevych. Modeling global and local node contexts for text generation from knowledge graphs. TACL, 8:589-604, 2020.
- [Scudder, 1965] H. J. Scudder. Probability of error of some adaptive pattern-recognition machines. IEEE Trans. Inf. Theory, 11(3):363-371, 1965.
- [Shimorina and Gardent, 2018] Anastasia Shimorina and Claire Gardent. Handling rare items in data-to-text generation. In INLG, pages 360-370, 2018.
- [Trisedya et al., 2018] Bayu Distiawan Trisedya, Jianzhong Qi, Rui Zhang, and Wei Wang. GTR-LSTM: A triple en- coder for sentence generation from RDF data. In ACL, pages 1627-1637, 2018.
- [Xing and Wan, 2021] Xinyu Xing and Xiaojun Wan. Structure-aware pre-training for table-to-text generation. In Findings of ACL-IJCNLP, pages 2273-2278, 2021.
References were extracted automatically from the PDF and may contain errors.
Full text extracted automatically from the PDF; figures, tables and equations may differ. The PDF is the version of record.
1 Introduction
Recently, text-to-text pre-trained models like BART [Lewis et al., 2020] and T5 [Raffel et al., 2020] have emerged in the field of natural language generation (NLG). Their main idea is to capture the relationship among texts by reconstructing original sentences with the input of corrupted sentences. These models can achieve state-of-the-art performance in various NLG tasks via fine-tuning on downstream datasets.
Despite the success of text-to-text pre-trained models, it's challenging to directly apply them to few-shot NLG tasks because their performance can be largely restricted by the number of labeled data [Chen et al., 2020a; Chen et al., 2020b]. Especially in the task of few-shot data-to-text generation, it's hard to learn the complex relationship between source structured data and target texts via limited labeled data [Gong et al., 2020]. Existing works commonly continue pre-training on large amounts of structured data without corresponding texts for task adaption, aiming to enhance the model performance [Gururangan et al., 2020]. As shown in Figure 1(a), this task-adaptive pre-training strategy appears between general pre-training and fine-tuning, whose purpose is to adapt general pre-trained models (such as BART) to specific tasks (such as data-to-text generation) using unlabeled task data [Xing and Wan, 2021]. We argue that task-adaptive pretraining only captures the relationship among structured data but fails to explicitly model the alignment between structured data and texts, thereby restricting the model performance on the few-shot data-to-text generation tasks.
∗Corresponding author
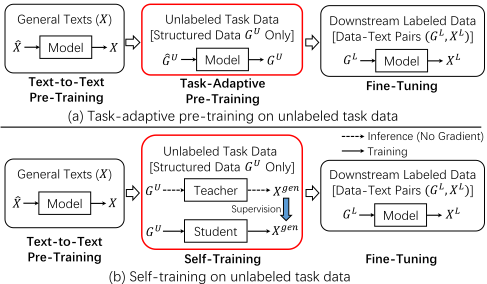
In this paper, we introduce self-training [Scudder, 1965] as a better few-shot learner for data-to-text generation. As shown in Figure 1(b), self-training is a teacher-student framework where the teacher model creates synthetic labels for the unlabeled data, and the student model is trained on the pseudo-labeled data constructed by the teacher model. Compared with task-adaptive pre-training, self-training explicitly models the relationship between structured data and texts by training the student model on the pseudo-labeled data generated by the teacher model, instead of solely conducting unsupervised pre-training on the unlabeled structured data. We argue that the main challenge falls into the quality of pseudolabeled data. Even if the teacher model is initialized with pre-trained models, it may generate low-quality texts especially when dealing with the structured data with complex topologies, which hurt the performance of the student model.
Thus, we present a novel method called Curriculum-Based Self-Training (CBST) to address the challenge. This method utilizes curriculum learning [Bengio et al., 2009] to construct pseudo-labeled data from easy cases to hard ones, and leverages such data into the training process at different iterations. Specifically, we divide the unlabeled dataset into different subsets based on some difficulty metric such as the number of input triples [Ribeiro et al., 2020b]. At each iteration, we first collect the unlabeled data that satisfy the difficulty metric of the current curriculum. Then, we generate synthetic texts for these data using the teacher model, and select the pseudo-labeled data based on the coverage and generation probability. Finally, we train the student model on the labeled data and the selected pseudo-labeled data, and make it act as the teacher model at the next iteration. This method is expected to gradually increase the difficulty of generating texts for unlabeled structured data and improve the quality of pseudo-labeled data constructed by the teacher model.
Our contributions are mainly as follows 1 :
- We introduce self-training to improve text-to-text pretraining for few-shot data-to-text generation. This method explicitly captures the relationship between structured data and texts by generating texts for unlabeled structured data with the teacher model and training the student model on the pseudo-labeled data.
- We propose a novel method called CBST to alleviate the side-effect of low-quality pseudo-labeled data, which introduces curriculum learning to effectively leverage the unlabeled structured data into the training process in the order determined by the difficulty metric.
- We conduct extensive experiments in the few-shot setting of WebNLG and WikiBio datasets. Results show that our method can outperform fine-tuning and taskadaptive pre-training methods, and achieve state-of-theart performance on these two benchmarks.
2 RelatedWork
2.1 Data-to-Text Generation
Early studies on data-to-text generation mainly focus on how to encode the structural information of input data better. Thus, researchers devise complex encoder structures based on sequential neural networks [Trisedya et al., 2018] and graph neural networks [Ribeiro et al., 2020b] to achieve this goal. Recently, since text-to-text pre-trained models have shown promising performance in various NLG tasks, some works directly fine-tune these pre-trained models including BART [Lewis et al., 2020] and T5 [Raffel et al., 2020] on data-to-text datasets and report impressive results [Ribeiro et al., 2020a; Kale and Rastogi, 2020]. Other works adapt pre-trained models to data-to-text generation tasks by designing specific pre-training tasks such as reconstructing structured data and texts, which further improve the model performance in both supervised and few-shot settings of downstream datasets [Chen et al., 2020a; Ke et al., 2021; Xing and Wan, 2021].
1 The codes are available at https://github.com/kepei1106/CBST.
Compared with existing works, we introduce self-training to explicitly capture the relationship between structured data and texts, instead of solely relying on unsupervised taskadaptive pre-training. Our method is expected to utilize unlabeled data more effectively and further improve text-to-text pre-trained models in few-shot data-to-text generation.
2.2 Self-Training
Self-training [Scudder, 1965] is a teacher-student framework to leverage unlabeled data through semi-supervised learning. Self-training has been applied to the tasks of text classification [Du et al., 2021] and generation [He et al., 2020]. With the development of pre-trained models, recent works also show that self-training is complementary to pre-training for various classification tasks [Du et al., 2021].
For comparison, our work is the first attempt to utilize selftraining to improve text-to-text pre-trained models for fewshot data-to-text generation. Moreover, we consider the difficulty of generating texts for different structured data and introduce curriculum learning [Bengio et al., 2009] to incorporate unlabeled data into the self-training process at different iterations to improve the quality of pseudo-labeled data.
3 Method
3.1 Task Definition andModel Overview
Given the text-to-text pre-trained model fθT2T , the downstream labeled dataset DL = {(GLi ,XL i )}mi=1 , and the unlabeled dataset DU = {GUi }Mi=1 where GLi / GUi denotes the structured data and XL i indicates the annotated texts (M ≫ m), our goal is to obtain a data-to-text pre-trained model which can perform well in the few-shot setting of downstream datasets.
The overview of our proposed method is shown in Figure 2. We follow the existing works to linearize the structured data as a sequence of triples containing subjects, predicates, and objects [Ribeiro et al., 2020a; Chen et al., 2020a] as shown in Figure 3. We first initialize the teacher model fθT with the pre-trained model fθT2T and train it on the labeled dataset DL. Then, we train the teacher model and the student model iteratively. At each iteration, the teacher model fθT generates synthetic texts for the unlabeled dataset D′U which contains the data satisfying the difficulty metric of the current curriculum. Then we select the pseudo-labeled dataset DPL based on the coverage and generation probability of the teacher model. The student model fθS which is also initialized with Initialization Text-to-Text PLM (𝑓𝜃2 )

Initialization
Text-to-Text
PLM (𝑓𝜃2 )
Unlabeled Dataset
( 𝐷𝑈 = 𝐷𝑈ሺ1ሻ ∪ ⋯ ∪ 𝐷𝑈ሺெ𝑐ሻ )
Curriculum Segmentation
Unlabeled Dataset (𝐷𝑈 )
Figure 2: Overview of CBST. Dotted lines indicate that the teacher is initialized with the text-to-text pre-trained model and trained on the
labeled dataset only before the first iteration. Afterward, the teacher model is initialized by the student model from the previous iteration.
MC denotes the number of curriculum, and D′U contains the unlabeled data included in the current curriculum at each iteration t.
Algorithm 1 Curriculum-Based Self-Training (CBST)
Require:
Labeled dataset: DL = {(GLi ,XL i )}mi=1
Unlabeled dataset: DU = {GUi }Mi=1
Curriculum segmentation criterion: C
Text-to-text pre-trained model: fθT2T
Ensure:
Data-to-text pre-trained model: fθD2T
- 1: Use C to split DU into D(1) U ,D(2) U , ...,D(MC) U
- 2: Initialize the teacher model fθT with fθT2T and train fθT on DL via Eq.(1)
- 3: for t = 1, 2, · · · ,MC do
- 4: D′U ← ⋃ti=1 D(i) U
- 5: Apply fθT to the unlabeled dataset D′U to acquire the generated texts via Eq.(3)
- 6: Select the pseudo-labeled data based on coverage and generation probability to construct the dataset DPL
- 7: Initialize the student model fθS with fθT2T and train fθS on DPL ∪ DL with input noise via Eq.(4)
- 8: fθT ← fθS
- 9: end for
- 10: fθD2T ← fθS
- 11: return fθD2T
At each iteration, we first utilize the teacher model to generate the synthetic texts for the unlabeled dataset D′U ⊂ DU which includes the unlabeled structured data that satisfy the difficulty metric of the current curriculum:
Then, we select the generated texts based on coverage and generation probability which reflect the generation quality [Gehrmann et al., 2018] to construct the pseudo-labeled dataset DPL with M ′ samples. Specifically, we choose the pseudo-labeled data where the proportion of subjects and objects appearing in the generated text is larger than ϵcov and the generation probability of the text ranks top-ϵgen to construct the dataset for the student model training. Here, ϵcov and ϵgen are both hyper-parameters.
Student Model Training
The goal of this module is to train the student model on the pseudo-labeled dataset and the labeled dataset. Initialized with the text-to-text pre-trained model fθT2T , the student
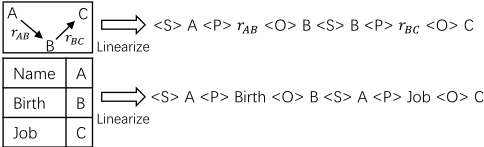
the pre-trained model fθT2T is trained on the pseudo-labeled dataset DPL and the labeled dataset DL. Finally, the student model fθS acts as the teacher model fθT in the next iteration.
3.2 Curriculum-Based Self-Training
Our proposed method is shown in Algorithm 1, which consists of three main steps: curriculum segmentation, pseudolabeled data construction, and student model training.
Curriculum Segmentation
Curriculum segmentation is designed based on the difficulty of generating texts for structured data. In this paper, we choose the number of triples as the difficulty metric to segment the unlabeled dataset DU into MC subsets. This metric reflects the complexity of structures in the input data and has a significant impact on the quality of the generated texts [Ribeiro et al., 2020b]. We also try other metrics in §4.6.
Pseudo-Labeled Data Construction
This module aims to generate pseudo-labeled data with the teacher model at each iteration. Prior to the first iteration, the teacher model fθT is initialized with the pre-trained model fθT2T and trained on the labeled dataset DL with the following loss function:
where l(X,G; fθ) indicates the negative log-likelihood loss and is commonly used in the sequence generation tasks:
Note that except for the first iteration, the teacher model is initialized by the student model from the previous iteration.
| Word Substitution: Replace words with their synonyms |
| Example Input: <S> Bakewell pudding <P> served <O> Warm or cold |
| Example Output: <S> Bakewell dessert <P> acted <O> Warm or cold |
| Reordering: Shuffle the order of triples |
| Triple |
| Example Input: Alan Shepard <P> status <O> Deceased Alan Shepard <P> occupation <O> Test pilot |
| <S> |
| <S> |
| Example Output: <S> Alan Shepard <P> occupation <O> Test pilot |
| <S> Alan Shepard <P> status <O> Deceased |
model fθS is trained with the following loss function:
where NF(G) denotes the noise function perturbing the structured data G. Existing works show that input noise is beneficial for self-training because it increases the smoothness of the student model [He et al., 2020]. Inspired by the existing works [Jia et al., 2019; Hoyle et al., 2021], we devise two-level noise functions as shown in Table 1, including word substitution at the semantic level and triple reordering at the structural level. Specifically, we substitute each word by its synonym with the probability pword and shuffle the order of triples in each sample with the probability ptriple, where pword and ptriple are hyper-parameters. These functions are expected to perturb the input structured data while largely keeping the semantic and structural information.
In practice, we adopt a separate training strategy which shows better performance than joint training [He et al., 2020]. This strategy first trains the student model on the pseudolabeled dataset DPL with the first term of LS, and then trains it on the labeled dataset DL with the second term.
4 Experiment
4.1 Dataset
WebNLG. This dataset aims to generate textual descriptions for RDF triples [Shimorina and Gardent, 2018]. The number of instances in training / validation / test set is 34,352 / 4,316 / 4,224, respectively. We followed the existing works [Chen et al., 2020a] to pre-process this dataset and use 0.5%, 1%, 5%, 10% of the training instances as the labeled datasets in the few-shot setting.
WikiBio. This dataset aims to generate the first sentence of biography descriptions for Wikipedia tables [Lebret et al., 2016]. The original split of the training / validation / test set is 582,658 / 2,000 / 72,831. We followed the existing works [Chen et al., 2020a; Chen et al., 2020b] to pre-process this dataset and use 50, 100, 200, and 500 samples from the training dataset as the labeled datasets in the few-shot setting.
We further constructed the unlabeled dataset for each benchmark dataset based on GenWiki [Jin et al., 2020]. This dataset consists of general-domain unpaired structured data and texts sharing the same content distribution. We directly removed the texts in this dataset, and filtered out the structured data that do not have the subjects and objects appearing in the corresponding labeled dataset. Thus, we obtained two unlabeled datasets for WebNLG and WikiBio, respectively, which contain 375,408 / 163,804 samples of structured data without annotated texts 2 .
4.2 Implementation Detail
In our self-training algorithm, we set the number of curriculum MC to be 3. For both WebNLG and WikiBio datasets, we split the corresponding unlabeled dataset into 3 subsets which contain the structured data with (≤2) / 3-4 / (≥5) triples. For the hyper-parameters to select pseudo-labeled data, we set ϵcov = 1.0, ϵgen = 50%. The probabilities of word substitution and triple reordering were set to pword = ptriple = 0.4.
As for the model structure, we used BART [Lewis et al., 2020] as the text-to-text pre-trained model in our experiments. The base version of BART was adopted because of the limited computational resources. We followed BART to use Byte-Pair Encoding vocabulary with the size of 50,265. The training epoch at each iteration was set to be 20. The learning rate was 0.00003. The batch size was 32 / 24 for WebNLG / WikiBio, respectively. The maximum length of linearized structured data was 256 / 384 for WebNLG / WikiBio, respectively, while the length of text sequences was 128.
4.3 Baseline
Direct Fine-Tuning. This category of baselines directly fine-tunes the state-of-the-art pre-trained models including KGPT [Chen et al., 2020a], Switch-GPT-2 [Chen et al., 2020b] and BART [Lewis et al., 2020] on the labeled data without the use of unlabeled data. We denoted these baselines as FT-KGPT, FT-Switch-GPT-2 and FT-BART, respectively.
Task-Adaptive Pre-Training. This category of baselines designs task-adaptive pre-training methods on unlabeled data before fine-tuning. We chose two representative pretraining tasks: 1) Sequence-level reconstruction (SeqRecon) from BART [Lewis et al., 2020] which decodes complete linearized structured data when encoding corrupted structured data; 2) Graph-level reconstruction (GraphRecon) from JointGT [Ke et al., 2021] which predicts the masked tokens at the output layer of the encoder with the input of corrupted structured data. We denoted them as TAPT-SeqRecon and TAPT-GraphRecon, respectively.
For a fair comparison, we also used BART [Lewis et al., 2020] as the text-to-text pre-trained model for task-adaptive pre-training baselines. We presented the results of our model CBST with two ablation models, i.e., CBST w/o CL and CBST w/o CL & Noise. The former ablation model removes curriculum learning from CBST, which is similar to noisy self-training [He et al., 2020]. The latter one simultaneously removes curriculum learning and input noise, which acts as vanilla self-training. All the results were presented with the average values over 3 runs.
2 We have conducted triple-level matching on the filtered GenWiki and the test set of WebNLG / WikiBio. The results show that there is no overlap between them.
| % of Training Data | 0.5% | 1% | 5% | 10% | ||||||||
|---|---|---|---|---|---|---|---|---|---|---|---|---|
| Model | B-4 | M | R-L | B-4 | M | R-L | B-4 | M | R-L | B-4 | M | R-L |
| Direct Fine-Tuning | ||||||||||||
| FT-KGPT | 22.30 | - | - | 25.60 | - | - | 41.20 | - | - | 47.90 | - | - |
| FT-BART | 31.29 | 29.55 | 53.83 | 38.97 | 33.48 | 58.73 | 51.32 | 40.56 | 66.80 | 55.68 | 42.59 | 69.44 |
| Task-Adaptive Pre-Training | ||||||||||||
| TAPT-SeqRecon | 33.37 | 30.64 | 55.37 | 38.83 | 33.71 | 59.21 | 51.51 | 40.53 | 67.29 | 56.18 | 42.60 | 70.23 |
| TAPT-GraphRecon | 37.47 | 33.31 | 58.84 | 42.29 | 35.93 | 61.22 | 52.25 | 40.78 | 67.96 | 56.57 | 43.02 | 70.44 |
| Self-Training | ||||||||||||
| CBST (Ours) | 38.74** | 34.24** | 60.28** | 44.40** | 37.37** | 63.62** | 54.98** | 42.18** | 69.44** | 58.78** | 43.94** | 71.30** |
| w/o CL | 37.69 | 34.22 | 59.31 | 43.60 | 37.20 | 62.64 | 53.70 | 41.86 | 68.30 | 57.79 | 43.60 | 70.76 |
| w/o CL &Noise | 37.34 | 34.20 | 58.84 | 43.33 | 37.16 | 62.55 | 52.82 | 41.66 | 67.85 | 56.78 | 43.30 | 70.22 |
| # of Training Data | 50 | 100 | 200 | 500 |
|---|---|---|---|---|
| Direct Fine-Tuning | ||||
| FT-Switch-GPT-2 | 17.20 | 23.80 | 25.40 | 28.60 |
| FT-KGPT | 24.20 | 27.60 | 29.10 | 30.00 |
| FT-BART | 25.83 | 29.38 | 32.53 | 34.80 |
| Task-Adaptive Pre-Training | ||||
| TAPT-SeqRecon | 27.93 | 30.81 | 32.59 | 34.90 |
| TAPT-GraphRecon | 28.86 | 30.40 | 32.49 | 35.24 |
| Self-Training | ||||
| CBST (Ours) | 29.63* | 31.23* | 33.21* | 36.27** |
| w/o CL | 29.05 | 30.70 | 33.13 | 35.03 |
| w/o CL &Noise | 27.96 | 30.54 | 32.65 | 34.87 |
4.4 Automatic Result
We followed the existing works [Shimorina and Gardent, 2018; Chen et al., 2020a] to adopt BLEU-4 [Papineni et al., 2002], METEOR [Banerjee and Lavie, 2005], and ROUGEL [Lin, 2004] to evaluate the generated results on WebNLG, and use BLEU-4 as the metric on WikiBio.
The main results on WebNLG and WikiBio are shown in Table 2 and 3. We can observe that CBST significantly outperforms fine-tuning and task-adaptive pre-training methods in all the settings, which shows that our method can explicitly learn the relationship between structured data and texts via self-training and improve the model performance. The comparison between CBST and the ablation models indicates that curriculum learning can alleviate the problem of lowquality pseudo-labeled data and further improve the performance. The noise functions also contribute to the final performance by increasing the smoothness of our model.
4.5 Human Evaluation
To further evaluate the quality of generated results, we conducted human evaluation in the 1% setting of WebNLG. We followed the existing works [Ribeiro et al., 2020b] to use two criteria: fluency (whether a sentence is grammatically fluent)
| Criterion | Fluency | κ | ||
|---|---|---|---|---|
| Model | Win (%) | Lose (%) | Tie (%) | |
| CBST vs. FT-BART | 41.3* | 31.7 | 27.0 | 0.411 |
| CBST vs. TAPT-SeqRecon | 42.0** | 29.3 | 28.7 | 0.410 |
| CBST vs. TAPT-GraphRecon | 41.0* | 32.0 | 27.0 | 0.492 |
| CBST vs. CBST w/o CL | 40.3** | 28.0 | 31.7 | 0.438 |
| CBST vs. CBST w/o CL &Noise | 44.7** | 27.0 | 28.3 | 0.403 |
| Criterion | Adequacy | κ | ||
| Model | Win (%) | Lose (%) | Tie (%) | |
| CBST vs. FT-BART | 58.7** | 25.0 | 16.3 | 0.424 |
| CBST vs. TAPT-SeqRecon | 48.0** | 26.3 | 25.7 | 0.427 |
| CBST vs. TAPT-GraphRecon | 44.0* | 32.7 | 23.3 | 0.401 |
| CBST vs. CBST w/o CL | 40.0* | 31.3 | 28.7 | 0.495 |
| CBST vs. CBST w/o CL &Noise | 51.0** | 28.3 | 20.7 | 0.449 |
and adequacy (whether a sentence clearly describes the structured data). We randomly sampled 100 structured data from the test set, and collected the generated results from CBST and other baselines. We adopted pairwise comparison [Ke et al., 2021] between CBST and other baselines. For each pair of generated texts (one from CBST and the other from the corresponding baseline, given the same input structured data), three annotators were hired to determine which text is better (i.e., win, lose or tie) in terms of the above metrics.
Results in Table 4 show that CBST can significantly outperform the baselines based on direct fine-tuning and taskadaptive pre-training in both fluency and adequacy. In addition, the improvement of CBST over two ablation models shows the effectiveness of our curriculum learning module and noise functions to generate fluent texts which describe structured data more clearly. We also calculated Fleiss' Kappa [Fleiss, 1971] for each pairwise comparison to measure the agreement among different annotators, where the results in Table 4 show moderate agreement (0.4 ≤ κ ≤ 0.6).
4.6 Ablation Study
We conducted a detailed ablation test to study the effects of different noise functions, selection criteria, and difficulty metrics. We removed each module respectively and presented the results on WebNLG (1%) in Table 5. Note that w/ DiffLen denotes that we used the length of linearized structured data as the difficulty metric.
| Model | B-4 | M | R-L |
|---|---|---|---|
| CBST | 44.40 | 37.37 | 63.62 |
| w/o NoiseTriple | 43.87 | 37.24 | 62.92 |
| w/o NoiseWord | 43.53 | 36.93 | 62.94 |
| w/o SelectCov | 43.74 | 37.08 | 63.37 |
| w/o SelectProb | 43.53 | 37.19 | 62.44 |
| w/ DiffLen | 43.93 | 36.75 | 63.27 |
| Model | Hallucination | Missing Fact | Fluency |
|---|---|---|---|
| CBST | 11.3% | 19.0% | 4.45 |
| w/o CL | 17.7% | 19.3% | 4.02 |
| w/o CL & Noise | 18.0% | 19.7% | 3.97 |
Results in Table 5 show that all the modules contribute to the final performance. As for two noise functions, the performance of CBST degrades more in the setting of removing word substitution, which perturbs structured data more flexibly. In terms of the selection criterion, both coverage and generation probability improve the quality of pseudo-labeled data and contribute to the final performance. We can also observe the performance drop when CBST used the length of linearized structured data as the difficulty metric, indicating that the number of input triples is a more proper metric to reflect the difficulty of text generation from structured data.
4.7 Analysis on Pseudo-Labeled Data
To study whether our method can improve the quality of pseudo-labeled data via curriculum learning, we evaluated the quality of pseudo-labeled data generated by the teacher model at the last iteration before selection. We resorted to human evaluation since there is no annotated text for unlabeled structured data. We randomly sampled 100 unlabeled structured data and collected the generated results of the teacher models from CBST and the ablation models at the last iteration. Three annotators were hired to judge each generated text from the following fine-grained aspects: 1) Hallucination: whether the generated text includes non-existing facts; 2) Missing fact: whether the generated text misses input facts; 3) Fluency: the fluency score of generated texts (score 1-5 where 5 indicates fully fluent sentences).
We presented the fluency score and the proportions of generated results that belong to hallucination / missing fact in Table 6. Results show that curriculum learning in our method plays an important role in generating fluent and adequate texts to describe unlabeled structured data, resulting in better model performance. The relatively limited improvement on missing facts may be because our base model BART already has the strong ability to generate texts that appear in the input via its pre-training tasks based on text reconstruction.
4.8 Analysis on CurriculumLearning
To further analyze how curriculum learning helps selftraining in few-shot data-to-text generation, we first demonstrated how the number of curriculum (MC) affects the fi- Table 7: BLEU-4(B-4), METEOR(M), ROUGE-L(R-L) on WebNLG (1%) with different numbers of curriculum.
| MC | B-4 | M | R-L |
| 2 | 43.55 | 36.79 | 62.93 |
| 3 | 44.40 | 37.37 | 63.62 |
| 4 | 43.29 | 36.67 | 63.07 |
Iteration
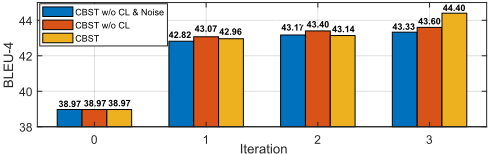
Figure 4: BLEU-4 of CBST and two ablation models at different iterations.
nal performance. The results in Table 7 show that the best performance is reached at MC = 3. When MC is smaller, the teacher model needs to generate texts for unlabeled structured data with multiple triples at early iterations, which may degrade the quality of pseudo-labeled data and the final performance. In contrast, when MC is larger, the student model is trained on easy unlabeled data for many iterations and cannot utilize the hard cases until the late iterations, which may also affect the model performance.
Furthermore, we set MC = 3 and visualized the performance of the student model at each iteration in Figure 4. Note that the values when the number of iterations equals 0 indicate the performance of direct fine-tuning. At early iterations, the two ablation models perform better because they directly incorporate the whole unlabeled dataset into self-training and acquire a larger pseudo-labeled dataset. However, the improvement of their performance is extremely limited at the second and third iterations since the low-quality texts generated by the teacher model at early iterations may restrict the model performance. For comparison, CBST only utilizes the unlabeled data that satisfy the difficulty metric at each iteration to avoid low-quality pseudo-labeled data. Despite the worse performance at early iterations due to the smaller number of unlabeled data included in the self-training process, CBST still obtains the best performance at the last iteration.
5 Conclusion
We introduce self-training to improve text-to-text pre-trained models on few-shot data-to-text generation tasks, which can utilize unlabeled structured data to explicitly model the relationship between structured data and texts. To alleviate the problem of low-quality pseudo-labeled data during self-training, we further propose a novel method called Curriculum-Based Self-Training to rearrange the order of unlabeled data incorporated into self-training based on the difficulty metric. Experimental results show that CBST outperforms fine-tuning and task-adaptive pre-training methods, and achieves state-of-the-art performance in the few-shot setting of WebNLG and WikiBio datasets.
Acknowledgments
This work was supported by the National Science Foundation for Distinguished Young Scholars (with No. 62125604) and the NSFC projects (Key project with No. 61936010 and regular project with No. 61876096). This work was supported by the Guoqiang Institute of Tsinghua University, with Grant No. 2019GQG1 and 2020GQG0005. This work was also supported by OPPO Research Fund. This work was sponsored by Tsinghua-Toyota Joint Research Fund.
@inproceedings{ijcai2022p580,
  title     = {Curriculum-Based Self-Training Makes Better Few-Shot Learners for Data-to-Text Generation},
  author    = {Ke, Pei and Ji, Haozhe and Yang, Zhenyu and Huang, Yi and Feng, Junlan and Zhu, Xiaoyan and Huang, Minlie},
  booktitle = {Proceedings of the Thirty-First International Joint Conference on
               Artificial Intelligence, {IJCAI-22}},
  publisher = {International Joint Conferences on Artificial Intelligence Organization},
  editor    = {Luc De Raedt},
  pages     = {4178--4184},
  year      = {2022},
  month     = {7},
  note      = {Main Track},
  doi       = {10.24963/ijcai.2022/580},
  url       = {https://doi.org/10.24963/ijcai.2022/580},
}
TY - CPAPER TI - Curriculum-Based Self-Training Makes Better Few-Shot Learners for Data-to-Text Generation AU - Ke, Pei AU - Ji, Haozhe AU - Yang, Zhenyu AU - Huang, Yi AU - Feng, Junlan AU - Zhu, Xiaoyan AU - Huang, Minlie T2 - Proceedings of the Thirty-First International Joint Conference on Artificial Intelligence, IJCAI-22 PB - International Joint Conferences on Artificial Intelligence Organization PY - 2022 SP - 4178 EP - 4184 DO - 10.24963/ijcai.2022/580 UR - https://doi.org/10.24963/ijcai.2022/580 ER -Copied
Machine-readable versions of this paper, for tools and AI agents:





