
c-TPE: Tree-structured Parzen Estimator with Inequality Constraints for Expensive Hyperparameter Optimization
Proceedings of the Thirty-Second International Joint Conference on Artificial Intelligence. Main Track. Pages 4371-4379.
https://doi.org/10.24963/ijcai.2023/486
Keywords
- Machine Learning: ML: Hyperparameter optimization
- Machine Learning: ML: Automated machine learning
Abstract
Hyperparameter optimization (HPO) is crucial for strong performance of deep learning algorithms and real-world applications often impose some constraints, such as memory usage, or latency on top of the performance requirement. In this work, we propose constrained TPE (c-TPE), an extension of the widely-used versatile Bayesian optimization method, tree-structured Parzen estimator (TPE), to handle these constraints. Our proposed extension goes beyond a simple combination of an existing acquisition function and the original TPE, and instead includes modifications that address issues that cause poor performance. We thoroughly analyze these modifications both empirically and theoretically, providing insights into how they effectively overcome these challenges. In the experiments, we demonstrate that c-TPE exhibits the best average rank performance among existing methods with statistical significance on 81 expensive HPO with inequality constraints. Due to the lack of baselines, we only discuss the applicability of our method to hard-constrained optimization in Appendix D. See https://arxiv.org/abs/2211.14411 for the latest version with Appendix.
- [Addison et al., 2022] H. Addison, KS. inversion, H. Ryan, and C. Ted. Happywhale -whale and dolphin identifica- tion. Kaggle, 2022.
- [Akiba et al., 2019] T. Akiba, S. Sano, T. Yanase, T. Ohta, and M. Koyama. Optuna: A next-generation hyperparam- eter optimization framework. In International Conference on Knowledge Discovery & Data Mining, 2019.
- [Alina et al., 2019] JE. Alina, C. Phil, B. Rodrigo, and G. Victor. Open images 2019 -object detection. Kaggle, 2019.
- [Arnold and Hansen, 2012] D. Arnold and N. Hansen. A (1+1)-CMA-ES for constrained optimisation. In Genetic and Evolutionary Computation Conference, 2012.
- [Awad et al., 2021] N. Awad, N. Mallik, and F. Hutter. DEHB: Evolutionary hyberband for scalable, robust and efficient hyperparameter optimization. arXiv:2105.09821, 2021. IJCAI
- [Bergstra and Bengio, 2012] J. Bergstra and Y. Bengio. Ran- dom search for hyper-parameter optimization. Journal of Machine Learning Research, 13(2), 2012.
- [Bergstra et al., 2011] J. Bergstra, R. Bardenet, Y. Bengio, and B. Kégl. Algorithms for hyper-parameter optimiza- tion. In Advances in Neural Information Processing Sys- tems, 2011.
- [Bergstra et al., 2013] J. Bergstra, D. Yamins, and D. Cox. Making a science of model search: Hyperparameter op- timization in hundreds of dimensions for vision architec- tures. In International Conference on Machine Learning, 2013.
- [Brochu et al., 2010] E. Brochu, V. Cora, and N. de Fre- itas. A tutorial on Bayesian optimization of expensive cost functions, with application to active user modeling and hi- erarchical reinforcement learning. arXiv:1012.2599, 2010.
- [Chen et al., 2018] Y. Chen, A. Huang, Z. Wang, I. Antonoglou, J. Schrittwieser, D. Silver, and N. de Fre- itas. Bayesian optimization in alphago. arXiv:1812.06855, 2018.
- [Deb et al., 2002] K. Deb, A. Pratap, S. Agarwal, and T. Me- yarivan. A fast and elitist multiobjective genetic algorithm: NSGA-II. IEEE Transactions on Evolutionary Computa- tion, 6(2):182-197, 2002.
- [Dong and Yang, 2020] X. Dong and Y. Yang. NAS-Bench- 201: Extending the scope of reproducible neural architec- ture search. arXiv:2001.00326, 2020.
- [Eriksson and Poloczek, 2021] D. Eriksson and M. Poloczek. Scalable constrained Bayesian opti- mization. In International Conference on Artificial Intelligence and Statistics, 2021.
- [Falkner et al., 2018] S. Falkner, A. Klein, and F. Hutter. BOHB: Robust and efficient hyperparameter optimization at scale. In International Conference on Machine Learn- ing, 2018.
- [Gardner et al., 2014] J. Gardner, M. Kusner, ZE. Xu, K. Weinberger, and J. Cunningham. Bayesian optimiza- tion with inequality constraints. In International Confer- ence on Machine Learning, 2014.
- [Garnett, 2022] R. Garnett. Bayesian Optimization. Cam- bridge University Press, 2022.
- [Garrido-Merchán et al., 2023] EC.
- Garrido-Merchán, D. Fernández-Sánchez, and D. Hernández-Lobato. Parallel predictive entropy search for multi-objective Bayesian optimization with constraints applied to the tuning of machine learning algorithms. Expert Systems with Applications, 215, 2023.
- [Gelbart et al., 2014] M. Gelbart, J. Snoek, and R. Adams. Bayesian optimization with unknown constraints. arXiv:1403.5607, 2014.
- [Jones et al., 1998] D. Jones, M. Schonlau, and W. Welch. Efficient global optimization of expensive black-box func- tions. Journal of Global Optimization, 13(4):455-492, 1998.
- [Klein and Hutter, 2019] A. Klein and F. Hutter. Tabular benchmarks for joint architecture and hyperparameter op- timization. arXiv:1905.04970, 2019.
- [Kushner, 1964] HJ. Kushner. A new method of locating the maximum point of an arbitrary multipeak curve in the presence of noise. Joint Automatic Control Conference, 1964.
- [Letham et al., 2019] B. Letham, B. Karrer, G. Ottoni, and E. Bakshy. Constrained Bayesian optimization with noisy experiments. Bayesian Analysis, 14(2):495-519, 2019.
- [Liaw et al., 2018] R. Liaw, E. Liang, R. Nishihara, P. Moritz, J. Gonzalez, and I. Stoica. Tune: A re- search platform for distributed model selection and train- ing. arXiv:1807.05118, 2018.
- [Lobato et al., 2015] JH. Lobato, M. Gelbart, M. Hoffman, R. Adams, and Z. Ghahramani. Predictive entropy search for bayesian optimization with unknown constraints. In International Conference on Machine Learning, 2015.
- [Loshchilov and Hutter, 2016] I. Loshchilov and F. Hutter. CMA-ES for hyperparameter optimization of deep neural networks. arXiv:1604.07269, 2016.
- [Loshchilov et al., 2013] I. Loshchilov, M. Schoenauer, and M. Sebag. Bi-population CMA-ES agorithms with surro- gate models and line searches. In Genetic and Evolution- ary Computation Conference, 2013.
- [Melis et al., 2018] G. Melis, C. Dyer, and P. Blunsom. On the state of the art of evaluation in neural language models. In International Conference on Learning Representations, 2018.
- [Montes et al., 2006] EM. Montes, J. Velázquez-Reyes, and CA. Coello. Modified differential evolution for con- strained optimization. In International Conference on Evo- lutionary Computation, 2006.
- [Nardi et al., 2019] L. Nardi, D. Koeplinger, and K. Oluko- tun. Practical design space exploration. In Interna- tional Symposium on Modeling, Analysis, and Simulation of Computer and Telecommunication Systems, pages 347- 358. IEEE, 2019.
- [Perrone et al., 2019] V. Perrone, I. Shcherbatyi, R. Jenat- ton, C. Archambeau, and M. Seeger. Constrained Bayesian optimization with max-value entropy search. arXiv:1910.07003, 2019.
- [Shahriari et al., 2016] B. Shahriari, K. Swersky, Z. Wang, R. Adams, and N. de Freitas. Taking the human out of the loop: A review of Bayesian optimization. Proceedings of the IEEE, 104(1):148-175, 2016.
- [Watanabe, 2023] S. Watanabe. Tree-structured Parzen esti- mator: Understanding its algorithm components and their roles for better empirical performance. arXiv:2304.11127, 2023.
- [Ying et al., 2019] C. Ying, A. Klein, E. Christiansen, E. Real, K. Murphy, and F. Hutter. NAS-Bench-101: To- wards reproducible neural architecture search. In Interna- tional Conference on Machine Learning, 2019.
References were extracted automatically from the PDF and may contain errors.
Full text extracted automatically from the PDF; figures, tables and equations may differ. The PDF is the version of record.
1 Introduction
While deep learning (DL) has achieved various breakthrough successes, its performance highly depends on the proper settings of its hyperparameters [Chen et al., 2018; Melis et al., 2018]. Furthermore, practical applications often impose several constraints on memory usage or latency of inference, making it necessary to apply constrained hyperparameter optimization (HPO).
Recent developments in constrained HPO have led to the emergence of new acquisition functions (AFs) [Gardner et al., 2014; Lobato et al., 2015; Eriksson and Poloczek, 2021] in Bayesian optimization (BO) with Gaussian process (GP), which judge the promise of a configuration based on the surrogate model. While GP-based methods offer theoretical advantages, recent open source softwares (OSS) for HPO, such as Optuna [Akiba et al., 2019], Hyperopt [Bergstra et al., 2013], and Ray [Liaw et al., 2018], instead employ the tree-structured Parzen estimator (TPE) [Bergstra et al., 2011; Bergstra et al., 2013; Watanabe, 2023], a variant of BO using the density ratio of kernel density estimators for good and bad observations, as the main algorithm, and Optuna played a pivotal role for HPO of DL models in winning Kaggle competitions [Alina et al., 2019; Addison et al., 2022]. Despite its versatility for expensive HPO problems, the existing AFs are not directly applicable to TPE and no study has been conducted on TPE's extension to constrained optimization.
In this paper, we propose c-TPE, a constrained optimization method that generalizes TPE. We first show that it is possible to integrate the original TPE into the existing AF proposed by Gelbart et al. [2014], which uses the product of AFs for the objective and each constraint, and thus TPE can be generalized with constrained settings. Then, a na¨ıve extension, which calculates AF by the product of density ratios for the objective and each constraint with the same split algorithm, could be simply obtained; however, the na¨ıve extension suffers from performance degradation under some circumstances. To circumvent these pitfalls, we propose (1) the split algorithm that includes a certain number of feasible solutions, and (2) AF by the product of relative density ratios, and analyze their effects empirically and theoretically.
In the experiments, we demonstrate (1) the strong performance of c-TPE with statistical significance on expensive HPO problems and (2) robustness to changes in the constraint level. Notice that we briefly discuss the applicability of our method to hard-constrained optimization in Appendix D, and we discuss the limitations of our work in Appendix E caused by our choices of search spaces that are limited to tabular benchmarks to enable the stability analysis of the performance variations depending on constraint levels.
In summary, the main contributions of this paper are to:
- prove that TPE can be extended to constrained settings using the AF proposed by Gelbart et al. [2014],
- present two pitfalls in the na¨ıve extension and describe how our modifications mitigate those issues,
- provide the stability analysis of the performance variations depending on constraint levels, and
- demonstrate that the proposed method outperforms existing methods with statistical significance on average on 9 tabular benchmarks with 27 different settings.
The implementation and the experiment scripts are available at https://github.com/nabenabe0928/constrained-tpe/.
2 Background
2.1 Bayesian Optimization (BO)
Suppose we would like to minimize a validation loss metric f(x) = L(x,A,Dtrain,Dval) of a supervised learning algorithm A given training and validation datasets Dtrain,Dval, then the HPO problem is defined as follows:
Note that x ∈ X is a hyperparameter configuration, X = X1 × · · · × XD is the search space of the hyperparameter configurations, and Xd ⊆ R (for d = 1, . . . ,D) is the domain of the d-th hyperparameter. In Bayesian optimization (BO) [Brochu et al., 2010; Shahriari et al., 2016; Garnett, 2022], we assume that f(x) is expensive and consider the optimization in a surrogate space given a set of observations D := {(xn, fn)}Nn=1 . In each iteration of BO, we build a predictive model p(f|x,D) and optimize an AF to yield the next configuration. A common choice for AF is the following expected improvement (EI) [Jones et al., 1998]:
Another common choice is the following probability of improvement (PI) [Kushner, 1964]:
2.2 Tree-Structured Parzen Estimator (TPE)
TPE [Bergstra et al., 2011; Bergstra et al., 2013] is a variant of BO methods and it uses EI. See Watanabe [2023] to better understand the algorithm components. To transform Eq. (2), we assume the following:
where D(l) ,D(g) are the observations with fn ≤ f γ and fn > f γ , respectively. Note that f γ is the top-γ quantile objective value in D at each iteration and p(x|D(l) ), p(x|D(g) ) are built by the kernel density estimator [Bergstra et al., 2011; Bergstra et al., 2013; Falkner et al., 2018]. Combining Eqs. (2), (4) and Bayes' theorem, the AF of TPE is computed as [Bergstra et al., 2011]:
where φ(x) rank ≃ ψ(x) implies the order isomorphic and ∀x, x′ ∈ X, φ(x) ≤ φ(x′ ) ⇔ ψ(x) ≤ ψ(x′ ) holds and we use f ⋆ = f γ at each iteration. In each iteration, TPE samples configurations from p(x|D(l) ) and takes the configuration that achieves the maximum r(x|D).
2.3 Bayesian Optimization with Unknown Constraints
We consider unknown constraints ci(x) = Ci(x,A,Dtrain,Dval), e.g. memory usage of the algorithm A given the configuration x. Then the optimization is formulated as follows:
where c⋆i ∈ R is a threshold for the i-th constraint. Note that we reverse the sign of inequality if constraints must be larger than a given threshold. To extend BO to constrained optimization, the following expected constraint improvement (ECI) has been proposed [Gelbart et al., 2014]:
where c⋆ = [c⋆1 , . . . , c⋆C ] ∈ RC and D = {(xn, fn, cn)}Nn=1 is a set of observations, and cn = [c1,n, . . . , cC,n] ∈ RC is the n-th observation of each constraint. However, the following simplified factorized form is the common choice:
Since there are few methods available for hard-constrained optimization, we only discuss the applicability of our method to hard-constrained optimization in Appendix D.
3 Constrained TPE (c-TPE)
In this section, we first prove that TPE can be extended to constrained settings via the simple product of AFs. Then we describe an extension na¨ıvely inspired by the original TPE and discuss two pitfalls hindering efficient search. Finally, we present modifications for those pitfalls and analyze the effects on toy problems.
Note that throughout this paper, we use the terms γquantile value f γ as the top-γ quantile function value, γc⋆ as the quantile of c⋆ , and Γ-feasible domain as the feasible domain in the search space X that covers 100 × Γ% of X. For the formal definitions, see Appendix A.1. Furthermore, we consider two assumptions mentioned in Appendix A.2 and those assumptions allow the whole discussion to be extended to search spaces with categorical parameters.
3.1 Na¨ıve Acquisition Function
Suppose we would like to solve constrained optimization problems formalized in Eq. (6) with ECI. To realize ECI in TPE, we first show the following proposition.
The proof is provided in Appendix A.3. Since PI and EI are equivalent under the TPE formulation, we obtain the following by combining Proposition 1 and Eq. (8):
Note that we provide the definition of ri(x|D) for i ∈ {0, 1, . . . , C} in the next section.
3.2 Two Pitfalls in Na¨ıve Extension
Na¨ıve Extension and Modifications
From the discussion above, we could na¨ıvely extend the original TPE to constrained settings using the split in Eq. (4) and the AF in Eq. (5). More specifically, the na¨ıve extension computes the AF as follows:
Algorithm 1 c-TPE algorithm (With modifications)
- 1: Ninit (The number of initial configurations), Ns (The number of candidates to consider in the optimization of the AF)
- 2: D← ∅
- 3: for n = 1, . . . ,Ninit do
- 4: Randomly pick x
- 5: D←D∪ {(x, f(x), c1(x), . . . , cC(x))}
- 6: while Budget is left do
- 7: S = ∅
- 8: for i = 0, . . . , C do
9:
Split D into D(l)
i and D(g)
γi ← |D(l)
i , ˆ
i |/|D|
- 10: Build p(·|D(l) i ), p(·|D(g) i )
- 12: ▷ See Appendix D for the hard-constrained version
- 13: Pick xopt ∈ argmaxx∈S ∏Ci=0 rrel i (x|D)
- 14: D←D∪{(xopt, f(xopt), c1(xopt), . . . , cC(xopt))}
- Pick the ⌈γ|D|⌉-th best objective value f ⋆ in D,
- Split D into D(l) 0 and D(g) 0 at f ⋆ , and D into D(l) i and D(g) i at c⋆i for i ∈ {1, . . . ,C},
- Build kernel density estimators p(x|D(l) i ), p(x|D(g) i ) for i ∈ {0, . . . , C}, and
- Take the product of density ratios ∏Ci=0 ri(x|D) := ∏Ci=0 p(x|D(l) i )/p(x|D(g) i ) as the AF.
Note that as c⋆i is a user-defined threshold, c⋆i is fixed during the optimization. Although this implementation could be naturally inspired by the original TPE, Operations 1 and 4 could incur performance degradation under (1) small overlaps in top domains for the objective and feasible domains, or (2) vanished constraints.
For this reason, we change Operations 1 and 4 as follows:
- Pick the ⌈γ|D|⌉-th best feasible objective value f ⋆ in D (Line 9), and
- Take the product of relative density ratios ∏Ci=0 rrel i (x|D) := ∏Ci=0 (ˆ γi + (1 - ˆ γi)ri(x|D)-1 )-1 as the AF (Line 13).
Note that we color-coded the modifications in Algorithm 1 and we define ˆ γi := |D(l) i |/|D|. Intuitively, when all configurations satisfy the i-th constraint, i.e. |D(l) i | = |D| ⇒ ˆ γi = 1, we trivially yield rrel i = 1; therefore, the i-th constraint will be ignored and it is equivalent to ∀x ∈ X, P[ci ≤ c⋆| x, D] = 1. Additionally, the following corollary guarantees the mathematical validity of our algorithm:
We provide the proof in Appendix A.4.
The split algorithm in the original TPE by Bergstra et al. [2013] first sorts the observations D by f and takes the first ⌈√N/4⌉ observations as D(l) 0 and the rest as D(g) 0 . On the other hand, our method includes all the observations until the
⌈√N/4⌉-th feasible observations into D(l) 0 and the rest into D(g) 0 , and this split algorithm matches the original algorithm when Γ = 1. For the split of constraints, we first check the upper bound of {ci,n}Nn=1 that satisfies a given threshold c⋆i and let this value be c′i . Note that ci,n is the i-th constraint value in the n-th observation. If such values do not exist, we take the best value min{ci,n}Nn=1 so that the optimization of this constraint will be strengthened (see Theorem 1). Then we split D into D(l) i and D(g) i so that D(l) i includes only observations that satisfy ci,n ≤ c′i and vice versa. We describe more details in Appendix B and the applicability to hard-constrained optimization in Appendix D. We start the discussion of why these modifications mitigate the issues in the next section.
Issue I: Vanished Constraints
We refer to constraints that are satisfied in almost all configurations as vanished constraints. In other words, if the i-th constraint ci is a vanished constraint, its quantile is ˆ γi := ˆ γc⋆i ≃ 1. In this case, ri(x|D) should be a constant value as P(ci ≤ c⋆i |x,D) = 1 holds for almost all configurations x. As discussed in Section 3.2, the relative density ratio rrel i (x|D) resolves this issue and it can be written more formally as follows:
Corollary 2 Assuming the feasible domain quantile Γ = 1, then ∏Ci=0 rrel i (x|D) rank ≃ r0(x|D) holds.
Recall that we previously defined r0(x|D) := p(x|D(l) 0 )/p(x|D(g) 0 ) for D(l) 0 ,D(g) 0 obtained by splitting D at f ⋆ . The proof is provided in Appendix A.6. Corollary 2 indicates that the AF of c-TPE is equivalent to that of the original TPE when Γ = 1 and it means that our formulation achieves P(ci ≤ c⋆i |x,D) = 1 if ˆ γi = 1. Corollary 2 is a special case of the following theorem:
Theorem 1 Given a pair of constraint thresholds c⋆i , c⋆j and the corresponding quantiles ˆ γi, ˆ γj (ˆ γi ≤ ˆ γj), if ri+ ˆ γi 1-ˆ γi r2 i ≤ rj + ˆ γj 1-ˆ γj r2 j holds, then
holds where the first equality holds if ˆ γi = ˆ γj and ri = rj and the second one holds iff ˆ γj = 1.
The proof is provided in Appendix A.5. Roughly speaking, Theorem 1 implies that our modified AF puts more priority on the variations of the density ratios with lower quantiles, i.e. ri in the statement above, when ri = rj.
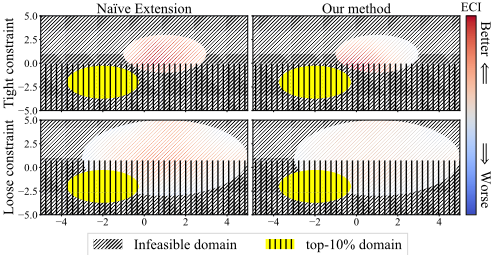
We empirically and intuitively present the effect of Theorem 1 in Figure 1. We used the objective function f(x, y) = (x+2)2+(y+2)2 and the constraint c1(x, y) = (x-1)2+(y1)2 ≤ c⋆1 ∈ {4, 16} and visualize the heat maps of the AF using exactly the same observations for each figure. Note that all used parameters are described in Appendix G. As mentioned earlier, since the na¨ıve extension (Left column) does not decay the contribution from the objective or the constraint with a large ˆ γi, it has two peaks. For our algorithm, however, we only have one peak between the top-10% domain and the feasible domain because our AF decays the contribution from either the objective or the constraint based on their quantiles ˆ γi as mentioned in Theorem 1. More specifically, for the tight constraint case (Top right), since the feasible domain quantile ˆ γ1 ≃ 0.12 is relatively small compared to the top-solution quantile ˆ γ0 ≃ 0.3, the peak in the top-10% domain vanishes. Notice that we discuss why we have the peak not at the center of the feasible domain, but between the feasible domain and the top-10% domain in the next section. For the loose constraint case (Bottom right), ˆ γ1 ≃ 0.50 is much larger than ˆ γ0 ≃ 0.02 and this decays the contribution from the center of the feasible domain where we have the largest r1(x|D). As mentioned in Corollary 2, rrel i (x|D) = 1 holds for i ∈ {1, . . . ,C} when Γ = 1, and thus the AF coincides with that for the single objective optimization. Note that since we yield γ0 = 1.0 in the case of all observations being infeasible, the objective function will be ignored and only constraints will be optimized.
Issue II: Small Overlaps in Top and Feasible Domains
Since the original TPE algorithm just takes the top-γ quantile observations, it does not guarantee that D(l) has feasible solutions. We explain its effect using Figure 1. For the tight constraint case (Top row), an overlap between the feasible domain and the top-10% domain does not exist and it causes the two peaks in the AF for the original split algorithm (Top left); however, it is necessary for constrained optimization to sample intensively within feasible domains. In turn, we modify the split algorithm to include a certain number of feasible solutions. This modification leads to the large white circle that embraces the top-10% domain (Top right). As a result, our algorithm yields a peak at the overlap between the large white circle and the feasible domain.
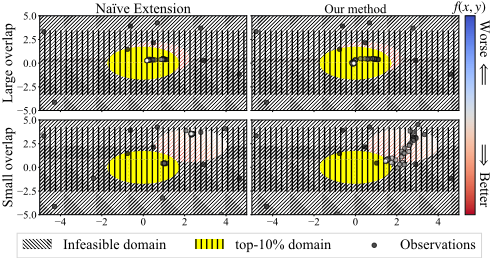
In Figure 2, we visualize how our algorithm and the na¨ıve extension samples configurations using a toy example. We used the objective function f(x, y) = x2 + y2 and the constraint c1(x, y) = (x - z)2 + (y - z)2 ≤ c⋆1 = 3 where z ∈ {0.5, 2.3}. This experiment also follows the settings used in Appendix G and both algorithms share the initial configurations. For the large overlap case (Top row), both algorithms search similarly. In contrast to this case, the small overlap case (Bottom row) obtained different sampling behaviors. While our algorithm (Bottom right) samples intensively at the boundary between the feasible domain and the top-10% domain, the na¨ıve extension (Bottom left) does not. Furthermore, we can see a trajectory from the top right of the feasible domain to the boundary for our algorithm and it exists only in our algorithm although both methods have some observations, which are colored by strong gray, meaning that they were obtained at the early stage of the optimization, in the top right of the feasible domain. Based on Figure 1 (Top right), we can infer that this is because we include some feasible solutions in D(l) 0 and the peak of the AF will be shifted toward the top-10% domain in our algorithm.
Figure 2: Scatter plots of observations obtained by the na¨ıve extension (Left column) and our c-TPE (Right column) on a large (Top row, z = 0.5) or small (Bottom row, z = 2.3) overlap between the top-10% domain and feasible domain. Each figure shows the 2D search space for each task and the observations obtained during optimization are plotted. Earlier observations are colored black and later observations are colored white. Each figure has 50 observations.
4 Experiments
4.1 Setup
The evaluations were performed on the following 10 tabular benchmarks:
- HPOlib (Slice Localization, Naval Propulsion, Parkinsons Telemonitoring, Protein Structure) [Klein and Hutter, 2019]: All with 6 numerical and 3 categorical parameters;
- NAS-Bench-101 (CIFAR10A, CIFAR10B, CIFAR10C) [Ying et al., 2019]: Each with 26 categorical, 14 categorical, and 22 numerical and 5 categorical parameters, respectively; and
- NAS-Bench-201 (ImageNet16-120, CIFAR10, CIFAR100) [Dong and Yang, 2020]: All with 6 categorical parameters.
The reason behind this choice is that tabular benchmarks enable us to control the quantiles of each constraint γ true i , which significantly change the feasible domain size and the quality of solutions. For example, suppose a tabular dataset has Nall configurations {(xn, fn, cn)}Nall n=1 and the dataset is sorted so that it satisfies ci,1 ≤ ci,2 ≤ · · · ≤ ci,Nall where ci,n is the i-th constraint value in the n-th configuration, then we fix the threshold for the i-th constraint c⋆i as ci,⌊Nall/10⌋ in the setting of γ true i = 1/10. We evaluated each benchmark with 9 different quantiles γ true i for each constraint and 3 different constraint choices. Constraint choices are network size, runtime, or both. The search space for each benchmark followed Awad et al. [2021].
| Quantiles Methods / # of configs | γ true i 100 | = 0.1 150 | 200 | 50 | true i = 0.5 | 200 | 50 | γ true i = | 0.9 150 | 200 | |
|---|---|---|---|---|---|---|---|---|---|---|---|
| 50 | γ 100 | 150 | 100 | ||||||||
| Na¨ıve c-TPE | 26/0/1 27/0/0 | 27/0/0 | 27/0/0 | 25/0/2 | 25/0/2 | 25/1/1 | 25/0/2 | 21/5/1 | 23/1/3 | 21/1/5 | 24/1/2 |
| Vanilla TPE | 27/0/0 27/0/0 | 27/0/0 | 27/0/0 | 25/0/2 | 26/0/1 | 26/1/0 | 24/0/3 | 14/11/2 | 18/8/1 | 15/5/7 | 16/7/4 |
| Random | 25/0/2 26/1/0 | 27/0/0 | 27/0/0 | 27/0/0 | 26/0/1 | 26/0/1 | 27/0/0 | 27/0/0 | 27/0/0 | 27/0/0 | 27/0/0 |
| CNSGA-II | 25/0/2 27/0/0 | 24/0/3 | 24/0/3 | 26/0/1 | 26/0/1 | 26/0/1 | 25/0/2 | 26/1/0 | 27/0/0 | 27/0/0 | 26/0/1 |
| NEI | 24/1/2 27/0/0 | 27/0/0 | 27/0/0 | 27/0/0 | 26/0/1 | 26/0/1 | 27/0/0 | 27/0/0 | 27/0/0 | 27/0/0 | 27/0/0 |
| HM2 | 23/2/2 26/1/0 | 25/2/0 | 25/2/0 | 22/3/2 | 23/2/2 | 25/1/1 | 23/0/4 | 27/0/0 | 27/0/0 | 23/0/4 | 26/0/1 |
As the baseline methods, we chose:
- Random search [Bergstra and Bengio, 2012],
- CNSGA-II [Deb et al., 2002], 1 (population size 8),
- Noisy ECI (NEI) [Letham et al., 2019] 2 ,
- Hypermapper2.0 (HM2) [Nardi et al., 2019] 3 ,
- Vanilla TPE (Optimize only loss as if we do not have constraints), and
- Na¨ıve c-TPE (The na¨ıve extension discussed in Section 3).
We describe the details of each method and their control parameters in Appendix G. Note that all experiments were performed 50 times with different random seeds and we evaluated 200 configurations for each optimization. Additionally, since the optimizations by NEI and HM2 on CIFAR10C failed due to the high-dimensional (22 dimensions) continuous search space for NEI and an unknown internal issue for HM2, we used the results on 9 benchmarks (other than CIFAR10C) for the statistical test and the average rank computation. The results on CIFAR10C by the other methods are available in Appendix H and the source code is available at https://github.com/nabenabe0928/constrained-tpe along with complete scripts to reproduce the experiments, tables, and figures. A query of c-TPE with {50, 100, 150, 200} observations took {0.22, 0.24, 0.26, 0.28} seconds for a 30D problem with 8 cores of core i7-10700.
4.2 Robustness to Feasible Domain Size
This experiment shows how c-TPE performance improves given various levels of constraints. We optimized each benchmark with the aforementioned three types of constraints and chose γ true i ∈ {0.1, 0.5, 0.9} for each constraint. All results on other benchmarks are available in Appendix H. Table 1 presents the numbers of wins/loses/ties and statistical significance by the Wilcoxon signed-rank test and Figure 3 shows the performance curves for each benchmark.
1 Implementation: https://github.com/optuna/optuna
2 Implementation: https://github.com/facebook/Ax
3 Implementation: https://github.com/luinardi/hypermapper
As a whole, while the performance of c-TPE is stable across all constraint levels, that of NEI, HM2, and CNSGA-II variates depending on constraint levels. Furthermore, Table 1 shows that c-TPE is significantly better than other methods in almost all settings. This experimentally validates the robustness of c-TPE to the variations in constraint levels.
For ImageNet of NAS-Bench-201 (Bottom row), the na¨ıve c-TPE is completely defeated by the other methods while cTPE achieves the best or indistinguishable performance from the best performance. This gap between c-TPE and the na¨ıve c-TPE is caused by the small overlaps discussed in Section 3.2. For example, only 59% of the top-10% configurations belong to the feasible domain in NAS-Bench-201 of γ true i = 0.9 although we can usually expect that 90%of them belong to the feasible domain, and 84% and 77% of those in HPOlib and NAS-Bench-101 actually belong to the feasible domain for γ true i = 0.9, respectively. The small overlap leads to the performance gap between c-TPE and the vanilla TPE as well. As TPE is not a uniform sampler and tries to sample from top domains, ˆ γi will not necessarily approach γ true i . In our case, it is natural to consider ˆ γi to be closer to 59% rather than 90% as only 59% of top-10% configurations are feasible. As mentioned also in Theorem 1, c-TPE is advantageous to such settings compared to the vanilla TPE and the na¨ıve c-TPE.
For CIFAR10A of NAS-Bench-101 (Middle row), the results show different patterns from the other settings due to the high-dimensional (D = 26) nature. For γ true i = 0.1, 0.5 (Left, center), most methods exhibit indistinguishable performance from random search especially in the beginning because little information on feasible domains is available in the early stage of optimizations due to the high dimensionality although c-TPE outperforms in the end. In γ true i = 0.9 (Right), the na¨ıve c-TPE is slightly better than c-TPE due to large overlaps (84% of the top-10% configurations are feasible). It implies that if search space is high dimensions and overlaps in top domains and feasible domains are large, it might be better to greedily optimize only the objective rather than regularizing the optimization of the objective as in our modification.
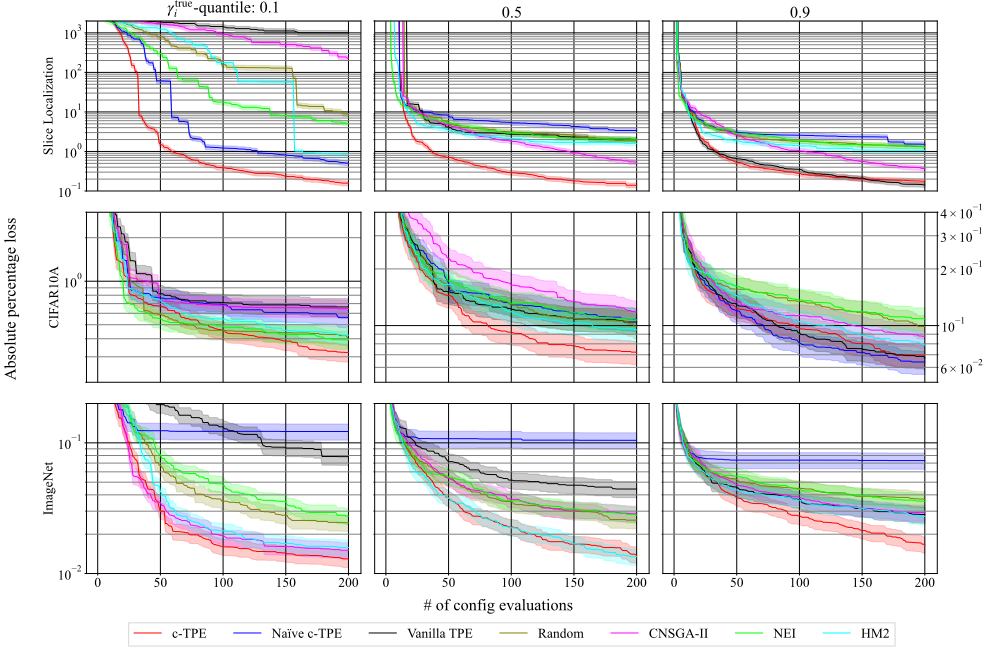
For Slice Localization of HPOlib (Top row), c-TPE outperforms the other methods. Furthermore, its performance almost coincides with that of the vanilla TPE in γ true i = 0.9 and it implies that our method gradually decays the priority of each constraint as γ true i becomes larger. In fact, the na¨ıve c-TPE does not exhibit stability when the constraint level changes as it does not consider the priority of each constraint and the objective. This result empirically validates Theorem 1.
4.3 Average Rank over Number of Evaluations
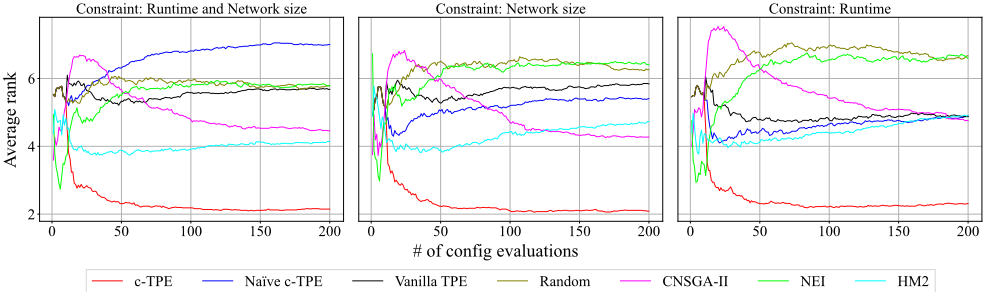
This experiment demonstrates how c-TPE performance improves compared to the other methods over the number of evaluations. Table 2 presents the numbers of wins/loses/ties and statistical significance by the Wilcoxon signed-rank test and Figure 4 shows the average rank over 81 settings (9 benchmarks × 9 quantiles).
According to Figure 4, c-TPE quickly takes the top and keeps the rank until the end. From the figures, we can see that CNSGA-II improves in rank as the number of evaluations grows. In fact, since such slow-starting is often the case for evolutionary algorithms such as CMA-ES [Loshchilov and Hutter, 2016], the quick convergence achieved by c-TPE is appealing. For the multiple-constraint setting (Right), while the na¨ıve c-TPE is worse than random search due to the small overlap, c-TPE overcomes this problem as discussed in Section 3.2. Table 2 confirmed the anytime performance of cTPE by the statistical test over all the settings. All results on individual settings and quantile-wise average rank are available in Appendices H and I.
5 RelatedWork &Discussion
ECI was introduced by Gardner et al. [2014] and Gelbart et al. [2014]. Furthermore, there are various extensions of these prior works. For example, NEI is more robust to the noise caused in experiments [Letham et al., 2019] and SCBO is scalable to high dimensions [Eriksson and Poloczek, 2021]. Another technique for constrained BO is entropy search, such as predictive entropy search [Lobato et al., 2015; GarridoMerch´an et al., 2023] and max-value entropy search [Perrone et al., 2019]. They choose the next configuration by approximating the expected information gain on the value of the constrained minimizer. While entropy search could outperform c-TPE on multimodal functions by leveraging the global search nature, slow convergence due to the global search nature and the expensive query cost hinder practical usages. Note that as the implementations of these methods are not provided in the aforementioned papers except NEI, we used only NEI in the experiments. The major advantages of TPE over standard GP-based BOs, used by all of these papers, are more natural handling of categorical and conditional parameters (see Appendix F) and easier integration of cheap-toevaluate partial observations due to the linear time complexity with respect to |D|. The concept of the integration of partial observations and its results, which showed a further acceleration of c-TPE, are available in Appendix C.
| Constraints | Runtime & Network size | Network size | Runtime | |||||||||
|---|---|---|---|---|---|---|---|---|---|---|---|---|
| Methods / # of configs | 50 | 100 | 150 | 200 | 50 | 100 | 150 | 200 | 50 | 100 | 150 | 200 |
| Na¨ıve c-TPE | 77/3/1 | 79/0/2 | 78/0/3 | 79/0/2 | 75/4/2 | 77/1/3 | 76/1/4 | 80/0/1 | 66/8/7 | 71/5/5 | 70/3/8 | 69/2/10 |
| Vanilla TPE | 73/7/1 | 75/5/1 | 72/3/6 | 73/4/4 | 69/10/2 | 74/6/1 | 74/3/4 | 72/6/3 | 62/12/7 | 67/10/4 | 62/6/13 | 60/9/12 |
| Random | 80/0/1 | 81/0/0 | 81/0/0 | 80/0/1 | 80/0/1 | 79/2/0 | 80/1/0 | 81/0/0 | 80/0/1 | 78/0/3 | 79/0/2 | 81/0/0 |
| CNSGA-II | 80/0/1 | 79/0/2 | 76/1/4 | 75/2/4 | 77/3/1 | 78/1/2 | 75/2/4 | 75/1/5 | 74/1/6 | 76/0/5 | 74/0/7 | 74/0/7 |
| NEI | 79/1/1 | 81/0/0 | 81/0/0 | 81/0/0 | 79/1/1 | 80/1/0 | 80/1/0 | 81/0/0 | 77/0/4 | 78/0/3 | 79/0/2 | 81/0/0 |
| HM2 | 74/5/2 | 77/3/1 | 77/1/3 | 76/2/3 | 76/4/1 | 78/2/1 | 76/2/3 | 78/0/3 | 71/4/6 | 73/2/6 | 67/3/11 | 70/2/9 |
Also in the evolutionary algorithm (EA) community, constrained optimization has been studied actively, such as genetic algorithms (e.g. CNSGA-II [Deb et al., 2002]), CMA-ES [Arnold and Hansen, 2012], or differential evolution [Montes et al., 2006]. Although CMA-ES has demonstrated the best performance among more than 100 methods for various black-box optimization problems [Loshchilov et al., 2013], it does not support categorical parameters, so we did not include it in our experiments. Furthermore, since EAs have many control parameters, such as mutation rate and population size, meta-tuning may be necessary. Another downside of EAs is that it is hard to integrate partial observations because EAs require all the metrics to rank each configuration at each iteration. In general, BO overcomes these difficulties as discussed in Appendix C.
6 Conclusion
In this paper, we introduced c-TPE, a new constrained BO method. Although the AF of constrained BO and TPE could naturally come together using Corollary 1, such a na¨ıve extension fails in some circumstances as discussed in Section 3. Based on the discussion, we modified c-TPE so that the formulation strictly generalizes TPE and falls back to it in settings of loose constraints. Furthermore, we empirically demonstrated that our modifications help to guide c-TPE to overlaps in the top and feasible domains. In our series of experiments on 9 tabular benchmarks and with 27 constraint settings, we first showed that the performance of c-TPE is not degraded over various constraint levels while the other BO methods we evaluated (HM2 and NEI) degraded as constraints became looser. Furthermore, the proposed method outperformed the other methods with statistical significance; however, since we focus only on the tabular benchmarks to enable the stability analysis of the performance variations depending on constraint levels, we discuss other possible situations where c-TPE might not perform well in Appendix E. Since TPE is very versatile and prominently used in several active OSS tools, such as Optuna and Ray, c-TPE will yield direct positive impact to practitioners in the future.
Acknowledgments
The authors appreciate the valuable contributions of the anonymous reviewers and helpful feedback from Edward Bergman and Noor Awad. Robert Bosch GmbH is acknowledged for financial support. The authors also acknowledge funding by European Research Council (ERC) Consolidator Grant "Deep Learning 2.0" (grant no. 101045765). Views and opinions expressed are however those of the authors only and do not necessarily reflect those of the European Union or the ERC. Neither the European Union nor the ERC can be held responsible for them.
@inproceedings{ijcai2023p486,
  title     = {c-TPE: Tree-structured Parzen Estimator with Inequality Constraints for Expensive Hyperparameter Optimization},
  author    = {Watanabe, Shuhei and Hutter, Frank},
  booktitle = {Proceedings of the Thirty-Second International Joint Conference on
               Artificial Intelligence, {IJCAI-23}},
  publisher = {International Joint Conferences on Artificial Intelligence Organization},
  editor    = {Edith Elkind},
  pages     = {4371--4379},
  year      = {2023},
  month     = {8},
  note      = {Main Track},
  doi       = {10.24963/ijcai.2023/486},
  url       = {https://doi.org/10.24963/ijcai.2023/486},
}
TY - CPAPER TI - c-TPE: Tree-structured Parzen Estimator with Inequality Constraints for Expensive Hyperparameter Optimization AU - Watanabe, Shuhei AU - Hutter, Frank T2 - Proceedings of the Thirty-Second International Joint Conference on Artificial Intelligence, IJCAI-23 PB - International Joint Conferences on Artificial Intelligence Organization PY - 2023 SP - 4371 EP - 4379 DO - 10.24963/ijcai.2023/486 UR - https://doi.org/10.24963/ijcai.2023/486 ER -Copied
Machine-readable versions of this paper, for tools and AI agents:





