
G2Pxy: Generative Open-Set Node Classification on Graphs with Proxy Unknowns
Proceedings of the Thirty-Second International Joint Conference on Artificial Intelligence. Main Track. Pages 4576-4583.
https://doi.org/10.24963/ijcai.2023/509
Keywords
- Machine Learning: ML: Classification
- Data Mining: DM: Mining graphs
Abstract
Node classification is the task of predicting the labels of unlabeled nodes in a graph. State-of-the-art methods based on graph neural networks achieve excellent performance when all labels are available
during training. But in real-life, models are of ten applied on data with new classes, which can lead to massive misclassification and thus significantly degrade performance. Hence, developing
open-set classification methods is crucial to determine if a given sample belongs to a known class. Existing methods for open-set node classification generally use transductive learning with part or all
of the features of real unseen class nodes to help with open-set classification. In this paper, we propose a novel generative open-set node classification method, i.e., G2Pxy, which follows a stricter inductive learning setting where no information about unknown classes is available during training and validation. Two kinds of proxy unknown nodes, inter-class unknown proxies and external unknown proxies are generated via mixup to efficiently anticipate the distribution of novel classes. Using the generated proxies, a closed-set classifier can be transformed into an open-set one, by augmenting it with an extra proxy classifier. Under the constraints
of both cross entropy loss and complement entropy loss, G2Pxy achieves superior effectiveness for unknown class detection and known class classification, which is validated by experiments on bench
mark graph datasets. Moreover, G2Pxy does not have specific requirement on the GNN architecture and shows good generalizations.
- [Bendale and Boult, 2016] Abhijit Bendale and Terrance E Boult. Towards open set deep networks. In IEEE con- ference on computer vision and pattern recognition, pages 1563-1572, 2016.
- [Chen et al., 2018] Hao-Yun Chen, Pei-Hsin Wang, Chun- Hao Liu, Shih-Chieh Chang, Jia-Yu Pan, Yu-Ting Chen, Wei Wei, and Da-Cheng Juan. Complement objective training. In International Conference on Learning Rep- resentations, 2018.
- [Ge et al., 2017] ZongYuan Ge, Sergey Demyanov, Zetao Chen, and Rahil Garnavi. Generative openmax for multi- class open set classification. In British Machine Vision Conference. BMVA Press, 2017.
- [Guo et al., 2017] Chuan Guo, Geoff Pleiss, Yu Sun, and Kilian Q Weinberger. On calibration of modern neural net- works. In International conference on machine learning, pages 1321-1330, 2017.
- [Hamilton et al., 2017] Will Hamilton, Zhitao Ying, and Jure Leskovec. Inductive representation learning on large graphs. Neural information processing systems, 30, 2017.
- [Han et al., 2022] Xiaotian Han, Zhimeng Jiang, Ninghao Liu, and Xia Hu. G-mixup: Graph data augmentation for graph classification. In International Conference on Ma- chine Learning, pages 8230-8248. PMLR, 2022.
- [Hein et al., 2019] Matthias Hein, Maksym An- driushchenko, and Julian Bitterwolf. Why relu networks yield high-confidence predictions far away from the train- ing data and how to mitigate the problem. In IEEE/CVF Conference on Computer Vision and Pattern Recognition, pages 41-50, 2019.
- [Hendrycks and Gimpel, 2017] Dan Hendrycks and Kevin Gimpel. A baseline for detecting misclassified and out- of-distribution examples in neural networks. International Conference on Learning Representations, 2017.
- [Kipf and Welling, 2017] Thomas N Kipf and Max Welling. Semi-supervised classification with graph convolutional networks. In International Conference on Learning Rep- resentations, 2017.
- [Liu et al., 2021] Zemin Liu, Yuan Fang, Chenghao Liu, and Steven CH Hoi. Relative and absolute location embedding for few-shot node classification on graph. In AAAI Con- ference on Artificial Intelligence, volume 35, pages 4267- 4275, 2021.
- [Neal et al., 2018] Lawrence Neal, Matthew Olson, Xiaoli Fern, Weng-Keen Wong, and Fuxin Li. Open set learn- ing with counterfactual images. In European Conference on Computer Vision, pages 613-628, 2018.
- [Perera et al., 2020] Pramuditha Perera, Vlad I Morariu, Ra- jiv Jain, Varun Manjunatha, Curtis Wigington, Vicente Ordonez, and Vishal M Patel. Generative-discriminative feature representations for open-set recognition. In IEEE/CVF Conference on Computer Vision and Pattern Recognition, pages 11814-11823, 2020.
- [Scheirer et al., 2012] Walter J Scheirer, Anderson de Rezende Rocha, Archana Sapkota, and Terrance E Boult. Toward open set recognition. IEEE transac- tions on pattern analysis and machine intelligence, 35(7):1757-1772, 2012.
- [Shu et al., 2017] Lei Shu, Hu Xu, and Bing Liu. Doc: Deep open classification of text documents. In Proceedings of the 2017 Conference on Empirical Methods in Natural Language Processing, pages 2911-2916, 2017.
- [Tang et al., 2021] Yan Tang, Zhijin Zhao, Chun Li, and Xueyi Ye. Open set recognition algorithm based on con- ditional gaussian encoder. Mathematical Biosciences and Engineering, 18(5):6620-6637, 2021.
- [Veličković et al., 2018] Petar Veličković, Guillem Cucurull, Arantxa Casanova, Adriana Romero, Pietro Liò, and Yoshua Bengio. Graph attention networks. In Interna- tional Conference on Learning Representations, 2018.
- [Verma et al., 2019] Vikas Verma, Alex Lamb, Christopher Beckham, Amir Najafi, Ioannis Mitliagkas, David Lopez- Paz, and Yoshua Bengio. Manifold mixup: Better rep- resentations by interpolating hidden states. In Interna- tional Conference on Machine Learning, pages 6438- 6447, 2019.
- [Wang et al., 2020] Zifeng Wang, Batool Salehi, Andrey Gritsenko, Kaushik Chowdhury, Stratis Ioannidis, and Jen- nifer Dy. Open-world class discovery with kernel net- works. In IEEE International Conference on Data Mining, pages 631-640, 2020.
- [Wong et al., 2021] Randy Yee Man Wong, Christy MK Cheung, Bo Xiao, and Jason Bennett Thatcher. Standing up or standing by: Understanding bystanders' proactive re- porting responses to social media harassment. Information Systems Research, 32(2):561-581, 2021.
- [Wu et al., 2020] Man Wu, Shirui Pan, and Xingquan Zhu. Openwgl: Open-world graph learning. In IEEE interna- tional conference on data mining, pages 681-690, 2020.
- [Wu et al., 2021] Man Wu, Shirui Pan, and Xingquan Zhu. Openwgl: open-world graph learning for unseen class node classification. Knowledge and Information Systems, pages 1-26, 2021.
- [Yu et al., 2017] Yang Yu, Wei-Yang Qu, Nan Li, and Zimin Guo. Open-category classification by adversarial sample generation. In International Joint Conference on Artificial Intelligence, pages 3357-3363, 2017. IJCAI
- [Zheng et al., 2020] Chuanpan Zheng, Xiaoliang Fan, Cheng Wang, and Jianzhong Qi. Gman: A graph multi-attention network for traffic prediction. In AAAI Conference on Artificial Intelligence, volume 34, pages 1234-1241, 2020.
- [Zhou et al., 2021] Da-Wei Zhou, Han-Jia Ye, and De- Chuan Zhan. Learning placeholders for open-set recog- nition. In the IEEE/CVF Conference on Computer Vision and Pattern Recognition, pages 4401-4410, 2021.
- [Zhu et al., 2022] Qi Zhu, Chao Zhang, Chanyoung Park, Carl Yang, and Jiawei Han. Shift-robust node classifi- cation via graph adversarial clustering. arXiv preprint arXiv:2203.15802, 2022.
References were extracted automatically from the PDF and may contain errors.
Full text extracted automatically from the PDF; figures, tables and equations may differ. The PDF is the version of record.
1 Introduction
Node classification is the task of assigning labels (categories) to unlabeled graph nodes. This task has many important applications such as traffic state prediction [Zheng et al., 2020], and completing user profiles in social networks [Wong et al., 2021]. Graph Neural Network (GNN) based methods [Zhu et al., 2022; Liu et al., 2021] achieve state-of-theart performance for this problem. However, they generally assume that the full set of labels (known classes) is available for training. Unfortunately, this assumption does not hold in many practical scenarios because of unforeseen factors. For instance, a trained GNN may be applied on samples from a research social network where researchers may have published in new conferences that were unseen in training. When facing samples of unknown classes, typical GNN methods [Kipf and Welling, 2017; Veliˇckovi´c et al., 2018; Hamilton et al., 2017] will incorrectly label nodes using known classes, which can considerably degrade performance. Hence, building models that can classify samples from known classes and reject samples from unknown classes is a key issue, which is known as the open set classification problem.
∗Corresponding author.
Recent techniques that have been designed to address the open-set node classification problem [Wu et al., 2021] presume that a model will be more confident in its predictions for closed-set samples than for open-set samples. Relying on this assumption, a threshold is applied on a model's confidence scores to separate unknown samples from known ones. Though this approach is intuitive [Hendrycks and Gimpel, 2017], it often fails because deep neural networks tend to be over-confident in input samples and may output high confidence scores even for an unknown input [Hein et al., 2019; Guo et al., 2017; Bendale and Boult, 2016; Scheirer et al., 2012]. Moreover, finding an optimal threshold to separate known from unknown classes is hard and timeconsuming [Perera et al., 2020; Ge et al., 2017].
Another critical challenge for open-set classification is the lack of open-set data. It is hard to collect open-set data due to the very large diversity. However, most of the prior solutions [Wu et al., 2020] follow a transductive learning approach, i.e., suppose that part or all of the features of the real unseen class samples can be observed and used to help with open-set learning. This setting is not suitable for most realworld applications. To alleviate this issue, several studies on image classification have attempted to estimate the distribution of unknown classes and calibrate a network's confidence. For example, G-OpenMax [Ge et al., 2017] utilizes a GAN to generate unknown samples for training an image classifier. Neal et al. [Neal et al., 2018] introduced a counterfactual image generation method to produce image samples lying between decision boundaries through GANs. Perera et al. [Perera et al., 2020] combined self-supervision and a generative model to enhance the optimal closed-set features and to effectively identify open-set samples. PROSER [Zhou et al., 2021] learns placeholders to prepare for unknown classes by allocating placeholders for both data and classifier, which yields high disparity.
Motivated by the above studies, we propose a novel Generative open-set node classification method on Graphs with Proxy unknowns (G 2Pxy for short). Under the constraints of not being able to obtain open-set data, G 2Pxy first generates pseudo unknown class nodes (unknown proxies) via mixup [Verma et al., 2019; Han et al., 2022], to mimic the distribution of unknown classes using only the closedset graph for learning. Two kinds of proxy unknown nodes, inter-class unknown proxies and external unknown proxies, are generated. Using the generated proxies, a closed-set classifier can be transformed into an open-set one, by augmenting it with an extra proxy classifier. The whole model is optimized under the supervision of cross entropy and tailored complement entropy loss [Chen et al., 2018] together, and can then adaptively perform class-specific classification and detection during testing. Moreover, G 2Pxy can be adopted by different kinds of GNNs and shows good generalizations. The contributions of this paper are summarized as follows:
- A novel method G 2Pxy for open-set node classification is proposed with efficient unknown proxy generation and open-set classifier learning, under the constraint of both cross entropy and complement entropy loss. To the best of our knowledge, G 2Pxy is the first generative method for open-set graph learning.
- No open-set data (samples of unknown classes or any side information of unknown classes) is required during training and validation. G 2Pxy has an explicit classifier for unknown and does not require tuning a threshold.
- G 2Pxy does not have specific requirement on the GNN architecture, and shows good generalizations. Using mixup as the generative method also ensures the efficiency, due to the acceptable extra computation cost.
- Experiments on benchmark graph datasets demonstrate the good performance of G 2Pxy.
2 ProblemDefinition &Preliminary
This paper focuses on the node classification problem for a graph. Consider a graph denoted as G = (V,E,X), where V = {vi|i = 1, . . . ,N} is a set of N nodes in the graph. E = {ei,j|i, j = 1, . . . ,N. i ̸= j} is a set of edges between pairs of nodes vi and vj. X ∈ RN×d denotes the feature matrix of nodes, and d is the dimension of node features. xi ∈ X indicates the feature vector associated with each node vi. The topological structure of G is represented as an adjacency matrix A ∈ RN×N , where Ai,j = 1 if the nodes vi and vj are connected, i.e., ∃ei,j ∈ E, otherwise Ai,j = 0. Y ∈ RN×C is the label matrix of G, where C is the already-known node classes. If node vi ∈ V is associated with a label c, yi,c = 1, otherwise, yi,c = 0.
For a typical closed-set node classification problem, a GNN encoder fθg takes node features X and adjacency matrix A as input, aggregates the neighborhood information and outputs representations. Then, a classifier fθc is used to classify the nodes into C already-known classes. The GNN encoder and the classifier are optimized to minimize the expected risk [Yu et al., 2017] in Eq. (1), with the assumption that test data Dte and train data Dtr share the same feature space and label space, i.e.,
where H is the hypothesis space, I(·) is the indicator function which outputs 1 if the expression holds and 0 otherwise. Generally, it can be optimized with cross-entropy to discriminate between known classes.
In open-set node classification problem, given a graph G = (V,E,X), Dtr = (X, Y ) denotes the train nodes. Dte = (Xte, Yte) is the test nodes, where Xte = S ∪ U, Yte = {1, . . . , C, C+1, . . .}. S is the set of nodes that belong to seen classes that already appeared in Dtr and U is the set of nodes that do not belong to any seen class (i.e., unknown class nodes). Open-set node classification aims to learn a (C + 1)- class classifier fθc that f(θg, θc;Xte,A) : {Xte,A} → Y, Y = {1, . . . , C, unknown}, with the minimization of the expected risk [Yu et al., 2017]:
where A is the adjacency matrix for Xte. The predicted class unknown ∈ Y contains a group of novel categories, which may contain more than one class. Thus, the overall risk aims to classify known classes while also detecting the samples from unseen categories as class unknown.
From close-set to open-set classifier, an intuitive way is thresholding [Hendrycks and Gimpel, 2017]. Taking the max output probability as confidence score, i.e., conf = maxc=1,...,Cfc(x,A), it assumes the model is more confident in closed-set instances than open-set ones. Then we can extend a closed-set classifier by
where τ is a threshold. However, due to the overconfidence phenomena of deep neural networks, the output confidence of known and unknown is both high [Bendale and Boult, 2016]. As a result, tuning a threshold that well separates known from unknown is hard and time-consuming.
Differently, the approach presented in this paper utilizes an additional proxy classifier to detect the unknown class nodes, with well-designed generated unknown proxies to facilitate the model training. There are advantages of adding a class instead of optimizing a threshold as in previous methods [Shu et al., 2017; Wu et al., 2020; Bendale and Boult, 2016], since it does not require real open-set samples in validation and also eliminates the difficulty of tuning the threshold.
3 Methodology
Facing the difficulty of closed-set classifier calibration, we need proxy unknown nodes to foresee the distribution of unknown classes and prepare the open-set model for novel classes.
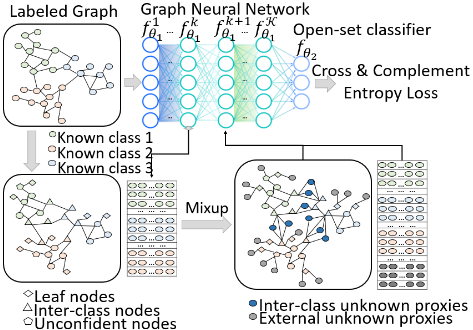
The overall framework of G 2Pxy is introduced in Fig. 1. Specifically, a GNN encoder fθ1 takes node features X and adjacency matrix A as input, aggregates the neighborhood information and outputs representation hki for each node vi in its k-th layer, k = 1, . . . ,K. K is the total number of layers. Thus, in the k-th layer, for node vi, the GNN encoder aggregates neighbor information from the k-1 layer into a neighborhood representation:
where hki ∈ Rdk is the hidden representation at the k-th layer, Ni is the neighborhood of node vi and h0 = X.
Meanwhile, we mimic novel patterns by generating proxy unknown nodes through manifold mixup [Verma et al., 2019; Han et al., 2022]. Targeted node pairs are selected and mixed up at the middle layer of the GNN, and two kinds of proxies are created: inter-class unknown proxies that separate known classes from each other and external unknown proxies that separate known from unknown. Generated proxies and original known class nodes are input into the remaining layers together to learn discriminative representations. Then, a classifier fθ2 is learned to classify the nodes into C + 1 classes, achieving open-set node classification.
To conclude, the proposed G 2Pxy method consists of two main modules: 1) a proxy node generation module to create proxy unknown class nodes; 2) an open-set classifier learning module to guarantee the classification of known classes and the rejection of the unknown class. We introduce them in details.
3.1 Proxy Node Generation
As out-of-distribution nodes are unavailable during training, we propose an effective way of generating proxy unknown nodes, which are designed to be located at the boundaries between different classes. These nodes are utilized in the learning process to supervise and tell apart unknown nodes from known ones. Specifically, two different kinds of proxies are produced, inter-class unknown proxies and external unknown proxies. We adopt manifold mixup [Verma et al., 2019] as our generation method, due to its efficiency and good interpretability [Han et al., 2022].
Inter-Class Unknown Proxies
For a well-trained classifier, features of nodes that belong to the same categories are close to each other, while those from different classes are distant. Ideally, clear boundaries separate the different classes. Since nodes whose features are close to the boundaries are more likely to be less representative to their own classes, we decided to generate proxy unknowns using nodes near the boundary regions. Thus, samples that belong to different classes but are close to each other are ideal node pairs for proxy generation, i.e., node pairs where the two nodes are in different classes but have an edge between them. In details, given two connected nodes from different categories, i.e., {(xi, yi), (xj, yj)}, where yi ̸= yj and aij = 1, their embeddings in the k-th layer are hki and hkj , obtained by giving the graph to the network f 1∼k θ1 . The inter-class unknown proxy (˜xi, ˜ yi) are calculated by Eq. (5).
where α ∈ [0, 1] is randomly sampled from a Beta distribution and the value of α is around 0.5. ˜ yi = C + 1 is the category index of ˜xi, indicating it belongs to the unknown class. Two edges between (xi, ˜xi) and (xj, ˜xi) are also added into the graph. We denote the set of generated inter-class proxies samples as Xint. The purpose of Xint is to simulate the distribution of unknown class nodes that exist between known classes. The mixed hidden representation ˜xi is then passed to f k+1∼K θ1 to yield the final representation ˜hKi = f K θ1 (˜xi).
External Unknown Proxies
Besides the inter-class unknown proxies, external unknown proxies are further generated to mimic the unknown distributions at the periphery. We use the peripheral nodes from each known class and their corresponding class center to generate the external unknown proxies.
Specifically, the peripheral nodes are selected according to two rules. Rule 1 is to select the leaf nodes of known classes, i.e., xi ∈ Xtr, s.t. ∑j Ai,j = 1. Rule 2 is to collect the nodes with low classification confidence, i.e., the nodes which have the top T least confident scores are selected in each known class. In this way, both structure-based and semanticbased peripheral nodes are picked out. We record the set of peripheral nodes as Xper.
Moreover, the embedding of class centers in the k-th layer can be calculated according to the ground-truth annotations following Eq. (6):
where Xc denotes the nodes annotated with the class label c. Then, the manifold mixup is applied on peripheral nodes and their corresponding reversed class centers {(xi, yi), (x(yi), yi), xi ∈ Xper, yi ∈ {1, . . . , C}} to obtain the external unknown proxies in the k-th layer, i.e.,
where α > 0 is a hyperparameter to control the distance between the generated samples and the existing known class samples. Edges between (xi, ˜xi), xi ∈ Xper are also added into the graph. We denote the set of generated external unknown proxies as Xext.
3.2 Open-Set Classifier Learning
To handle the diverse compositions of known-unknown categories, it is necessary to extract invariant information from the known and unknown classes. Thus, the backbone GNN network fθ1 is shared by the C + 1 classes to learn class distributions and node representations.
Further, to calibrate closed-set (known classes) classifier to open-set classifier, an extra category is added to the last classification layer for unknown prediction. Suppose that the weights of the closed-set classifier is wclose ∈ RdK×C where dK is the dimension of the embeddings in the last layer of GNN, the open-set classifier is the combination of the closed-set classifier and the proxy classifier, i.e., θ2 = [wclose,wproxy] ∈ RdK×(C+1) , where wproxy ∈ RdK×1 is the weights w.r.t. the proxy classifier. Here, the bias term is omitted for simplicity. Then, the integrated classifier is trained with the original known class samples and the generated proxy samples, i.e., Dtr = Dtr ∪ (Xpxy, YC+1), Xpxy = Xint ∪Xext, with the cross entropy loss in Eq. (8):
where ˆ yi = softmax(fθ2 (fθ1 (xi))) is the output vector of the open-set classifier for the input node xi. lCrE denotes the cross entropy loss, i.e., lCrE(ˆ yi, yi) = -yi log ˆ yi .
Though the cross-entropy loss in Eq. (8) exploits mostly the information from the ground-truth class for maximizing data likelihood, the influence from complement classes (i.e., incorrect classes) has been largely ignored [Chen et al., 2018]. Thus, we further adopt complement entropy [Chen et al., 2018] to complement the softmax cross entropy by neutralizing the effects of complement classes.
The complement entropy loss LCoE is defined as the average of sample-wise entropies over complement classes, i.e.,
where ˆ yi,c denotes the predicted probability of node xi belonging to class c.
For the needs of the generative open-set classification method G 2Pxy, we further modify the above complement entropy according to the data distribution so that it better fits the task. Specifically, for generated unknown proxies, we minimize their original complement entropy, i.e., minimize the average of entropy over the C known classes, since the generated proxies could be adjacent to any of the known class. For the known class nodes, they are mostly adjacent to the generated proxies, i.e., the C + 1 class, thus we push the proxy classifier to output the second-largest probability for nodes from known classes. According to this consideration, we propose a tailored complement entropy loss for G 2Pxy as follows:
where ˆ yi/yi represents the prediction logits after removing the probability of its ground-truth label. The first term helps to reduce the misclassification of known class nodes for other known classes. It is believed that with the help of loss in Eq. (10), the open-world classifier fθ2 can classify nodes of known classes to their real categories, and use the proxy classifier to set an appropriate boundary to tell apart the known and the unknown. Finally, the total loss of G 2Pxy is a combination of cross entropy and the tailored complement entropy loss, i.e.,
where λ2 > 0 is the hyperparameter to balance these two losses.
In the test phase, the well learned open-set classifier will be applied to a test node xi ∈ Dte, and outputs C + 1 probabilities ˆ yi ∈ R(C+1)×1 . We choose the largest probability and give the related class label as prediction. Thus, xi will be detected as unknown class sample if the predicted label is C + 1.
4 Experiments
Experiments were conducted to validate the performance of G 2Pxy. These experiments include: open-set node classification comparison, ablation study, and use case. Codes are available online 1 .
Datasets. Experiments to evaluate the performance for open-set node classification were mainly carried out on four benchmark graph datasets [Wu et al., 2020; Zhu et al., 2022], namely Cora 2 , Citeseer 3 , DBLP 4 , PubMed 5 , which are widely used citation network datasets. Statistics are presented in Table 1.
| Dataset | Nodes | Edges | Features | Labels |
|---|---|---|---|---|
| Cora | 2708 | 5429 | 1433 | 7 |
| Citeseer | 3312 | 4732 | 3703 | 6 |
| DBLP | 17716 | 105734 | 1639 | 4 |
| PubMed | 19717 | 44325 | 500 | 3 |
1 https://github.com/ejfomxhue2o3239djnwkk/G2Pxy
2 https://graphsandnetworks.com/the-cora-dataset/
3 https://networkrepository.com/citeseer.php
4 https://dblp.uni-trier.de/xml/
5 https://pubmed.ncbi.nlm.nih.gov/download/
Metrics. Accuracy andMacro-F1 are used for performance evaluation.
Implementation Details. Generally, G 2Pxy adopts GCN [Kipf and Welling, 2017] as the backbone neural network for experimental evaluation unless otherwise specified. The GCN is configured with two hidden GCN layers in the dimensions of 512 and 128, followed by an additional multilayer perceptron layer of size 64. G 2Pxy is implemented with PyTorch and the networks are optimized using stochastic gradient descent with a learning rate of 1e-3 . The balance parameters λ1 and λ2 are chosen by a grid search in the interval from 10-2 to 102 with a step size of 101 .
The baseline methods are evaluated according to the instructions reported in the original papers with the same parameter configuration unless otherwise specified, and the best results are selected. For each experiment, the baselines and the proposed method were applied using the same training, validation, and testing datasets. The hyperparameters were tuned to get the best performance on the validation set.
All the experiments were conducted on a workstation equipped with an Intel(R) Xeon(R) Gold 6226R CPU and an Nvidia A100.
Test Settings. Compared to existing studies focusing on open-set classification [Wu et al., 2021; Tang et al., 2021; Wang et al., 2020], the evaluation framework is extended. Two kinds of open-set classification evaluations were conducted to consider short or long distances between known classes and unknown classes, i.e., near open-set classification and far open-set classification. Besides, a discussion is provided of different settings in terms of the availability of side information of unknown class samples during training and validation, i.e., the inductive learning setting and the transductive learning setting.
Specifically, in the near open-set classification experiment, for each dataset, the data of several classes were held out as the unknown classes for testing and the remaining classes were considered as the known classes. 70% of the known class nodes were sampled for training, 10% for validation and 20% for testing. In the far open-set classification experiment, nodes from other datasets were used as unknown class samples for testing, instead of the nodes from the same dataset used in training. In experiments with inductive learning setting, there is not any information about the real unknown class (such as the features xi or side information of unknown classes) used during training or evaluation, while under the transductive learning setting, the whole graph (including unlabeled real unknown class nodes) are input during model training or validation.
Baselines. The following methods are used as the baselines for the open-set classification comparison.
- GCN soft: GCN [Kipf and Welling, 2017] is adopted for graph learning, where a softmax layer is used as the final output layer. It has no capability of recognizing the unknown classes.
- GCN sig: This baseline replaces the softmax layer of GCN with multiple 1-vs-rest of sigmoids as the final out-
| Methods | Cora | Citeseer | DBLP | Pubmed | ||||
|---|---|---|---|---|---|---|---|---|
| Acc | F1 | Acc | F1 | Acc | F1 | Acc | F1 | |
| GCN soft | 70.6 | 67.6 | 44.6 | 38.9 | 63.8 | 59.2 | 28.9 | 29.9 |
| GCN sig | 69.2 | 64.7 | 45.3 | 44.5 | 63.5 | 58.7 | 28.9 | 29.8 |
| GCN soft τ | 73.6 | 73.8 | 57.3 | 54.5 | 65.0 | 62.4 | 49.7 | 48.6 |
| GCN sig τ | 79.7 | 80.1 | 62.1 | 54.6 | 69.2 | 68.2 | 45.1 | 46.0 |
| GCN Opmax | 74.6 | 75.1 | 56.2 | 54.5 | 67.2 | 67.2 | 49.1 | 48.7 |
| GCN DOC | 77.8 | 78.1 | 66.0 | 56.7 | 69.9 | 69.2 | 45.6 | 46.2 |
| GCN PROSER | 83.2 | 83.7 | 73.7 | 63.6 | 71.7 | 72.6 | 71.0 | 58.4 |
| OpenWGL | 78.1 | 78.9 | 64.1 | 60.8 | 71.4 | 72.2 | 65.3 | 63.4 |
| G 2Pxy | 84.3 | 84.8 | 75.5 | 71.0 | 77.3 | 79.0 | 73.7 | 70.2 |
put layer, which still does not have the capability of rejecting the unknown classes.
- GCN soft τ: Based on GCN soft, a probability threshold chosen in {0.1, 0.2, . . . , 0.9} is used for the classification of each class .
- GCN sig τ: Similar to GCN soft τ, a threshold is combined to GCN sig.
- GCN Opmax: Openmax [Bendale and Boult, 2016] is an open-set recognition model based on "activation vectors". Extreme value distribution is used to calibrate softmax scores to Openmax scores, which are then used for open-set classification.
- GCN DOC: DOC [Shu et al., 2017] is an open-world classification method for text classification. It uses multiple 1-vs-rest of sigmoids as the final output layer and defines an automatic threshold setting mechanism. GCN is combined with DOC to allow comparison with the proposed model.
- GCN PROSER: PROSER [Zhou et al., 2021] is a novel and highly effective open-set recognition method used in the field of image processing. We paired it with GCN for graph-based comparison.
- OpenWGL: OpenWGL [Wu et al., 2020] employs an uncertainty loss in the form of graph reconstruction loss on unlabeled data and using an adaptive threshold to detect the unknown class samples.
4.1 Open-Set Node Classification Comparison
Since real-world scenarios are complex, where seen and unseen differs in diverse tasks, we evaluate our model from two aspects: near open-set classification, and far open-set classification.
Near Open-Set Classification
Table 2 and 3 list the accuracy and macro-F1 scores of the methods for the near open-set node classification task, where the last class of each dataset is set as the unknown class (i.e. u=1) and the remaining classes are used to train the model. The results in Table 2 were obtained under the inductive learning setting, where there is no side information about the real unknown class samples available during training or validation. The results in Table 3 are obtained under the transductive learning setting, i.e., the features of unknown class nodes are used to facilitate the model training or validation.
| Methods | Cora | Citeseer | DBLP | Pubmed | ||||
|---|---|---|---|---|---|---|---|---|
| Acc | F1 | Acc | F1 | Acc | F1 | Acc | F1 | |
| GCN soft | 70.8 | 68.2 | 44.7 | 38.9 | 62.9 | 57.0 | 29.2 | 29.7 |
| GCN sig | 68.8 | 64.5 | 44.6 | 40.1 | 63.4 | 59.2 | 29.0 | 29.5 |
| GCN soft t | 78.1 | 78.9 | 67.3 | 57.0 | 67.3 | 67.7 | 68.9 | 27.2 |
| GCN sig t | 78.3 | 78.5 | 65.4 | 55.3 | 71.4 | 71.5 | 69.0 | 27.2 |
| GCN Opmax | 77.2 | 76.9 | 57.5 | 56.7 | 69.0 | 70.6 | 55.0 | 52.1 |
| GCN DOC | 77.3 | 77.9 | 65.1 | 55.3 | 71.7 | 72.0 | 68.4 | 34.2 |
| GCN PROSER | 84.7 | 83.6 | 74.3 | 66.6 | 75.3 | 71.6 | 72.8 | 60.8 |
| OpenWGL | 83.3 | 83.5 | 70.0 | 65.4 | 74.3 | 74.2 | 71.2 | 68.0 |
| G 2Pxy | 90.7 | 89.7 | 76.3 | 71.8 | 77.5 | 79.5 | 78.0 | 73.4 |
It is observed from these results that G 2Pxy outperforms the baselines on the datasets under both the inductive learning and transductive learning settings. This shows that G 2Pxy can better differentiate between a known class and an unknown class, though they are similar to each other. Specifically, G 2Pxy achieves an average of 3.70% improvement over the second-best method (GCN PROSER) in terms of accuracy, and an average of 9.60% improvement in terms of F1 score on the four datasets, under the inductive learning setting. Also, G 2Pxy achieves 5.01% and 11.25% improvements on average in terms of accuracy and F1 on the four datasets under the transductive learning setting, respectively. Furthermore, by comparing Table 2 and Table 3, it is observed that the involving of real unknown class information during training or validation benefits the model, which is reasonable.
Besides, we show the detailed classification accuracy in terms of known classes (i.e. in-distribution classification, ind for short) and unknown classes (i.e. out-of-distribution classification, ood for short) respectively, in Table 4. The experiment was conducted under the same setting of Table 2. It shows that in order to gain the ability of unknown class detection, there is a slight decrease in the performance of known class classification, i.e. from 86.9% to 82.5% on average, comparing G 2Pxy to closed-set classification method GCN soft. However, the unknown class detection accuracy is improved from 0% to 73.3% on average, which is remarkable. Compared to other open-set classification methods, such as the globally second best method GCN PROSER, the average performance of unknown-class node detection is improved from 71.7% to 73.3% while the performance of the knownclass classification still gain a certain increase from 78.0% to 82.5% on average.
Far Open-Set Classification
Following the protocol defined in [Perera et al., 2020], the models are trained and validated by all training and validation instances of the original dataset (in-distribution data, IND data). While for testing, instances from another dataset are augmented to the original test set as open-set classes (Outof-distribution data, OOD data). Specifically, three experiments were designed: Cora Citeseer(i.e., Core as IND data and Citeseer as OOD data); Citeseer DBLP (Citeseer as IND, DBLP as OOD), and DBLP Pubmed (DBLP as IND, Pubmed as OOD), to evaluate the performance of the methods for the far open-set classification task. The known-unknown ratio is 1:1 by setting the number of test examples from the OOD dataset to the same number as in the IND dataset.
The results for far open-set classification are shown in Table 5. It is found that G 2Pxy can handle far outof-distribution classes from diverse inputs and achieve a large performance improvement over state-of-the-art method GCN PROSER. Surprisingly, the simple thresholding approach of GCN soft τ achieves comparable performance with G 2Pxy. This inspires us to combine the generative methods with discriminative methods for far open-set classification in future work.
4.2 Ablation Study
We compare variants of G 2Pxy with respect to the generative strategy to demonstrate its effect. The following G 2Pxy variants are designed for comparison.
- G 2Pxy τ: In this variant, generative strategies are removed, so the proxy unknown class is not involved in training. Instead, a threshold τ is set to separate the known and the unknown, which is chosen in {0.1, 0.2, . . . , 0.9}.
- G 2Pxy int: A variant of G 2Pxy with only inter-class unknown proxies.
- G 2Pxy ext: A variant of G 2Pxy with only external unknown proxies.
- G 2Pxy¬CoE: A variant of G 2Pxy that the complement entropy loss (Eq. (10)) is removed.
Table 6 illustrates the results of these four variants and the proposed method. It can be seen that both the generated inter-class unknown proxies and the external unknown proxies matter. The proposed G 2Pxy method achieves significant improvements over G 2Pxy τ without unknown proxies, and also outperforms variants that only use a single type of unknown proxies. Meanwhile, the comparison between G 2Pxy and G 2Pxy¬CoE illustrates that the complement entropy loss is also indispensable.
4.3 Use Case
The proposed model does not have specific requirement on the GNN architecture for classification. Hence, when unknown classes are expected in testing, the proposed proxy node generation mechanism can be integrated and jointly optimized with convergence guarantee. The generated proxies can help find potential unknown class distributions and facilitate the rejection of unknown class samples.
Table 7 compares the performance of the proposed G 2Pxy with other open-set classification baselines, with different GNN architectures, including GCN, GAT and GraphSage. The results confirm the effectiveness and generalization ability of G 2Pxy for open-set node classification.
| Methods | Cora | Citeseer | DBLP | Pubmed | Average | ||||||
|---|---|---|---|---|---|---|---|---|---|---|---|
| ind | ood | ind | ood | ind | ood | ind | ood | ind | ood | overall | |
| GCN soft | 89.7 | 00.0 | 71.8 | 00.0 | 92.9 | 00.0 | 93.2 | 00.0 | 86.9 | 00.0 | 52.0 |
| GCN sig | 87.8 | 00.0 | 73.0 | 00.0 | 92.5 | 00.0 | 93.0 | 00.0 | 86.6 | 00.0 | 51.7 |
| GCN soft τ | 87.2 | 23.3 | 61.4 | 50.5 | 85.6 | 19.2 | 70.4 | 40.3 | 76.2 | 33.3 | 61.4 |
| GCN sig τ | 85.6 | 57.9 | 67.1 | 53.8 | 79.9 | 45.8 | 78.1 | 30.2 | 77.7 | 47.0 | 64.0 |
| GCN Opmax | 86.6 | 30.0 | 60.4 | 49.4 | 85.4 | 27.6 | 73.4 | 38.1 | 76.4 | 36.3 | 61.8 |
| GCN DOC | 84.0 | 54.9 | 67.7 | 63.2 | 79.8 | 48.1 | 78.8 | 30.7 | 77.6 | 49.2 | 64.8 |
| GCN PROSER | 83.2 | 82.7 | 72.5 | 76.0 | 78.2 | 58.0 | 78.0 | 70.2 | 78.0 | 71.7 | 74.9 |
| OpenWGL | 83.4 | 58.6 | 66.4 | 59.9 | 76.6 | 60.0 | 87.9 | 55.2 | 78.6 | 58.4 | 69.7 |
| G 2Pxy | 83.8 | 86.5 | 73.6 | 78.7 | 85.1 | 60.3 | 87.6 | 67.5 | 82.5 | 73.3 | 77.7 |
| Methods | Cora Citeseer | Citeseer DBLP | DBLP PubMed | |||
|---|---|---|---|---|---|---|
| Acc | F1 | Acc | F1 | Acc | F1 | |
| GCN soft | 43.0 | 58.9 | 38.4 | 42.5 | 41.9 | 53.7 |
| GCN sig | 41.6 | 57.5 | 36.3 | 42.1 | 41.6 | 45.2 |
| GCN soft τ | 81.2 | 77.6 | 86.2 | 71.1 | 85.0 | 75.6 |
| GCN sig τ | 69.4 | 51.8 | 68.7 | 48.0 | 79.8 | 69.1 |
| GCN Opmax | 56.2 | 55.1 | 69.6 | 60.3 | 69.6 | 58.7 |
| GCN DOC | 69.4 | 57.8 | 75.5 | 62.3 | 78.0 | 70.7 |
| GCN PROSER | 78.5 | 79.1 | 81.5 | 66.4 | 78.6 | 69.0 |
| OpenWGL | 80.6 | 76.7 | 44.6 | 11.9 | 84.6 | 70.7 |
| G 2Pxy | 81.3 | 80.5 | 87.5 | 74.4 | 86.5 | 72.3 |
| Methods | Cora | Citeseer | DBLP | Pubmed | ||||
|---|---|---|---|---|---|---|---|---|
| Acc | F1 | Acc | F1 | Acc | F1 | Acc | F1 | |
| G 2Pxy τ | 79.6 | 80.5 | 71.4 | 62.8 | 67.1 | 67.1 | 70.0 | 56.5 |
| G 2Pxy int | 84.2 | 84.7 | 75.3 | 70.8 | 75.3 | 76.9 | 73.4 | 68.7 |
| G 2Pxy ext | 84.1 | 84.6 | 75.4 | 70.9 | 75.5 | 74.8 | 71.4 | 66.9 |
| G 2Pxy¬CoE | 84.2 | 84.7 | 75.2 | 69.0 | 76.5 | 77.7 | 70.1 | 47.3 |
| G 2Pxy | 84.3 | 84.8 | 75.5 | 71.0 | 77.3 | 79.0 | 73.7 | 70.2 |
5 Conclusion
This paper introduced a novel generative method for openset node classification, named G 2Pxy. Unlike prior methods, it does not require side-information about unknown classes for model training and validation. Two kinds of proxy unknown nodes, inter-class unknown proxies and external unknown proxies are generated to foresee the distributions of unknown classes. Under constraint of both cross entropy loss and complement entropy loss, G 2Pxy achieves superior effectiveness for unknown class detection and known class classification, which is validated by experiments on benchmark graph datasets. Moreover, G 2Pxy also has good generalization since it has no specific requirement on the GNN architecture. In future work, we will try to find an effective combination of the generative model and discriminative model for near and far open-set node classification.
| Methods | Cora | Citeseer | Dblp | PubMed | ||||
|---|---|---|---|---|---|---|---|---|
| Acc | F1 | Acc | F1 | Acc | F1 | Acc | F1 | |
| GCN τ | 73.6 | 73.8 | 57.3 | 54.5 | 65.0 | 62.4 | 49.7 | 48.6 |
| GCN DOC | 77.8 | 78.1 | 66.0 | 56.7 | 69.9 | 69.2 | 45.6 | 46.2 |
| GCN Opmax | 74.6 | 75.1 | 56.2 | 54.5 | 67.2 | 67.2 | 49.1 | 48.7 |
| GCN G2Pxy | 84.3 | 84.8 | 75.5 | 71.0 | 77.3 | 79.0 | 73.7 | 70.2 |
| GAT τ | 71.6 | 69.2 | 58.9 | 51.1 | 65.4 | 66.6 | 43.2 | 43.7 |
| GAT DOC | 71.1 | 72.6 | 62.4 | 59.5 | 64.2 | 61.8 | 42.1 | 42.9 |
| GAT Opmax | 66.3 | 63.4 | 48.6 | 48.9 | 62.5 | 56.9 | 48.6 | 47.0 |
| GAT G2Pxy | 80.4 | 81.0 | 75.2 | 70.9 | 72.9 | 73.7 | 71.7 | 47.0 |
| G-Sage τ | 72.7 | 72.9 | 63.5 | 51.2 | 64.3 | 64.0 | 46.6 | 46.9 |
| G-Sage DOC | 76.0 | 75.4 | 63.6 | 59.9 | 68.9 | 72.2 | 44.6 | 45.7 |
| G-Sage Opmax | 71.1 | 70.6 | 47.9 | 48.7 | 62.3 | 56.9 | 44.4 | 45.1 |
| G-Sage G2Pxy | 87.2 | 87.3 | 78.6 | 76.9 | 74.4 | 74.7 | 72.8 | 64.9 |
Acknowledgments
This research was supported by National Key R&D Program of China(2021YFB3301500), National Natural Science Foundation of China (62206179, 92270122), Guangdong Provincial Natural Science Foundation (2022A1515010129, 2023A1515012584), University stability support program of Shenzhen (20220811121315001), Shenzhen Research Foundation for Basic Research, China(JCYJ20210324093000002).
@inproceedings{ijcai2023p509,
  title     = {G2Pxy: Generative Open-Set Node Classification on Graphs with Proxy Unknowns},
  author    = {Zhang, Qin and Shi, Zelin and Zhang, Xiaolin and Chen, Xiaojun and Fournier-Viger, Philippe and Pan, Shirui},
  booktitle = {Proceedings of the Thirty-Second International Joint Conference on
               Artificial Intelligence, {IJCAI-23}},
  publisher = {International Joint Conferences on Artificial Intelligence Organization},
  editor    = {Edith Elkind},
  pages     = {4576--4583},
  year      = {2023},
  month     = {8},
  note      = {Main Track},
  doi       = {10.24963/ijcai.2023/509},
  url       = {https://doi.org/10.24963/ijcai.2023/509},
}
TY - CPAPER TI - G2Pxy: Generative Open-Set Node Classification on Graphs with Proxy Unknowns AU - Zhang, Qin AU - Shi, Zelin AU - Zhang, Xiaolin AU - Chen, Xiaojun AU - Fournier-Viger, Philippe AU - Pan, Shirui T2 - Proceedings of the Thirty-Second International Joint Conference on Artificial Intelligence, IJCAI-23 PB - International Joint Conferences on Artificial Intelligence Organization PY - 2023 SP - 4576 EP - 4583 DO - 10.24963/ijcai.2023/509 UR - https://doi.org/10.24963/ijcai.2023/509 ER -Copied
Machine-readable versions of this paper, for tools and AI agents:





