
Recursive Small-Step Multi-Agent A* for Dec-POMDPs
Proceedings of the Thirty-Second International Joint Conference on Artificial Intelligence. Main Track. Pages 5402-5410.
https://doi.org/10.24963/ijcai.2023/600
Keywords
- Agent-based and Multi-agent Systems: MAS: Multi-agent planning
- Planning and Scheduling: PS: Planning under uncertainty
- Planning and Scheduling: PS: Distributed and multi-agent planning
Abstract
We present recursive small-step multi-agent A* (RS-MAA*), an exact algorithm that optimizes the expected reward in decentralized partially observable Markov decision processes (Dec-POMDPs). RS-MAA* builds on multi-agent A* (MAA*), an algorithm that finds policies by exploring a search tree, but tackles two major scalability concerns. First, we employ a modified, small-step variant of the search tree that avoids the double exponential outdegree of the classical formulation. Second, we use a tight and recursive heuristic that we compute on-the-fly, thereby avoiding an expensive precomputation. The resulting algorithm is conceptually simple, yet it shows superior performance on a rich set of standard benchmarks.
- [Amato and Zilberstein, 2009] Christopher Amato and Shlomo Zilberstein. Achieving goals in decentralized POMDPs. In AAMAS, pages 593-600, 2009.
- [Amato et al., 2006] Christopher Amato, Daniel S. Bern- stein, and Shlomo Zilberstein. Optimal fixed-size con- trollers for decentralized POMDPs. In AAMAS MSDM workshop, 2006.
- [Amato et al., 2007] Christopher Amato, Daniel S. Bern- stein, and Shlomo Zilberstein. Optimizing memory- bounded controllers for decentralized POMDPs. In UAI, pages 1-8, 2007.
- [Amato et al., 2009] Christopher Amato, Jilles Steeve Dibangoye, and Shlomo Zilberstein. Incremental policy generation for finite-horizon DEC-POMDPs. In ICAPS, 2009.
- [Amato et al., 2019] Christopher Amato, George Dimitri Konidaris, Leslie Pack Kaelbling, and Jonathan P. How. Modeling and planning with macro-actions in decentral- ized POMDPs. JAIR, 64:817-859, 2019.
- [Barto and Mahadevan, 2003] Andrew G. Barto and Sridhar Mahadevan. Recent advances in hierarchical reinforce- ment learning. Discret. Event Dyn. Syst., 13(4):341-379, 2003.
- [Bernstein et al., 2002] Daniel S. Bernstein, Robert Givan, Neil Immerman, and Shlomo Zilberstein. The com- plexity of decentralized control of Markov decision pro- cesses. Mathematics of operations research, 27(4):819- 840, 2002.
- [Cazenave, 2010] Tristan Cazenave. Partial move A*. In 22nd IEEE International Conference on Tools with Arti- ficial Intelligence, volume 2, pages 25-31. IEEE, 2010.
- [Dibangoye et al., 2016] Jilles Steeve Dibangoye, Christo- pher Amato, Olivier Buffet, and Franc ¸ois Charpillet. Op- timally solving Dec-POMDPs as continuous-state MDPs. JAIR, 55:443-497, 2016.
- [Hansen et al., 2004] Eric A. Hansen, Daniel S. Bernstein, and Shlomo Zilberstein. Dynamic programming for par- tially observable stochastic games. In AAAI, pages 709- 715, 2004.
- [Kaelbling et al., 1998] Leslie Pack Kaelbling, Michael L. Littman, and Anthony R. Cassandra. Planning and Acting in Partially Observable Stochastic Domains. Artif. Intell., 101(1-2):99-134, 1998.
- [Lauri et al., 2019] Mikko Lauri, Joni Pajarinen, and Jan Pe- ters. Information gathering in decentralized POMDPs by policy graph improvement. In AAMAS, pages 1143-1151.
- IFAAMAS, 2019.
- [Lauri et al., 2020] Mikko Lauri, Joni Pajarinen, and Jan Pe- ters. Multi-agent active information gathering in dis- crete and continuous-state decentralized POMDPs by pol- icy graph improvement. Auton. Agents Multi Agent Syst., 34(2):42, 2020.
- [Nair et al., 2003] Ranjit Nair, Milind Tambe, Makoto Yokoo, David Pynadath, and Stacy Marsella. Taming de- centralized POMDPs: Towards efficient policy computa- tion for multiagent settings. In IJCAI, pages 705-711, 2003. IJCAI
- [Oliehoek and Amato, 2016] Frans A. Oliehoek and Christo- pher Amato. A Concise Introduction to Decentralized POMDPs. Briefs in Intelligent Systems. Springer, 2016.
- [Oliehoek and Vlassis, 2007] Frans A. Oliehoek and Nikos Vlassis. Q-value heuristics for approximate solutions of Dec-POMDPs. In AAAI Spring Symposium: Game Theo- retic and Decision Theoretic Agents, pages 31-37, 2007.
- [Oliehoek et al., 2008] Frans A. Oliehoek, Matthijs T. J. Spaan, and Nikos Vlassis. Optimal and approximate Q- value functions for decentralized POMDPs. JAIR, 32:289- 353, 2008.
- [Oliehoek et al., 2009] Frans A. Oliehoek, Shimon White- son, and Matthijs T. J. Spaan. Lossless clustering of his- tories in decentralized POMDPs. In AAMAS, pages 577- 584, 2009.
- [Oliehoek et al., 2013] Frans A. Oliehoek, Matthijs T. J. Spaan, Christopher Amato, and Shimon Whiteson. Incre- mental clustering and expansion for faster optimal plan- ning in Dec-POMDPs. JAIR, 46:449-509, 2013.
- [Oliehoek et al., 2017] Frans A. Oliehoek, Matthijs T. J. Spaan, Bas Terwijn, Philipp Robbel, and João V. Mes- sias. The MADP toolbox: An open source library for plan- ning and learning in (multi-)agent systems. JMLR, 18:1-5, 2017.
- [Pateria et al., 2022] Shubham Pateria, Budhitama Sub- agdja, Ah-Hwee Tan, and Chai Quek. Hierarchical rein- forcement learning: A comprehensive survey. ACM Com- put. Surv., 54(5):109:1-109:35, 2022.
- [Russell and Norvig, 2020] Stuart Russell and Peter Norvig. Artificial Intelligence: A Modern Approach (4th Edition).
- [Seuken and Zilberstein, 2007] Sven Seuken and Shlomo Zilberstein. Memory-bounded dynamic programming for DEC-POMDPs. In IJCAI, pages 2009-2015, 2007. IJCAI
- [Spaan and Melo, 2008] Matthijs T. J. Spaan and Fran- cisco S. Melo. Interaction-driven Markov games for de- centralized multiagent planning under uncertainty. In AA- MAS, pages 525-532, 2008.
- [Spaan et al., 2011] Matthijs T. J. Spaan, Frans A. Oliehoek, and Christopher Amato. Scaling up optimal heuristic search in Dec-POMDPs via incremental expansion. In IJ- CAI, 2011. IJCAI
- [Szer et al., 2005] Daniel Szer, Franc ¸ois Charpillet, and Shlomo Zilberstein. MAA*: A heuristic search algorithm for solving decentralized POMDPs. In UAI, 2005.
- [Xie et al., 2020] Yuxuan Xie, Jilles Dibangoye, and Olivier Buffet. Optimally solving two-agent decentralized POMDPs under one-sided information sharing. In ICML, volume 119 of Proceedings of Machine Learning Re- search, pages 10473-10482, 2020.
References were extracted automatically from the PDF and may contain errors.
Full text extracted automatically from the PDF; figures, tables and equations may differ. The PDF is the version of record.
1 Introduction
This paper considers finite-horizon decentralized decisionmaking under stochastic dynamics and partial observability. Markov decision processes (MDPs) are the formalism to capture decision-making under (stochastic) uncertainty. These models assume that a centralized controller can fully observe the state space. Partially observable MDPs (POMDPs) capture the natural restriction that a controller only observes features of the current state. However, they still assume a centralized controller that can collect information from all sensors. In decentralized control, we assume that various agents each locally observe features of the state space and must locally select actions to execute. Such problems are formally captured by decentralized partially observable Markov decision processes (Dec-POMDPs) [Oliehoek and Amato, 2016]. These models naturally capture, for instance, sensor networks or multi-robot navigation in settings where communication is impossible, ineffective, or lossy.
Finding an optimal (decentralized) controller (hereafter: a policy) is computationally challenging; the associated decision problem is NEXP-hard [Bernstein et al., 2002]. Nevertheless, a series of advances resulted in a collection of effective algorithms that can find (1) provably optimal (exact) or (2) ε-optimal solutions. The focus of this paper is the former type, and we will refer to those as exact algorithms. In particular, we consider a family of exact algorithms referred to as multi-agent A∗ (MAA∗ ) [Szer et al., 2005; Oliehoek et al., 2008; Oliehoek et al., 2013] based on A∗ - style heuristic search that finds provably optimal policies.
Multi-agent A∗ . At every time-step (stage) of the decisionmaking problem, a local policy must reason about the history of observations to decide upon an action. Such a mapping is commonly referred to as decision rules, and for all policies together, these rules are the joint decision rules. A (joint) policy is then described by a sequence of (joint) decision rules. MAA∗ employs a search tree where a path through the tree encodes this sequence of decision rules. Consequently, the leaves of this tree correspond to all policies. MAA∗ searches through the tree by incrementally fixing decision rules for the individual stages. Every node corresponds to a partial policy up to time step t. As standard in A∗ , the order in which we explore the tree is steered by an admissible heuristic that, for every inner node of the tree, guarantees that we conservatively overapproximate the optimal reward obtained by a policy at the leaves of the subtree. Note that nodes reflect choices for the joint decision rules, i.e., we must choose responses for each agent and for each observation history. This representation yields a search tree with an outdegree that is double exponential in the stage t. Avoiding the double exponential blowup and providing a tight admissible heuristic are two primary concerns when developing variations to MAA∗ .
Our Approach: Small-step MAA∗ . In classical MAA∗ , expanding nodes is cumbersome due to the double exponential outdegree of nodes. While incremental expansion [Spaan et al., 2011] aims to alleviate the prohibitive outdegree, we prevent this massive outdegree by taking smaller steps in the decision-making process. In particular, we pick actions for each agent and each observation history successively. Compared to MAA∗ , our search tree limits the outdegree of nodes from double exponential to constant, while increasing the height from linear to exponential. Paired with a tight heuristic, this significantly limits the number of nodes expanded. Furthermore, the depth of the tree is further restricted by using clustering [Oliehoek et al., 2009], which is applicable offthe-shelf to small-step MAA∗ .
Admissible Heuristics. A further important step towards efficient small-step MAA∗ is the efficient computation of a tight and admissible heuristic. We base our heuristic on the recursive heuristic from Szer et al. [2005]. In a nutshell, to obtain a heuristic value for a node at stage t, we assume that, at stage t, the agents once communicate their local observations. This (generally unrealistic) assumption yields a reward value that overapproximates the actual value and thus yields an admissible heuristic. In particular, this assumption allows us to compute a distribution over the current state. We can then compute a heuristic value by solving a Dec-POMDP problem for horizon h - t from the current state. We add two ingredients that make this heuristic effective. First, we can decide to assume communication at a stage t′ < t, which often allows us to reuse earlier computations and provides even tighter results. Second, when computing the heuristic value, we can terminate the computation early and use the current heuristic value as a sound overapproximation of the true value. This means that even the aborted computation yields an admissible heuristic value. With these ingredients, the recursive heuristic has three benefits: 1) It is tighter than heuristics employed by the state-of-the-art. 2) It can be computed on-the-fly and avoids precomputing and storing heuristic values. 3) It avoids dependencies on other algorithms or formalisms, like POMDP solvers or Bayesian games.
Contributions. We present recursive small-step multiagent A∗ (RS-MAA∗ ), a fast yet conceptually simple instantiation of MAA∗1 . In particular, RS-MAA∗ can be concisely implemented and relies neither on precomputed external heuristics nor solvers for cooperative Bayesian games. Its on-the-fly recursive heuristic only computes heuristic values for nodes in the search tree that are expanded. This alleviates a well-known weakness in the state-of-the-art GMAA∗ - ICE which relates to the memory consumption of storing the heuristic values [Spaan et al., 2011]. Our formulation is compatible with clustering [Oliehoek et al., 2009]. A prototype of our algorithm significantly outperforms the state-of-the-art optimal planners. In particular, to the best of our knowledge 2 , RS-MAA∗ is the first to scale to horizon 12 on DECTIGER (an improvement from 6) and to horizon 1500 on RECYCLING ROBOTS (an improvement from 80).
Related Work
We review extensions and improvements of MAA∗ and some recent trends. For a survey and in-depth treatment of various approximate and exact approaches, we refer to the detailed monograph by Oliehoek and Amato [2016].
Szer et al. [2005] introduce multi-agent A∗ (MAA∗ ), investigating heuristics based on different approximations such as an MDP, a POMDP and a recursive MAA∗ . Thereafter, different heuristics have been proposed to reduce the number of nodes expanded during the search. Oliehoek and Vlassis [2007] introduce a heuristic that models interactions between the agents in one time step using Bayesian games. Oliehoek et al. [2008] introduce generalized MAA∗ (GMAA∗ ), which uses a Bayesian game to determine which child of a given partial policy is the best, but solving the Bayesian game itself is also expensive. Oliehoek et al. [2009] propose the GMAA∗ with incremental clustering
1 Proofs and source code are given in the supplementary material available at https://zenodo.org/record/7949016
2 Based on masplan.org and our experiments.
(GMAA∗ -IC) algorithm, which clusters observation histories while expanding the tree to reduce the number of nodes in the tree. This is the first approach to solve DECTIGER (see Example 1) for horizon 5. Finally, Spaan et al. [2011] introduce GMAA∗ -IC with incremental expansion (GMAA∗ - ICE), which, when expanding a node, finds the best child incrementally by a second (nested, but not recursive) A∗ search over partially specified Bayesian game policies. This was the first method to solve DECTIGER for horizon 6. We refer to Oliehoek et al. [2013] for an in-depth explanation of these approaches. In this paper, we propose a new variation of MAA∗ that improves the scalability even further, solving DECTIGER with horizon 12.
The state-of-the-art to generate ϵ-optimal solutions reduces the Dec-POMDP to an MDP with continuous state space and uses an adaption of heuristic-search value-iteration for continuous MDPs [Dibangoye et al., 2016]. Recent work has studied different subclasses of Dec-POMDPs to alleviate the complexity of the general method. Amato et al. [2019] adds macro actions (also known as option [Pateria et al., 2022; Barto and Mahadevan, 2003]) to the Dec-POMDP, which allows an agent to perform multiple actions without having to coordinate with the remaining agents. Xie et al. [2020] study problems with two agents under one-sidedness, that is, where one of the agents observes the actions and observations of the other agent. Finally, Lauri et al. [2019; 2020] investigate the information gathering task where the reward function is based on the joint belief of the agents.
The idea of splitting up steps in the A∗ search tree into smaller steps to limit the outdegree of the tree was proposed before by Cazenave [2010], and applied to multi-agent path finding and multiple sequence alignment. However, it has not been applied before to solving Dec-POMDPs.
2 Problem Statement
∆(X) denotes distributions over finite sets X.
Definition 1 (Dec-POMDP). A Dec-POMDP is a tuple ⟨D, S,A,O, b, T,R,O⟩ with a set D = {1, . . . , n} of n agents, a finite set S of states, a set A =×i∈D Ai of joint actions, where each Ai is the finite set of local actions of agent i, and a set O =×i∈D Oi of joint observations, where each Oi is the finite set of local observations of agent i. The transition function T : S × A → ∆(S) defines the transition probability Pr(s′ | s, a), b ∈ ∆(S) is the initial belief, R: S ×A → R is the reward function, and the observation function O : A × S → ∆(O) defines the observation probability Pr(o | a, s′ ).
A Dec-POMDP describes a system that initially starts in a state s0 with probability b(s0 ). At each time step t, each agent i selects a local action ati . Together, this yields a joint action at = ⟨at1 , . . . , atn ⟩ and a reward rt = R(st , at ). The system evolves to the next state st+1 with probability Pr(st+1 | st , at ). The observation ot+1 is obtained with probability Pr(ot+1 | at , st+1 ), and each agent i receives the local observation ot+1 i . We call the sequence of joint observations τ = o1o2 . . . ot a joint observation history (JOH) and the sequence of local observations τi = o1i o2i . . . oti of agent i a local observation history (LOH). We denote the first d observations of τ by pre(τ, d). We denote the set of all LOHs of length exactly ℓ and at most ℓ by Oℓ i andO≤ℓ i , respectively.
We are interested in offline planning: How should the individual agents act locally such that, jointly, they optimize the cumulative reward up until horizon h? A local policy for agent i maps LOHs for that agent to a local action, formally: πi : O≤h-1 i → Ai. A joint policy is a tuple of local policies π = ⟨π1, · · · , πn⟩, and Π denotes the set of all joint policies.
Given a joint policy π, we can define the value of executing this policy in the initial belief b over a horizon h as:
where st and at are the state and joint action at time step t.
Problem statement: Given a Dec-POMDP and a horizon h, find a joint policy π that maximizes Vπ(b, h).
Example 1 (Decentralized tiger problem). The DECTIGER problem [Nair et al., 2003] is a multi-agent variation of the Tiger problem [Kaelbling et al., 1998]. In this problem, two agents are in front of two doors. A tiger is behind the left or the right door, which indicates the state of the environment (TL or TR), and a treasure is behind the other. Each agent has three actions: listen (Li), open the left door (OL), or open the right door (OR). Listening gives a noisy observation regarding the location of the tiger (HL or HR). In the multi-agent variation, the dynamics depend on the joint action. The state resets if any agent opens a door, in which case both agents get an uninformative observation (uniform distribution over the observations). If only one agent opens the door with the treasure, they receive a positive reward. But, if both agents find the treasure, they receive a larger reward. A large penalty is given for opening the door with the tiger.
The DECTIGER problem (Example 1) illustrates the challenges in cooperating to solve a Dec-POMDP. In this case, besides finding a policy to gather information, the agents must also coordinate in the offline phase deciding the right moment to open a door. Without such coordination, the actions of one agent could compromise the belief of the remaining agents.
3 Small-stepMulti-agent A∗
In this section, we frame the search for an optimal policy by an incremental heuristic search over partial policies.
Ordered LOHs. For our algorithm, we explore LOHs in a fixed order. Intuitively, we order the LOHs of all agents as follows: first by stage (length of the observation history), then by agent, and then lexicographically by observation history. This ordering is formalized in the following definition.
Definition 2. Given a total order ⪯i on Oi, we define a total order ⪯ on ⋃ni=1 O≤h-1 i such that τ t i ⪯ τ t′ j if
Throughout the paper, we use this fixed order for LOHs.
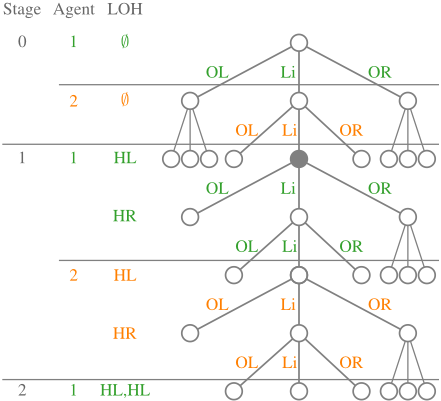
Partial policies. A local partial policy for agent i is a partial function φi : O≤h-1 i → Ai. A partial policy is a tuple of local partial policies φ = ⟨φ1, . . . , φn⟩. The length of a partial policy is ℓ, if every local partial policy φi is defined on only the first ℓ LOHs (of any agent) according to the order in Definition 2. Hence, a partial policy of length ℓ is defined on ℓ LOHs in total, summed over all local partial policies. The stage σ(φ) of a partial policy φ is t, if the policy is defined for all LOHs of length t-1, but not for all LOHs of length t. The set of all partial policies is Φ. A partial policy φ′ extends a partial policy φ, denoted by φ <E φ′ if φ′ agrees with φ on all LOHs for which φ specifies the action. Formally,
where φi(τi) = ⊥ denotes that φi is not defined at τi. The extensions of φ are the fully-specified policies extending φ:
Search tree. We define a search tree with an empty policy at the root and fully specified policies at the leaves.
Definition 3 (Small-step search tree). In a small-step search tree for a Dec-POMDP, the nodes are the partial policies, the root node is the empty policy, and the children of a partial policy φ of length ℓ are exactly the partial policies φ′ such that φ <E φ′ and the length of φ′ is ℓ + 1.
Example 2. Consider the (partial) tree in Figure 1. For the highlighted node, we add three children, each reflecting the choice of an action by agent 1 after observing HL. In this tree, we can extract the policy of a node by backtracking. For example, the policy in the bottom-left node is ⟨{∅ ↦→ Li,HL ↦→ Li, HR ↦→ Li}, {∅ ↦→ Li, HL ↦→ Li, HR ↦→ OL}⟩.
A∗ . Small-step MAA∗ applies A∗ on the small-step search tree. A∗ successively expands the nodes in the tree [Russell and Norvig, 2020]. To guide the expansion of nodes, a heuristic Q: Φ → R is used. The A∗ algorithm keeps a list of open nodes, which initially only contains the root. In each step, the open node with the highest heuristic value is selected, this node is removed from the list of open nodes, and all children are added to the list of open nodes. Once a leaf is selected as node with the highest heuristic value, that node is returned as the final solution. The algorithm is exact if the heuristic is admissible, i.e. if Q is an overapproximation:
Difference to classical MAA∗ . Classical MAA∗ constructs a stage-(t + 1) policy in one step from a stage-t policy, specifying actions for all length-t LOHs for all n agents. As a result, each stage-t policy has O (|A∗|n|O∗|t ) children in the A∗ search tree, where |A∗| and |O∗| denote the sizes of the largest local action and observation sets, respectively. In small-step MAA∗ , this is split up in n|O∗|t levels, where each node has up to |A∗| children and just adds an action for one agent for one particular LOH.
Example 3. In the tree from Fig. 1, RS-MAA∗ reaches only 12 nodes in stage 1 and 6 nodes in stage 2 by expanding only 6 nodes below the gray node in stage 1. By contrast, MAA∗ would have reached 81 nodes at stage 2 after expanding the gray node.
Compared to MAA∗ , our search tree limits the outdegree of the nodes from double exponential to constant, at the cost of increasing the tree height from linear to exponential.
4 Admissible Recursive Heuristics
Next, we introduce two families of admissible heuristics.
Generalized policies. To define admissible heuristics, we introduce more general types of policies. First, we allow local policies πi for each agent to depend on the joint observation history. A generalized local policy πi : O≤h-1 → Ai maps JOHs to a local action. A generalized (joint) policy is a tuple of generalized local policies (one for each agent). Let Πgen denote the set of all generalized policies. As before, a generalized policy π extends a partial policy φ, denoted by φ <E π, if πi agrees with φi on all OHs corresponding to an LOH for which φi specifies the action. Formally,
The generalized extensions of a partial policy φ are the set of all fully specified generalized policies agreeing with φ:
Fixed-depth heuristics. First, we write the Dec-POMDP optimization problem over generalized policies as
Intuitively, we optimize over the generalized policies but add constraints that ensure agents have to take equal actions on joint OHs that they cannot distinguish, therefore any feasible solution encodes a decentralized policy. By relaxing some of the constraints, we achieve optimization problems that describe an upper bound on the optimal Dec-POMDP value, thus forming admissible heuristics.
Definition 4. Let φ be a partial policy. The Dec-POMDP heuristic QDec,d(φ) of depth d is defined as
The heuristic QDec,d allows local policies to condition their choices after stage d on the local observation of other agents up to stage d. Notice that for d = 0, the Dec-POMDP heuristic corresponds to the original optimization problem (1).
For stage-t partial policies with d ≤ t, this heuristic is easier to compute than the Dec-POMDP value itself. Since d ≤ t, the policy for the first d stages is specified by φ, and we can compute the realized reward Vφ(b, d) up to stage d as
vations τ ∈ Od provides the agents with a new joint belief bτ after d stages, so for each length-d JOH we solve a DecPOMDP with horizon h - d and the new belief bτ :
where φ|τ is the shortened partial policy for which φ has already specified an action: (φ|τ )i(˜ τ ) = φi(τi˜ τ). Note that φ may have already specified actions for LOHs of length larger than d. These actions are then also specified in problems with horizon h - d through the shortened partial policy φ|τ .
When computing QDec,d, we allow each agent to also base their decision on these first d joint observations. The smaller d, the less information agents have, so the tighter the heuristic is. This provides the intuition for the following lemma.
Proof. The definitions of QDec,d′ and QDec,d only differ in the condition used in the antecedent of the constraint. Since the condition pre(τ, d) = pre(˜ τ, d) is stronger than pre(τ, d′ ) = pre(˜ τ, d′ ), the maximization problem for QDec,d effectively removes some constraints from the maximization problem for QDec,d′ .
Since a less constrained maximization problem has a higher (or equal) optimal value, the result follows.
Theorem 1. QDec,d is admissible.
Proof. We can write maxπ∈E(φ) Vπ(b) as
Since the condition pre(τ , 0) = pre(˜ τ, 0) is empty, it follows that maxπ∈E(φ) Vπ(b) = QDec,0(φ). By Lemma 1, it follows that QDec,d(φ) ≥ QDec,0(φ) = maxπ∈E(φ) Vπ(b) for all partial policies φ, so QDec,d is admissible.
Variable-depth heuristics. The smaller d, the harder the heuristic QDec,d is to compute, since (by Eq. 2) we have to solve Dec-POMDPs with a larger horizon. On the other hand, we do not want to compute QDec,d(φ) if σ(φ) < d, because then Eq. 2 cannot be used. We suggest to use QDec,d unless σ(φ) < d, in which case we use QDec,σ(φ)(φ).
Towards this idea, for some φ we would like to use heuristics QDec,σ(φ)(φ). However, this heuristic is suboptimal in the following sense: Along the search tree, whenever we increase the stage, we switch to a looser heuristic. Consequently, it is possible that the heuristic value of a node is larger than that of its parent, despite more actions being fixed. To fix this weakness, we may simply take the minimum with the heuristic value of the parent. Formally, let the parent φof a partial policy φ of length ℓ > 0 be the partial policy of length ℓ - 1 such that φ- <E φ.
Definition 5. Let φ be a partial policy. The heuristic Qd is recursively defined by Qd(φ) = ∞ if σ(φ) = 0, and if σ(φ) > 0 we define
We can also set d = ∞; then min{σ(φ), d} = σ(φ).
Corollary 1. Qd is admissible for d ≥ 1.
This follows from Thm. 1 and Qd(φ) ≥ QDec,1(φ), d ≥ 1.
Comparing heuristics. The recursiveDec-POMDP heuristic proposed by Szer et al. [2005] can be written as QDec,σ(φ)(φ). It does exhibit the weakness mentioned above that we fix in the definition of Qd. Two other commonly used heuristics in the literature [Oliehoek and Vlassis, 2007; Oliehoek et al., 2013] are the QPOMDP and QBG heuristic. For the QPOMDP heuristic, it is assumed that the agents can communicate and hence have access to all joint observations when making their decisions. For the QBG heuristic, it is assumed that agents can communicate with one step of delay. The QPOMDP and QBG heuristics can be captured as instances of the generalized policy optimization problem. This allows to compare our heuristics to QPOMDP and QBG.
Proof. The (centralized) POMDP policy optimization problem is the unconstrained version of the optimization problem (1), fromwhich the first inequality follows.
The one-step delay communication problem used to compute QBG corresponds constraints of the form
The antecedent of the constraint pre(τ , t-1) = pre(˜ τ , t-1)∧ τi = ˜ τi used in QDec,t-1(φ) is weaker for s ≥ t (leading to a more constrained problem), whereas all actions corresponding to OHs of length s ≤ t - 1 are already fixed (and satisfy the Dec-POMDP constraint, so certainly also the constraint for QBG). This shows the second inequality.
5 Abandoning Heuristic Computations Early
In this section, we consider a cheap variation of the recursive heuristic that provides an upper bound on Qd and is thus admissible. We algorithmically obtain this heuristic by early termination of the computation of the recursive heuristic.
Assume we are computing a heuristic value for the partial policy φ. By Eq. 2, this can be done by solving DecPOMDPs with a smaller horizon, e.g., using an A∗ algorithm with an admissible heuristic Q. Due to the nature of A∗ , the highest heuristic value of an open node is an upper bound for the expected reward of an optimal policy. Hence, we can abandon a computation after exploring M nodes and return the highest heuristic value of an open node at that point. We call this value LM(φ,Q). If the heuristic is such that the heuristic value of node φ is always at most the value of its parent φ-, then the A∗ algorithm explores nodes in order of decreasing values. LM(φ,Q) will be the Mth largest value in the tree, or, if A∗ terminates within M steps, the value of the fully specified policy. Next, we formalize LM(φ, Q).
Definition 6. Consider a search tree with heuristic Q: Φ → R and some fixed partial policy φ. We define the set of candidate policies Φc = {φ <E φ′ ∧ σ(φ′ ) ≥ 1}. Let w be an ordered list over Φc such that Q(wi) ≥ Q(wj) for i < j, and k∗ = min{k | wk ∈ Π} is the smallest index where w contains a fully specified policy. With K = min{k∗ ,M}, we define LM (φ, Q) = Q(wK).
Indeed, wk∗ = argmaxπ∈Φc∩Πgen Q(π), i.e., the fully specified policy in Φc with the largest heuristic value is the first fully specified policy in the list. Furthermore, we know that Q(wK) ≥ Q(wM). Note that we only count partial policies with stage larger than 0, as we do not want to compute heuristic values for partial policies with stage 0; formally, we assign these nodes an infinite heuristic value.
Recall that the heuristic Qd can be written in terms of optimal values of Dec-POMDPs with a lower horizon. For the heuristic QM,d, we substitute the precise values with the values obtained after early termination.
Definition 7. First, QM,d(φ) = ∞ for σ(φ) = 0. For σ(φ) ≥ 1, we define QM,d(φ) inductively over the horizon. For h = 1, partial policies with σ(φ) ≥ 1 are fully specified and QM,d(φ) = Vφ(b, 1). For h = ℓ + 1, QM,d(φ) is
Note that the QM,d values used for computing LM(φ|τ ) are values with horizon ℓ + 1 - t ≤ ℓ, so these are defined already. Hence, the recursion is well-founded. Naturally aborting earlier leads to values that are less tight:
Lemma 2. Let φ be a partial policy. Then
A proof of this lemma is given in the supplementary material.
6 Recursive Small-StepMulti-Agent A∗
In a nutshell, Recursive Small-step Multi-Agent A∗ (RSMAA∗ ) applies the QM,d heuristic with suitable M and d on the search tree in Def. 3. Here, we discuss the choice for M and d, as well as other improvements that help scalability.
Clustering. Following Oliehoek et al. [2009], we employ incremental lossless clustering. Clustering computes groups of LOHs for which the same action choice is provably optimal. We use incremental clustering to compute the clustered LOHs for stage t + 1 once a policy is expanded where each LOH corresponding of length t is assigned an action, but no LOH of length t + 1. Each edge in the small-step search tree now corresponds to assigning an action to each LOH in a clustered set of LOHs.
Storing heuristics. A key feature of RS-MAA∗ is that heuristics are computed on-the-fly, in contrast to precomputing them. Recall that we solve the Dec-POMDP for smaller horizons and different initial beliefs. The combination of horizon and initial belief (and initial part of the policy) can appear in multiple computations. To avoid recomputing those heuristic values, we memoize all values. To enable finding values that we already computed, we characterize each heuristic as a tuple containing 1) the horizon, 2) the initial belief, 3) an index describing the partial policy, and 4) a list of indices describing the clustering structure at each stage. We additionally reuse computations for which we completed the computation of Qd, i.e., for which we did not terminate early. Those values can be reused when evaluating extended policies. In particular, whenever we do not terminate early, we not only find a heuristic value, but also a fully specified policy π. Then, for all φ′ satisfying φ <E φ′ <E π we have Q(φ′ ) = V (π, σ(π)). Hence, we can also store the heuristic value for all such φ′ without explicitly computing them. 3
Dynamically abandoning heuristic computations early. In Section 5, we have shown how heuristic computations can be terminated early based on a fixed maximum number of iterations M. We can go further and also terminate the heuristic computation of Q(φ) when the highest heuristic value of an open node is much smaller than the heuristic value of the parent u = Q(φ-), which is an upper bound for Q(φ). Specificially, we terminate the heuristic computation after M iterations or if the new heuristic value v satisfies v ≤ u - αmax{|u|, 1}, where α is a parameter, called the threshold. The intuition for this is that a large drop in computing the heuristic value is sufficient to avoid expanding that node again (at least for a long time), so spending more time computing heuristics for this node is likely a waste of time.
Dynamically increasing depth. While Lemma 1 tells us that Qd(φ) ≤ Qd′(φ) if d ≤ d′ , the inequality QM,d(φ) ≤ QM,d′(φ) does not necessarily hold, i.e., taking the lowest depth does not always lead to the tightest heuristic when abandoning heuristic computations early. Hence, we actually compute Qd′ (φ) for all d′ ≥ d. Computing the heuristic is much more expensive for lower depths, the additional runtime cost of computing heuristics for higher depths is negligible. Each time we expand a node φ, we update d to argmind′ Qd′(φ) (taking the largest value of d′ in case of a tie) for all descendants of that node.
3 We only store it for policies φ′ of the same stage as clustering in later stages may depend on the observations that are revealed.
Last stage. We treat nodes almost at the bottom of the search tree differently. To compute actions for the last agent for the last stage, we can compute the best fully specified policy that is a descendant of this policy directly. For each LOH of the last agent, we can compute the best action to take independently by computing the expected reward of each action according to the joint multi-agent belief.
Storing distributions. To compute policy values and the clustering structure, we need to work with the full joint distribution Pr(τ , o, s) and its conditional distributions. It turns out to be more efficient to instead store the marginal probabilities Pr(τ , o) and indices of conditional distributions over states Pr(s | τ, o), where the map between indices of state distributions and the corresponding distributions is stored globally. While in the worst case this takes more space than simply storing the joint distribution Pr(τ, o, s), in practice many of the conditional distributions Pr(s | τ, o) are equal, thereby saving space. Moreover, using the indices allows for easy caching.
Choosing parameters. The most important parameter to set is d. Lower values of d give tighter heuristics but are more expensive to compute. Setting the number of iterations M too low leads to an overly loose heuristic. However, setting M high leads to generally higher computation times. Due to the recursive nature of the algorithm, however, the time can scale as badly as O(M h ). Typically, the computational effort is much less, in particular due to the tighter heuristic and the fact that recursive heuristics at later stages are easier to compute. Furthermore, some heuristics already find a complete policy before M iterations and most heuristics do not nest h layers deep (except if d = 1). The effect of α is similar to the effect of M, but harder to quantify. In particular, higher values of α yield tighter heuristics and are harder to compute.
7 Empirical Evaluation
This section provides an empirical evaluation of RS-MAA∗ on a set of standard benchmarks, in comparison with GMAA∗ -ICE [Oliehoek et al., 2013], the current state-of-theart exact solver for Dec-POMDPs. Furthermore, we provide an ablation study, showing the effects of clustering, computing the best response for the last agent in the last stage directly, the choice of heuristic (Qd), and abandoning the computation of the recursive heuristic early based on a maximum number of iterations (M) or a threshold (α).
Setup. We implemented a stand-alone prototype of RSMAA∗ in Python 3 that does not have any dependencies. We execute it using PyPy. 4 For GMAA∗ -ICE, we use the C++ implementation in the MADP toolbox [Oliehoek et al., 2017].
4 The supplementary material contains the source code and scripts to reproduce the empirical results.
We use two versions of the QBG heuristic 5 using a hybrid representation and using tree-based incremental pruning. We also show results for QMDP. Both implementations use floating point numbers and a threshold of 10-12 for comparing probabilities and rewards. We run RS-MAA∗ in two configurations, outlined in the paragraph below. For RS-MAA∗ , we report the total running time, for GMAA∗ -ICE, we give the 'overall time' as reported by solver. Reported timings are an average over 3 runs. We did not observe significant variations in the timings. All experiments were ran on 3.7GHz Intel Core i9 CPU running Ubuntu 22.04.1 LTS. We limited each process to 16GB of memory and 1 hour of CPU time.
Hyperparameter selection. Our algorithm has three hyperparameters, d,M, α, discussed in Sec. 6. For most problems, Q1 and Q2 are too expensive to compute, but Q3 is a good compromise. For easier problems, Q∞ also works well. In a preliminary evaluation using M ∈ {100, 200, 400} and α ∈ {0.1, 0.2}, we observed that M = 100 sometimes expands much more nodes than M = 200, but increasing M to 400 did not reduce the number of nodes (significantly) compared to M = 200, and hence typically increased running times. Hence, we set M = 200. The threshold α had a small effect, so we conservatively set it to 0.2.
Benchmarks. We used the standard benchmarks from the literature: DECTIGER [Nair et al., 2003], FIREFIGHTING [Oliehoek et al., 2008] (3 fire levels, 3 or 4 houses), GRID with two observations [Amato et al., 2006], BOXPUSHING [Seuken and Zilberstein, 2007], GRID3X3 [Amato et al., 2009], MARS [Amato and Zilberstein, 2009], HOTEL [Spaan and Melo, 2008], RECYCLING [Amato et al., 2007], and BROADCAST [Hansen et al., 2004].
Results
Table 1 summarizes the results for the benchmarks with different horizons h. We show the optimal value and timing results for GMAA∗ -ICE (for three heuristics) and for RS-MAA∗ (for two heuristics). In summary, we observe that RS-MAA∗ scales to larger horizons on DECTIGER,FIREFIGHTING4, GRID, GRID3X3, MARS, and RECYCLING. On HOTEL, scalability is comparable, but RSMAA∗ is faster. On BROADCAST and FIREFIGHTING3, GMAA∗ -ICE scales better. In line with the computational complexity, horizons ≤ 10 are already challenging on many benchmarks. However, HOTEL, RECYCLING and BROADCAST have a constant number of clustered LOHs which allows to scale to much larger horizons [Oliehoek et al., 2013].
RS-MAA∗ scales much further on on DECTIGER and MARS. On DECTIGER, the tightness of the heuristic is essential. The QBG heuristic reveals too much information which leads to unrealistically high heuristic values. On Q3, however, only information from the first two stages is shared, which under an optimal policy becomes irrelevant in later stages. This leads to a very tight heuristic in the later stages.
On MARS, QBG struggles as its run time complexity includes a factor O (|A∗|n|O∗| ), which is 616 for MARS due to the eight different observations. Hence, computing QBG is infeasible (for every horizon). QMDP can be computed, but is not sufficiently tight. Likewise, the tighter heuristic Q3 outperforms Q∞ for sufficiently large horizons.
5 The exact configurations used by [Oliehoek et al., 2013] do not seem to be available in the MADP toolbox, we use QBGhybrid and QBGTreeIncPrune.
| GMAA∗ -ICE | RS-MAA∗ | |||||
|---|---|---|---|---|---|---|
| h | value | QMDP | prune | hybrid | Q3 | Q∞ |
| DECTIGER | ||||||
| 5 | 7.026451 | 40 | <1 | 1 | <1 | <1 |
| 6 | 10.381625 | MO | 16 | 18 | <1 | 17 |
| 7 | 9.993568 | MO | TO | MO | 2 | MO |
| 8 | 12.217263 | MO | TO | MO | 2 | MO |
| 9 | 15.572437 | MO | TO | MO | 9 | MO |
| 10 | 15.184380 | MO | TO | MO | 628 | MO |
| 11 | 17.408076 | MO | TO | MO | 249 | MO |
| 12 | 20.763250 | MO | TO | MO | 762 | MO |
| FIREFIGHTING (⟨nh = 3, nf = 3⟩) | ||||||
| 3 | -5.736969 | 2 | TO | 4 | 1 | 1 |
| 4 | -6.578834 | 29 | TO | 181 | 3 | 3 |
| 5 | -7.069874 | 1730 | TO | 221 | 24 | 41 |
| 6 | -7.175591 | 57 | TO | TO | 281 | 281 |
| 7 | -7.175591 | 33 | TO | TO | MO | MO |
| FIREFIGHTING (⟨nh = 4, nf = 3⟩) | ||||||
| 3 | -11.135643 | 567 | TO | 989 | 8 | 8 |
| 4 | -14.106819 | TO | TO | TO | 137 | 138 |
| GRID | ||||||
| 3 | 1.550444 | <1 | TO | 7 | <1 | <1 |
| 4 | 2.241577 | 5 | TO | 288 | 2 | 2 |
| 5 | 2.970496 | MO | TO | TO | 9 | 9 |
| 6 | 3.717168 | MO | TO | TO | 97 | 96 |
| BOXPUSHING | ||||||
| 3 | 66.081000 | <1 | TO | 2535 | <1 | <1 |
| 4 | 98.593613 | 131 | TO | TO | 10 | 9 |
| 5 | 107.729851 | TO | TO | TO | MO | MO |
| GRID3X3 | ||||||
| 4 | 0.432900 | 1 | MO | TO | 1 | 1 |
| 5 | 0.895656 | 3 | MO | TO | 2 | 2 |
| 6 | 1.492987 | MO | MO | TO | 12 | 12 |
| MARS | ||||||
| 4 | 10.180800 | 8 | MO | TO | 1 | 1 |
| 5 | 13.266538 | MO | MO | TO | 2 | 2 |
| 6 | 18.623165 | MO | MO | TO | 5 | 5 |
| 7 | 20.900724 | MO | MO | TO | 21 | 10 |
| 8 | 22.478798 | MO | MO | TO | 40 | MO |
| 9 | 24.320398 | MO | MO | TO | 160 | MO |
| HOTEL | ||||||
| 5 | 27.187500 | MO | 3 | 19 | <1 | <1 |
| 100 | 502.187500 | MO | 69 | MO | 201 | 21 |
| 250 | 1252.187500 | MO | 126 | MO | 595 | 57 |
| 500 | 2502.187500 | MO | 230 | MO | 1317 | 119 |
| 1500 | 7502.187500 | MO | 629 | MO | TO | 397 |
| 2000 | 10002.187500 | MO | 832 | MO | TO | 557 |
| RECYCLING | ||||||
| 8 | 25.709878 | <1 | <1 | MO | 1 | <1 |
| 20 | 62.633136 | 52 | <1 | MO | 4 | 1 |
| 70 | 216.479290 | MO | 14 | MO | 209 | 2 |
| 80 | 247.248521 | MO | 68 | MO | 292 | 3 |
| 100 | 308.786982 | MO | MO | MO | 467 | 4 |
| 500 | 1539.556213 | MO | MO | MO | TO | 21 |
| 1500 | 4616.479290 | MO | MO | MO | TO | 113 |
| BROADCAST | ||||||
| 10 | 9.290000 | <1 | <1 | MO | <1 | <1 |
| 100 | 90.760423 | MO | 32 | MO | 37 | 36 |
| 250 | 226.500545 | MO | 149 | MO | 718 | 720 |
| 500 | 452.738119 | MO | 385 | MO | 3496 | 3016 |
| 800 | 724.214207 | MO | MO | MO | TO | TO |
| M | 200 Q3 | ∞ Q3 | 200 | ∞ | 200 | 200 Q2 | no clus- | last |
| Qd | Q3 | Q3 | Q1 | tering | no stage | |||
| α | 0.2 | 0.2 | ∞ | ∞ | 0.2 | 0.2 | ||
| h = 6 | <1 | <1 | <1 | <1 | 3 | 1 | 1 | 1 |
| h = 7 | 2 | 2 | 2 | 2 | 293 | 5 | MO | 2 |
| h = 8 | 2 | 31 | 3 | 40 | 3355 | 15 | MO | 2 |
| h = 10 | 628 | MO | 630 | TO | TO | TO | MO | 2453 |
| h = 12 | 762 | MO | 1129 | TO | TO | TO | MO | 1296 |
GRID is a prime example where the on-the-fly computation of the heuristic values is an essential benefit, as the QBG heuristic cannot finish the computation of the heuristic values.
On HOTEL and BROADCAST, the QBG heuristic is already tight, which means that the more expensive computation of Qd does not significantly reduce the number of nodes that are explored. This also explains why Q∞ outperforms Q3.
FIREFIGHTING3's structure makes h = 5 expensive (no potential for clustering). The recursive nature of RS-MAA∗ suffers from this when computing values for h ≥ 6.
In short, RS-MAA∗ performs generally better on domains where agent knowledge about the state is relatively valuable. Note that the recursive heuristics are tighter than other known competitive heuristics because they share less information about observations (and hence about the state). Hence, if knowledge about the state is valuable, then the additional tightness of the recurive heuristic is more essential for limiting the number of nodes expanded in the search tree.
RS-MAA∗ is also better on domains with many clustered observations, as the speed-up provided by using the smallstep search tree is more significant in this case. By contrast, GMAA∗ -ICE seems better on domains where there are very few clustered observations, although in these cases RSMAA∗ can sometimes still outperform GMAA∗ -ICE.
Ablation study. For DECTIGER, we provide additional results using alternative configurations in Table 2. The first configuration reflects the baseline. The next 5 configurations change the three hyperparameters. In particular, setting M = α = ∞ disables abandoning computations as described in Sec. 5. We additionally used the baseline parameters but without clustering or the last-stage optimization from Sec. 6. Clustering, early termination, and avoiding low-depth heuristics are essential components for the performance. Terminating early based on a threshold and the last-stage optimization are less essential, but still provide a significant speedup.
Benchmark-specific parameters. Although the parameters M = 200, d = 3, and α = 0.2 work well for a wide range of benchmarks, some benchmarks benefit from different parameters. For example, BOXPUSHING is solved faster when using the tighter Q2 heuristic, namely in respectively 3 and 6 seconds for h = 4 and h = 5. HOTEL can be solved in 44 seconds for h = 2000 using a less tight M = 25 and Q∞. Finally, BROADCAST can be solved in respectively 250, 465 and 1342 seconds for h = 500, h = 800, and h = 2000 using a less tight M = 25 and Q∞. Notably, it seems that for most benchmarks, parameter choices that are good for a short horizon are also a good choice on larger horizons.
Comparison to ϵ-optimal Algorithms
It is interesting to understand the performance of RS-MAA∗ compared to less strict ϵ-optimal algorithms, such as FBHSVI [Dibangoye et al., 2016]. These algorithms provide an upper bound and a lower bound for the optimal value that are at most ϵ apart. As there is no implementation of FBHSVI available at the time of writing, we provide a short qualitative comparison based on the data from Dibangoye et al. [2016]. For GRID, GRID3X3, MARS and BOXPUSHING, FB-HSVI is able to provide ϵ-optimal solutions for horizon 10, thereby outperforming RS-MAA∗ . For BROADCAST, it is is likely that RS-MAA∗ outperforms FB-HSVI, as computing the solution for horizon 100 already took 473 seconds for FBHSVI. For RECYCLING, both algorithms perform very well and to see which algorithm performs better, results for FBHSVI beyond horizon 100 are needed. All run times above allow an ϵ = 0.01 optimality gap.
Based on this qualitative comparison, some aspects remain unclear: It is unclear from which ϵ onwards RS-MAA∗ outperforms FB-HSVI, and it is also unclear in which circumstances the upper bounds obtained with RS-MAA∗ within a given timelimit are stricter than the ones found by FB-HSVI.
8 Conclusion
We presented a novel method for finding optimal solutions for finite-horizon Dec-POMDP problems. Our approach showed competitive, and often superior, performance compared to the state-of-the-art. In particular, for several benchmarks, we extend the highest horizon for which an optimal solution is known. The contributions that led to this advancement are a small-step variant of the search tree for MAA∗ , as well as a novel heuristic that is computed on-the-fly. In the future, we will investigate supporting nonlinear objectives, relevant, e.g., for rewards that relate the joint belief of agents, as in Lauri et al. [2019] and Lauri et al. [2020]. Finally, towards further scalability, we will integrate results by approximate Dec-POMDP solvers in the heuristic computation.
Acknowledgements
We would like to thank the anonymous reviewers for their useful comments. This work has been partially funded by the ERC Starting Grant 101077178 (DEUCE) and the NWO grant NWA.1160.18.238 (PrimaVera).
Contribution Statement
Wietze Koops is the primary designer of the algorithm and implemented it and evaluated the algorithms. The other authors contributed discussions, ideas, and shaped the description of the algorithm.
@inproceedings{ijcai2023p600,
  title     = {Recursive Small-Step Multi-Agent A* for Dec-POMDPs},
  author    = {Koops, Wietze and Jansen, Nils and Junges, Sebastian and Simão, Thiago D.},
  booktitle = {Proceedings of the Thirty-Second International Joint Conference on
               Artificial Intelligence, {IJCAI-23}},
  publisher = {International Joint Conferences on Artificial Intelligence Organization},
  editor    = {Edith Elkind},
  pages     = {5402--5410},
  year      = {2023},
  month     = {8},
  note      = {Main Track},
  doi       = {10.24963/ijcai.2023/600},
  url       = {https://doi.org/10.24963/ijcai.2023/600},
}
TY - CPAPER TI - Recursive Small-Step Multi-Agent A* for Dec-POMDPs AU - Koops, Wietze AU - Jansen, Nils AU - Junges, Sebastian AU - Simão, Thiago D. T2 - Proceedings of the Thirty-Second International Joint Conference on Artificial Intelligence, IJCAI-23 PB - International Joint Conferences on Artificial Intelligence Organization PY - 2023 SP - 5402 EP - 5410 DO - 10.24963/ijcai.2023/600 UR - https://doi.org/10.24963/ijcai.2023/600 ER -Copied
Machine-readable versions of this paper, for tools and AI agents:





