
HyperTrans: Efficient Hypergraph-Driven Cross-Domain Pattern Transfer in Image Anomaly Detection
Proceedings of the Thirty-Fourth International Joint Conference on Artificial Intelligence. Main Track. Pages 2395-2403.
https://doi.org/10.24963/ijcai.2025/267
Keywords
- Computer Vision: CV: Transfer, low-shot, semi- and un- supervised learning
- Computer Vision: CV: Multimodal learning
Abstract
Anomaly detection plays a pivotal role in industrial quality assurance processes, with cross-domain problems, exemplified by the model upgrade from RGB to 3D, being prevalent in real-world scenarios yet remaining systematically underexplored. To address the severe challenges posed by the extreme lack of datasets in target domain, we retain the knowledge from source models and explore a novel solution for anomaly detection through cross-domain learning, introducing HyperTrans. Targeting few-shot scenarios, HyperTrans centers around hypergraphs to model the relationship of the limited patch features and employs a perturbation-rectification-scoring architecture. The domain perturbation module injects and adapts channel-level statistical perturbations, mitigating style shifts during domain transfer. Subsequently, a residual hypergraph restoration module utilizes a cross-domain hypergraph to capture higher-order correlations in patches and align them across domains. Ultimately, with feature patterns exhibiting reduced domain shifts, an inter-domain scoring module aggregates similarity information between patches and normal patterns within the multi-domain subhypergraphs to make an integrated decision, generating multi-level anomaly predictions. Extensive experiments demonstrate that HyperTrans offers significant advantages in anomaly classification and anomaly segmentation tasks, outperforming state-of-the-art non-cross-domain methods in image-wise ROCAUC by 13%, 12%, and 15% in 1-shot, 2-shot, and 5-shot settings on MVTec3D AD.
- [Bai et al., 2024] Shuanghao Bai, Min Zhang, Wanqi Zhou, Siteng Huang, Zhirong Luan, Donglin Wang, and Badong Chen. Prompt-based distribution alignment for unsuper- vised domain adaptation. In Proceedings of the AAAI Con- ference on Artificial Intelligence, volume 38, pages 729- 737, 2024.
- [Bergmann et al., 2021] Paul Bergmann, Xin Jin, David Sat- tlegger, and Carsten Steger. The mvtec 3d-ad dataset for unsupervised 3d anomaly detection and localization. arXiv preprint arXiv:2112.09045, 2021.
- [Caron et al., 2021] Mathilde Caron, Hugo Touvron, Ishan Misra, Hervé Jégou, Julien Mairal, Piotr Bojanowski, and Armand Joulin. Emerging properties in self-supervised vi- sion transformers. In Proceedings of the IEEE/CVF in- ternational conference on computer vision, pages 9650- 9660, 2021.
- [Chen et al., 2023] Ruitao Chen, Guoyang Xie, Jiaqi Liu, Jinbao Wang, Ziqi Luo, Jinfan Wang, and Feng Zheng. Easynet: An easy network for 3d industrial anomaly detec- tion. In Proceedings of the 31st ACM International Con- ference on Multimedia, pages 7038-7046, 2023.
- [Defard et al., 2021] Thomas Defard, Aleksandr Setkov, An- gelique Loesch, and Romaric Audigier. Padim: a patch distribution modeling framework for anomaly detection and localization. In International Conference on Pattern Recognition, pages 475-489. Springer, 2021.
- [Feng et al., 2023] Yifan Feng, Shuyi Ji, Yu-Shen Liu, Shaoyi Du, Qionghai Dai, and Yue Gao. Hypergraph- based multi-modal representation for open-set 3d object retrieval. IEEE Transactions on Pattern Analysis and Ma- chine Intelligence, 2023.
- [Fu et al., 2025] Yuqian Fu, Yu Wang, Yixuan Pan, Lian Huai, Xingyu Qiu, Zeyu Shangguan, Tong Liu, Yanwei Fu, Luc Van Gool, and Xingqun Jiang. Cross-domain few- shot object detection via enhanced open-set object detec- tor. In European Conference on Computer Vision, pages 247-264. Springer, 2025.
- [Gao et al., 2020] Yue Gao, Zizhao Zhang, Haojie Lin, Xibin Zhao, Shaoyi Du, and Changqing Zou. Hypergraph learning: Methods and practices. IEEE Transactions on Pattern Analysis and Machine Intelligence, 44(5):2548- 2566, 2020.
- [Gao et al., 2022] Yue Gao, Yifan Feng, Shuyi Ji, and Ron- grong Ji. Hgnn+: General hypergraph neural networks. IEEE Transactions on Pattern Analysis and Machine In- telligence, 45(3):3181-3199, 2022.
- [Hamilton et al., 2017] Will Hamilton, Zhitao Ying, and Jure Leskovec. Inductive representation learning on large graphs. Advances in neural information processing sys- tems, 30, 2017.
- [Horwitz and Hoshen, 2023] Eliahu Horwitz and Yedid Hoshen. Back to the feature: classical 3d features are (almost) all you need for 3d anomaly detection. In Proceedings of the IEEE/CVF Conference on Computer Vision and Pattern Recognition, pages 2968-2977, 2023.
- [Huang and Belongie, 2017] Xun Huang and Serge Be- longie. Arbitrary style transfer in real-time with adaptive instance normalization. In Proceedings of the IEEE in- ternational conference on computer vision, pages 1501- 1510, 2017.
- [Huang et al., 2022] Chaoqin Huang, Haoyan Guan, Aofan Jiang, Ya Zhang, Michael Spratling, and Yan-Feng Wang. Registration based few-shot anomaly detection. In Eu- ropean Conference on Computer Vision, pages 303-319. Springer, 2022.
- [Jolliffe and Cadima, 2016] Ian T Jolliffe and Jorge Cadima. Principal component analysis: a review and recent devel- opments. Philosophical transactions of the royal soci- ety A: Mathematical, Physical and Engineering Sciences, 374(2065):20150202, 2016.
- [Kipf and Welling, 2022] Thomas N Kipf and Max Welling. Semi-supervised classification with graph convolutional networks. In International Conference on Learning Rep- resentations, 2022.
- [Li et al., 2024] Xurui Li, Ziming Huang, Feng Xue, and Yu Zhou. Musc: Zero-shot industrial anomaly classifi- cation and segmentation with mutual scoring of the unla- beled images. In International Conference on Learning Representations, 2024.
- [Liu et al., 2023] Zhikang Liu, Yiming Zhou, Yuansheng Xu, and Zilei Wang. Simplenet: A simple network for image anomaly detection and localization. In Proceedings of the IEEE/CVF Conference on Computer Vision and Pat- tern Recognition, pages 20402-20411, 2023.
- [Liu et al., 2024] Yingnan Liu, Yingtian Zou, Rui Qiao, Fusheng Liu, Mong Li Lee, and Wynne Hsu. Cross- domain feature augmentation for domain generalization. In International Joint Conference on Artificial Intelli- gence, 2024.
- [Muandet et al., 2013] Krikamol Muandet, David Balduzzi, and Bernhard Schölkopf. Domain generalization via in- variant feature representation. In International conference on machine learning, pages 10-18. PMLR, 2013.
- [Perlin, 1985] Ken Perlin. An image synthesizer. ACM Sig- graph Computer Graphics, 19(3):287-296, 1985.
- [Roth et al., 2022] Karsten Roth, Latha Pemula, Joaquin Zepeda, Bernhard Schölkopf, Thomas Brox, and Peter Gehler. Towards total recall in industrial anomaly detec- tion. In Proceedings of the IEEE/CVF conference on com- puter vision and pattern recognition, pages 14318-14328, 2022.
- [Rudolph et al., 2023] Marco Rudolph, Tom Wehrbein, Bodo Rosenhahn, and Bastian Wandt. Asymmetric student-teacher networks for industrial anomaly detection. In Proceedings of the IEEE/CVF winter conference on ap- plications of computer vision, pages 2592-2602, 2023.
- [Su et al., 2024] Jiapeng Su, Qi Fan, Wenjie Pei, Guangming Lu, and Fanglin Chen. Domain-rectifying adapter for cross-domain few-shot segmentation. In Proceedings of the IEEE/CVF Conference on Computer Vision and Pat- tern Recognition, pages 24036-24045, 2024.
- [Torralba and Efros, 2011] Antonio Torralba and Alexei A Efros. Unbiased look at dataset bias. In IEEE Confer- ence on Computer Vision and Pattern Recognition, pages 1521-1528. IEEE, 2011.
- [Van Den Oord et al., 2017] Aaron Van Den Oord, Oriol Vinyals, et al. Neural discrete representation learning. Advances in neural information processing systems, 30, 2017.
- [Van der Maaten and Hinton, 2008] Laurens Van der Maaten and Geoffrey Hinton. Visualizing data using t-sne. Journal of machine learning research, 9(11), 2008.
- [Wang et al., 2023] Yue Wang, Jinlong Peng, Jiangning Zhang, Ran Yi, Yabiao Wang, and Chengjie Wang. Mul- timodal industrial anomaly detection via hybrid fusion. In Proceedings of the IEEE/CVF Conference on Computer Vision and Pattern Recognition, pages 8032-8041, 2023.
- [Wilson and Cook, 2020] Garrett Wilson and Diane J Cook. A survey of unsupervised deep domain adaptation. ACM Transactions on Intelligent Systems and Technology, 11(5):1-46, 2020.
- [Xie et al., 2023a] Guoyang Xie, Jingbao Wang, Jiaqi Liu, Feng Zheng, and Yaochu Jin. Pushing the limits of fewshot anomaly detection in industry vision: Graphcore. In Inter- national Conference on Learning Representations, 2023.
- [Xie et al., 2023b] Guoyang Xie, Jingbao Wang, Jiaqi Liu, Feng Zheng, and Yaochu Jin. Pushing the limits of fewshot anomaly detection in industry vision: Graphcore. In Inter- national Conference on Learning Representations, 2023.
- [Zavrtanik et al., 2022] Vitjan Zavrtanik, Matej Kristan, and Danijel Skočaj. Dsr-a dual subspace re-projection network for surface anomaly detection. In European conference on computer vision, pages 539-554. Springer, 2022.
- [Zavrtanik et al., 2024] Vitjan Zavrtanik, Matej Kristan, and Danijel Skočaj. Cheating depth: Enhancing 3d surface anomaly detection via depth simulation. In Proceedings of the IEEE/CVF Winter Conference on Applications of Com- puter Vision, pages 2164-2172, 2024.
- [Zhang et al., 2022] Min Zhang, Siteng Huang, and Donglin Wang. Domain generalized few-shot image classification via meta regularization network. In IEEE International Conference on Acoustics, Speech and Signal Processing, pages 3748-3752. IEEE, 2022.
- [Zhou et al., 2021] Kaiyang Zhou, Yongxin Yang, Yu Qiao, and Tao Xiang. Domain generalization with mixstyle. In International Conference on Learning Representations, 2021.
- [Zuo et al., 2024a] Zuo Zuo, Yao Wu, Baoqiang Li, Jiahao Dong, You Zhou, Lei Zhou, Yanyun Qu, and Zongze Wu. Clip-fsac: Boosting clip for few-shot anomaly classifica- tion with synthetic anomalies. In International Joint Con- ference on Artificial Intelligence, 2024. IJCAI
- [Zuo et al., 2024b] Zuo Zuo, Zongze Wu, Badong Chen, and Xiaopin Zhong. A reconstruction-based feature adaptation for anomaly detection with self-supervised multi-scale ag- gregation. In IEEE International Conference on Acoustics, Speech and Signal Processing, pages 5840-5844. IEEE, 2024.
References were extracted automatically from the PDF and may contain errors.
Full text extracted automatically from the PDF; figures, tables and equations may differ. The PDF is the version of record.
1 Introduction
Image anomaly detection aims to identify abnormal images and segment anomalous subregions, playing a vital role in industrial quality control [Defard et al., 2021; Roth et al., 2022]. Traditional methods have predominantly relied on the RGB modality, achieving significant progress [Zuo et al.,
∗Co-Correpsonding Authors.
2024b; Li et al., 2024]. However, advancements in technology have facilitated the adoption of image acquisition devices with multiple modalities, introducing pervasive crossdomain [Torralba and Efros, 2011] challenges. Among these, the shift to 3D is the most representative, as 3D sensors provide unique advantages for detecting depth-related defects [Zavrtanik et al., 2024]. This transition has increased demand for model upgrades. Various approaches have been proposed from a non-cross-domain perspective, including point cloud-based methods [Wang et al., 2023] and depth map-based methods [Chen et al., 2023; Liu et al., 2023], applied in both single-modal and multi-modal scenarios.
However, these non-cross-domain methods encounter inherent challenges. Multi-modal approaches, which rely on the collaborative input of both source and target data, impose high demands on acquisition devices and modality alignment. Single-modal methods, which retrain the sourcespecific model, tend to discard valuable information embedded in the original source model-information, optimized with extensive validated data. Furthermore, all existing approaches encounter substantial challenges due to the limited availability of target datasets, which are characterized by extreme scarcity and insufficient labeled samples. This limitation hinders the effective training of large-scale target models, particularly during the initial phases when acquiring adequate labeled data remains a resource-intensive endeavor.
To address these challenges and preserve the effective supervisory signals in the source model, we introduce and explore the feasibility of cross-domain (CD) adaptation [Wilson and Cook, 2020; Zhang et al., 2022] in industrial anomaly detection. This approach transfers and fine-tunes the source model for other domains. To further mitigate the issue of limited target domain data, we emphasize few-shot learning (FS) scenarios [Huang et al., 2022; Xie et al., 2023a]. Specifically, we conduct the first dedicated study on the problem of Cross-Domain Few-Shot Image Anomaly Detection (CDFSAD), which transfers knowledge from the source domain and leverages few-shot samples from the target domain, providing an innovative solution to anomaly detection.
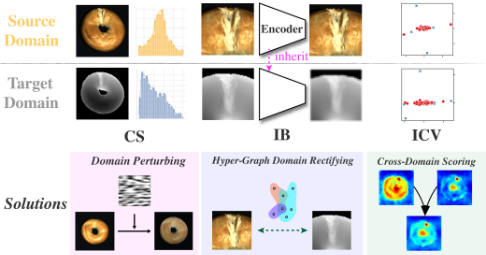
Cross-domain adaptation in defect detection poses significant challenges. As illustrated in Figure 1, images captured by different sensors exhibit significant disparities. Achieving domain alignment is impeded by three key factors: 1) changes in image style (CS), which hinder feature extraction; 2) blurred boundaries (IB), which degrade anomaly segmentation accuracy; and 3) inter-class variance (ICV) [Fu et al., 2025], which compromises defect classification precision. To systematically address these challenges, we propose an innovative perturbation-rectification-scoring framework named HyperTrans, which maximizes the exploitation of source-domain information by hierarchically aligning and scoring patches across domains, achieving cross-domain generality and defect-detection specificity.
Specifically, a domain perturbation module injects channel-level perturbations to simulate new domain styles, followed by a lightweight adapter to align these features with the original domain, improving generalization. Furthermore, limited samples exhibit inherent relational information, as different patches from both domains may share similar properties, such as reflecting translation and rotation invariance of the same object attributes. To capture this higherorder correlations and enhance boundary delineation, we construct cross-domain hypergraphs [Hamilton et al., 2017; Gao et al., 2020; Kipf and Welling, 2022; Feng et al., 2023] that link patches globally across samples and domains. A residual hypergraph convolutional network (ResHGNN) further integrates and refines these latent relationships, with pseudo-features designated for target domain features, enabling effective cross-domain feature alignment.
While improving target domain adaptability, the previous training strategy also brings the source and target domain patches closer, thereby enhancing the utility of the source domain bank. Consequently, we incorporate the source domain bank into inference and propose a cross-domain scoring module leveraging subhypergraphs to assign anomaly scores and segmentation maps. By synthesizing differential outcomes between normal patterns across domains and query features, the module offers a unified solution to ICV and enables more precise anomaly classification and segmentation.
Our main contributions are listed as follows:
- We pioneer the application of domain adaptation to image anomaly detection and propose an innovative perturbation-rectification-scoring framework tailored for cross-domain few-shot scenarios, facilitating
- efficient knowledge transfer between domains with minimal labeled data.
- We design a compact hypergraph cross-domain anomaly detection module. Centered on hypergraph, three key functions are implemented: a residual hypergraph convolutional network to model cross-domain higher-order correlations, a pseudo-feature generation method to guide the alignment and a cross-domain scoring method leveraging cross-domain normal patch patterns to facilitate anomaly detection.
- Comprehensive experiments validate the superiority of the proposed model, significantly outperforming other state-of-the-art non-cross-domain methods in few-shot anomaly detection tasks and establishing a benchmark for cross-domain few-shot anomaly detection.
2 RelatedWorks
2.1 Image Anomaly Detection
Anomaly detection identifies rare data points that indicate defects in industrial production [Defard et al., 2021; Roth et al., 2022]. Similar to surface anomaly detection [Zavrtanik et al., 2022], both aim to recognize unexpected patterns in data or images. Methods for anomaly detection can be broadly classified into two categories: contrastive reasoning based methods and meta-learning based methods. Among the contrastive methods, image-level contrastive reasoning focuses on comparing entire images, such as in SimpleNet [Liu et al., 2023], which learns simpler representations for anomaly detection through image-level reconstruction. Feature-level contrastive reasoning compares features extracted from images, and includes methods like PatchCore [Roth et al., 2022], which performs anomaly detection by comparing feature patches. Instead, DSR [Zavrtanik et al., 2022], which trains a general VQ-VAE [Van Den Oord et al., 2017] and a specialized decoder to output anomaly maps, can be categorized as a meta-learning-based method. Similarly, AST [Rudolph et al., 2023] is also a meta-learning based method, as it employs a student-teacher architecture and utilizes knowledge distillation for anomaly detection. However, neither method can solve the cross-domain problem, as its model cannot adapt well to the diverse styles of features on the target domain.
2.2 Few-shot and Cross-domain Learning
In few-shot defect detection, many methods have been explored. For example, CLIP-FSAC [Zuo et al., 2024a] leverages the high generalization ability of the CLIP model and uses an alternately trained adapters to enable few-shot defect classification, demonstrating that adapters are effective for transferring the model to new domains. Additionally, graphbased methods have shown promising results by exploiting the correlation information between samples. The graph structure can effectively reduce the reliance on the number of samples by leveraging information from a few samples [Xie et al., 2023b]. In this work, we generalize this idea to hypergraph and extend it to model cross-domain feature patterns. Although cross-domain approaches have not been exclusively explored in defect detection, many general crossdomain frameworks [Muandet et al., 2013; Liu et al., 2024;
Fu et al., 2025] have emerged in recent years and can serve as paradigms. For instance, PDA [Bai et al., 2024] also inherits the high generalization capability of the CLIP model and utilizes cross-domain memory banks with a cross-attention enhancement mechanism, addressing the domain adaptation problem and more relevantly, demonstrating the effectiveness of memory banks in cross-domain tasks. DR-Adapter [Su et al., 2024] achieves top results in cross-domain few-shot segmentation through perturbations and a novel cyclic perturbation correction model. However, it is a one-to-one correction mode and lacks targeted exploration of relationships in small sample settings. By leveraging these approaches and uncovering high-order patch correlations, we introduce crossdomain few-shot learning to anomaly detection via the HyperTrans framework, which is tailored for defect detection and holds broader cross-domain applicability.
3 Methodology
3.1 ProblemDefinition
A typical defect detection task includes anomaly classification (AC) and anomaly segmentation (AD) [Li et al., 2024]. The dataset is divided into a normal sample set N and an anomaly sample set A. The goal is to train a model f(·) in an unsupervised manner, using only normal samples from dataset x ∈ N, to produce output consisting of a binary classification result for defect detection (denoted as a) and a binary semantic segmentation result for defect localization (denoted as S), where the classification result a is more primary. The whole process can be expressed as:
Cross-domain few-shot anomaly detection aims at generalizing and transferring the applicability from the source domain to the target domain, where only a few normal samples are available for training. Formally, given a model f(·) trained with data from the source domain x ∈ Ns and fewshot target domain normal samples N few-shot t , the task is to align the model to mitigate the issue of domain discrepancy between Ns ∪ As and Nt ∪ At. The training process is conducted on the source domain followed by fine-tuning on the target domain, and the inference process is performed on the target domain, which can be denoted as:
3.2 Hyper-graph Cross-domain Few-shot Anomaly Detection Framework
Overview
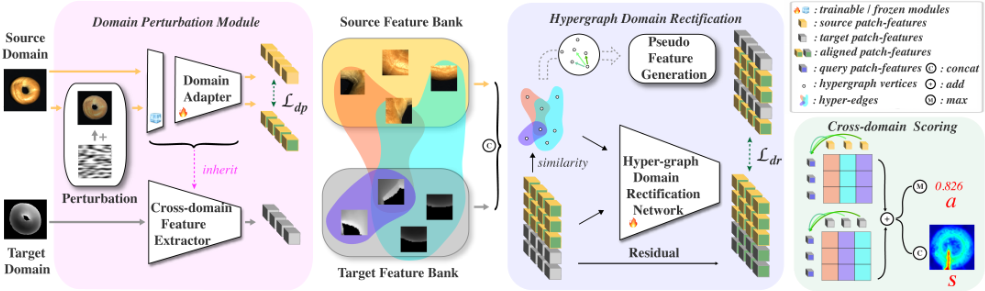
To accomplish CD-FSAD, we propose a novel framework called HyperTrans, with its architecture illustrated in Figure 2. The training process is firstly conducted on the sourcedomain, where the domain adapter is optimized with perturbed patches and a source-domain feature bank is generated. Correspondingly the target feature bank is generated with few-shot target samples. The two banks are united to construct a cross-domain hyper-graph, representing the higher-order correlations between patches. Subsequently, a pseudo-feature is assigned to each feature through the hypergraph, and the distances between them are reduced by the hyper-graph residual network to correct the cross-domain feature shift. During the inference process, the the source and target domain subhypergraphs are separately contracted along hyperedges to compute the anomaly score of patches, and the vertice-level results are weighted and integrated to form the image-wise anomaly score and pixel-wise anomaly map.
Domain Perturbation
Previous studies [Zhou et al., 2021; Su et al., 2024] have shown that perturbing channel statistics can effectively simulate different domain styles, thereby enhancing the domain adaptability. Building on this insight, we apply this technique to simulate diverse image patches extracted by the backbone.
For clarity, we denote the feature extractor symbolically as B(·), which derives patch features F = B(Ns) from the source samples Ns. Given the feature set F ∈ Rn×c×h×w , the mean avg(·) and variance std(·) are first calculated to represent feature channel statistics:
where n is the number of patches, c is the number of channels, h and w represent the height and weight of the patches. In defect detection, changes are typically localized and abrupt. Therefore, instead of using Gaussian noise, we design an alternative mechanism based on Perlin noise [Perlin, 1985] to better approximate smooth local variations in spatial structures and perturb the channel statistics (mean and variance) of feature maps. Specifically, two perturbation factors, Pavg and Pstd, are generated using Perlin noise, with dimensions matching the feature channels. These factors are applied to adjust the original mean and standard deviation as follows:
The perturbed statistics are then integrated into the Adaptive Instance Normalization (AdaIN) formula [Huang and Belongie, 2017] to compute the modified feature map:
To simplify, this can be rewritten as:
Such perturbations are accommodated by a learnable adapter of the deep layers of the backbone. To bring the simulated features Fp closer to the original features Fo, a domain perturbation loss with Mean Squared Error (MSE) is developed as the objective function, formally expressed as:
where ∥ · ∥2 denotes calculating the 2-norm of the matrix. n is the number of elements in the patch.
This approach dynamically adjusts the perturbation of the mean and variance using Perlin noise, leveraging its smooth, spatially coherent properties. Unlike direct noise addition, this method seamlessly integrates the perturbations with the feature map's channel statistics, resulting in spatially consistent and locally adaptive feature variations. Subsequently, through Ldp, the adaptability of the original backbone to different domain styles is augmented.
Hyper-graph Domain Rectification
To mitigate the domain discrepancy of patch features across different domains, we designed a cross-domain hypergraph feature correction module (HDR) centered on hypergraphs. Samples from the source and target domains represent different manifestations of the same object, with intra-domain and inter-domain patches exhibiting correlations-such as describing the same attributes of an object. Hypergraph is utilized to bridge such high-order correlations. Unlike edges in simple graphs, hyperedges in hypergraphs naturally simulate the attribute features shared among multiple vertices.
Each core patch in the banks from different domains is treated as a vertex. If let Fs denote the set of patches from the source domain and Ft denote the patches from the target domain, the cross-domain hypergraph can be represented as G = {Fs ∪ Ft, E,W}, where E is the hyperedge set. W ∈ R|E|×|E| is a diagonal matrix, where Wi,i denotes the weight of the i-th hyperedge.
The hyperedges are constructed based on the nodes with the reciprocal of Euclidean distance being the similarity metric. A hyperedge is created for each node, connecting it to other nodes based on similarity. For a source feature bank containing |Fs| patches and a target bank with |Ft| patches, a total of |Fs|+|Ft| hyperedges are constructed in this manner.
For computational convenience, the hypergraph is represented in matrix form as H ∈ [0, 1]|Fs∪Ft|×|E| where each row represents the vertex and each column represents a hyperedge. The value of Hi,j ∈ [0, 1] indicates the correlation from i-th vertex to the j-th hyperedge. To leverage the highorder relational information embedded in the hypergraph to guide feature rectification, a hypergraph convolution [Gao et al., 2022] (HGNNConv) is employed. It is based on hypergraph convolution layers c(·), defined as follows:
where Dv and De are the diagonal degree matrices for vertex and hyperedge, respectively. Θ ∈ R is the trainable parameter for the HGNNConv layer. By applying HGNNConv on the hypergraph constructed from cross-domain patches, the generated structure-aware embeddings can capture latent collaborative information from both the source and target domains.
The final hypergraph network is constructed with two layers of HGNNConv. Additionally, a residual structure is equipped to preserve the original features and reduce the compromise of feature correction on the original information. The overall output of the Res-HGNN is expressed as:
where α is a hyperparameter to balance the corrected and original features. The dropout rate is set to 0.5.
The pseudo feature generation is then developed to assign a prototype to each patch by leveraging the correlation information within the hypergraph. Specifically, for each node in the hypergraph, the feature of the most correlated node within its corresponding hyperedges is selected as the pseudo feature. In matrix form, the generation process can be denoted as:
where g(a, b) represents extracting elements from matrix a based on index list b and max index(·) outputs the index of the largest component for each row. InHc , non-cross-domain connections are set to 0.
To align the output features with the pseudo features and the original ones, Mean Squared Error is adopted:
Cross-domain Scoring
The feature bank from the source domain stores extensive information about normal samples. Relying on the feature bank for inference solely on target domain samples is insufficient, as it neglects the valuable information from source domain. Initially, due to domain shift, the differences between the source domain's feature bank and the original normal features of the target domain are significant, greatly impacting the effectiveness of defect scoring. However, the preceding domain perturbation and rectification modules align the target domain features generated by the model with the source domain features, mitigating the effects of domain shift. This alignment enhances the utility of the source domain bank for comparative scoring in the target domain. To further capitalize on this, we propose a cross-domain scoring module.
For each image I from the target domain requiring inference, we denote its patch feature set as F = R(B(I)), from which f is a specific patch feature. In the first step, the patches to be inferred are incorporated alongside the source and target domain banks to build the hypergraph H. To separately leverage the similarity information from both the source and target domains, the hypergraph matrix H is split. The source domain subhypergraph Hs ∈ [0, 1]|F|×|Fs| preserves the correlations between target features to be inferred and source feature bank, while the target domain subhypergraph Ht ∈ [0, 1]|F|×|Ft| preserves correlations of query target features and target feature bank. Subsequently, a defect score is assigned to each patch leveraging the subhypergraph from the source domain Hs , and the maximum score among all patches is taken as the image-level anomaly score:
where max(·) returns the max element of a vector and Hs (f) is the row with f being the vertex in the subhypergraph matrix in the source domain Hs . The pixel-wise anomaly map is obtained by rearranging patch anomaly scores based on their respective spatial positions:
The procedure is also adopted to assign anomaly score and segmentation map with the target domain subhypergraph:
The final image-wise anomaly score a and pixel-wise anomaly map S are obtained by combining the results of multiple domains with a parameter β to balance the impact of information from source and target domain:
To match the original input resolution, the final anomaly map is upsampled using bilinear interpolation. Additionally, a Gaussian function with a kernel width of σ = 4 is applied to smooth the results.
3.3 Model Training
Benefiting from the above observation, we propose a twostage learning strategy to train the whole model. The first stage will employ the domain perturbation loss Formula (7) to optimize the domain adapter in DP. Then, the model switch into the second stage with the domain rectification loss, i.e., Formula (11), to optimize the parameters in Res-HGNN. The overall procedure is illustrated in Algorithm 1.
Algorithm 1 Optimization algorithm for HyperTrans
Input: Backbone B(·), domain perturbing module ω(·), normal samples from source domain Ns, few-shot normal samples from target domain Nt, original parameters in domain adapter Θ, initialized parameters of Res-HGNN {Θ1, Θ2}
Parameters: epochsP, epochsR, ...
Output: Memory banks {Ms,Mt}, optimized parameters {Θ, Θ1, Θ2}
1: while training do 2: for e = 1 → epochsP do 3: F ←- B(Ns), Fp ←- ω(F) 4: Θ optim ←---- Ldp(F, Fp) 5: end for 6: while constructing feature banks do 7: Fs ←- B(Ns), Ft ←- B(Nt) 8: Ms store ←--- Fs, Mt store ←--- Ft 9: end while 10: for e = 1 → epochsR do 11: F ←- B(Nt) ∪Ms, 12: Fr ←-R(B(F)), Fpse ←- S(F) 13: {Θ1,Θ2} optim ←---- Ldr (Fr , Fpse) 14: end for- 15: end while
4 Experiments
4.1 Experimental Settings
Dataset: The MVTec-3D AD dataset [Bergmann et al., 2021] is a standard 3D anomaly detection dataset, on which our experiments are performed. It consists of 10 categories, a total of 2656 training samples, and 1137 testing samples. The 3D scans were acquired by a high-resolution industrial 3D sensor using structured light. Due to the scarcity of defective samples, only normal samples are contained in the training set of MVTec-3D AD, while the testing set contains both normal and defective samples. The following experiments are carried out on it, with RGB data as the source domain and the XYZ data preprocessed into depth images to be the target domain.
Implementation Details: We implement HyperTrans using PyTorch2.4.0 and conduct evaluations on an NVIDIA A100. The ViT base patch8 224 dino [Caron et al., 2021] serves as the backbone. The domain perturbation module is integrated into layers 3 to 10 of the backbone, employing Perlin noise with a mean of 0 and a standard deviation of 0.75 for domain perturbations. 1
EvaluationMetrics: Models are evaluatedwithROCAUC in image and pixel orientation (Receiver operating characteristic - Area under the curve), which is a metric to evaluate the performance of a classifier by calculating the area under the ROC curve at various thresholds. The image-wise ROCAUC evaluates the performance based on the classification of entire images as defective or non-defective, while the pixel-wise ROCAUC assesses the ability to correctly classify each individual pixel as part of a defect or not. Initial values of other parameters are listed in Table 2.
1 https://github.com/raRn0y/HyperTrans
| Task | Type | Method | Backbone | bagel | cable gland | carrot | cookie | dowel | foam | peach | potato | rope | tire | AVG 1 |
|---|---|---|---|---|---|---|---|---|---|---|---|---|---|---|
| Target 1-shot | Depth iNet [Horwitz and Hoshen, 2023] SIFT [Horwitz and Hoshen, 2023] AST [Rudolph et al., 2023] 3DSR [Zavrtanik et al., 2024] M3DM [Wang et al., 2023] | ResNet 0.486 SIFT EfficientNet VQ-VAE ViT | 0.502 0.642 0.665 0.754➁ | 0.587 0.476 0.598 0.613➀ 0.549 | 0.615 0.503 0.693 0.562 0.718➁ | 0.814 0.651 0.821➁ 0.610 0.582 | 0.598 0.688 ➀ 0.581 0.599 0.64➁ | 0.589 0.574 0.532 0.601➁ 0.791➀ | 0.460 0.553 0.654 0.531 0.772➁ | 0.584 0.536 0.595 0.603➁ 0.576 | 0.619 0.580 0.911➁ 0.651 0.801 | 0.625 0.541 0.531 0.519 0.68➀ | 0.598 0.560 0.656 0.595 0.686➁ | |
| Img 2 | Target | Depth iNet [Horwitz and Hoshen, 2023] SIFT [Horwitz and Hoshen, 2023] AST [Rudolph et al., 2023] 3DSR [Zavrtanik et al., 2024] | ViT ResNet SIFT EfficientNet VQ-VAE ViT | 0.816➀ 0.522 0.562 0.722 0.565 | 0.606➁ 0.496 0.420 0.602 0.623➀ 0.607➁ 0.581 | 0.957➀ 0.639 0.543 0.713 0.575 0.762➁ 0.965➀ 0.675 | 0.955➀ 0.822 0.579 0.84➁ 0.531 0.626 0.958➀ 0.852➁ 0.777 0.764 | 0.463 0.599 0.613➁ 0.548 0.568 0.683➀ 0.551 0.675➁ 0.614 0.455 | 0.569 0.529 0.634➁ 0.505 0.551 0.708➀ 0.489 0.599 0.591 0.556 0.627➁ 0.704➀ 0.621 | 0.926➀ 0.475 0.567 0.676 0.567 0.809➁ 0.962➀ 0.474 0.530 0.601 0.599 0.863➁ 0.954➀ | 0.926➀ 0.663➁ 0.506 0.570 0.521 0.601 0.99➀ 0.683 | 0.921➀ 0.662 0.769 0.909➀ 0.624 0.827 0.909➀ | 0.64➁ 0.584➁ 0.530 0.522 0.567 0.571 0.646➀ 0.526 0.528 0.445 0.602➁ | 0.778➀ 0.599 0.572 0.654 0.569 0.71➁ 0.798➀ 0.629 0.588 0.624 0.607 0.721➁ |
| 2-shot Target 5-shot | HyperTrans M3DM [Wang et al., 2023] HyperTrans Depth iNet [Horwitz and Hoshen, 2023] SIFT [Horwitz and Hoshen, 2023] AST [Rudolph et al., 2023] 3DSR [Zavrtanik et al., 2024] M3DM [Wang et al., 2023] HyperTrans Depth iNet [Horwitz and Hoshen, 2023] SIFT [Horwitz and Hoshen, 2023] AST [Rudolph et al., 2023] 3DSR [Zavrtanik et al., 2024] M3DM [Wang et al., 2023] HyperTrans Depth iNet [Horwitz and Hoshen, 2023] SIFT [Horwitz and Hoshen, 2023] | ViT ResNet SIFT EfficientNet VQ-VAE ViT ViT | 0.909➁ 0.93➀ 0.592 0.568 0.739 0.603 0.921➀ 0.92➁ 0.940 | 0.504 0.371 0.519 0.600 0.631➀ 0.631➀ | 0.601 0.639 0.578 0.781➁ 0.998➀ | 0.576 0.585 0.981➀ 0.963➁ 0.931 0.628 | 0.613 0.831➀ 0.604 0.938 0.942 | 0.744 0.876➁ 0.556 0.573 0.826 | 0.951 0.974➁ 0.684 0.657 | 0.689➁ 0.658 0.600 0.579 0.996➀ | 0.708 0.607 0.863➁ 0.672 0.801 0.904➀ | 0.512 0.697➀ 0.597 0.590 | 0.831➀ 0.893 0.949➁ 0.713 0.632 0.861 | |
| Target 1-shot | [Rudolph et al., 2023] [Zavrtanik et al., 2024] [Wang et al., 2023] | ResNet SIFT EfficientNet VQ-VAE ViT ViT ResNet | 0.969➁ 0.929 0.441 0.954 0.984➀ | 0.911 0.923➁ 0.516 0.498 0.859 0.935➀ | 0.966 0.988➁ 0.925 0.868 0.965 0.997➀ | 0.705 0.959 0.976➀ | 0.543 0.747 0.956➀ 0.954➁ | 0.895➀ 0.752 0.897➁ 0.564 | 0.959 0.995➀ 0.957 0.972➁ 0.678 | 0.958 0.993➁ 0.853 0.906 0.913 0.998➀ | 0.962 0.971➁ 0.910 0.362 0.967 0.992➀ | 0.923➀ 0.567 0.247 0.821➁ 0.497 | 0.955➀ | |
| Pix 3 | Target 2-shot | AST 3DSR M3DM HyperTrans | 0.944 0.973➁ 0.940 0.544 0.960 | 0.918 0.927➁ 0.507 0.810 | 0.966 0.99➁ 0.925 0.884 | 0.967➁ 0.932 0.639 0.692 0.962 | 0.913 0.943 0.539 0.748 | 0.612 0.804 | 0.601 0.967 | 0.960 0.993➁ 0.863 0.870 0.910 0.999➀ | 0.966 0.978➁ 0.929 0.411 0.968 | 0.522 0.611 0.629 | 0.884 0.955➁ 0.711 0.678 0.896 | |
| iNet [Horwitz and Hoshen, 2023] [Horwitz and Hoshen, 2023] | 0.840 0.937➀ | 0.965 0.998➀ | 0.984➀ 0.967➁ 0.940 0.614 | 0.956➁ 0.967➀ 0.944 0.956➁ | 0.901➀ 0.747 0.89➁ | 0.996➀ 0.959 | 0.958 | 0.995➀ | 0.561 | 0.96➀ | ||||
| Depth SIFT AST [Rudolph et al., 2023] 3DSR [Zavrtanik et al., 2024] M3DM [Wang | SIFT EfficientNet VQ-VAE ViT ViT | 0.989➀ 0.946 0.974➁ | 0.884 | 0.967 | 0.594 | 0.977➁ 0.601 | 0.995➁ 0.944 | 0.971 | 0.941➀ 0.834➁ | 0.890 | ||||
| SIFT et al., 2023] ViT | 0.958 0.619 | 0.925➁ 0.519 0.833 | 0.867 0.675 | 0.692 | 0.485 | 0.569 | 0.864 | 0.931➀ 0.445 | 0.956➁ 0.689 | |||||
| Target 5-shot | ResNet EfficientNet VQ-VAE | 0.960 | 0.500 | 0.633 | 0.390 | 0.976➁ 0.420 | 0.717 | 0.605 | ||||||
| 0.962 | ||||||||||||||
| 0.770 | 0.993➁ 0.968 | 0.959➀ | 0.970 | 0.912 | 0.973 0.993➀ | 0.556 | 0.881 | |||||||
| 0.992➀ | 0.98➀ | 0.775 | 0.9➁ | |||||||||||
| HyperTrans ViT | 0.935➀ | 0.997➀ | 0.955 | 0.895➀ | 0.996➀ | 0.999➀ | 0.964➀ |
| α | β | epochsP | epochsR |
| 0.3 | 0.6 | 3 | 100 |
4.2 Comparision Experiments
Statistics: To verify the few-shot general anomaly detection performance, we compare HyperTrans with advanced depth methods. The image-wise and pixel-wise ROCAUCs are reported in Table 1. It can be concluded that source models generally have limited domain adaptability. When handling tasks with domain shift, most methods suffer from great accuracy loss, most of which come from the model design targeting source characteristics and the deep fitting of network to source data. With only a few depth samples (1, 2 and 5 samples for each classes) given, HyperTrans achieves the SOTA depth-domain performance in the task of cross-domain anomaly classification and segmentation. The advantage is more significant on the primary metric of image-wise ROCAUC with an improvement of 13%, 12% and 15% on 1, 2 and 5 shot settings compared with the best non-cross-domain methods. Tracing the image-wise results, HyperTrans improves the distinguishability on anomaly samples and alleviates the issue of inter-class variance. From the pixel-wise results, it enhances feature clarity and, through cross-domain joint inference-making, mitigates the problem of IB.
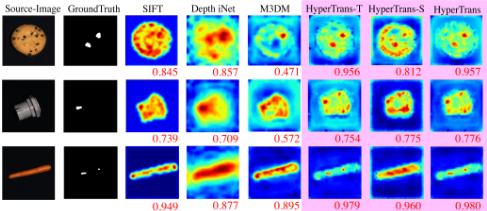
Visualizations: Figure 3 shows intuitive examples of predicted segmentation maps. HyperTrans achieves the best segmentation, effectively addressing the issue of IB.
4.3 Parameter Analysis
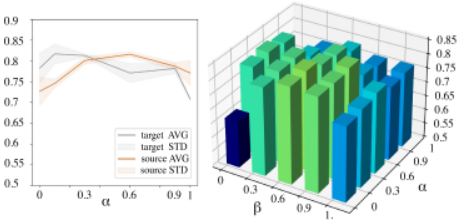
To evaluate the impact of α (residual on hypergraph crossdomain feature alignment), β (the influence of the source and target domains during inference), and the cross-interaction between feature alignment and inference, we conducted a series of parameter analysis experiments on the two parameters. The results are shown in Figure 4. As α increases, the crossdomain enhancement component increases, while the residual component decreases. From Figure 4 (Left), it can be seen that due to the fitting of HDR module on the source domain, the results relying on source domain patterns show an increase in fluctuations, while the results on the target domain gradually decrease. Therefore it's necessary to introduce β to balance the weight of source and target domain for inference and study the cross impact of α and β. From Figure 4 (Right), it can be concluded that HyperTrans achieves the best average ROCAUC on the test set when α = 0.3, β = 0.6 and the introduction of both components is essential.
| DP | HDR | CDS | I-ROCAUC |
|---|---|---|---|
| ✗ | ✗ | ✗ | 0.813 ± 0.203 |
| ✓ | ✗ | ✗ | 0.817 ± 0.257 |
| ✗ | ✓ | ✗ | 0.826 ± 0.217 |
| ✗ | ✗ | ✓ | 0.817 ± 0.233 |
| ✓ | ✓ | ✓ | 0.831 ± 0.158 |
4.4 Ablation Studies
Impact of EachModules: To measure the impact of each losses on the results and the effectiveness of each component in the framework, we conduct an ablation analysis with results shown in Table 3. We observe a consistent performance improvement with the introduction of each proposed modules, and the combination of them improves the averaged results by 0.018. This improvement is attributed to the effectiveness of cross-domain alignment, which not only mitigates the issues highlighted in Figure 1 but also brings the source and target domain patches closer. This proximity enhances the utility of the source domain bank, further improving the inference performance of the CDS mechanism.
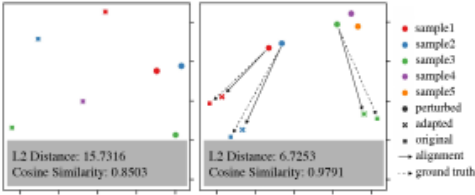
Impact of Domain Perturbation: The DPmodule aims to simulate samples from various domains with channel statistic noise injection, guiding the model to adapt to non-existent domain styles in advance. t-SNE [Van der Maaten and Hinton, 2008] in Figure 5 shows that the perturbed features, after undergoing correction through this module, become closer to the original ones, demonstrating its effectiveness.
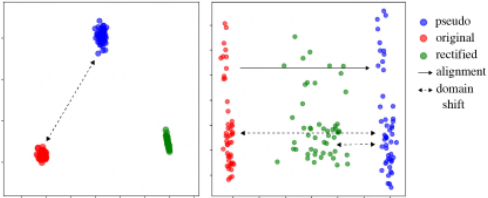
Impact of Hypergraph Domain Rectification: The HDR module provides a global correction across domains. We visualize its impact with PCA [Jolliffe and Cadima, 2016] in Figure 6. Comparing the distributions of the original patches with those of the HDR-enhanced patches, the representation spaces of the source and target samples become closer and the features are more aligned. This reduces the domain shift and enhances the utility of source bank during inference.
5 Summary
In this paper, we pioneer the exploration of cross-domain learning in image anomaly detection and introduce CDFSAD, a task designed to enable the effective transfer of knowledge for anomaly detection in few-shot learning scenarios. A novel perturbation-rectification-scoring solution named HyperTrans is then developed. The domain perturbation module simulates target domain styles using statistical Perlin noise, while the domain rectification module employs hypergraphs to capture higher-order cross-domain feature correlations, integrating residual hypergraph convolution and pseudo-feature generation for alignment. During inference, a cross-domain scoring method jointly leveraging multi-domain subhypergraph similarity information for multi-level anomaly reasoning. Extensive experiments validate that HyperTrans achieves SOTA performance, significantly outperforming non-cross-domain methods in classification and segmentation tasks, and providing a scalable, efficient and universal solution for image anomaly detection.
Acknowledgements
This work was supported in part by the Grants of Guangdong Major Project of Basic and Applied Basic Research (2023B0303000009) and the National Major Scientific Instruments and Equipments Development Project of National Natural Science Foundation of China under Grant (62327808) and the Shenzhen University 2035 Program for Excellent Research (00000224), and the National Natural Science Foundation of China Project (62403326).
@inproceedings{ijcai2025p267,
  title     = {HyperTrans: Efficient Hypergraph-Driven Cross-Domain Pattern Transfer in Image Anomaly Detection},
  author    = {Zhang, Tengyu and Zeng, Deyu and Li, Baoqiang and Wang, Wei and Liu, Wei and Wu, Zongze},
  booktitle = {Proceedings of the Thirty-Fourth International Joint Conference on
               Artificial Intelligence, {IJCAI-25}},
  publisher = {International Joint Conferences on Artificial Intelligence Organization},
  editor    = {James Kwok},
  pages     = {2395--2403},
  year      = {2025},
  month     = {8},
  note      = {Main Track},
  doi       = {10.24963/ijcai.2025/267},
  url       = {https://doi.org/10.24963/ijcai.2025/267},
}
TY - CPAPER TI - HyperTrans: Efficient Hypergraph-Driven Cross-Domain Pattern Transfer in Image Anomaly Detection AU - Zhang, Tengyu AU - Zeng, Deyu AU - Li, Baoqiang AU - Wang, Wei AU - Liu, Wei AU - Wu, Zongze T2 - Proceedings of the Thirty-Fourth International Joint Conference on Artificial Intelligence, IJCAI-25 PB - International Joint Conferences on Artificial Intelligence Organization PY - 2025 SP - 2395 EP - 2403 DO - 10.24963/ijcai.2025/267 UR - https://doi.org/10.24963/ijcai.2025/267 ER -Copied
Machine-readable versions of this paper, for tools and AI agents:





