
Multi Objective Quantile Based Reinforcement Learning for Modern Urban Planning
Proceedings of the Thirty-Fourth International Joint Conference on Artificial Intelligence. Main Track. Pages 232-239.
https://doi.org/10.24963/ijcai.2025/27
Keywords
- Agent-based and Multi-agent Systems: MAS: Applications
- Agent-based and Multi-agent Systems: MAS: Multi-agent learning
- Agent-based and Multi-agent Systems: MAS: Agent-based simulation and emergence
Abstract
We present a novel Multi-Agent Reinforcement Learning approach to understand and improve policy development by land-shaping agents, such as governments and institutional bodies. We derive the underlying policy decisions by analyzing the land and developing an intelligent system that proposes optimal land conversion strategies. The aim is an efficient method for allocating residential spaces while considering the dynamic population influx in different regions, jurisdictional constraints, and the intrinsic characteristics of the land. Our main goal is to be sustainable, preserving desirable land types such as forests and fluvial lands while optimizing land organization. We introduce an attractiveness metric that quantifies the proximity to different land types and other factors to optimize land usage. It distinguishes two types of agents: ``top-down'' agents, which are policymakers and shareholders, and ``bottom-up'' agents representing individuals or groups with specific housing preferences. Our main objective is to create a synergistic environment where the top-down policy meets the bottom-up preferences to devise a comprehensive land use and conversion strategy. This paper, thus, serves as a pivotal reference point for future urban planning and policy-making processes, contributing to a sustainable and efficient landscape design model.
- [Bellemare et al., 2017] Marc G. Bellemare, Will Dabney, and Rémi Munos. A distributional perspective on reinforce- ment learning. In Proceedings of the 34th International Conference on Machine Learning, pages 449-458. PMLR, 2017.
- [Bone et al., 2011] Christopher Bone, Suzana Dragicevic, and Roger White. Modeling-in-the-middle: bridging the gap between agent-based modeling and multi-objective decision-making for land use change. International Jour- nal of Geographical Information Science, 25(5):717-737, 2011.
- [Dabney et al., 2018] Will Dabney, Mark Rowland, Marc G. Bellemare, and Rémi Munos. Implicit quantile networks for distributional reinforcement learning. In International conference on machine learning, pages 1104-1113. PMLR, 2018.
- [Li and Yeh, 2002] Xia Li and Anthony Gar-On Yeh. Neural- network-based cellular automata for simulating multiple land use changes using gis. International Journal of Geo- graphical Information Science, 16(4):323-343, 2002.
- [Liu et al., 2015] Chunming Liu, Xin Xu, and Dewen Hu. Multiobjective reinforcement learning: A comprehensive overview. IEEE Transactions on Systems, Man, and Cyber- netics: Systems, 45(3):385-398, 2015.
- [Pelcner et al., 2024] Lukasz Pelcner, Matheus Aparecido do Carmo Alves, Leandro Soriano Marcolino, Paula Harrison, and Peter Atkinson. Incentive-based marl approach for commons dilemmas in property-based environments. In Proceedings of the 23rd International Conference on Au- tonomous Agents and Multiagent Systems, AAMAS '24, page 2414-2416, Richland, SC, 2024. International Foun- dation for Autonomous Agents and Multiagent Systems.
- [Qian et al., 2023] Kejiang Qian, Lingjun Mao, Xin Liang, Yimin Ding, Jin Gao, Xinran Wei, Ziyi Guo, and Jiajie Li. Ai agent as urban planner: Steering stakeholder dy- namics in urban planning via consensus-based multi-agent reinforcement learning, 2023.
- [Roijers et al., 2013] Diederik M. Roijers, Peter Vamplew, Richard Dazeley, and Gerhard Weiss. A survey of multi- objective sequential decision-making. In Journal of Artifi- cial Intelligence Research, volume 48, pages 67-113. AI Access Foundation, 2013.
- [Stetter et al., 2024] Christian Stetter, Robert Huber, and Robert Finger. Agricultural land use modeling and climate change adaptation: A reinforcement learning approach. Ap- plied Economic Perspectives and Policy, 46, 05 2024.
- [UK Centre for Ecology & Hydrology, 2023] UK Centre for Ecology & Hydrology. Ukceh land cover map (2015-2021 series). https://www.ceh.ac.uk/services/land-cover-map, 2023. Accessed: 2025-06-10. Link
- [Wiering, 2000] Marco Wiering. Multi-agent reinforcement learning for traffic light control. In Proc. ICML 2000, pages 1151-1158, 2000.
- [Yi et al., 2021] Yuxuan Yi, Ge Li, Yaowei Wang, and Zongqing Lu. Learning to share in multi-agent reinforce- ment learning. arXiv preprint arXiv:2112.08702, page 16, 2021.
- [Zheng et al., 2023] Yu Zheng, Hongyuan Su, Jingtao Ding, Depeng Jin, and Yong Li. Road planning for slums via deep reinforcement learning, 2023.
References were extracted automatically from the PDF and may contain errors.
Full text extracted automatically from the PDF; figures, tables and equations may differ. The PDF is the version of record.
1 Introduction
Urban planning is a critical domain that requires harmonizing "top-down" policy decisions, implemented by governments and institutional bodies, and "bottom-up" preferences, reflecting the needs and desires of individuals and communities. This duality is particularly significant in addressing the "tragedy of the commons", a scenario where individual incentives clash with the sustainable management of shared resources. Achieving this balance is crucial for the future of human populations, especially in the context of effective use of scarce resources.
This study focuses on solving a specific instance of this duality by introducing a novel machine learning (ML) approach that emphasizes both the theoretical and practical significance of this problem. Specifically, we address residential housing allocation and optimization using a dual agent framework inspired by the work of Bone et al. [2011]. This approach leverages a robust experimental setting to demonstrate how intelligent systems can navigate trade-offs between policydriven objectives and individual preferences.
We propose a comprehensive framework that incorporates two distinct types of agents: "top-down" agents, such as policymakers and institutional stakeholders, and "bottom-up" agents, representing individuals or groups with specific housing preferences. By employing this dual agent framework, we aim to design methods tailored to the unique challenges of this class of problems, focusing on preserving ecological balance while optimizing land use. Therefore, we introduce:
- (i) Quantile-Optimized Land Use (QOLU) Algorithm for Top-Down Agents, which employs deep reinforcement learning (RL) to model strategic land use planning. QOLU agents optimize multiple goals, such as minimizing agricultural land conversion, preserving proximity to freshwater sources, and ensuring that new developments increase spatial proximity with existing urban and suburban areas. QOLU agents aim to act as stewards of the environment, safeguarding the continuity of woodlands, agricultural expanses, and other pivotal land use types.
- (ii) Neural Network-based Bottom-Up Investor Agent (BUIA) Algorithm, a decentralized planning model which uses limited observability to prioritize land use changes based on historical data and local preferences. This agent leverages neural networks to identify profitable and sustainable opportunities within a 2 km radius.
Our framework addresses the technical gaps in balancing top-down and bottom-up approaches, while also offering practical innovations by explicitly optimizing multi-objective tradeoffs present in our context. This novel integration allows for a synergistic strategy that adapts to diverse geographical, climatic, and socio-economic conditions.
The remainder of this paper details the problem formulation, methodology, and a comparative analysis against established benchmarks from the literature. We also present experimental results, validating our approach and discussing its broader implications for future urban planning, along with potential extensions to enhance scalability and applicability.
2 RelatedWork
Balancing economic development with environmental stewardship is a key theme in computational urban planning. Early approaches often employed methods such as neural-networkbased cellular automata [Li and Yeh, 2002] or probabilistic graphical models [Bone et al., 2011] to simulate land-use changes under diverse constraints. Multi-agent systems were later introduced to model interactions among heterogeneous stakeholders, as in studies of distributed decision-making for traffic coordination [Wiering, 2000] and sustainable zoning [Zheng et al., 2023]. In parallel, single-agent reinforcement learning (RL) techniques leveraged spatial information to predict urban expansion, but often prioritized a single global objective [Qian et al., 2023].
Recent advances in distributional RL have offered more robust solutions for tasks involving uncertainty and conflicting goals by estimating a return distribution instead of a point estimate [Bellemare et al., 2017]. Methods such as implicit quantile networks [Dabney et al., 2018] allow finer control over multi-objective trade-offs, making them appealing for land management scenarios where ecological interests can clash with development demands. Work in multi-objective RL provides a broader framework for learning policies that balance competing criteria, surveyed extensively in Roijers et al. [2013] and Liu et al. [2015], while specific applications to urban growth reveal the viability of RL-based algorithms for complex spatial environments [Stetter et al., 2024].
Despite these developments, bridging top-down regulations (e.g., environmental protection) with bottom-up stakeholder preferences (e.g., local housing markets) remains challenging, though early attempts at "modeling-in-the-middle" [Bone et al., 2011] underscored the need for linking policy instruments to agent-level decisions. We address this gap by integrating a quantile-based multi-objective RL framework, suitable for safeguarding critical land types, with decentralized agents that capture localized incentives. This hybrid design seeks to produce more context-aware and environmentally aligned outcomes than purely top-down or purely bottom-up models.
3 Methodology
We frame our land management problem as a modified multiagent Partially Observable Stochastic Game (POSG), aiming to combine macro-level policy objectives with micro-level stakeholder preferences. The methodology centers on two distinct agent types: top-down Quantile-Optimized Land Use (QOLU) agents that adopt distributional RL to guard critical land types, and bottom-up Neural Network-based Investor Agents (BUIA) that capture localized incentives based on an attractiveness metric.
3.1 ProblemFormulation
We formulate our problem as a POSG due to its capability to model the uncertainties and agents in our context - mimicking the realistic constraints in urban planning. Our formulation tries not only to capture the inherent complexity of urban environments but also allows for robust policy evaluation against conflicting objectives. Our POSG is given by the tuple:
where Φ = (ϕ1, . . . , ϕn) is the set of agents, partitioned into top-down shareholders (ΦTD) and bottom-up investors (ΦBU). Each state s ∈ S describes a set of 1 km2 parcels with unique attributes (e.g., current land usage, geographic constraints). The action space A = A1 × · · · × An encodes land-conversion decisions, and T is the transition function specifying the probability of moving from one configuration of parcels to another given a joint action. Each agent observes only partial information, defined by an observation function O: S×A×Z→ [0, 1]. The reward function:
integrates heterogeneous agent objectives via the weights wi. Contrary to the usual POSG formulation, although each agent computes its own objective Rϕi , the environment supplies one shared team reward R(s, a), encouraging fully cooperative learning. For a top-down agent, Rϕi may include terms for preserving woodlands and agricultural land and maintaining proximity to freshwater, whereas the societal reward Rsociety(s, a) captures the net public benefit of protecting overall forest and agricultural areas (parameterized by α and β). Bottom-up agents receive rewards linked to attractiveness values of newly developed parcels, reflecting immediate local gains.
3.2 Attractiveness Metric
A key component for bottom-up decisions is the attractiveness metric that assigns to each parcel a score based on proximity to natural features (e.g., forests, fluvial areas) and existing urban centers. Let Battractiveness store the scores Ai for each parcel i, with higher values signifying increased desirability for residential or commercial development. The probability of an investor agent targeting a parcel is proportional to its attractiveness, thereby balancing land conversion pressures against ecological and jurisdictional constraints. Post-conversion, the attractiveness scores update to reflect changes in neighboring parcels, allowing the system to evolve iteratively.
3.3 Quantile-Optimized Land Use (QOLU)
Top-down agents adopt a quantile-based distributional RL approach designed to preserve environmental continuity while accommodating necessary development. Each top-down agent or stakeholder may optimize multiple objectives, from minimizing agricultural land loss to maintaining sufficient distance from fragile ecosystems. The RL algorithm produces a unified quality metric indicating how favorable the conversion of a non-residential parcel is to the agent's weighted goals.
QOLUAlgorithm. We instantiate QOLUwith a deep RL model that applies quantile regression to learn a distribution over returns, rather than a single expected value. This formulation is initialized by parameters ψ0 and updated iteratively:
where η is the learning rate. The loss L(ψt ) is computed over transitions (s, a, r, s′ ) using the quantile regression function
Algorithm 1 Quantile-Optimized Land Use (QOLU) Algo.
- 1: Initial policy parameters θ, empty replay buffer D, exploration schedule Epsilon, number of atoms N, Vmin,Vmax, γ discount factor
- 2: for each actor k running in parallel do
- 3: Initialize the actor's environment state s
- 4: for each step t do
- 5: Select action a by exploiting noisy network parameters θ or exploratory action based on Epsilon
- 6: Execute action a in the environment to get reward r and new state s′
- 7: Store the transition (s, a, r, s′ ) in D
- 8: Update s ← s′
- 9: end for
- 10: end for
- 11: Sample a minibatch of transitions (s, a, r, s′ ) fromD
- 12: for each transition in minibatch do
- 13: Calculate n-step return Rt = ∑n-1 i=0 γ i rt+i + γ n maxa′ Q(st+n, a′ ; θ)
- 14: Update target distribution Z = Rt for the corresponding atom
- 15: end for
- 16: For Double Q-learning, use argmaxa Q(s′ , a; θ) to select an action and θ- to evaluate it, resulting in Z = Rt + γZ(s′ , arg maxa Q(s′ , a; θ); θ-)
- 17: With a dueling architecture, separate the value and advantage streams in the network, then combine them for the final Q values calculated as:
- 18: Perform a gradient descent step on the Kullback-Leibler divergence DKL(Z||Z(s, a; θ)) with respect to the network parameters θ
- 19: Every tn steps reset θ- = θ
with τj ∈ (0, 1) specifying the quantile index and ρτj the quantile loss function. For each sampled transition, we update the distribution of future returns, thereby capturing the range of possible outcomes under uncertain land conversion scenarios. Pseudocode for QOLU closely follows a Distributional DQN with quantile regression, as shown in Algorithm 1.
Once trained, each QOLU agent assigns a quality score to candidate conversions. Summing these scores across all stakeholders provides a consensus-driven measure that balances ecological, economic, and policy-related objectives. Table 1 presents the details about the architecture and hyperparameters used for the QOLU implementation.
Atom support. Following Bellemare et al. [2017], we approximate the return distribution by a categorical ("atombased") distribution supported on a fixed, finite interval.
The interval is divided into N equally-spaced atoms
which play the role of "canonical" returns.
Algorithm 2 Bottom-Up Investor Agent (BUIA) Algo.
- 1: Initialize model parameters θ
- 2: Define feature set X capturing local land-use data
- 3: for each decision point do
- 4: Compute logits Z = NeuralNetwork(X; θ)
- 5: Convert Z to distribution P = softmax(Z)
- 6: Sample an action a fromCategorical(P)
- 7: Execute a (e.g., convert selected parcels)
- 8: Observe reward RNN based on change in attractiveness
- 9: end for
3.4 Neural Network-Based Bottom-Up Investor Agent (BUIA)
While top-down QOLU agents promote global objectives, bottom-up agents capture the micro-level incentives of individuals or groups seeking property development. Each BUIA operates under limited observability, constrained to a small radius of nearby parcels. By exploiting local attractiveness scores and historical land-use changes, BUIA agents can identify economically and ecologically favorable parcels to convert.
BUIAAlgorithm. Each BUIA agent uses a neural network that processes local features, such as surrounding land types and updated attractiveness values. The network outputs a probability distribution over potential development actions, typically selecting parcels that maximize expected profitability while aligning with partial ecological constraints. At each decision step, the agent:
- Gathers local context (e.g., land cover, neighbors' attractiveness updates).
- Feeds these features into a neural model (parameters θ).
- Obtains a categorical action distribution via softmax.
- Samples an action a and executes the corresponding landuse change.
The reward RNN(s, a) = Attract(s′ ) - Attract(s) encourages conversions that increase desirability over time. Algorithm 2 defines BUIA's pseudo code, showing the critical role of the attractiveness metric in guiding bottom-up decisions.
Once a BUIA completes its localized conversion, the corresponding land records update, and newly computed attractiveness scores propagate to both bottom-up and top-down agents. This interplay establishes a feedback loop in which micro-level parcel changes feed into macro-level planning objectives, creating an evolving land-use landscape that balances individual development goals and broader policy constraints. Table 2 presents the details for BUIA's implementation.
| Conv. Block Flatten Layer | 3×3 kernels, 32 → 64 → 128 filters |
| Residual MLP | 2 fully-connected layers (256 units) + skip connection around the pair |
| Quantile Head | 51 atoms with V ∈ [-200, 200] |
| Optimizer | Adam |
| Mini-batch size | 256 |
| Discount factor γ | 0.99 |
| Exploration | ϵ-greedy (schedule not fixed) |
| Conv. block | 1 convolutional layer, kernel and fil- ter counts matching the input |
| MLP | 128 → 128 → 64 |
| Output | Softmax over current candidate parcels |
3.5 Environment Representation and Iteration
The experimentation within the simulated environment adheres to a sequential decision-making process, wherein the actions proposed by various algorithms are collated before any updates to the environmental state are enacted. This section delineates the procedural environment workflow, emphasizing the role of decision-making in optimizing land usage.
Sequential DecisionMaking. In the simulated environment, decision-making is executed in a sequential manner. The iterative process unfolds as follows:
- Each algorithm proposes its actions based on the current state of the environment.
- The proposed changes to the map are applied only after all decisions have been made, ensuring a synchronized update across the entire environment.
This approach ensures that each algorithm operates with the same information, and changes are made based on an aggregation of all decisions at the end of each iteration.
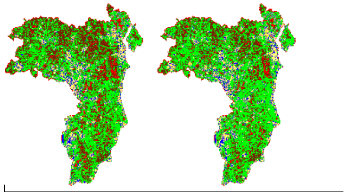
Map Division and QOLUAgent Allocation. The environment is partitioned into blocks of 40 × 40 pixel units, referred to as parcels, as shown in Figure 1. These parcels represent the jurisdiction of individual QOLU agents, who act as stakeholders with vested interests in the land use outcomes. Each parcel is assigned an attractiveness metric, reflecting the desirability of the neighborhood characteristics within that segment.
In Equation 1, B denotes a buffer storing attractiveness scores for every parcel, Ai denotes the attractiveness rating of parcel i, and n is the total number of parcels.
Decision Buffer and Sampling. A decision buffer is constructed to hold the parcels from which they are sampled. The probability of a parcel being sampled is directly proportional to its attractiveness rating:
In Equation 2, the weighted sampling ensures that parcels with higher attractiveness are more likely to undergo decisionmaking processes by the agents, thus ensuring faster convergence from a machine learning perspective, and higher average satisfaction with the change.
Neural Network Agent DecisionMaking. After sampling, the BUIA agent selects positions within the non-urban land that will be converted into urban land types. This agent's decisions are informed by the updated land attractiveness metrics, influencing the development pattern of the urban landscape.
Reward Allocation and Iteration Completion. Once the BUIA agent has made its selections, the new parcel data is fed back to the Stakeholder QOLU agents. Each QOLU agent then allocates rewards based on the degree of compliance with their individual objectives:
where f represents the reward function specific to each QOLU agent i, and their pre-determined objectives for each agent i.
Simulation Iteration and Land Conversion. An iteration of the simulation is deemed complete once the reward allocation is finalized. It is noteworthy that during each iteration, 50 parcels are sampled with replacement, allowing for the potential conversion of up to 11 land types into urban areas.
Iterative Process and Convergence. The simulation proceeds iteratively, with the described sequence of steps repeating. Convergence towards an optimized state is measured by the stabilization of attractiveness metrics and reward distributions across successive iterations.
This experimental framework is designed to provide insights into the effectiveness of the proposed algorithms in managing land development in a way that balances individual objectives with broader societal and environmental considerations.
3.6 Metrics
Land Preference Metric. The land preference metric is defined based on the probability distribution of land types L for a given cell. Let P(L) be the distribution. The land preference metric, denoted as LP, is calculated as:
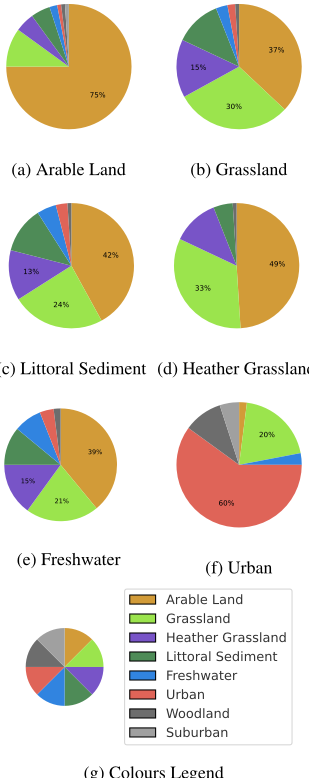
In Equation 3, wi represents the weight for each top-down agent, PϕTDi is the land preference function for the i-th high policy agent, and Psociety is the societal land preference function taken from a dataset and visualized in Figure 2.
(g) Colours Legend
Figure 2: Land preferences represent natural co-occurrence of land types in the real world, guiding future balance preservation.
Well-being Metric. The well-being metric considers the housing capacity and unoccupied houses. Let Htotal be the total housing capacity and Hoccupied be the occupied housing. The well-being metric is calculated as WB = Hoccupied Htotal , assessing how effectively the housing capacity is utilized.
4 Experimental Settings
Overview. The evaluation process involves:
- (i) Initialization: Each agent is initialized with a set of objectives, which can include minimizing the loss of woodland and arable land, maximizing the distance of developed parcels from bog, mountain, and heath areas, and minimizing the distance to urban areas.
- (ii) Simulation: The agents get sampled on a 50 × 50 grid (each cell represents a land parcel). The bottom-up agents propose changes to the land parcels based on their objectives, and top-down agents appraise the solution.
- (iii) Reward Calculation: The agents assign rewards to each change based on how well the change aligns with their objectives. Rewards are calculated using a combination of individual rewards (based on specific objectives) and a global reward (based on the overall impact on the environment and urban planning).
- (iv) Iteration: The process is repeated for 1000 iterations, with each iteration representing a new set of proposed changes and evaluations.
- (v) Aggregation: The results from all iterations are aggregated to provide a comprehensive assessment of the agent's performance. This includes calculating the average rewards and analyzing the distribution of land use changes over the entire grid.
The primary metrics used for evaluation include:
- (i) Proximity to Desired Land Types: Measuring how close the developed parcels are to bog, mountain, and heath areas.
- (ii) Preservation of Land Types: Assessing the extent to which woodland and arable land types are preserved.
- (iii) UrbanConnectivity: Evaluating howwell the developed parcels are connected to existing urban areas.
Stakeholders Preferences and Scenarios. To evaluate the performance of our proposed method, we performed experiments considering three stakeholders' preferences: (i) maximizing the distance of developed parcels to specific land uses (bog, mountain, heath) aggregated into a single land type; (ii) minimizing the loss of woodland and arable land types due to development, and; (iii) minimizing the distance of newly developed parcels to urban or suburban lands.
From these preferences, we created four scenarios, each emphasizing a different preference. The scenarios and their respective weights are outlined in Table 3.
Conversion Metric. A critical metric introduced in this study is the land type distribution alignment Calign:
where N is the number of parcels, si is the set of land types neighboring parcels i before agent actions, and ˆ si is the set after agent actions. The function commonality(s) measures the frequency of the most common neighboring land type to parcel i. This metric assesses the agents' capacity to preserve existing land type distributions that are assumed to reflect historical human land-shaping preferences as shown in Figure 2.
| Land Use | Woodland | Urban | |
|---|---|---|---|
| Scenario 1 | 0.33 | 0.33 | 0.33 |
| Scenario 2 | 0.50 | 0.25 | 0.25 |
| Scenario 3 | 0.25 | 0.50 | 0.25 |
| Scenario 4 | 0.25 | 0.25 | 0.50 |
Baselines. We propose three baselines from the state-of-theart for our experiments:
- the Modelling-in-the-Middle (MitM)'s approach, proposed by Bone et al. [2011].
- the LToS algorithm, proposed by Yi et al. [2021].
- the P-MADDPG, proposed by Pelcner et al. [2024].
5 Results
In the result analysis, we conducted paired t-tests for each scenario and metric to evaluate the confidence in our results. All scores are presented normalized with standard errors.
Scenario 1: UniformWeights. Under the uniformweights scenario (Table 4), our proposed method significantly outperforms the baseline methods in all three metrics (t-test analysis with p < 0.05). This demonstrates the robustness of our approach when all stakeholders are given equal importance.
Scenario 2: High Emphasis on Distance to Land. In Table 5, we can see that our method achieves the highest score (0.85) for this metric, significantly outperforming LToS (0.75) and PMADDPG (0.80). However, for Woodland Loss and Distance to Urban, our method performs similarly to P-MADDPG (0.75 and 0.80, respectively). This suggests that while our approach is highly effective in prioritizing Distance to Land Use, it maintains competitive performance in other metrics.
Scenario 3: High Emphasis on Woodland Loss. Table 6 shows that our method achieves the highest score (0.85) for this metric among baselines. While the performance on Distance to Land Use is slightly lower (0.75), it is still comparable to P-MADDPG (0.75). The t-tests indicate that the improvements in Woodland Loss are statistically significant (p < 0.05), demonstrating our method's capability to effectively reduce the impact on woodland areas.
Scenario 4: High Emphasis on Distance to Urban. Table 7 shows the results for this setting. Our method achieves the highest score (0.85) for this metric. Although the performance on Distance to Land Use and Woodland Loss (0.75) is not significantly better than for P-MADDPG, the overall performance indicates that our method effectively prioritizes urban proximity while maintaining balance across other metrics.
| Method | Land | Woodland | Urban |
|---|---|---|---|
| LToS | 0.70 ± 0.01 | 0.75 ± 0.02 | 0.80 ± 0.03 |
| P-MADDPG | 0.75 ± 0.02 | 0.8 ± 0.03 | 0.85 ± 0.02 |
| MitM | 0.60 ± 0.02 | 0.65 ± 0.02 | 0.70 ± 0.01 |
| US | 0.8 ± 0.03 | 0.85 ± 0.02 | 0.9 ± 0.01 |
| Method | Land Use | Woodland | Urban |
|---|---|---|---|
| LToS | 0.75 ± 0.02 | 0.70 ± 0.02 | 0.75 ± 0.02 |
| P-MADDPG | 0.80 ± 0.01 | 0.75 ± 0.02 | 0.80 ± 0.02 |
| MitM | 0.65 ± 0.02 | 0.61 ± 0.01 | 0.65 ± 0.02 |
| US | 0.85 ± 0.02 | 0.75 ± 0.02 | 0.80 ± 0.01 |
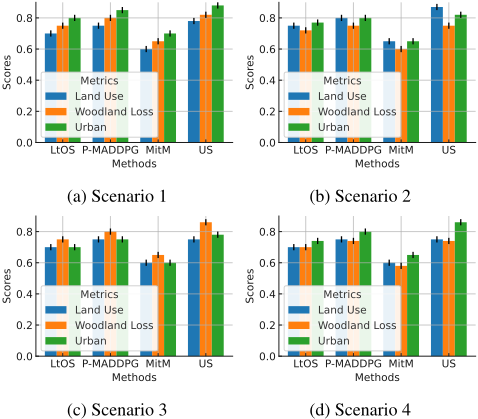
Summary. While our method demonstrates significant improvements across most scenarios, the mixed results in certain cases can be attributed to the inherent trade-offs between the different metrics. For instance, optimizing Distance to Land Use might slightly compromise Woodland Loss and vice-versa. These trade-offs highlight the complexity of urban planning and the need for flexible and adaptive approaches. Our method's ability to perform well across various scenarios, significantly improving key metrics, affirms its robustness and effectiveness in addressing diverse urban planning challenges.
6 UKCEHDataset
In environmental research, the availability of extensive and long-term datasets is crucial for the development and application of advanced algorithms. The UK Centre for Ecology & Hydrology (UKCEH) stands as a key contributor, offering a valuable repository of data that not only informs scientific endeavors but also facilitates practical applications in real-life scenarios. This section highlights this dataset's utility as a crucial piece in developing and applying an RL MAS.
| Method | Land Use | Woodland | Urban |
|---|---|---|---|
| LToS | 0.70 ± 0.01 | 0.75 ± 0.02 | 0.70 ± 0.02 |
| P-MADDPG | 0.75 ± 0.02 | 0.80 ± 0.02 | 0.75 ± 0.02 |
| MitM | 0.60 ± 0.02 | 0.65 ± 0.02 | 0.60 ± 0.01 |
| US | 0.75 ± 0.02 | 0.85 ± 0.02 | 0.75 ± 0.02 |
| Method | Land Use | Woodland | Urban |
|---|---|---|---|
| LToS | 0.70 ± 0.01 | 0.70 ± 0.01 | 0.75 ± 0.02 |
| P-MADDPG | 0.75 ± 0.02 | 0.75 ± 0.02 | 0.80 ± 0.02 |
| MitM | 0.60 ± 0.02 | 0.60 ± 0.01 | 0.65 ± 0.02 |
| US | 0.75 ± 0.02 | 0.75 ± 0.02 | 0.85 ± 0.02 |
As users of the UKCEH data, our primary objective is to leverage the land use dataset to enhance our understanding of the environmental dynamics in the southwest region of the United Kingdom. Spanning the years 2015 to 2021, this dataset serves as a vital component in our larger effort to create and implement a reinforcement learning multi-agent system, designed to navigate the complexities of real-world scenarios.
Our interest lies in the practical application of this dataset as we work towards developing algorithms that can adapt and learn within dynamic environmental contexts. By incorporating the UKCEH's land use data, we aim to enrich our understanding of the region, enabling our reinforcement learning multi-agent system to operate effectively in real-life settings.
7 Discussion &Conclusions
Discussion. The duality problem in urban planning, characterized by the interaction between "top-down" policies and "bottom-up" preferences, poses significant challenges in achieving sustainable resource management. This study addresses these challenges by proposing a dual-agent framework, combining the QOLU for policymakers and BUIA for individual stakeholders. This discussion highlights the implications, limitations, and potential extensions of our approach.
Relevance to the "Tragedy of the Commons". At the core of our research is the concept of the "tragedy of the commons", where unregulated individual actions can deplete shared resources. By explicitly modeling the duality between centralized decision-making and decentralized preferences, our framework systematically addresses resource depletion. The integration of QOLU and BUIA enables a synergistic optimization of societal goals, such as minimizing the loss of ecologically significant land types, while addressing the localized preferences of individuals seeking residential housing.
Strengths and Novel Contributions. Our framework contributes to the field of urban planning by addressing several critical aspects: (i) Multi-Objective Optimization: The QOLU algorithm demonstrates its ability to balance competing objectives, such as preserving agricultural and woodland areas while ensuring urban connectivity. (ii) Adaptability: The BUIA algorithm leverages local data and individual preferences, offering a decentralized approach to land-use planning that complements the global strategies of QOLU agents. (iii) Transferability: While our study focuses on urban residential planning, the proposed framework can be extended to other domains, such as agricultural land management, ecosystem conservation, and flood risk mitigation.
Conclusions. We developed a multi-agent system for landuse optimization, introducing two novel algorithms: QuantileOptimized Land Use (QOLU) and the neural network-based Bottom-Up Investor Agent (BUIA). QOLU agents balance competing land-use policy objectives, while BUIA agents select the most attractive parcels for development. Our approach models uncertainty by capturing full return distributions and balancing ecological, economic, and societal goals within a POSG framework. These objectives are adaptable, allowing incorporation of additional metrics and domain-specific knowledge for broader applicability. We benchmarked our framework against three state-of-the-art baselines across four scenarios reflecting diverse stakeholder preferences. Our method consistently outperformed these baselines, achieving statistically significant improvements in key metrics such as landuse alignment, woodland preservation, and urban proximity. QOLU agents effectively minimized ecologically critical land loss, ensured appropriate land separations, and enhanced urban planning. BUIA agents prioritized high-attractiveness parcels, enabling strategic, desirable development. This work advances sustainable land management by offering a robust framework that combines RL algorithms and neural networkbased decision-making. Future extensions could incorporate additional environmental and socio-economic factors to further improve adaptability and impact.
Limitations and Challenges. Despite its strengths, the proposed framework has several limitations that warrant further exploration: (i) Scalability: While our experiments demonstrate efficacy on a grid of 1 km2 land units, scaling the framework to larger regions with higher agent densities may introduce computational challenges. (ii) Data Dependency: The accuracy of the BUIA agent depends heavily on the availability and quality of local land-use data. In regions with sparse data, the performance of the framework may be affected. (iii) Dynamic Factors: Our current implementation assumes relatively static socio-economic and environmental conditions. Incorporating dynamic factors, such as population growth and climate change, remains an area for future work.
Future Direction. Building on our results and insights, avenues for future research are proposed: (i) Incorporation of Dynamic Models: Introducing dynamic population and environmental models can enhance the realism and applicability of the framework. (ii) Improved Scalability: Leveraging distributed computing and advanced optimization techniques can address scalability challenges in larger geographical settings. (iii) Integration of Additional Metrics: Expanding the framework to include socio-economic factors, such as income distribution and housing affordability, would make the framework more comprehensive. (iv) Real-World Validation: Collaborating with urban planners and policymakers to validate the framework in real scenarios could bridge the gap between theoretical research and practical implementation.
Although our current implementation is tailored to a specific domain (UKCEH dataset) [UK Centre for Ecology & Hydrology, 2023], our framework is naturally extendable. We are exploring transfer learning techniques and parameter tuning to adapt to different geographic regions with varying regulatory and socio-economic conditions. However, the promising results presented here already demonstrate the system's ability to handle complex, real-world dynamics.
Acknowledgments
This paper was partially funded by the New Approaches to Data Science Programme, Data Science of the Natural Environment (grant EP/R01860X/1) and S˜ao Paulo Research Foundation (FAPESP) grant no. 2024/15649-7. We thank Marta Maslankowska for reviewing the early draft of this work.
@inproceedings{ijcai2025p27,
  title     = {Multi Objective Quantile Based Reinforcement Learning for Modern Urban Planning},
  author    = {Pelcner, Lukasz and Marcolino, Leandro Soriano and do Carmo Alves, Matheus Aparecido and Harrison, Paula A. and Atkinson, Peter M.},
  booktitle = {Proceedings of the Thirty-Fourth International Joint Conference on
               Artificial Intelligence, {IJCAI-25}},
  publisher = {International Joint Conferences on Artificial Intelligence Organization},
  editor    = {James Kwok},
  pages     = {232--239},
  year      = {2025},
  month     = {8},
  note      = {Main Track},
  doi       = {10.24963/ijcai.2025/27},
  url       = {https://doi.org/10.24963/ijcai.2025/27},
}
TY - CPAPER TI - Multi Objective Quantile Based Reinforcement Learning for Modern Urban Planning AU - Pelcner, Lukasz AU - Marcolino, Leandro Soriano AU - do Carmo Alves, Matheus Aparecido AU - Harrison, Paula A. AU - Atkinson, Peter M. T2 - Proceedings of the Thirty-Fourth International Joint Conference on Artificial Intelligence, IJCAI-25 PB - International Joint Conferences on Artificial Intelligence Organization PY - 2025 SP - 232 EP - 239 DO - 10.24963/ijcai.2025/27 UR - https://doi.org/10.24963/ijcai.2025/27 ER -Copied
Machine-readable versions of this paper, for tools and AI agents:





