
DGExplainer: Explaining Dynamic Graph Neural Networks via Relevance Back-propagation
Proceedings of the Thirty-Fourth International Joint Conference on Artificial Intelligence. Main Track. Pages 3135-3143.
https://doi.org/10.24963/ijcai.2025/349
Keywords
- AI Ethics, Trust, Fairness: ETF: Trustworthy AI
- Machine Learning: ML: Explainable/Interpretable machine learning
- AI Ethics, Trust, Fairness: ETF: Explainability and interpretability
- Data Mining: DM: Mining graphs
Abstract
Dynamic graph neural networks (dynamic GNNs) have demonstrated remarkable effectiveness in analyzing time-varying graph-structured data. However, their black-box nature often hinders users from understanding their predictions, which can limit their applications. In recent years, there has been a surge in research aimed at explaining GNNs, but most studies have focused on static graphs, leaving the explanation of dynamic GNNs relatively unexplored. Explaining dynamic GNNs presents a unique challenge due to their complex spatial and temporal structures. As a result, existing approaches designed for explaining static graphs are not directly applicable to dynamic graphs because they ignore temporal dependencies among graph snapshots. To address this issue, we propose DGExplainer, which offers a reliable explanation of dynamic GNN predictions. DGExplainer utilizes the relevance back-propagation technique both time-wise and layer-wise. Specifically, it incorporates temporal information by computing the relevance of node representations along the inverse of the time evolution. Additionally, for each time step, it calculates layer-wise relevance from a graph-based module by redistributing the relevance of node representations along the back-propagation path. Quantitative and qualitative experimental results on six real-world datasets demonstrate the effectiveness of DGExplainer in identifying important nodes for link prediction and node regression in dynamic GNNs.
- [Bach et al., 2015] Sebastian Bach, Alexander Binder, Grégoire Montavon, Frederick Klauschen, Klaus-Robert Müller, and Wojciech Samek. On pixel-wise explanations for non-linear classifier decisions by layer-wise relevance propagation. PloS one, 10(7):e0130140, 2015.
- [Baldassarre and Azizpour, 2019] Federico Baldassarre and Hossein Azizpour. Explainability techniques for graph convolutional networks. In ICML Workshops, 2019.
- [Chen and Ying, 2023] Jialin Chen and Rex Ying. Tempme: Towards the explainability of temporal graph neural net- works via motif discovery. NeurIPS, 36:29005-29028, 2023.
- [Chen et al., 2022] Jinyin Chen, Xueke Wang, and Xuan- heng Xu. Gc-lstm: Graph convolution embedded lstm for dynamic network link prediction. Applied Intelligence, pages 1-16, 2022.
- [Chen et al., 2024] Yongqiang Chen, Yatao Bian, Bo Han, and James Cheng. How interpretable are interpretable graph neural networks? arXiv preprint arXiv:2406.07955, 2024.
- [Cho et al., 2014] Kyunghyun Cho, Bart Van Merriënboer, Dzmitry Bahdanau, and Yoshua Bengio. On the proper- ties of neural machine translation: Encoder-decoder ap- proaches. arXiv preprint arXiv:1409.1259, 2014.
- [Duval and Malliaros, 2021] Alexandre Duval and Fragkiskos D Malliaros. Graphsvx: Shapley value explanations for graph neural networks. In ECML PKDD, pages 302-318. Springer, 2021.
- [Fan et al., 2021] Yucai Fan, Yuhang Yao, and Carlee Joe- Wong. Gcn-se: Attention as explainability for node clas- sification in dynamic graphs. In ICDM, pages 1060-1065. IEEE, 2021.
- [Goyal et al., 2018] Palash Goyal, Nitin Kamra, Xinran He, and Yan Liu. Dyngem: Deep embedding method for dy- namic graphs. arXiv:1805.11273, 2018.
- [Goyal et al., 2020] Palash Goyal, Sujit Rokka Chhetri, and Arquimedes Canedo. dyngraph2vec: Capturing network dynamics using dynamic graph representation learning. Knowledge-Based Systems, 187:104816, 2020.
- [Gui et al., 2020] Yihan Gui, Danshi Wang, Luyao Guan, and Min Zhang. Optical network traffic prediction based on graph convolutional neural networks. In OECC, pages 1-3. IEEE, 2020.
- [Guo et al., 2019] Shengnan Guo, Youfang Lin, Ning Feng, Chao Song, and Huaiyu Wan. Attention based spatial- temporal graph convolutional networks for traffic flow forecasting. In AAAI, pages 922-929, 2019.
- [Hajiramezanali et al., 2019] Ehsan Hajiramezanali, Ar- man Hasanzadeh, Krishna Narayanan, Nick Duffield, Mingyuan Zhou, and Xiaoning Qian. Variational graph recurrent neural networks. In NeurIPS, volume 32, 2019.
- [Huang et al., 2022] Qiang Huang, Makoto Yamada, Yuan Tian, Dinesh Singh, and Yi Chang. Graphlime: Local in- terpretable model explanations for graph neural networks. TKDE, 2022.
- [Kapoor et al., 2020] Amol Kapoor, Xue Ben, Luyang Liu, Bryan Perozzi, Matt Barnes, Martin Blais, and Shawn O'Banion. Examining covid-19 forecasting us- ing spatio-temporal graph neural networks. arXiv preprint arXiv:2007.03113, 2020.
- [Kingma and Ba, 2014] Diederik P Kingma and Jimmy Ba. Adam: A method for stochastic optimization. arXiv preprint arXiv:1412.6980, 2014.
- [Kipf and Welling, 2016] Thomas N Kipf and Max Welling. Semi-supervised classification with graph convolutional networks. arXiv preprint arXiv:1609.02907, 2016.
- [Klimt and Yang, 2004] Bryan Klimt and Yiming Yang. The enron corpus: A new dataset for email classification re- search. In ECML PKDD, pages 217-226. Springer, 2004.
- [Kumar et al., 2018] Srijan Kumar, William L Hamilton, Jure Leskovec, and Dan Jurafsky. Community interaction and conflict on the web. In WWW, pages 933-943, 2018.
- [Li et al., 2017] Jundong Li, Harsh Dani, Xia Hu, Jiliang Tang, Yi Chang, and Huan Liu. Attributed network em- bedding for learning in a dynamic environment. In CIKM, pages 387-396, 2017.
- [Luo et al., 2020] Dongsheng Luo, Wei Cheng, Dongkuan Xu, Wenchao Yu, Bo Zong, Haifeng Chen, and Xiang Zhang. Parameterized explainer for graph neural network. NeurIPS, 33:19620-19631, 2020.
- [Ma et al., 2020] Yao Ma, Ziyi Guo, Zhaocun Ren, Jiliang Tang, and Dawei Yin. Streaming graph neural networks. In SIGIR, pages 719-728, 2020.
- [Nguyen et al., 2018] Giang Hoang Nguyen, John Boaz Lee, Ryan A Rossi, Nesreen K Ahmed, Eunyee Koh, and Sungchul Kim. Continuous-time dynamic network em- beddings. In WWW, pages 969-976, 2018.
- [Pareja et al., 2020] Aldo Pareja, Giacomo Domeniconi, Jie Chen, Tengfei Ma, Toyotaro Suzumura, Hiroki Kaneza- shi, Tim Kaler, Tao Schardl, and Charles Leiserson. Evolvegcn: Evolving graph convolutional networks for dynamic graphs. In AAAI, pages 5363-5370, 2020.
- [Pope et al., 2019] Phillip E Pope, Soheil Kolouri, Moham- mad Rostami, Charles E Martin, and Heiko Hoffmann. Ex- plainability methods for graph convolutional neural net- works. In CVPR, pages 10772-10781, 2019.
- [Rahman and Al Hasan, 2016] Mahmudur Rahman and Mo- hammad Al Hasan. Link prediction in dynamic networks using graphlet. In ECML PKDD, pages 394-409. Springer, 2016.
- [Sanchez-Lengeling et al., 2020] Benjamin Sanchez- Lengeling, Jennifer Wei, Brian Lee, Emily Reif, Peter Wang, Wesley Qian, Kevin McCloskey, Lucy Colwell, and Alexander Wiltschko. Evaluating attribution for graph neural networks. NeurIPS, 33:5898-5910, 2020.
- [Sankar et al., 2018] Aravind Sankar, Yanhong Wu, Liang Gou, Wei Zhang, and Hao Yang. Dynamic graph represen- tation learning via self-attention networks. arXiv preprint arXiv:1812.09430, 2018.
- [Schlichtkrull et al., 2020] Michael Sejr Schlichtkrull, Nicola De Cao, and Ivan Titov. Interpreting graph neural networks for nlp with differentiable edge masking. arXiv preprint arXiv:2010.00577, 2020.
- [Schnake et al., 2020] Thomas Schnake, Oliver Eberle, Jonas Lederer, Shinichi Nakajima, Kristof T Schütt, Klaus-Robert Müller, and Grégoire Montavon. Higher- order explanations of graph neural networks via relevant walks. arXiv preprint arXiv:2006.03589, 2020.
- [Schnake et al., 2021] Thomas Schnake, Oliver Eberle, Jonas Lederer, Shinichi Nakajima, Kristof T Schütt, Klaus-Robert Müller, and Grégoire Montavon. Higher- order explanations of graph neural networks via relevant walks. TPAMI, 44(11):7581-7596, 2021.
- [Selvaraju et al., 2017] Ramprasaath R Selvaraju, Michael Cogswell, Abhishek Das, Ramakrishna Vedantam, Devi Parikh, and Dhruv Batra. Grad-cam: Visual explanations from deep networks via gradient-based localization. In ICCV, pages 618-626, 2017.
- [Seo et al., 2018] Youngjoo Seo, Michaël Defferrard, Pierre Vandergheynst, and Xavier Bresson. Structured sequence modeling with graph convolutional recurrent networks. In ICONIP, pages 362-373. Springer, 2018.
- [Shapley, 1953] Lloyd S Shapley. A value for n-person games. Contributions to the Theory of Games, 2(28):307- 317, 1953.
- [Shrikumar et al., 2017] Avanti Shrikumar, Peyton Green- side, and Anshul Kundaje. Learning important features through propagating activation differences. In ICML, pages 3145-3153, 2017.
- [Skarding et al., 2021] Joakim Skarding, Bogdan Gabrys, and Katarzyna Musial. Foundations and modeling of dy- namic networks using dynamic graph neural networks: A survey. IEEE Access, 9:79143-79168, 2021.
- [Trivedi et al., 2019] Rakshit Trivedi, Mehrdad Farajtabar, Prasenjeet Biswal, and Hongyuan Zha. Dyrep: Learning representations over dynamic graphs. In ICLR, 2019.
- [Vu and Thai, 2020] Minh N Vu and My T Thai. PGM- explainer: Probabilistic graphical model explanations for graph neural networks. In NeurIPS, 2020.
- [Wang et al., 2023] Tianchun Wang, Dongsheng Luo, Wei Cheng, Haifeng Chen, and Xiang Zhang. Dyexplainer: Explainable dynamic graph neural networks. arXiv preprint arXiv:2310.16375, 2023.
- [Xia et al., 2022] Wenwen Xia, Mincai Lai, Caihua Shan, Yao Zhang, Xinnan Dai, Xiang Li, and Dongsheng Li. Explaining temporal graph models through an explorer- navigator framework. In ICLR, 2022.
- [Xiong et al., 2023] Ping Xiong, Thomas Schnake, Michael Gastegger, Grégoire Montavon, Klaus Robert Muller, and Shinichi Nakajima. Relevant walk search for explaining graph neural networks. In ICML, pages 38301-38324.
- PMLR, 2023.
- [Yang et al., 2020] Li Yang, Xiangxiang Gu, and Huaifeng Shi. A noval satellite network traffic prediction method based on gcn-gru. In WCSP, pages 718-723. IEEE, 2020.
- [Ying et al., 2019] Rex Ying, Dylan Bourgeois, Jiaxuan You, Marinka Zitnik, and Jure Leskovec. GNNExplainer: Generating explanations for graph neural networks. In NeurIPS, volume 32, page 9240, 2019.
- [You et al., 2022] Jiaxuan You, Tianyu Du, and Jure Leskovec. Roland: graph learning framework for dynamic graphs. In KDD, pages 2358-2366, 2022.
- [Yu et al., 2018a] Bing Yu, Haoteng Yin, and Zhanxing Zhu. Spatio-temporal graph convolutional networks: a deep learning framework for traffic forecasting. In IJCAI, pages 3634-3640, 2018. IJCAI
- [Yu et al., 2018b] Wenchao Yu, Wei Cheng, Charu C Aggar- wal, Kai Zhang, Haifeng Chen, and Wei Wang. Netwalk: A flexible deep embedding approach for anomaly detec- tion in dynamic networks. In KDD, pages 2672-2681, 2018.
- [Yuan et al., 2020] Hao Yuan, Jiliang Tang, Xia Hu, and Shuiwang Ji. Xgnn: Towards model-level explanations of graph neural networks. In KDD, pages 430-438, 2020.
- [Yuan et al., 2021] Hao Yuan, Haiyang Yu, Jie Wang, Kang Li, and Shuiwang Ji. On explainability of graph neural net- works via subgraph explorations. In ICML, pages 12241- 12252. PMLR, 2021.
- [Zhang et al., 2018] Jianming Zhang, Sarah Adel Bargal, Zhe Lin, Jonathan Brandt, Xiaohui Shen, and Stan Sclaroff. Top-down neural attention by excitation back- prop. IJCV, 126(10):1084-1102, 2018.
- [Zhang et al., 2022] Mengqi Zhang, Shu Wu, Xueli Yu, Qiang Liu, and Liang Wang. Dynamic graph neural net- works for sequential recommendation. TKDE, 2022.
- [Zhao et al., 2018] Xujiang Zhao, Feng Chen, and Jin-Hee Cho. Deep learning for predicting dynamic uncertain opin- ions in network data. In 2018 IEEE International Con- ference on Big Data (Big Data), pages 1150-1155. IEEE, 2018.
- [Zhao et al., 2019] Ling Zhao, Yujiao Song, Chao Zhang, Yu Liu, Pu Wang, Tao Lin, Min Deng, and Haifeng Li. T-gcn: A temporal graph convolutional network for traffic prediction. TITS, 21(9):3848-3858, 2019.
- [Zheng et al., 2023] Xu Zheng, Farhad Shirani, Tianchun Wang, Wei Cheng, Zhuomin Chen, Haifeng Chen, Hua Wei, and Dongsheng Luo. Towards robust fidelity for evaluating explainability of graph neural networks. arXiv preprint arXiv:2310.01820, 2023.
- [Zhu et al., 2016] Linhong Zhu, Dong Guo, Junming Yin, Greg Ver Steeg, and Aram Galstyan. Scalable temporal latent space inference for link prediction in dynamic so- cial networks. TKDE, 28(10):2765-2777, 2016.
References were extracted automatically from the PDF and may contain errors.
Full text extracted automatically from the PDF; figures, tables and equations may differ. The PDF is the version of record.
1 Introduction
Dynamic GNNs have achieved significant success in practical applications such as social network analysis [Zhu et al., 2016], transportation forecasting [Gui et al., 2020], and pandemic forecasting [Kapoor et al., 2020]. However, since most of the dynamic GNNs [Ma et al., 2020; Li et al., 2017] are developed without interpretability, they are treated as black-boxes. Without understanding the underlying mechanisms behind their predictions, dynamic GNNs cannot be fully trusted, preventing their use in critical applications. In
→Appendix available at https://github.com/yezil3/DGExplainer IJCAI/blob/main/IJCAI appendix.pdf
Corresponding author.
(a) Traffic flow prediction.
Time
12:00 PM
1
3
15:00 PM
1
3
21:00 PM
1
3
2
2
2
Relevance
|
|
|
1.0
0.0
-1.0
(b) Explaining traffic-flow prediction of dynamic GNNs.
Figure 1: The diagram of the explanation task of dynamic GNNs on traffic flow data.
order to safely and trustworthily employ dynamic GNN models, it is important to provide both accurate predictions and human-understandable explanations.
Recent studies have extensively explored explanation techniques for static GNNs. These techniques include approximation-based methods [Baldassarre and Azizpour, 2019; Pope et al., 2019], which use gradients or surrogate functions to approximate the output of a local model. Perturbation-based approaches [Ying et al., 2019; Luo et al., 2020] explain static GNNs by masking specific features to observe their impact on the model's output. Gradient-based methods [Selvaraju et al., 2017] adopt the additive assumption of feature values or gradients to measure the importance of input features. Further relevant research on explaining static GNNs can be found in Appendix A.13. However, these methods overlook the critical temporal dimension crucial for explaining dynamic GNNs. Applying static-graph explanation frameworks to dynamic graphs yields discrete, snapshotbased explanations that ignore temporal context.
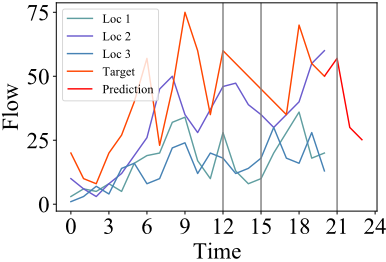
Explaining dynamic GNNs can be challenging. We illustrate this process in Figure 1. The prediction task, shown in Figure 1a, aims to forecast future traffic flows (denoted by dashed lines) at different locations based on historical observations (denoted by solid lines). This spatial-temporal data is modeled as a dynamic graph, represented in Figure 1b, where each graph snapshot records traffic flows at different time steps (e.g., 12:00 PM, 3:00 PM, and 9:00 PM). In each graph snapshot, a dashed line between two nodes indicates a commute between locations, and an arrow represents traffic flows, contributing to the prediction for the target location (denoted by a yellow triangle). The explanation task aims to determine the influence of other locations on the prediction of the target location. The polarity of the influence is denoted by the color of the arrows: blue indicates a positive correlation, while red indicates a negative correlation, with the darkness of the color indicating the strength of the influence. Dynamic graph data involves both temporal and spatial patterns, which dynamic GNNs capture using separate temporal and spatial modules. This makes explanation challenging, as it requires tracing how the input influences the output through these complex components.
To address this challenge, we propose DGExplainer (Dynamic Graph Neural Network Explainer). DGExplainer uses layer-wise relevance propagation (LRP), which was originally introduced for image classifiers [Bach et al., 2015]. LRP can assign relevance scores without the need for a surrogate model or additional optimization. Unlike methods that only consider individual nodes or edges, LRP evaluates sequences of edges or walks, making it especially well-suited for dynamic GNNs. Our framework operates in three main steps. First, DGExplainer decomposes the prediction of a dynamic GNN to determine how time-related modules contribute to that prediction, using relevance back-propagation. Second, it propagates relevance scores through the graph-related modules (e.g., a GCN) layer by layer at each time step to calculate the importance of input features. Finally, DGExplainer aggregates the relevance scores from both steps to produce the final relevance of the node features. The contributions of our work are as follows:
- The proposed method explains the predictions of dynamic graph neural networks, marking one of the pioneering efforts to tackle this challenge.
- This paper is the first to derive LRP for time-varying modules. These hand-derived derivations are essential as they serve as a reference for adjusting or writing code when the provided functions fail, and adaptations are needed.
- Experimental results across six datasets and three quantitative metrics show that DGExplainer provides faithful explanations. Furthermore, qualitative analysis indicates
that DGExplainer outperforms other baseline methods in effectively explaining dynamic GNNs.
2 ProblemDefinition
This paper solves the problem of explaining dynamic GNNs by computing the relevances of input features. The proposed method first redistributes the prediction from the last layer to the relevance of hidden representations. Then, we use LRP to back-propagate the relevances through time-related and graph-related modules, finally reaching the input layer to obtain the relevances of input features of each node.
We study a series of input graphs G = ¶Xt↪ At♦Tt=1 , where T is the length of the sequence. Each graph at time t, Gt = ¶Xt↪At♦, consists of a feature matrix Xt ↑ RN→D and an adjacency matrix At ↑ RN→N . Here, N = ♣Vt♣ denotes the number of nodes, and D is the feature dimension. The feature vector for node i at time t is xit = (X(i↪:) t )↑ ↑ RD , which corresponds to the i-th row of Xt. Without loss of generality, A(i↪j) denotes the entry at the i-th row and j-th column of the adjacency matrix A, and x(i) denotes the i-th entry of the vector x. The relevance of an element k, which can be a node, an edge, a feature, etc., is represented by Rk. Additionally, Rk1↓k2 denotes the relevance of k1 distributed from k2. The problem of explaining dynamic GNNs involves identifying the subgraph within G, which consists of nodes and edges that are most important at a specific time step t, given a dynamic GNN model f(G).
3 Preliminaries
In this section, we present the preliminaries relevant to our proposed method. We begin with an overview of dynamic GNNs in Section 3.1, followed by an introduction to layerwise relevance propagation in Section 3.3.
3.1 Dynamic Graph Neural Networks
Dynamic GNNs [Skarding et al., 2021; Zhang et al., 2022] take a sequence of graphs as input and output representations of topology, nodes, and/or edges. A notable approach involves co-training a GNN with a recurrent neural network (RNN), referred to as a GNN-RNN model. Examples include GCN-GRU [Zhao et al., 2019], ChebNet-LSTM [Seo et al., 2018], and GCN-RNN [Pareja et al., 2020]. Detailed related work about dynamic GNNs can be found in Appendix A.13. Despite the introduction of various methods, recent approaches still do not consistently outperform the GCN-GRU model [Pareja et al., 2020]. Therefore, in this work, we choose to use the GCN-GRU model as the basis for elaborating our method. In addition to explaining the GCN-GRU model, we also apply DGExplainer to other dynamic GNNs that utilize different GNN or RNN architectures. Detailed results of these experiments can be found in Appendix A.7.
3.2 The GCN-GRUModel-Forward Pass
In the GCN-GRU model, the GCN module first encodes input features of the current time step, capturing dependencies between nodes. These encoded features are then passed to the GRU module, which captures temporal dependencies across different time steps. Below, we outline the forward process of the GCN-GRU.
(a) The Graph Convolutional Network (GCN) module: GCNs represent a node using local information from its surrounding neighbors [Kipf and Welling, 2016]. This graph convolution process is formulated as follows:
Here, Vt := ˜D↔ 12 t ˜At ˜D↔ 12 t is the normalized adjacency matrix, where ˜At =At+IN and ˜Dt =Dt+IN. ThematrixDt is the degree matrix, defined as D(i↪i) t = ∑j A(i↪j) t , and IN is an identity matrix of size N. The output at the l-th layer is denoted as F(l) t , with the initial layer output F(0) t = Xt. Assuming the GCN has L layers, the final node representation at time step t, which contains the graph structural information, is denoted as ˆXt = F(L) t . The GCN-encoded features from all time steps ¶ ˆXt♦Tt=1 are then fed into a GRU.
(b) The Gated Recurrent Unit (GRU) module: GRU is a variant of the RNN designed to learn long-term dependencies using two selective gates [Cho et al., 2014]. In the GRU, each cell processes an input ˆxt = ( ˆX(i↪:) t )↑ and a hidden state ht = (H(i↪:) t )↑. The update rule for a GRU cell is as follows:
where Wir, Whr, Whz, Win, Whn, bir, bhr, bhz, bin, and bhn are learnable parameters in GRU, ω(·) is an activation function, and ↓ is an element-wise product operation.
3.3 Layer-wise Relevance Propagation
In this paper, we consider neural networks consisting of layers of neurons. The output xk2 of a neuron k2 is a non-linear activation function g as given by:
Assume that we know the relevance R(l+1) k2 of a neuron k2 at network layer (l + 1) for the classification decision f(x), then we like to decompose this relevance into messages R(l↪l+1) k1↓k2 sent to those neurons k1 at the layer l which provide inputs to neuron k2 such that eq. (4) holds.
We can then define the relevance of a neuron k1 at layer l by summing all messages from neurons at layer (l + 1) as in eq. (5):
The relevance of the output neuron at layer M is R(M) 1 = f(x). The pixel-wise scores are the resulting relevances of the input neurons R(1) d .
4 The Proposed DGExplainer
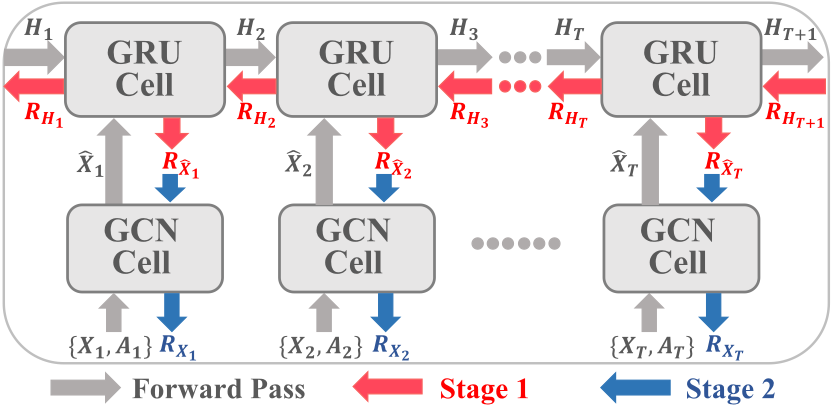
This section introduces the proposed DGExplainer framework (summarized in Figure 2), which explains dynamic GNN predictions by back-propagating relevance through both time-varying and message-passing reverse paths. By accounting for the structural and temporal information in dynamic graphs, DGExplainer computes the relevance of each input feature, offering deeper insights into how the model arrives at its predictions.
DGExplainer operates in two stages: Stage 1: Compute Relevance in the GRU Module. In this stage, relevance scores are back-propagated through the time-related module (GRU) along its reversed time paths. As a result, we obtain the relevance scores for the GCN-encoded features at every time step. Stage 2: Back-Propagate Relevance in the GCN Module. Next, the relevance scores from Stage 1 are taken as input and back-propagated through the graph-related module (e.g., GCN) along the inverse of its message-passing path. This allows us to determine the relevance of the original input features across all time steps, providing an explanation for the dynamic graphs.
4.1 Stage 1: Relevance Back-Propagation in GRU
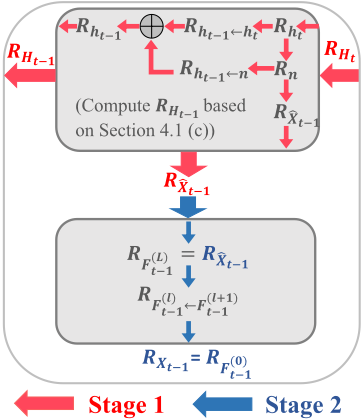
Stage 1 focuses on deriving the relevance of each GRU cell's inputs by propagating the output relevance backward in time. Specifically, DGExplainer first obtains the relevance of the output from the final GRU cell. Then, at each time step t, it uses the current cell's output relevance to compute the relevances of the two inputs: (1) the GCN-encoded feature and (2) the hidden state. The detailed process is illustrated below.
Given the final hidden state for a node, RhT , where hT = (H(i↪:) T )↑, the objective is to compute the relevances of the inputs, Rht→1 and Rˆxt→1 , from the relevance of the output, Rht , for each GRU cell at time t. As described in Section 3.3, relevance back-propagation redistributes the activation of a descendant neuron to its predecessor neurons, with the relevance being proportional to the weighted activation value. Based on the dependencies among different components in the final step of the GRU, as shown in Equation (2d), we derive the relevance back-propagation for this step as follows:
Note that neurons r and z only receive messages from neuron ht↔1, as shown in Equations (2a) and (2b). Consequently, their contribution to ht can be merged into the contribution from ht↔1, and their relevances can be regarded as constants. Notice that ht↔1 is used to compute both n in Equation (2c) and ht in Equation (2d). This reveals that the relevance Rht→1 has two sources: n and ht. Based on the contributions from Rht→1↓n and Rht→1↓ht , we can define Rht as follows:
Given that the relevance of a neuron is proportional to its activation at the same layer, i.e., Rk↓k1 : Rk↓k2 = a(l) k1 : a(l) k2 , we can derive the following based on Equation (2d):
We can conclude that if we derive Rht→1↓ht and Rht→1↓n, we can then obtain Rht . Therefore, we break down this problem into three steps: computing Rht→1↓ht , Rht→1↓n, and Rht→1 , as formulated below: (a) Compute Rht→1↓ht : Solving for Equations (7) and (8) obtains:
where ε > 0 is a constant introduced to keep the denominator non-zero. Notice that the only ancestor neuron of n is ht, so here Rn↓ht is actually Rn, so in the following left of section, we use Rn for simplicity.
(b) Compute Rht→1↓n: From Equation (2c) we obtain:
Then, their relevance satisfies:
Hence, Rn1 and Rn2 can be obtained.
Since ht↔1 influences only n2 among the three components of n, we compute Rht→1↓n using the ε-rule (see appendix A.6 for details) based on Equation (13):
(c) Compute Rht→1 : Rht→1 can be computed by adding Equations (10) and (15) together: Rht→1 = Rht→1↓ht + ∑j R(j) ht→1↓n▷ Notice that Rˆxt is the relevance of a node feature ˆxt, which is a row in ˆXt. By computing the set of relevances ¶Rˆxit ♦Ni=1 for all nodes, we can obtain the overall relevance matrix RˆXt , by concatenating the individual node relevances, i.e., RˆXt = [Rˆx1t ;Rˆx2t ; ▷ ▷ ▷ ;RˆxNt ].
| Dataset | Metric | SA | GNN-GI | GradCAM | GNNE | PGE | SubX | GCN-SE | T-GNNE | DyExplainer | Ours |
|---|---|---|---|---|---|---|---|---|---|---|---|
| Fidelity ↗ Fidelity+ ↗ Sparsity ↗ Stability ↘ | 0.35 0.19 0.79 0.29 | 0.34 0.23 0.86 0.17 | 0.33 0.22 0.53 0.26 | 0.29 0.16 0.67 0.25 | 0.28 0.12 0.75 0.27 | 0.24 0.10 0.34 0.30 | 0.32 0.21 0.71 0.21 | 0.39 0.24 0.86 0.15 | 0.35 0.27 0.84 0.18 | 0.42 0.27 0.87 0.13 | |
| PeMS04 | Fidelity ↗ Fidelity+ ↗ Sparsity ↗ Stability ↘ | 0.30 0.21 0.99 0.18 | 0.29 0.19 0.99 0.22 | 0.26 0.17 0.95 0.25 | 0.24 0.16 0.92 0.22 | 0.19 0.13 0.90 0.23 | 0.18 0.14 0.87 0.27 | 0.33 0.24 0.91 0.23 | 0.44 0.25 0.97 0.17 | 0.37 0.30 0.98 0.19 | 0.39 0.29 0.99 0.15 |
| PeMS08 | Fidelity ↗ Fidelity+ ↗ Sparsity ↗ Stability ↘ | 0.26 0.19 0.94 0.15 | 0.25 0.16 0.94 0.16 | 0.20 0.12 0.95 0.18 | 0.19 0.11 0.91 0.14 | 0.15 0.09 0.92 0.15 | 0.13 0.08 0.90 0.23 | 0.26 0.20 0.92 0.16 | 0.27 0.21 0.94 0.13 | 0.28 0.26 0.94 0.16 | 0.30 0.25 0.95 0.12 |
| Enron | Fidelity ↗ Fidelity+ ↗ Sparsity ↗ Stability ↘ | 0.20 0.14 0.84 0.13 | 0.19 0.15 0.83 0.15 | 0.16 0.11 0.79 0.17 | 0.09 0.06 0.75 0.15 | 0.09 0.07 0.74 0.16 | 0.08 0.05 0.70 0.19 | 0.19 0.13 0.83 0.11 | 0.21 0.15 0.81 0.19 | 0.19 0.17 0.82 0.17 | 0.23 0.18 0.85 0.15 |
| FB | Fidelity ↗ Fidelity+ ↗ Sparsity ↗ Stability ↘ | 0.29 0.18 0.94 0.13 | 0.22 0.14 0.93 0.15 | 0.19 0.13 0.91 0.17 | 0.16 0.11 0.90 0.16 | 0.15 0.09 0.86 0.14 | 0.10 0.07 0.80 0.18 | 0.33 0.17 0.92 0.22 | 0.31 0.20 0.98 0.16 | 0.33 0.22 0.95 0.18 | 0.36 0.23 0.96 0.12 |
| COLAB | Fidelity ↗ Fidelity+ ↗ Sparsity ↗ Stability ↘ | 0.50 0.32 0.96 0.18 | 0.45 0.30 0.95 0.25 | 0.39 0.25 0.94 0.27 | 0.27 0.19 0.93 0.16 | 0.26 0.18 0.93 0.19 | 0.25 0.20 0.90 0.25 | 0.43 0.28 0.94 0.24 | 0.55 0.33 0.99 0.21 | 0.51 0.29 0.96 0.24 | 0.53 0.35 0.96 0.18 |
4.2 Stage 2: Relevance Back-Propagation in GCN
To find the relevance of the input data in a GCN, we start with the relevance of the output and backtrack through the network layers. We calculate the relevance of each layer's nodes using specific equations that distribute relevance from one layer to the previous. By repeating this process, we determine the relevance of the original input features. Finally, we average the absolute values of these relevances across all features to identify the importance of each node at a specific time. In the following, we show the concrete process in algorithm 1.
Then we backtrack in the GCN to get RXt from RˆXt . Note that the RˆXt is the relevance of the output ˆX of the GCN at t and RF(L) t = RˆXt . We rewrite Equation (1) as:
Let (F(l+1) t )(k↪:) , (P(l) t )(k↪:) , (P(l) t )(:↪k) , (F(l) t )(:↪k) denote the k-th row of F(l+1) t , the k-th row of P(l) t , the k-th column of P(l) t , the k-th column of F(l) t , respectively. We have
Leveraging the ε rule, we assign the relevance by:
where (W(l) t )(j↪k) represents the entry at the j-th row and kth column of W(l) t , and V(b↪j) t denotes the entry at the b-th row and j-th column of V(k↪j) t . And the R(P(l) t )(k↪j) can be obtained similarly as R(F(l) t )(j↪k) . The relevance RF(l) t can be obtained from RF(l+1) t using equation Equation (19), and R(P(l) t )(k↪j) . Finally, the relevance RF(0) t can be determined. Notice that RF(0) t = RXt , so we have RF(0) t = RXt , thus completing the backward process for obtaining relevance in the GCN. To further identify important nodes at a specific time step, we take the absolute values of the relevances and average them along the feature dimension to get the relevance of a node at time t: Rxit = ∑Dj=1 ♣(Rxit )(j) ♣◁D.
Figure 3 illustrates the LRP process for a time step of these two states. Specifically, DGExplainer redistributes the relevance of the output hidden state, RHt , to 1) the relevance of the input hidden state, RHt→1 , and 2) the relevance of the GCN-encoded feature, RˆXt . It then back-propagates the latter through the GCN and finally obtains the relevance of the input feature at this time step, RXit→1 . The entire algorithm is summarized in Appendix A.1.
5 Experiments
We conduct quantitative and qualitative experiments on six real-world graphs to answer the following research questions: RQ1: Can the proposed DGExplainer learn high-quality explanations for the GCN-GRU model?
RQ2: What are the benefits of DGExplainer in explaining dynamic GNNs compared to static methods?
RQ3: How do the hyperparameters affect DGExplainer?
Implementation details are provided in Appendix A.4. Unless otherwise specified, we present the performance of DGExplainer on the GCN-GRU model in our experiments. Additionally, in Appendix A.7, we demonstrate the performance of DGExplainer across various other dynamic GNN models.
5.1 Experiment Settings
Datasets. We evaluate the proposed framework on six realworld datasets. For the link prediction tasks, we use four datasets: Reddit Hyperlink (Reddit) [Kumar et al., 2018], Enron [Klimt and Yang, 2004], Facebook (FB) [Trivedi et al., 2019], and COLAB [Rahman and Al Hasan, 2016]. For the node regression tasks, we use two datasets: PeMS04 and PeMS08 [Guo et al., 2019] 1 . The statistics of these datasets and the initial performance of GCN-GRU on them are presented in Appendix A.2.
Baselines. We assess our proposed method against eight baseline explanation methods. These include two general explanation methods: Sensitivity Analysis (SA) [Baldassarre and Azizpour, 2019] and GradCAM [Pope et al., 2019]. Additionally, we compare our method with six GNN explanation methods: GNN-GI [Schnake et al., 2020], GNNExplainer, PGExplainer, SubgraphX, GCN-SE, T-GNNExplainer, and DyExplainer. Detailed descriptions of these baseline methods are provided in Appendix A.3.
Evaluation. We compare the quality of each explanation baseline and our method using four quantitative metrics: confidence, sparsity, stability, and fidelity. Following the experimental setup of a previous work [Pareja et al., 2020], we conduct experiments on link prediction and node classification. Detailed introduction of evaluation is in Appendix A.5.
5.2 Prediction and Explanation Performance
To address RQ1, we conducted a comprehensive comparison of our proposed method, DGExplainer, against several baseline methods. Our evaluation focused on two key aspects: prediction accuracy and the quality of explanations in identifying important nodes. The results demonstrate that DGExplainer outperforms the baselines in terms of fidelity and sparsity, providing more accurate and concise explanations. Additionally, our method exhibits good stability, ensuring consistent explanations even in the presence of minor perturbations, although on some datasets, it slightly underperforms SA and GradCAM. These results establish the effectiveness and reliability of our proposed method in capturing important nodes and providing reliable explanations in the context of link prediction and node regression tasks. Traditional explanation baselines also demonstrate competitive performance. For example, SA and GradCAM achieve strong sparsity, even surpassing some graph-specific explanation methods.
1 pems.dot.ca.gov
Results on Fidelity, Fidelity+ and Sparsity. Fidelity measures a method's ability to accurately capture important nodes. A high-fidelity explanation method is desirable. Fidelity+ is a surrogate version of fidelity, where a graph is sampled from the explanation subgraph by retaining each edge with probability ϑ and erasing it with probability 1 ↔ ϑ. To assess fidelity, we ranked the nodes based on their importance and conducted occlusion experiments by selectively occluding a fraction of the top nodes while keeping 80% of the nodes unchanged (ϖ1 = 0▷8). For fidelity+, we define the explanation subgraph as the subgraph consisting of nodes with relevance greater than ϖ1. The proposed method consistently outperformed the baselines in terms of both fidelity and fidelity+, and sparsity across most datasets, as shown in Table 1. In the remaining datasets, our method achieved comparable results. The Fidelity+ gap between the proposed method and the baselines is larger than the Fidelity gap, further demonstrating DGExplainer's effectiveness in assigning higher relevance to important nodes.
Results on Stability. A stability evaluation was conducted to assess how well the explanation method handles perturbations in the input graph. We introduced random perturbations by adding additional edges to the original graph at a ratio of r = 20% and evaluated the resulting changes in the relevances generated by the model. A stable explanation method should provide consistent explanations when the input undergoes minor perturbations, resulting in lower stability scores. As presented in Table 1, our proposed method generally exhibited good stability, although it did not outperform SA and GNNExplainer. These findings indicate that our method demonstrates relative robustness to small perturbations in the input graph.
5.3 Qualitative Analysis
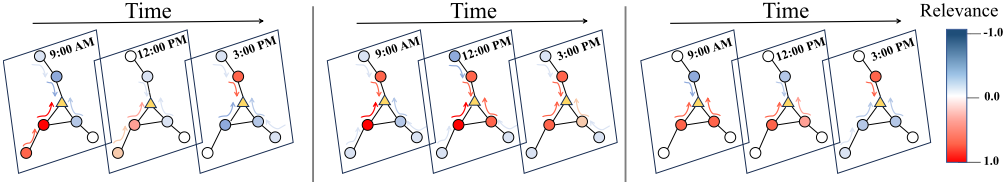
To address RQ2, we conducted quantitative experiments and visualizations of the generated explanations using DGExplainer and baseline methods on the PeMS04 dataset, which represents traffic flow on a highway network. The results, presented in Figure 4, indicate that DGExplainer generates the most reasonable and detailed explanations compared to the GNN-GI and GNNExplainer approaches. Our analysis revealed several key findings: (a) GNN-GI tends to assign equally extreme relevances to every individual node, suggesting that each node has a strong correlation with the prediction. In contrast, GNNExplainer generates average scores for all the identified nodes. (b) GNN-GI identifies nearly all nodes as important, while GNNExplainer only identifies a few nodes as significant, disregarding the correlations of other nodes with the target variable.
These disparities in the visualization results are due to the fact that the comparison methods fail to capture the temporal patterns of dynamic graphs, treating each time step independently and considering only spatial information. In contrast, DGExplainer excels in generating comprehensive and context-aware explanations by effectively incorporating temporal dynamics into the analysis. By considering both spatial and temporal information, DGExplainer provides a more accurate understanding of the underlying relationships within the dynamic GNNs.
5.4 Parameter Sensitivity Analysis
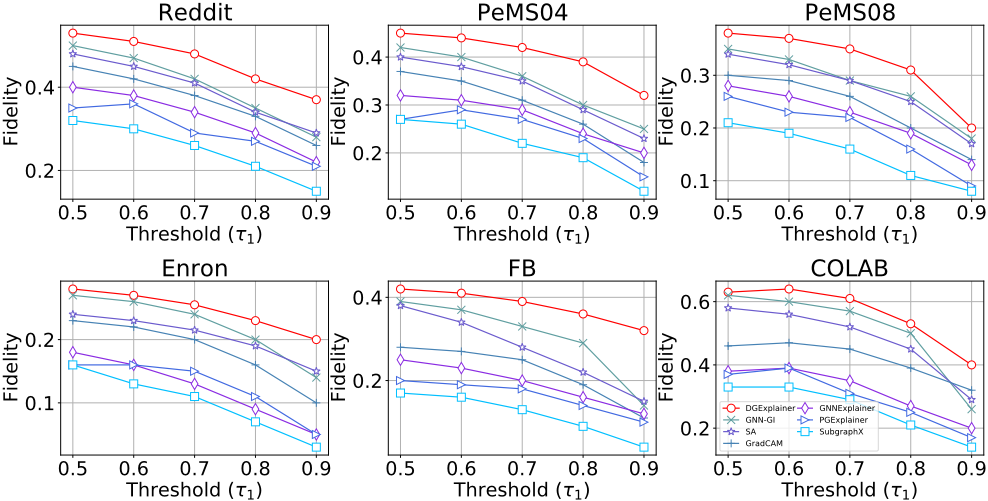
To address (RQ3), we investigate fidelity across various threshold values, denoted as ϖ1 = ¶0▷5↪ 0▷6↪ 0▷7↪ 0▷8↪ 0▷9♦. The fidelity analysis is presented in Figure 5. Our observations are as follows: (a) With smaller ϖ1 values, the fidelity is high. This is because a larger number of nodes are occluded when their relevance surpasses the threshold, resulting in a substantial change in accuracy. (b) As ϖ1 increases, the fidelity gradually decreases, with a steeper decline observed in the range of [0▷8↪ 0▷9]. Overall, our proposed method consistently achieves the highest fidelity across all thresholds and datasets, affirming the robustness of our framework. These findings provide substantial insights into the relationship between fidelity and the chosen threshold values, reinforcing the efficacy of our approach.
6 Conclusion
In this paper, we present DGExplainer, a novel and efficient framework that utilizes both layer-wise and timewise relevance back-propagation to explain the predictions of dynamic Graph Neural Networks (GNNs). To evaluate DGExplainer's performance, we conduct both quantitative and qualitative experiments. The results demonstrate the framework's effectiveness in identifying crucial nodes for link prediction and node regression tasks, outperforming existing explanation methods. This research pioneers the exploration of dynamic GNNs, offering insights into their intricate structures, which is a significant challenge due to the complexity of inference in time-varying modules. Unlike existing static GNN explainers, DGExplainer does not require learning a surrogate function or executing any optimization procedures. Additionally, it can be extended to other advanced dynamic GNNs.
Acknowledgements
Work in the paper is supported by NSF ECCS 2412484 and NSF RISE 2425748.
@inproceedings{ijcai2025p349,
  title     = {DGExplainer: Explaining Dynamic Graph Neural Networks via Relevance Back-propagation},
  author    = {Liu, Yezi and Xie, Jiaxuan and Shen, Yanning},
  booktitle = {Proceedings of the Thirty-Fourth International Joint Conference on
               Artificial Intelligence, {IJCAI-25}},
  publisher = {International Joint Conferences on Artificial Intelligence Organization},
  editor    = {James Kwok},
  pages     = {3135--3143},
  year      = {2025},
  month     = {8},
  note      = {Main Track},
  doi       = {10.24963/ijcai.2025/349},
  url       = {https://doi.org/10.24963/ijcai.2025/349},
}
TY - CPAPER TI - DGExplainer: Explaining Dynamic Graph Neural Networks via Relevance Back-propagation AU - Liu, Yezi AU - Xie, Jiaxuan AU - Shen, Yanning T2 - Proceedings of the Thirty-Fourth International Joint Conference on Artificial Intelligence, IJCAI-25 PB - International Joint Conferences on Artificial Intelligence Organization PY - 2025 SP - 3135 EP - 3143 DO - 10.24963/ijcai.2025/349 UR - https://doi.org/10.24963/ijcai.2025/349 ER -Copied
Machine-readable versions of this paper, for tools and AI agents:





