
Inverse Game Theory: An Incenter-Based Approach
Proceedings of the Thirty-Fourth International Joint Conference on Artificial Intelligence. Main Track. Pages 3805-3813.
https://doi.org/10.24963/ijcai.2025/423
Keywords
- Game Theory and Economic Paradigms: GTEP: Noncooperative games
Abstract
Estimating player utilities from observed equilibria is crucial for many applications. Existing approaches to tackle this problem are either limited to specific games or do not scale well with the number of players. Our work addresses these issues by proposing a novel utility estimation method for general multi-player non-cooperative games. Our main idea consists in reformulating the inverse game problem as an inverse variational inequality problem and in selecting among all utility parameters consistent with the data, the so-called incenter. We show that the choice of the incenter can produce parameters that are most robust to the observed equilibrium behaviors. However, its computation is challenging, as the number of constraints in the corresponding optimization problem increases with the number of players and the behavior space size. To tackle this challenge, we propose a loss function-based algorithm, making our method scalable to games with many players or a continuous action space. Furthermore, we show that our method can be extended to incorporate prior knowledge of player utilities, and that it can handle inconsistent data, i.e., data where players do not play exact equilibria. Numerical experiments on three game applications demonstrate that our methods outperform the state of the art. The code, datasets, and supplementary material are available at https://github.com/cuilvye/Incenter-Project.
- [Alizadeh et al., 1998] Farid Alizadeh, Jean-Pierre A Hae- berly, and Michael L Overton. Primal-dual interior- point methods for semidefinite programming: Conver- gence rates, stability and numerical results. SIAM Journal on Optimization, 8(3):746-768, 1998.
- [Aswani et al., 2018] Anil Aswani, Zuo-Jun Shen, and Auyon Siddiq. Inverse optimization with noisy data. Op- erations Research, 66(3):870-892, 2018.
- [Beck and Teboulle, 2003] Amir Beck and Marc Teboulle. Mirror descent and nonlinear projected subgradient meth- ods for convex optimization. Operations Research Letters, 31(3):167-175, 2003.
- [Berry et al., 1995] Steven Berry, James Levinsohn, and Ariel Pakes. Automobile prices in market equilibrium. Econometrica: Journal of the Econometric Society, pages 841-890, 1995.
- [Berry, 1994] Steven T Berry. Estimating discrete-choice models of product differentiation. The RAND Journal of Economics, pages 242-262, 1994.
- [Bertsekas, 2016] Dimitri Bertsekas. Nonlinear program- ming, volume 4. Athena Scientific, 2016.
- [Bertsimas et al., 2015] Dimitris Bertsimas, Vishal Gupta, and Ioannis Ch Paschalidis. Data-driven estimation in equilibrium using inverse optimization. Mathematical Programming, 153:595-633, 2015.
- [Besbes et al., 2023] Omar Besbes, Yuri Fonseca, and Ilan Lobel. Contextual inverse optimization: Offline and online learning. Operations Research, 2023.
- [Blum et al., 2014] Avrim Blum, Nika Haghtalab, and Ariel D Procaccia. Learning optimal commitment to over- come insecurity. Advances in Neural Information Process- ing Systems, 27, 2014.
- [Bnouhachem et al., 2015] Abdellah Bnouhachem, Qam- rul Hasan Ansari, and Ching-Feng Wen. A projection de- scent method for solving variational inequalities. Journal of Inequalities and Applications, 2015:1-14, 2015.
- [Boyd and Vandenberghe, 2004] Stephen Boyd and Lieven Vandenberghe. Convex optimization. Cambridge Univer- sity Press, 2004.
- [Bubeck and others, 2015] Sébastien Bubeck et al. Con- vex optimization: Algorithms and complexity. Founda- tions and Trends R in Machine Learning, 8(3-4):231-357, 2015.
- [Chan et al., 2023] Timothy CY Chan, Rafid Mahmood, and Ian Yihang Zhu. Inverse optimization: Theory and appli- cations. Operations Research, 2023.
- [Facchinei and Pang, 2003] Francisco Facchinei and Jong- Shi Pang. Finite-dimensional variational inequalities and complementarity problems. Springer, 2003.
- [Fukushima, 1992] Masao Fukushima. Equivalent differ- entiable optimization problems and descent methods for asymmetric variational inequality problems. Mathemati- cal programming, 53:99-110, 1992.
- [Haghtalab et al., 2016] Nika Haghtalab, Fei Fang, Thanh Hong Nguyen, Arunesh Sinha, Ariel D Pro- caccia, and Milind Tambe. Three strategies to success: Learning adversary models in security games. 2016. IJCAI
- [Harker and Pang, 1990] Patrick T Harker and Jong-Shi Pang. Finite-dimensional variational inequality and non- linear complementarity problems: A survey of theory, al- gorithms and applications. Mathematical programming, 48(1):161-220, 1990.
- [Heuberger, 2004] Clemens Heuberger. Inverse combinato- rial optimization: A survey on problems, methods, and re- sults. Journal of combinatorial optimization, 8:329-361, 2004.
- [Jensen, 2018] Martin Kaae Jensen. Aggregative games. In Handbook of Game Theory and Industrial Organization, Volume I, pages 66-92.
- [Korpelevich, 1976] Galina M Korpelevich. The extragradi- ent method for finding saddle points and other problems. Matecon, 12:747-756, 1976.
- [Kuleshov and Schrijvers, 2015] Volodymyr Kuleshov and Okke Schrijvers. Inverse game theory: Learning utili- ties in succinct games. In Web and Internet Economics: 11th International Conference, WINE 2015, Amsterdam, The Netherlands, December 9-12, 2015, Proceedings 11, pages 413-427. Springer, 2015.
- [LeBlanc et al., 1975] Larry J LeBlanc, Edward K Morlok, and William P Pierskalla. An efficient approach to solving the road network equilibrium traffic assignment problem. Transportation research, 9(5):309-318, 1975.
- [Ling et al., 2018] Chun Kai Ling, Fei Fang, and J Zico Kolter. What game are we playing? end-to-end learning in normal and extensive form games. In Proceedings of the 27th International Joint Conference on Artificial Intel- ligence, pages 396-402, 2018. IJCAI
- [Ling et al., 2019] Chun Kai Ling, Fei Fang, and J Zico Kolter. Large scale learning of agent rationality in two- player zero-sum games. In Proceedings of the AAAI Con- ference on Artificial Intelligence, volume 33, pages 6104- 6111, 2019.
- [Maddux et al., 2023] Anna M Maddux, Nicolò Pagan, Giuseppe Belgioioso, and Florian Dörfler. Data-driven behaviour estimation in parametric games. IFAC- PapersOnLine, 56(2):9330-9335, 2023.
- [Mohajerin Esfahani et al., 2018] Peyman Mohajerin Esfa- hani, Soroosh Shafieezadeh-Abadeh, Grani A Hanasu- santo, and Daniel Kuhn. Data-driven inverse optimization with imperfect information. Mathematical Programming, 167:191-234, 2018.
- [Narahari et al., 2009] Yadati Narahari, Dinesh Garg, Rama- suri Narayanam, and Hastagiri Prakash. Game theoretic problems in network economics and mechanism design so- lutions. Springer Science & Business Media, 2009.
- [Nash, 1950] John F Nash. Equilibrium points in n-person games. Proceedings of the National Academy of Sciences of the United States of America, 36(1):48-49, 1950.
- [Nesterov and Nemirovskii, 1994] Yurii Nesterov and Arkadii Nemirovskii. Interior-point polynomial algo- rithms in convex programming. SIAM, 1994.
- [Noti, 2021] Gali Noti. From behavioral theories to econo- metrics: Inferring preferences of human agents from data on repeated interactions. In Proceedings of the AAAI Con- ference on Artificial Intelligence, volume 35, pages 5637- 5646, 2021.
- [Patriksson, 2015] Michael Patriksson. The traffic assign- ment problem: models and methods. Courier Dover Pub- lications, 2015.
- [Peters et al., 2023] Lasse Peters, Vicenc ¸Rubies-Royo, Claire J Tomlin, Laura Ferranti, Javier Alonso-Mora, Cyrill Stachniss, and David Fridovich-Keil. Online and offline learning of player objectives from partial obser- vations in dynamic games. The International Journal of Robotics Research, 42(10):917-937, 2023.
- [Risanger et al., 2020] Simon Risanger, Stein-Erik Fleten, and Steven A Gabriel. Inverse equilibrium analysis of oligopolistic electricity markets. IEEE Transactions on Power Systems, 35(6):4159-4166, 2020.
- [Sheffi, 1985] Yosef Sheffi. Urban transportation networks, volume 6. Prentice-Hall, Englewood Cliffs, NJ, 1985.
- [Tsai et al., 2016] Dorian Tsai, Timothy L Molloy, and Tris- tan Perez. Inverse two-player zero-sum dynamic games. In 2016 Australian Control Conference (AuCC), pages 192- 196. IEEE, 2016.
- [Vandenberghe and Boyd, 1996] Lieven Vandenberghe and Stephen Boyd. Semidefinite programming. SIAM review, 38(1):49-95, 1996.
- [Waugh et al., 2011] Kevin Waugh, Brian D Ziebart, and J Andrew Bagnell. Computational rationalization: the in- verse equilibrium problem. In Proceedings of the 28th International Conference on International Conference on Machine Learning, pages 1169-1176, 2011.
- [Wu et al., 2022] Jibang Wu, Weiran Shen, Fei Fang, and Haifeng Xu. Inverse game theory for stackelberg games: the blessing of bounded rationality. Advances in Neural Information Processing Systems, 35:32186-32198, 2022.
- [Xiu and Zhang, 2003] Naihua Xiu and Jianzhong Zhang. Some recent advances in projection-type methods for vari- ational inequalities. Journal of Computational and Ap- plied Mathematics, 152(1-2):559-585, 2003.
- [Yu et al., 2022] Yue Yu, Jonathan Salfity, David Fridovich- Keil, and Ufuk Topcu. Inverse matrix games with unique quantal response equilibrium. IEEE Control Systems Let- ters, 7:643-648, 2022.
- [Zattoni Scroccaro et al., 2024] Pedro Zattoni Scroccaro, Bilge Atasoy, and Peyman Mohajerin Esfahani. Learning in inverse optimization: Incenter cost, augmented sub- optimality loss, and algorithms. Operations Research, 2024.
References were extracted automatically from the PDF and may contain errors.
Full text extracted automatically from the PDF; figures, tables and equations may differ. The PDF is the version of record.
1 Introduction
Game theory analyzes the strategic behaviors of players using equilibrium concepts, while inverse game theory focuses on the inverse problem: given the observed equilibrium behaviors of players, what are the possible player utilities leading to these behaviors? Inverse game theory has garnered increasing attention [Waugh et al., 2011; Kuleshov and Schrijvers, 2015; Ling et al., 2019; Noti, 2021; Wu et al., 2022], because understanding player utilities can lead to better-designed mechanisms and economic policies.
�Corresponding author.
When estimating player utilities, the existing approaches have two main limitations: (i) most methods are tailored to specific games, such as matrix games [Noti, 2021; Yu et al., 2022] and attacker-defender security games [Blum et al., 2014]; (ii) many existing methods do not scale well with the number of players, often focusing on two-player games [Bertsimas et al., 2015; Tsai et al., 2016; Ling et al., 2018; Ling et al., 2019; Wu et al., 2022].
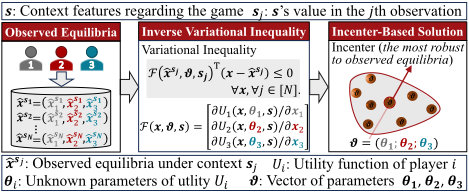
In this work, we study general multi-player noncooperative games, and propose utility estimation methods applicable to a broad range of games and practical applications. Figure 1 illustrates our main ideas. The player utility functions are parameterized, and we aim to estimate the vector ϑ of these utility parameters under which the observed player behaviors constitute a Nash equilibrium. Our idea is to reformulate this as an inverse variational inequality problem: given the observed player behaviors, what vector ϑ ensures that these behaviors satisfy the variational inequalities?
The crucial challenge is that even with many observations of player behaviors, there may be multiple parameter vectors ϑ solving the inverse variational inequality problem. This raises a fundamental question: how should we select a single ϑ from the set of ϑ consistent with the observed equilibria? Existing approaches, such as [Bertsimas et al., 2015], do not address this question but simply single out a ϑ without following a guiding principle. To the contrary, we attempt to solve this problem using a more principled approach.
Our key idea is to select the incenter among all consistent ϑ. This concept introduced in inverse optimization [Besbes et al., 2023; Zattoni Scroccaro et al., 2024] describes a point that lies within a given set and is located furthest away from its boundary. Due to its geometric properties, selecting the incenter as the estimated ϑ reduces the error in estimating the true parameter vector ϑtrue.
We can efficiently compute the incenter of the set of all consistent ϑ using convex optimization. When the action space is continuous, the optimization problem of finding the exact incenter is challenging to solve, since it may involve infinitely many constraints. We convert it to an unconstrained loss minimization problem by defining a novel loss function. Then, we propose a first-order algorithm to minimize the loss, and thus estimate the parameter vector ϑ.
Our loss function-based approach of approximating the incenter has the advantage of handling settings where players do not play exact equilibria. When players are boundedrational, it is possible that no ϑ satisfies all variational inequalities. In this case, our loss function still guides the search for ϑ toward minimizing the degree of violating the constraints defined based on variational inequalities.
We further explore a class of games where the player utility functions exhibit a specific structural property (e.g., monotonicity of gradients). We extend our parameter estimation method to incorporate this property by leveraging techniques from semidefinite programming.
We summarize our contributions as follows.
- We propose a novel framework for solving inverse equilibrium problems, through integrating techniques from variational inequalities and inverse optimization. We further extend our framework to account for specific structural property of player utility functions.
- Our framework can be broadly applied to many multiplayer non-cooperative games and traffic routing games in the transportation field. It imposes no restrictions on the number of players in these game scenarios.
- We conduct extensive numerical experiments on three game applications: Bertrand-Nash price competition [Narahari et al., 2009], aggregative games [Jensen, 2018], and network traffic games [Patriksson, 2015]. Evaluation using different metrics demonstrates that our methods outperform the state of the art.
2 RelatedWork
Inverse Game Theory [Kuleshov and Schrijvers, 2015] is one of the pioneering studies in this field, and investigated the tractability of estimating player utilities in succinct games. Most subsequent studies addressed the inverse game problem within specific games, such as normal-form games [Ling et al., 2018; Noti, 2021; Yu et al., 2022], two-player zero-sum games [Ling et al., 2019], and attacker-defender security games [Blum et al., 2014; Haghtalab et al., 2016; Wu et al., 2022]. [Ling et al., 2018] proposed an end-to-end parameter estimation framework that applies to two-player normal and extensive form games. Different from these studies, our methods are applicable to a broad range of noncooperative games and applications, and do not impose restrictions on the number of players.
Our work is related to [Bertsimas et al., 2015], which utilized inverse optimization to estimate utility parameters in Bertrand competition. That approach can handle only a small number of players and behavior observations (e.g., it requires dealing with over 120, 000 constraints when there are 4 players and 500 observations). As will be shown in experiments, our incenter-based method is more accurate and scalable.
Inverse Optimization The goal of inverse optimization [Heuberger, 2004; Chan et al., 2023] is to identify the parameters of an optimization model that render observed decisions approximately or exactly optimal. To estimate the parameters, the literature in this field has proposed various loss functions, such as Predictability Loss [Aswani et al., 2018], Suboptimality Loss [Mohajerin Esfahani et al., 2018; Besbes et al., 2023], Augmented Suboptimality Loss [Zattoni Scroccaro et al., 2024], and Variational Inequality Loss [Bertsimas et al., 2015]. Our work is inspired by [Zattoni Scroccaro et al., 2024]. The main difference is that we focus on game scenarios with multiple decision makers, rather than optimization problems involving a single decision maker. We seek parameters that make the observed data equilibria, rather than the optimal solutions to an optimization problem.
3 ProblemFormulation
We represent a multi-player non-cooperative game using a tuple G :� tI, tXiuiPI , tUiuiPI u. Here, I :� t1, . . . , pu denotes the set of players. Each player i P I chooses an action xi from its feasible action set Xi � Rmi , where mi P Z� denotes the dimension of the action. Let x :� px1, . . . , xpq P X be the action profile, where X � -iPI Xi is the global action set. We consider the setting where the game is played in different contexts, representing exogenous (but observable) conditions, e.g., variations in GDP and seasonality in Bertrand-Nash games. Given a contextual feature s P S, we assume each player i seeks to maximize its own utility function Ui pxi, x�i, sq : X � S � R. The utility depends on its own action xi P Xi, other players' actions x�i P X�i, and the contextual feature s. Here, X�i :� -jPIztiu Xj .
A Nash equilibrium x� :� �x�1 , . . . , x�p � P X of the game is defined as a point at which no player can unilaterally increase its utility [Nash, 1950], i.e., Ui �x�i , x��i , s� ¥ Ui �xi, x��i , s� , @xi P Xi, i P I under the given s P S.
We make the following standard assumptions: (i) The feasible set Xi is a nonempty, closed, and convex subset of Rmi for all i P I; (ii) Utility function Ui is continuously differentiable and pseudo-concave with respect to xi for all i P I; (iii) The contextual feature s is publicly known to all players. Under these assumptions, a Nash equilibrium x� P X exists in the game G [Nash, 1950].
Given a contextual feature ˆ sj of game G, there exists a Nash equilibrium ˆxj . Let pD � tpˆxj , ˆ sj quNj�1 denote the observable dataset of all equilibrium-context pairs. Our target is to estimate the utility functions of all players from pD. 1
We consider the case where Ui pxi, x�i, s; θiq can be parameterized by θi P Θi for each i. In practice, the form of Ui pxi, x�i, s; θiq is often known, but θi P Θi needs to be estimated from data. Let ϑ � pθ1; � � � ; θpq denote the parameter vector, i.e., the vertical concatenation of all θi. Our data-driven inverse game problem is as follows.
1 For example, in a price competition, each firm's utility is known only to itself, and depends on the prices of all firms and the economic condition. By observing the equilibrium prices under different economic conditions, we estimate the utility functions of all firms.
Problem 1. Given dataset pD � tpˆxj , ˆ sj quNj�1 , estimate parameters ϑ that reproduce equilibrium ˆxj in context ˆ sj , @j.
4 Incenter-Based Solution
4.1 ProblemReformulation
We begin by exploiting the fact that, under the assumption considered, x� P X is a Nash equilibrium if and only if it solves the variational inequality [Harker and Pang, 1990]:
Hence, Problem 1 can be equivalently reformulated as seeking a ϑ that satisfies the following inequalities for all j P rNs (j indexes the context-equilibrium pairs):
In the following, we consider a general setting where the player action set X j can also change with the contextual feature ˆ sj . Following the existing literature, e.g., [Bertsimas et al., 2015; Peters et al., 2023; Maddux et al., 2023], our work focuses on games where Ui px, s; θiq can be expressed as a linear combination of parameters θi and functions ϕi px, sq, i.e., Ui px, s; θiq � xθi,ϕi px, sqy. As will be shown in Section 5.1, many classic games fall into this category, including Bertrand-Nash price competition, aggregative games, and traffic games. For ease of presentation, let xi P R and ∇xi ϕi px, sq � φi px, sq. Then, we can rewrite (2) as
While there may exist (infinitely) many ϑ satisfying (3), motivated by [Zattoni Scroccaro et al., 2024], we propose to seek the incenter of all ϑ satisfying (3). As will be explained in Section 4.2, this solution is most robust to perturbations of the observable dataset pD.
We first formally define the incenter in Section 4.2. We then introduce a novel loss function approach to estimate it and thus learn ϑ in Sections 4.3 and 4.4. In Section 4.5, we extend our solution to incorporate prior knowledge about ϑ.
4.2 Incenter Parameter Vector
We define the set of parameter vectors consistent with the observed dataset pD as follows.
Definition 1 (Consistent Parameter Vectors). Given feasible action sets tX j uNj�1 , the dataset pD � tpˆxj , ˆ sj quNj�1 , and functions tφi px, squiPI , the set of consistent parameter vectors is defined as
In other words, C is the set of ϑ satisfying (3). Geometrically, it forms a convex cone. We focus on searching for the incenter of C, which is defined as follows.
Definition 2 (Incenter of C). Given a nonempty set C, its incenter ϑin is defined as
Here, int pCq is the region excluding the interior of C, and a �ϑ, ˜ ϑ� is the angle between ϑ and ˜ ϑ, i.e.,
.
Geometrically, an incenter ϑin of C can be viewed as a vector furthest away from the boundary of C, as measured by the angle. Since each facet of C is determined by a � ˆxj , ˆ sj � pair in dataset pD, incenter ϑin can be informally interpreted as the parameter vector that is most robust to perturbations of data pD (i.e., perturbations of the facets of C). For a formal description of this property, see the supplementary material.
For simplicity, we define a column vector φj :� �φ1 � ˆxj , ˆ sj � ; � � � ;φp � ˆxj , ˆ sj ��. In the following theorem, we formulate the problem of finding an incenter ϑin .
Theorem 1 (Incenter Computation). When C is defined as (4) and its interior is nonempty, finding ϑin that satisfies (5) is equivalent to solving the following problem:
In (6), d is the Hadamard product, vec p�q means stacking all elements into a column vector, and b denotes the Kronecker product. 1n is an n-dimensional all-one vector, where n is the dimension of φi � ˆxj , ˆ sj �. All the proofs are provided in the supplementary material.
Remark: The formulation in (6) converts the problem of finding ϑin that satisfies (5) to a convex optimization problem. Each xj P X j introduces a constraint to (6). In many games, the cardinality of Xj is very large or infinite. In this case, it is intractable to enumerate all elements of X j for all j P rNs to check if ϑ meets the inequality constraints.
4.3 Loss Function Design
We propose a loss function-based method to tackle the case where |Xj| is large or infinite. Interestingly, we notice that this approach also applies when there may be no ϑ consistent with pD, i.e., C{ t0u �H. This scenario is common, and arises if players are bounded-rational and may only choose actions close to the optimum, leading to an ϵ-Nash equilibrium. Towards obtaining a loss function, we first relax the
�
constraints of (6) by introducing slack variables β1, . . . , βN:
Then, we define the following loss function.
Definition 3 (Loss Function). Given a context-action pair � ˆxj , ˆ sj �, the loss ℓϑ � ˆxj , ˆ sj � of a parameter vector ϑ is defined as
.
Using the loss function, we reformulate the convex problem (7) as the following regularized empirical loss minimization problem (which remains convex):
Here, we replace }ϑ}2 in the objective with a general regularization function Rp�q and use α ¥ 0 as a hyperparameter. In our supplemental material, we use a toy example to illustrate the effectiveness of the reformulation.
Remark 1: In (8), we use the loss function to capture the hard inequality constraints in (7). Since (8) is an unconstrained optimization, we can solve it using a first-order algorithm in Section 4.4 even when |Xj | is infinite.
Remark 2: If no ϑ is consistent with pD, problem (6) has no feasible solution satisfying all the hard constraints. In this case, our loss function can still guide the search towards a vector that minimizes the degree of constraint violation.
4.4 Estimation Algorithm
In this section, we introduce a first-order algorithm for solving (8). We apply the mirror descent method [Beck and Teboulle, 2003], which enables the learning of ϑ in both Euclidean and non-Euclidean geometries. Specifically, at each iteration t, the mirror descent update is give by
Here, ηt ¡ 0 is the step-size, gt pϑtq is the subgradient of the complete loss function in (8), and function Bω is the Bregman divergence w.r.t. ω : Θ� R [Bubeck and others, 2015], i.e.,
In particular, when ω pϑq � 1 2 }ϑ}22 , (9) reduces to ϑt�1 � ϑt � ηtgt pϑtq, i.e., the subgradient descent update.
To implement the mirror descent method, we first derive subgradient gt pϑtq for the loss function in (8). Let h �xj , ˆxj , ˆ sj � :� ��φj d vec �1n b �xj � ˆxj �� ��2 . Using Danskin's Theorem [Bertsekas, 2016], we compute Bℓϑ � ˆxj , ˆ sj � (the subdifferential of ℓϑ � ˆxj , ˆ sj � w.r.t. ϑ) as
Algorithm 1 Mirror Descent for Problem (8)
1: function MIRROR DESCENT( pD, ω,R, tφiu , α, tηtu ,ϑ0) 2: for t P t0, . . . T � 1u do � Iteration of Estimation 3: for j P t1, . . .Nu do � Loop over pD 4: Compute ˜xjt according to (11); 5: Compute Bℓϑt � ˆxj , ˆ sj � according to (10); 6: end for 7: Compute subgradient gt pϑtq according to (12); 8: Apply mirror descent updates according to (9); 9: end for 10: return tϑtuTt�1 . 11: end functionHere, conv t�u represents the convex hull of the given set, and set X j pϑq � ˜xj (, where
Based on (10), the subgradient gt pϑtq is derived as
Algorithm 1 presents the pseudocode of the mirror descent algorithm for solving (8). In line 4 of Algorithm 1, we compute ˜xjt for each data point � ˆxj , ˆ sj � by solving a maximization problem. In line 5, we use the obtained ˜xjt to compute the subdifferential of ℓϑt � ˆxj , ˆ sj � based on (10). In lines 7 to 8, we utilize the entire dataset to compute the subgradient gt pϑtq of the objective function in (8), and then update current parameters to obtain ϑt�1 by solving (9). Under certain conditions, the mirror descent method guarantees that the expected objective value at the average of tϑtuTt�1 converges to the global minimum [Zattoni Scroccaro et al., 2024]. We leave the complexity analysis of Algorithm 1 to the supplemental material.
4.5 Incorporation of Priors
In this subsection, we extend our estimation method to incorporate a specific type of prior knowledge about ϑ. We define Fi px; θiq :� �BUi px, s; θiq{Bxi and let F px; θq :� pF1 px; θiq ; . . . ; Fp px; θiqq. In many games [LeBlanc et al., 1975; Jensen, 2018], F px; θq is known to be monotone, i.e., to satisfy
Such monotonicity property is closely related to the equilibrium solution in (1). For instance, if F px; θq is strictly monotone, there exists at most one Nash equilibrium [Harker and Pang, 1990]. Moreover, the projection gradient methods for solving (1) exhibit global convergence under this condition [Fukushima, 1992; Korpelevich, 1976; Xiu and Zhang, 2003; Bnouhachem et al., 2015].
We then aim at estimating ϑ while ensuring that F px; θq remains monotone. Towards this goal, we build upon the fact that F px; θq is monotone if and only if its Jacobian matrix is positive-semidefinite [Facchinei and Pang, 2003], i.e., dJ∇F pxq d ¥ 0, @x P X, d P Rp . Based on this observation, we incorporate this condition in (8) by using semidefinite program [Vandenberghe and Boyd, 1996].
The specific form of F px; θq can vary across different game applications, making a unified formulation of the semidefinite program challenging. Hence, we take the Bertrand-Nash competition as an example to introduce our solution. It is a classic game widely studied in literature [Berry, 1994; Berry et al., 1995; Bertsimas et al., 2015]. We include the formulations of Cournot and traffic games in the supplementary material.
For ease of presentation, we consider a two-firm Bertrand competition (i.e., p � 2). The analysis of more than two firms is provided in the supplementary material. Each firm i P t1, 2u chooses price xi to maximize revenue [Bertsimas et al., 2015; Maddux et al., 2023]:
where the terms in the parentheses correspond to the demand of firm i. In this case, ϑ � pθ1; θ2q P R8 .
In addition to the monotonicity property, there are some other common assumptions on ϑ in this competition, e.g., Ui is concave w.r.t. xi, and θ21, θ12 can be normalized to 1 without loss of generality [Maddux et al., 2023]. Next, we reformulate (8) to consider all these priors and assumptions.
�
For a two-firm Bertrand competition, formulation (8) can be extended to the following problem:
Here, A equals �0 1 1 0�, and the vector ei has a one in the i-th position and zeros elsewhere. Tr p�q is the trace operator. Constraint Tr ��eieJi � ℶ� ¥ 0, @i � 1, 2 implies θ11, θ22 / 0, ensuring the concavity of each Ui. Tr pAℶq � �1 indicates θ21 � θ12 � 1. ℶ, ˜ℶ ' 0 means that both ℶ and ˜ℶ are positive semidefinite. Loss function ℓℶ,˜ℶ � ˆxj , ˆ sj � is
�
To solve the convex problem (15), we apply the primaldual interior-point method [Boyd and Vandenberghe, 2004]. The primal barrier method augments the primal objective with a barrier function to handle inequality constraints, penalizing solutions near the boundary of the feasible set. The primal-dual interior-point method extends this concept to both the primal and dual problems, solving them simultaneously. It is often more efficient than the barrier method.
Algorithm 2 Primal-Dual Interior-Point for Problem (15)
- 1: function PD-IP( pD, α, ϵ, ℶ0 , ˜ℶ0 , Ξ0 , ˜Ξ0 , λ0 , ν 0 ). 2: 1 µ0 - Trpℶ0Ξ0 q�Trp ˜ℶ0˜Ξ0 q 4p � �pi�1 λ0i TrppeieJi qℶ0 q 4 ; 3: k - 0. 4: while 1 µk ¡ϵ do 5: Compute Ψjs � ¯xjk �, ˜Ψjs � ¯xjk � by pD, ℶk and ˜ℶk ; 6: Compute �∆ℶk , ∆˜ℶk , ∆Ξk , ∆˜Ξk , ∆λk , ∆ν k �; 7: Backtracking line search for step-sizes ηk p , ηk d ; 8: Compute �ℶk�1 , ˜ℶk�1 , Ξk�1 , ˜Ξk�1 , λk�1 , ν k�1�; 9: Compute 1 µk�1 ; 10: k - k � 1; 11: end while 12: return �ℶk , ˜ℶk , Ξk , ˜Ξk , λk , ν k �. 13: end function
To use the primal-dual interior-point method, we derive the perturbed KKT conditions based on the logarithmic barrier [Nesterov and Nemirovskii, 1994] as follows.
Proposition 1. Let pℶ� , ˜ℶ� q and pΞ� , ˜Ξ� , λ� , ν � q be the optimal primal and dual solutions, respectively, and µ be the barrier parameter. Then, the optimality conditions for the logarithmic barrier centering problem are
where I is the identity matrix, and ¯xj is defined as arg maxxj PX j !�Tr �Ψjsℶ� ��Tr� ˜Ψjs ˜ℶ���h�xj , ˆxj , ˆ sj �).
We use Newton's method [Alizadeh et al., 1998] to solve the equations in Proposition 1. We leave the details to our supplementary material.
Algorithm 2 shows the primal-dual interior-point method for solving (15). In line 5, we use current parameters ℶk and ˜ℶk to compute ¯xjk for each data point � ˆxj , ˆ sj �, and then obtain Ψjs p¯xjk q and ˜Ψjs p¯xjk q. In line 6, we compute the Newton updates p∆ℶ,∆˜ℶ,∆Ξ,∆˜Ξ,∆λ,∆νq. In lines 7, we utilize the backtracking line search to compute current step sizes ηk p and ηk d for the primal and dual variables, respectively. In lines 8 to 9, we update the current primal and dual variables, and compute barrier parameter µk�1 in the next iteration.
5 Numerical Experiments
5.1 Games Applications
Demand Estimation in Bertrand Competition The twofirm Bertrand competition was described in Section 4.5.
The demand function estimation problem is: Given data tpˆxj1 , ˆxj2 , ˆ sj quNj�1 , we seek to estimate ϑ � pθ1; θ2q P R8 such that each pˆxj1 , ˆxj2 q is a Nash equilibrium for context ˆ sj .
Profit Estimation in Aggregative Games In aggregative games [Jensen, 2018], each player i's utility Ui depends on its own action xi and the aggregation of all players' actions, i.e., Ui pxq � ˜Ui pxi, �pk�1 xkq. We take the Cournot competition as an example. Each firm i decides the quantity xi of a homogeneous product to supply, aiming to maximize:
The terms in the parentheses represent the inverse demand function, and ci is the unit cost of production. Following [Risanger et al., 2020], we include s as a demand shock that adjusts the demand intercept b. The problem is as follows: Given tpˆxj , ˆ sj quNj�1 , we seek ϑ � pa, b, d, c1, . . . , cpq P Rp�3 such that each ˆxj constitutes a Nash equilibrium.
Cost Estimation in Traffic Game We represent a road network by a tuple pV,A,W, t p�qq, where V and A denote the sets of nodes and links, respectively. W is the set of all Origin-Destination (OD) pairs. t p�q denotes the cost functions, and its a-th element ta p�q is the travel latency cost function for link a P A. A common choice for ta p�q is the U.S. Bureau of Public Roads (BPR) [Sheffi, 1985] function:
Here, xa is the overall traffic on link a, Ca is the capacity of link a, γ is the congestion sensitivity parameter, and θ0a , θ1a are cost parameters. In these settings it is standard to assume Ca and γ are common knowledge, while only θ0a , θ1a need to be estimated. The cost estimation problem is: Given link flow data tˆxj � pˆxja ; a P AquNj�1 , we seek to estimate cost parameters tθa � pθ0a , θ1a q, a P Au, such that each ˆxj is a Wardrop equilibrium [Sheffi, 1985; Patriksson, 2015].
5.2 Experimental Settings
Experimental Data We describe the dataset as follows.
- Bertrand Competition: Following [Maddux et al., 2023], we generate ϑ by randomly sampling its elements from Gaussian distributions: θ11 � Np�1.2, 0.52 q, θ12 � Np0.5, 0.12 q, θ21 � Np0.3, 0.12 q, θ22 � Np�1, 0.52 q, and θi3, θi4 � Np1, 0.52 q for i � 1, 2. We take s to be i.i.d. samples from Np5, 1.52 q. Given each ˆ sj , we solve for the equilibrium prices pˆxj1 , ˆxj2 q using first-order methods. To evaluate different estimation methods, we generate 50 random ϑ. For each ϑ, we create a training dataset pDtrain and a test dataset pDtest, both with a size of 500.
- Cournot Competition: We consider p � 3 players, and generate ϑ by randomly sampling its elements as follows: a, d � Up5, 10q, b � Np50, 52 q, ci � Up10, 20q. Given each context ˆ sj � Np6, 22 q, we solve for the Nash equilibrium ˆxj using first-order methods. We randomly generate 50 different ϑ for evaluation. Each ϑ has a corresponding pDtrain and pDtest, both with 500 samples.
- Traffic Game: We consider the Sioux Falls network [LeBlanc et al., 1975], which contains 24 nodes and 76 links. Every two nodes in the network constitute OD pairs. We set ϑ according to this real network. To generate multiple equilibrium data, following [Bertsimas et al., 2015], we randomly perturb the OD demands 1000 times, with each perturbation drawn from Up0, 0.1q. Using Frank-Wolfe algorithm and true ϑ, we then compute ˆxa for each perturbed OD demand. pDtrain and pDtest both contain 500 samples.
ComparisonMethods We compare the performance of the following five estimation methods:
- I-MD (Incenter with Mirror Descent): We estimate ϑ using Algorithm 1.
- I-SDP (Incenter with SemiDefinite Programming): We use Algorithm 2, which incorporates the monotonicity of F (the versions tailored for the Cournot competition and traffic game are in the supplementary material).
- Bertsimas (Data-Driven Estimation in Equilibrium Using Inverse Optimization [Bertsimas et al., 2015]): It estimates ϑ from observed equilibria based on inverse optimization without using the concept of incenter.
- Feasibility: It chooses a parameter vector from the set C of consistent parameter vectors. To check the feasibility of the parameter vectors w.r.t. (3), it discretizes each X j .
- Random: It randomly chooses a parameter vector.
5.3 Experimental Results
We evaluate the estimation errors of the methods using two metrics: (i) The ℓ2-distance between the estimated parameter vector ϑesti and the true parameter vector ϑtrue, i.e., }ϑtrue � ϑesti}2. To ensure consistent comparisons, all parameter vectors are normalized before evaluation; (ii) The ℓ2distance between the equilibrium xesti computed using ϑesti and the equilibrium xtrue computed using the true parameter vector ϑtrue, i.e., }xtrue �xesti}2. The scalability analysis of our methods is provided in the supplementary material.
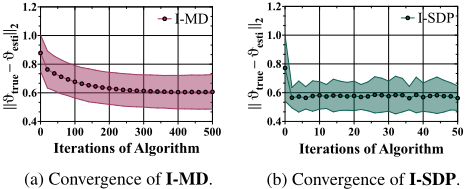
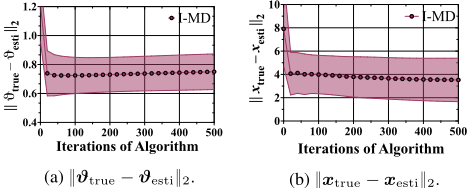
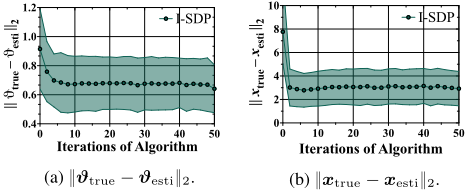
Bertrand Competition In Figure 2, we depict the convergence of our I-MD method on the Bertrand data. Figure 2a illustrates the average error between ϑesti and ϑtrue over 50 experiments (each with a different ϑtrue). The shaded area represents the standard deviation of these errors. Figure 2b shows the average error between the true equilibrium xtrue and the equilibrium xesti computed using ϑesti on the testing data. The convergence of our I-SDP method is depicted in Figure 3. Our I-SDP converges to lower errors in both metrics compared to I-MD. This is attributed to the incorporation of the monotonicity property of F. It can also be observed that I-SDP converges much faster, thanks to the efficiency of the primal-dual interior-point method.
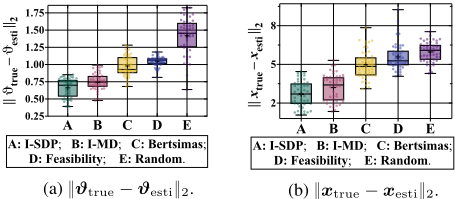
Figure 4 presents the comparative results of different estimation methods on the testing data, evaluated using two metrics. We use boxplots to illustrate the distribution of two error metrics across 50 trials for each method. Each box includes all error points, with the central line representing the median and the "�" sign denoting the mean error. Our I-SDP method achieves the lowest median and mean errors with minimal variability across both metrics. Specifically, for the metric }ϑesti � ϑtrue}2, I-SDP achieves the lowest mean error (around 0.663), whereas the comparison methods exhibit relatively large errors (with the best among them being 0.979). Similarly, for }xesti � xtrue}2, I-SDP again performs best, with a mean error around 2.690. Notably, our I-MD method outperforms all comparison methods across two metrics.
Cournot Competition In Figure 5, we present the convergence performance of our methods, measured by the gap between ϑesti and ϑtrue. We include the convergence about }xtrue � xesti}2 in the supplementary material. Comparing Figure 5a and Figure 5b, we can see that our I-SDP converges to a lower error at a much faster rate compared to I-MD.
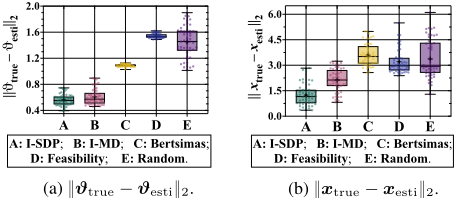
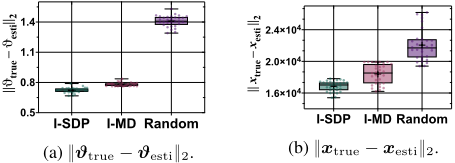
Figure 6 presents the boxplots concerning two error metrics across different estimation methods on the testing data. It can be observed that our I-SDP and I-MD methods outperform all the other methods across both metrics. Specifically, our I-SDP achieves the lowest errors, with a mean error of 0.562 for }ϑesti � ϑtrue}2 and a mean error of 1.245 for }xesti �xtrue}2. In contrast, the lowest errors among the comparison methods are 1.089 and 3.203 for the two metrics.
Traffic Game We leave the convergence performance of our methods with respect to }ϑesti � ϑtrue}2 to our supplementary material. Figure 7 presents a boxplot comparison of our two methods against Random on the testing data. Bertsimas and Feasibility are excluded, because (i) Bertsimas becomes intractable, as in the traffic game it requires solving an optimization problem with infinite constraints; (ii) Feasibility is impractical due to the vast size of the global action space (e.g., discretizing each flow region with only 2 values leads to a size of 276 ). It is evident that both our I-SDP and I-MD significantly outperform the Random method.
6 Conclusion
In this paper, we introduced a novel framework for estimating player utilities from their equilibrium behaviors. Our estimation framework is applicable to a broad range of multiplayer non-cooperative games and practical applications. We also extended it to account for a specific structural property in player utility functions. Experimental results on three game applications demonstrate the superiority of our methods over baselines. The main focus of our work is on efficiently computing the incenter and evaluating its effectiveness. Future directions will include analyzing the sample complexity of our utility estimation method and integrating utility estimation with the prediction of equilibrium behaviors.
Acknowledgments
This work was partially supported by the National Natural Science Foundation of China (No. 62202050), the Beijing Institute of Technology Research Fund Program for Young Scholars, the BIT Zhumeng Huanyu Scholarship for Innovative Talents, and the EPSRC grant EP/Y001001/1, funded by the International Science Partnerships Fund (ISPF) and UKRI.
@inproceedings{ijcai2025p423,
  title     = {Inverse Game Theory: An Incenter-Based Approach},
  author    = {Cui, Lvye and Yu, Haoran and Pinson, Pierre and Paccagnan, Dario},
  booktitle = {Proceedings of the Thirty-Fourth International Joint Conference on
               Artificial Intelligence, {IJCAI-25}},
  publisher = {International Joint Conferences on Artificial Intelligence Organization},
  editor    = {James Kwok},
  pages     = {3805--3813},
  year      = {2025},
  month     = {8},
  note      = {Main Track},
  doi       = {10.24963/ijcai.2025/423},
  url       = {https://doi.org/10.24963/ijcai.2025/423},
}
TY - CPAPER TI - Inverse Game Theory: An Incenter-Based Approach AU - Cui, Lvye AU - Yu, Haoran AU - Pinson, Pierre AU - Paccagnan, Dario T2 - Proceedings of the Thirty-Fourth International Joint Conference on Artificial Intelligence, IJCAI-25 PB - International Joint Conferences on Artificial Intelligence Organization PY - 2025 SP - 3805 EP - 3813 DO - 10.24963/ijcai.2025/423 UR - https://doi.org/10.24963/ijcai.2025/423 ER -Copied
Machine-readable versions of this paper, for tools and AI agents:





