
Beyond Symmetry in Repeated Games with Restarts
Proceedings of the Thirty-Fourth International Joint Conference on Artificial Intelligence. Main Track. Pages 3866-3873.
https://doi.org/10.24963/ijcai.2025/430
Keywords
- Game Theory and Economic Paradigms: GTEP: Noncooperative games
Abstract
Infinitely repeated games support equilibrium concepts beyond those present in one-shot games (e.g., cooperation in the prisoner's dilemma). Nonetheless, repeated games fail to capture our real-world intuition for settings with many anonymous agents interacting in pairs. Repeated games with restarts, introduced by Berker and Conitzer, address this concern by giving players the option to restart the game with someone new whenever their partner deviates from an agreed-upon sequence of actions. In their work, they studied symmetric games with symmetric strategies. We significantly extend these results, introducing and analyzing more general notions of equilibria in asymmetric games with restarts. We characterize which goal strategies players can be incentivized to play in equilibrium, and we consider the computational problem of finding such sequences of actions with minimal cost for the agents. We show that this problem is NP-hard in general. However, when the goal sequence maximizes social welfare, we give a pseudo-polynomial time algorithm.
- [Adar and Huberman, 2000] Eytan Adar and Bernardo A. Huberman. Free riding on gnutella. First Monday, 5(10), Oct. 2000.
- [Anastassacos et al., 2020] Nicolas Anastassacos, Stephen Hailes, and Mirco Musolesi. Partner selection for the emergence of cooperation in multi-agent systems using reinforcement learning. In Proceedings of the Thirty- Fourth AAAI Conference on Artificial Intelligence (AAAI- 20), 2020.
- [Berker and Conitzer, 2024] Ratip Emin Berker and Vincent Conitzer. Computing optimal equilibria in repeated games with restarts. In Proceedings of the Thirty-Third Interna- tional Joint Conference on Artificial Intelligence (IJCAI- 24), 2024. IJCAI
- [Blum, 1983] Manuel Blum. Coin flipping by telephone a protocol for solving impossible problems. ACM SIGACT News, 15(1):23-27, 1983.
- [Friedman, 1971] James W. Friedman. A non-cooperative equilibrium for supergames. The Review of Economic Studies, 38(1):1-12, 1971.
- [Fudenberg and Maskin, 1986] Drew Fudenberg and Eric Maskin. The folk theorem in repeated games with dis- counting or with incomplete information. Econometrica, 54(3):533-554, 1986.
- [Hardin, 1968] Garrett Hardin. The tragedy of the com- mons: the population problem has no technical solution; it requires a fundamental extension in morality. Science, 162(3859):1243-1248, 1968.
- [Hughes et al., 2005] Daniel Hughes, Geoff Coulson, and James Walkerdine. Free riding on gnutella revisited: the bell tolls? IEEE distributed systems online, 6(6), 2005.
- [Leung and Turrini, 2024] Chin-wing Leung and Paolo Tur- rini. Learning partner selection rules that sustain cooper- ation in social dilemmas with the option of opting out. In Proceedings of the Twenty-Third International Conference on Autonomous Agents and Multiagent Systems (AAMAS- 24), 2024.
- [Leung et al., 2024] Chin-wing Leung, Tom Lenaerts, and Paolo Turrini. To promote full cooperation in social dilem- mas, agents need to unlearn loyalty. In Proceedings of the Thirty-Third International Joint Conference on Artificial Intelligence (IJCAI-24), 2024. IJCAI
- [Mailath and Samuelson, 2006] George J Mailath and Larry Samuelson. Repeated games and reputations: long-run relationships. Oxford university press, 2006.
- [Mertens et al., 2015] Jean-Franc ¸ois Mertens, Sylvain Sorin, and Shmuel Zamir. Repeated games, volume 55. Cam- bridge University Press, 2015.
- [Moon and Conitzer, 2016] Catherine Moon and Vincent Conitzer. Role assignment for game-theoretic cooperation. In Proceedings of the Fifteenth International Conference on Autonomous Agents and Multiagent Systems (AAMAS- 16), pages 1413-1414, 2016.
- [Ngan et al., 2010] Tsuen-Wan Johnny Ngan, Roger Dingle- dine, and Dan S Wallach. Building incentives into tor. In Proceedings of the Fourteenth International Conference on Financial Cryptography and Data Security (FC-10), 2010.
- [Rand et al., 2011] David G Rand, Samuel Arbesman, and Nicholas A Christakis. Dynamic social networks promote cooperation in experiments with humans. Proceedings of the National Academy of Sciences, 108(48):19193-19198, 2011.
- [Wang et al., 2012] Jing Wang, Siddharth Suri, and Duncan J Watts. Cooperation and assortativity with dynamic partner updating. Proceedings of the National Academy of Sci- ences, 109(36):14363-14368, 2012.
- [Yang et al., 2012] Mu Yang, Vladimiro Sassone, and Sar- daouna Hamadou. A game-theoretic analysis of coopera- tion in anonymity networks. In Proceedings of the First International Conference on Principles of Security and Trust: First International Conference (POST-12), Held as Part of the European Joint Conferences on Theory and Practice of Software (ETAPS-12), 2012.
- [Zhang et al., 2016] Bo-Yu Zhang, Song-Jia Fan, Cong Li, Xiu-Deng Zheng, Jian-Zhang Bao, Ross Cressman, and Yi Tao. Opting out against defection leads to stable co- existence with cooperation. Scientific reports, 6(1):35902, 2016.
References were extracted automatically from the PDF and may contain errors.
Full text extracted automatically from the PDF; figures, tables and equations may differ. The PDF is the version of record.
1 Introduction
Social dilemmas often arise when individuals aim to satisfy their own incentives, which often may prohibit cooperation. In fact, in many games, although cooperating could yield better payoffs for both players, it does not yield a Nash equilibrium and is hence unlikely to occur. Repeated games can circumvent this concern by capturing more complex and realistic notions of equilibria, where mutual cooperation can be incentivized. For example, consider the game in Table 1.
Notice that in the single-shot version of the game, actions C1 and C2 ("cooperate") are strictly dominated by action D ("defect"). This leads to (D,D) being a dominant strategy Nash equilibrium, even though each player could obtain more value by cooperating. However, when playing this game repeatedly, cooperation ad infinitum can be an equilibrium given that players are sufficiently patient: both players can agree to cooperate by playing C1 until their opponent defects, at which point they start playing action D forever [Friedman, 1971]. In this case, no player is incentivized to deviate from C1, since any additional payoff they could receive from deviating would be offset by the subsequent punishment.
| C1 | C2 | D | |
|---|---|---|---|
| C1 | 8, 8 | 0, 8 | 0, 17 |
| C2 | 8, 0 | 2, 2 | 0, 11 |
| D | 17, 0 | 11, 0 | 1, 1 |
However, this type of collaboration fails in many realworld anonymous settings, in which players can choose to leave the game and restart with someone new. Consider an infinite collection of agents playing a repeated game in pairs either forever or until one of the players chooses to leave, in which case they are assigned a new partner. If there is no way for a player to check their new partner's history, a malicious agent could hop from partner to partner, defecting and then immediately leaving before suffering any punishment. In real-life relationships, such as ones between colleagues, freelancers with clients, or among romantic partners, agents tend to more gradually build up trust to avoid repeated exploitation. How can we formalize this game-theoretically?
One way is to consider repeated games with restarts [Berker and Conitzer, 2024], in which pairs of anonymous agents play an infinitely repeated game with the option to restart the game with a new player at any point. Consider then the strategy of everyone agreeing on a common sequence of actions to take, and if either player in a pair ever deviates from the sequence, the sequence is restarted. This simulates the agent punishing a defector by leaving the relationship and seeking a new partner. Ideally, such a sequence would incentivize agents to follow it at the risk of initiating a relationship with a new partner, which might come at a high cost.
Concretely, consider again the game in Table 1 and let (D,D), (C2,C2), (C1,C1), (C1,C1), . . . be a sequence of action pairs that both players commit to playing. Notice that the first action pair (D,D) is a dominant strategy Nash equilibrium, so no player has an incentive to deviate. In the second round, an agent can guarantee an additional payoff of +9 by deviating to action D. However, this results in their partner ending the relationship, at which point the deviating player will have to restart the sequence. This results in a (1 + 11)/2 = 6 per-round average payoff, whereas that player could have eventually guaranteed an average payoff of 8 by choosing to follow the sequence as is. Deviating to D on round three yields an additional payoff of 9, but this only amounts to a (1+2+17)/3 ≈ 6.66 average, compared to the 8 they could have gained following the existing sequence. A similar reasoning applies for future rounds, ensuring stability.
In previous work, Berker and Conitzer [2024] formalize this subclass of Nash equilibria in repeated games with restarts and analyze its computational complexity, in the restricted setting of symmetric games and symmetric strategies. However, even in a simple example such as the one above, having players alternate between two actions (an asymmetric strategy) can yield a higher per-round average payoff. For example, say from the third round onward, players follow the strategy (C1,D), (D,C1), . . . (alternating between actions C1 and D). Then, each will receive a per-round average payoff of (0 + 17)/2 = 8.5, compared to the 8 that the best symmetric strategy (C1,C1) could yield. This sequence is also stable: when each player plays action D, they receive a payoff of 17 and have no incentive to deviate. When playing C1, they could deviate to D for a +1 additional payoff, but this is once again offset by the cost of restarting the sequence. This shows that, even in symmetric games, equilibria with asymmetric strategies improve outcomes for both players. Therefore, in our work we aim to answer the following:
How can we optimize payoff of a (possibly asymmetric) equilibrium sequence in (possibly asymmetric) repeated games with restarts?
1.1 RelatedWork
Infinitely repeated games without restarts are well studied in the literature. For a thorough treatment, see Mailath and Samuelson [2006] and Mertens et al. [2015]. In particular, there are numerous characterizations of equilibria, referred to as Folk Theorems (see, for example, Friedman [1971] and Fudenberg and Maskin [1986]). One interpretation of a Folk theorem is that, for each action pair (a(1) , a(2) ) where players receive strictly more utility than their minmax payoff, there is a strategy and a sufficiently large discount factor such that (a(1) , a(2) ) is repeated forever in equilibrium. (Recall that in repeated games it is typical to introduce a discount factor β ∈ (0, 1) such that the round i utility is scaled by βi .) Here, the minmax payoff refers to the maximum payoff a player gets if their opponent plays the action minimizing the first player's maximum payoff. The key idea is that either player can punish their opponent for deviating by playing the action minimizing the opponent's (maximum) utility.
The Folk theorem result most relevant to our work is that of Fudenberg and Maskin [1986]. In their setting, the mere threat of punishment motivates players to adhere to Nash equilibria, since leaving your partner is not allowed. In comparison, as we will see, agents in our setting must be hazed upfront to prevent serial defectors. This distinction arises as a result of our model capturing anonymity among players, a feature common to many interactions in the real world. Another difference between our works is that our focus is not whether equilibria with a given stable sequence exist (the direct analogue of typical Folk theorem guarantees), but, given that they do, we aim to find the "best" such equilibrium among them. We view this as finding the "least severe" punishment for deviation that still ensures an equilibrium.
The negative impacts of anonymity on establishing cooperative outcomes are well-documented and have garnered significant scientific interest. For example, see Adar and Huberman [2000] and Hughes et al. [2005] for discussions of the rise of free-riding agents ultimately resulting in the decline of the peer-to-peer file sharing network Gnutella. This can be viewed as an instance of the Tragedy of the Commons [Hardin, 1968]. Several research strands have consequently analyzed game-theoretic approaches to encourage cooperation in anonymous settings [Ngan et al., 2010; Yang et al., 2012]. We take a different perspective, focusing not necessarily on how to incentivize cooperation, but, rather, how to understand and compute the most cooperative stable outcome under the restrictions imposed by the game at hand.
Cooperation among near-anonymous agents interacting in pairs has also been studied in repeated games in the context of partner selection rules [Zhang et al., 2016; Rand et al., 2011; Wang et al., 2012]. In prior work [Anastassacos et al., 2020; Leung and Turrini, 2024; Leung et al., 2024], they find the emergent dominance of "equivalent retaliation rules" akin to Tit-for-Tat. The latter two works demonstrate that learning agents both learn and (as a majority) adopt the Out-forTat rule, in which players leave partners who deviate against them. This provides strong empirical support for our model, which assumes this behavior.
Our starting point is a framework introduced by Berker and Conitzer [2024], who study repeated symmetric games with restarts in which all agents follow an identical sequence of moves. They prove several fundamental results on equilibrium sequences in this restricted setting.
Theorem 1. (Informal version of Proposition 1, Lemma 1, and Lemma 2 of Berker and Conitzer [2024]) In repeated symmetric games Γ with restarts and discount factor β, where all agents follow an identical sequence of actions (i.e., the strategy is symmetric), we have each of the following:
- If there is some equilibrium sequence for Γ, then there exists an equilibrium sequence maximizing the agents' payoffs, which we call an optimal sequence.
- Any optimal sequence will eventually reach a step in which both agents achieve a single payoff for the rest of the sequence. Call that payoff the goal value.
- For large enough β, the goal value of any optimal sequence will be the highest payoff of an action in Γ.
Theorem 1 has a number of implications. It is natural to seek equilibria where the agents have the best cumulative outcomes. The first property says that such equilibria in fact exist (at least, for example, in any game with a pure Nash equilibrium), making it reasonable to study such equilibria. The second and third properties characterize the general structure of optimal equilbrium sequences for sufficiently large discount factor β. They begin with a hazing period, in which the agents sacrifice utility to build mutual trust, followed by the agents reaping the reward of their camaraderie by receiving the goal value utility in each round thereafter.
Among such equilibrium sequences, some sequences require less hazing than others. Consider the game shown in Table 1. It is easy to check that both (D,D), (C2,C2), (C1,C1), (C1,C1), . . . and (D,D), (C2,C2), (C2,C2), . . . , (C2,C2), (C1,C1), (C1,C1), . . . are equilibrium sequences for sufficiently large β. However, the latter sequence delays the socially optimal action C1 unnecessarily.
Therefore, Berker and Conitzer [2024] define an equivalence relation among sequences, yielding a more granular view of optimality and capturing the notion of optimality of a sequence also with respect to the amount of required hazing (see Section 4 of Berker and Conitzer [2024], limit-utility equivalence classes). This in turn motivates a natural computational problem: given a symmetric game, compute an optimal symmetric strategy sequence with minimal hazing. They show that this problem is (weakly) NP-hard, while also giving a pseudo-polynomial time algorithm.
In showing these results, the authors utilize a number of properties of optimal sequences in this restricted setting. For instance, they exploit the so-called "threshold monotonicity" (see Lemma 3 of [Berker and Conitzer, 2024]) property, which intutively states we can restrict our attention to sequences that order actions in terms of how much hazing they need before they can be played. This does not hold when extending to asymmetric strategies, as playing an action pair might require different amounts of hazing for each player.
In this work, we significantly relax the structural assumptions of [Berker and Conitzer, 2024], considering repeated games in which the players need not play the same action in each round and in which the game itself may be asymmetric. In the case of symmetric games and asymmetric strategies, this raises the question of which strategy each player will be assigned to when rematching. We primarily consider the case in which players follows the same strategy every time they rematch with a new partner. In Section 6 we permit players to switch roles when rematching. Our main complexity and algorithmic results easily extend to this setting.
1.2 Motivating Examples
We begin by giving several examples to motivate our results, differentiate them from those in [Berker and Conitzer, 2024], and highlight the complex behaviors that arise in this setting.
Symmetric games with asymmetric strategies. Consider the game of two agents working on a series of group projects. Two distinct tasks must be done to complete each project, T1 and T2, and the agents only get utility 1 if the project is complete. This symmetric game is represented in Table 2. Note that, even though this is a symmetric game, no sequence of pairs of actions with both players always playing the same action will be stable: both players are incentivized to deviate when playing (T2, T2) or playing (T1, T1). Hence, no stable sequence exists in this game under the model considered in [Berker and Conitzer, 2024]. However, (T1, T2) is a pure strategy Nash equilibrium, and, hence, repeating this action pair forever is a stable sequence in our model.
Some (even symmetric) games are unfair. Can we always distribute the hazing cost or utility fairly between agents? It turns out that sometimes agents must be hazed unequally to achieve minimum total hazing.
| T1 | T1 0, 0 | T2 1, 1 |
| T2 | 1, 1 | 0, 0 |
| C | D | H1 | H2 | |
|---|---|---|---|---|
| C | 99, 99 | 0, 100 | 0, 0 | 0, 0 |
| D | 100, 0 | 0, 0 | 0, 0 | 0, 0 |
| H1 | 0, 0 | 0, 0 | 0, 0 | 5, 50 |
| H2 | 0, 0 | 0, 0 | 50, 5 | 0, 0 |
Consider the game in Table 3. The maximum social welfare outcome consists of (C,C) repeating ad infinitum, and, for large enough discount factor, it is possible to haze enough to disincentivize deviation from (C, C) in only a single round. However, the minimum hazing sequence must include only one of either (H1,H2) or (H2,H1), leading to uneven total hazing. Inherently unfair games are perhaps less surprising in the asymmetric setting, but which games this holds for is not immediately obvious. We explore this question in Section 3.
Due to the complexity of characterizing the "fairness" of stable sequences, we focus on formulating and solving corresponding optimization problems, the focus of Section 5.
1.3 Organization of the Paper
In Section 3, we formalize the notions of (possibly asymmetric) equilibrium sequences in repeated games with restarts. In Section 4, we characterize the conditions under which finite sequences of action pairs can form the "goal sequences" of stable sequences. In Section 5 we consider this problem in the limit as the discount factor becomes negligible. In this regime, we define two optimization problems related to finding minimum hazing stable sequences and show that both are NP-hard. We also show that when the goal sequence is composed of maximum social welfare action pairs, there is a pseudo-polynomial time algorithm for solving the problem. Section 6 addresses an alternative model where agents can change roles after restarting the game. In Section 7, we discuss several directions for future work. All omitted proofs can be found in the appendix of the full version of the paper.
2 Preliminaries
Say Γ is a two-player normal-form game, with a set of action pairs A = A(1) × A(2) , where A(i) = {a(i) 1 , a(i) 2 , . . . , a(i) n(i) } is the set of actions available to player i.
- We let p(i) : A → Z be the payoff function of player i, taking as input a pair of actions of the two players and outputting an integer value. As shorthand, we also let p(1)+(2) denote p(1) + p(2) .
- Let β ∈ (0, 1) be the discount factor such that if player i receives payoff p(i) t in timestep t, then her total discounted utility will be ∑∞t=0 βt p(i) t .
| R | C |
|---|---|
| r 1, 0 | -100,-100 |
| c -100,-100 | 0, 1 |
We will denote a game as a tuple, Γ = (p(1) , p(2) ,A). When i refers to a player, we use -i to refer to their opponent. The sequences of action pairs are 0-indexed for consistency with the powers of the discount factor β. With N we denote the non-negative integers.
3 Equilibrium Sequences
We focus on strategies corresponding to sequences σ = (σ(1) t , σ(2) t )t∈N, where σ ∈ AN is a sequence of action pairs in Γ such that player i commits to playing (σ(i) t )t∈N. Player 1 will restart the sequence if player 2 deviates from σ(2) and vice versa. We also allow either player to restart the game after any round (even without deviating). This is a subtlety that does not arise in [Berker and Conitzer, 2024]. We illustrate the possibility of agents wanting to restart the game without deviating through the following example.
Example 1 (Restarting without Deviating). Consider the game in Table 4. Consider any sequence (tightrope) σ ∈ {(r,R), (c,C)}N. Neither player can ever deviate or they receive -100 utility (fall off the tightrope). Hence, if players could only restart upon deviations of their opponents, any such σ would be stable. However, if the players are permitted to restart after any round, one of the players can always ensure they receive utility 1. Namely, if σ0 = (r,R), the row player can restart the game after the first round and similarly for the column player if σ0 = (c, C). We view the options for players to restart after any round as akin to typical assumptions of individual rationality.
Below we formally define the notion of a stable sequence of action pairs (i.e., a Nash equilibrium), in which no player can gain more utility by deviating or restarting.
Definition 2 (Stable Sequences). We call a sequence σ = (σ(1) t , σ(2) t )t∈N ∈ AN stable for discount factor β if no player can increase their discounted utility by deviating or restarting the game at any timestep. Concretely, for player 1 we have, for all k ∈ N and a(1) ∈ A(1) :
The analogous inequalities must also hold for player 2.
Remark 3. A careful reader might notice that Definition 2 only seems to consider players deviating a single time. This is because, if deviating only once cannot increase a player's utility, deviating more than once cannot either (this is an application of the "one-shot deviation principle"). An analogous observation was made in [Berker and Conitzer, 2024].
Proposition 4. It benefits a player to deviate at least once if and only if it benefits a player to deviate once.
The proof follows by a simple inductive argument, using that, post-deviation, the remaining game becomes a scaled version of the initial game.
Notice that there can be infinitely many stable sequences for a given game (e.g., stable sequences of the form (D,D), (C2,C2), (C2,C2), . . . , (C1,C1), (C1,C1), . . . in the game in Table 1). Therefore, we would like to be able to (1) distinguish these sequences and (2) compute the most desirable among them. To do so, we formalize the notions of Paretooptimality, welfare maximization, and limit-utility fairness. In Section 4, we describe stable sequences in symmetric games with asymmetric strategies that satisfy all three properties.
Remark 5. In our study of stable sequences, we restrict our attention to sequences of the following form: a finite length prefix followed by an infinite periodic sequence of action pairs. We call the initial prefix the hazing period and the finite sequence repeated infinitely thereafter the goal sequence. A finite description length is a prerequisite for efficient computation, and general sequences need not necessarily admit one -there is an uncountably infinite number of sequences but only a countably infinite number of finite descriptions. Moreover, periodicity allows us to take limits of the sums of differences of payoffs in sequences without concern for sequence convergence issues. This permits a natural way to compare the "quality" of sequences and formally define the related optimization problems of finding "optimal" stable sequences.
Definition 6 (Pareto-Optimal Sequence). Given a game Γ = (p(1) , p(2) ,A) and σ, ˜σ ∈ AN, we say that σ surpasses ˜σ if there exists i ∈ [2] such that:
A sequence σ ∈ AN is Pareto-optimal (in β → 1) if (1) it is stable for all sufficiently large β and (2) it is not surpassed by any other stable sequence.
A notion stronger than Pareto optimality is welfare maximization, which we define for our context below.
Definition 7 (Welfare maximization). Given a game Γ = (p(1) , p(2) ,A), a stable sequence σ ∈ AN is welfare maximizing (in the β → 1 limit) if, for any other stable sequence ˜σ ∈ AN, it holds that:
We give a final desirable property of stable sequences.
Definition 8 (Limit-utility fairness). Given a game Γ = (p(1) , p(2) ,A), a stable sequence σ ∈ AN is limit-utility fair if there exists T ∈ N such that limβ→1 ∑∞t=T βt (p(1) (σt) - p(2) (σt)) = 0.
Remark 9. Limit-utility fairness is not always possible in asymmetric games. For example, it is not possible in games where one player always receives strictly more utility than the other. Even when the players' utilities are normalized to be between 0 and 1, say by shifting their minimum utilities to each be 0 and then scaling down, there are inherently "unfair" examples, such as the one shown in Table 5.
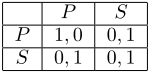
In this game, if either player plays S, the row player "suffers," receiving utility 0. Indeed, the row player only receives utility 1 if both players play P ("seek and receive pity"). But, the sequence repeating (S, S) forever is stable, and no stable sequence can ever include (P, P) since the column player will always be incentivized to deviate to (P, S).
4 Existence Results
Our starting point is the following:
For which pairs (Γ, γ), for Γ a game and γ ∈ Ar , can γ be the goal sequence of a stable sequence of Γ?
Not all (even symmetric) games admit stable sequences, e.g., Rock-Paper-Scissors. Moreover, although all 2×2 symmetric games have a stable sequence, this does not hold for asymmetric games. We discuss these nuances in the appendix of the full version of the paper.
Theorem 12 characterizes which goal sequences can arise in stable sequences. For convenience, we define the goal value of a goal sequence γ as the average per-round payoffs obtained in the goal sequence when β → 1. We also introduce notation for the deviation payoffs for an action pair.
Definition 10 (Goal value). Given a game Γ = (p(1) , p(2) , A) and a goal sequence γ ∈ Ar , its corresponding goal value is
Definition 11 (Deviation payoff). Given a game Γ = (p(1) , p(2) , A), and action pair a = (a(1) , a(2) ) ∈ A, define
Theorem 12. Let Γ = (p(1) , p(2) ,A) be a game and γ ∈ Ar .
- Suppose there exists a ∈ A such that d(1) a < v(1) γ and d(2) a < v(2) γ . Then, for large enough β ∈ (0, 1) and T ∈ N, the sequence σ repeating a for T time steps and then repeating γ forever is stable.
- If for all a ∈ Awe have d(1) a > v(1) γ or d(2) a > v(2) γ then, for any β, no stable sequence has γ as its goal sequence.
The proof of the first part is inspired by the Folk theorem. The second part follows from considering stability at the first action pair in a candidate stable sequence.
Corollary 13. Let Γ be symmetric and suppose there exists a∗ = (a(1) ∗ , a(2) ∗ ), a ∈ A with a∗ maximum social welfare and d(1) a , d(2) a < (p(1) (a∗) + p(2) (a∗))/2. Then γ = ((a(1) ∗ , a(2) ∗ ), (a(2) ∗ , a(1) ∗ )) is the goal sequence of some stable sequence in Γ by Theorem 12. Moreover, this stable sequence is Pareto-optimal, limit-utility fair, and welfare-maximizing.
5 ComputingMinimumHazing Sequences
We next consider the problem of computing stable sequences with minimum hazing in the β → 1 limit. We begin by defining the hazing cost and threshold for a given action pair.
Definition 14 (Hazing Cost, Threshold). For a game Γ = (p(1) , p(2) , A), goal sequence γ ∈ Ar , a ∈ A, and i ∈ [2], we define the hazing cost h(i) a := v(i) γ -p(i) (a) and the threshold t(i) a := d(i) a - v(i) γ for player i.
The hazing cost of an action pair for a player defines how much utility that player loses in the long run by playing that action compared to her average utility in the goal sequence. 1 Intuitively, we want the hazing sequence to have a sufficiently high cost for both players to disincentivize them from taking an action that would result in restarting the sequence. As we will see, the threshold of an action pair for a given player defines the amount of total hazing that that player must have accumulated before playing that action in order to guarantee that they will not deviate. In Theorem 17, we will make use of these two definitions to give a sufficient and necessary condition for stability in the β → 1 limit.
For conciseness, we also define notation for total hazing and the threshold for a goal sequence.
Definition 15 (Total Hazing). Let σ ∈ AN be a stable sequence with goal sequence γ ∈ Ar for a game Γ = (p(1) , p(2) ,A). For each k ∈ N, define the total hazing up to time k, Hk := (H(1) k ,H(2) k ) = ∑kt=0 hσt , to be the sum of hazing costs of the first k + 1 actions in the hazing period.
Definition 16 (Threshold for a goal sequence). For a goal sequence γ ∈ Ar and i ∈ [2], define its threshold as:
In words, for each k ∈ [r], we need to surpass the threshold for γk upon reaching it, which is only possible by accumulating θ(i) γ hazing for each player i by the time the goal sequence is reached. The summation in equation (1) accounts for the change in total hazing (after the goal sequence begins) up to the (k - 1)th action pair in the goal sequence.
Finally, Theorem 17 defines the stability of a sequence in the β → 1 limit.
Theorem 17. Let Γ = (p(1) , p(2) , A) be a game. A sequence σ ∈ AN with finite hazing period and goal sequence γ ∈ Ar is stable for all sufficiently large β ∈ (0, 1) if and only if, for all k ∈ N and i ∈ [2], we have H(i) k-1 > t(i) σk .
The intuition for the strict inequality here is that ties break in favor of deviating, since the deviation payoff comes earlier.
We can also characterize stability in the limit β → 1 using the language of thresholds of the goal sequence.
Corollary 18. A sequence σ formed by a hazing period of length T and a repeated goal sequence γ ∈ Ar is stable in the β → 1 limit if and only if σ is stable in the hazing period in the β → 1 limit and, for i ∈ [2], H(i) T > θ(i) γ .
1 Note that the hazing cost could be negative for some actions.
Using the necessary and sufficient conditions for stability from Corollary 18, we now define the computational problem of finding sequences inducing the minimum possible hazing. Definition 19 (MINHAZING). Denote the hazing and threshold tuples for each action pair and each player in a game as {(h(1) a , h(2) a , t(1) a , t(2) a )}a∈A∈ ((1/r · Z)4)|A| . Also let (θ(1) , θ(2) ) ∈ ( 1r · Z)2 be the thresholds for a goal sequence for each player. Given ∆ > 0, MINHAZING asks to find a sequence σ ∈ Aℓ (for any finite ℓ) such that the sum of the total hazings satisfies H(1)+(2) ℓ-1 = ∑ℓ-1 t=0 h(1)+(2) σt ≤∆, subject to:
Notice that, by Theorem 12, in some games it is easy to compute hazing sequences that induce stable sequences with goal sequence γ. In fact, if there exists some action pair a ∈ A that satisfies the conditions of Theorem 12, repeating a sufficiently many times makes for such a hazing sequence. Moreover, the sum of the players' total hazing will be at most:
where κ is the difference between the largest and smallest possible payoff values in Γ. However, this trivial upper bound, B, could be arbitrarily larger than the minimum hazing possible, which is what we explore in this section.
Remark 20. In the instance of MINHAZING induced by Γ and a finite length goal sequence γ ∈ Ar , we have (θ(1) γ , θ(2) γ ) ∈ ( 1r · Z)2 and {(h(1) σ , h(2) σ , t(1) σ , t(2) σ )}σ∈A ∈ (( 1r · Z)4 )|A| . This follows directly from Definitions 14 and 16. We make heavy use of this fact in Algorithm 1.
Theorem 21. MINHAZING is (weakly) NP-hard.
Proof Sketch. The key idea is to reduce from the Unbounded Subset-Sum Problem with non-negative integers. We define a symmetric game in which: all but the threshold for the goal sequence action pair are trivially met and only the main diagonal action pairs are viable in a minimum hazing stable sequence. The payoffs on the main diagonal can then be chosen such that their hazing costs correspond to the integers from the instance of Unbounded Subset-Sum.
Although MINHAZING is well-defined in broad generality, we are mostly interested in the problem of computing minimum hazing sequences for welfare-maximizing stable sequences with infinitely repeated finite-length goal sequences. So, we define the following computational problem.
Definition 22 (MAXWELFAREMINHAZING). Consider a game, Γ = (p(1) , p(2) ,A), and a goal sequence, γ ∈ Ar , where for each t ∈ [r], γt ∈ A is a maximum social welfare action pair. Suppose also that γ is the goal sequence of a stable sequence, σ, that achieves total sum of hazings B. Then MAXWELFAREMINHAZING(Γ, γ,B) is the instance of MINHAZING induced by Γ, γ, and total hazing bound B.
Remark 23. Since γt ∈ A is maximum social welfare for each t ∈ [r], we know that each a ∈ A has h(1) a + h(2) a ≥ 0. Indeed, if not, then a would induce higher social welfare than the per-round average payoff in γ, a contradiction.
We will use the structure of MAXWELFAREMINHAZING to show that for any stable sequence with goal sequence γ ∈ Ar , there exists another highly structured stable sequence with goal sequence γ and minimum hazing (Lemma 24). This insight will allow us to solve MAXWELFAREMINHAZING in pseudo-polynomial time (Theorem 27).
Lemma 24. For a game Γ, let γ ∈ Ar be a maximum social welfare goal sequence, such that there exists a stable sequence with goal sequence γ and total hazing B. Then, there exists a minimum hazing stable sequence σ with goal sequence γ, such that for k and k1 < k2 in the hazing period: 1. Total hazing bound: 0 ≤ H(1) k ,H(2) k ,H(1)+(2) k ≤ B.
- Monotonicity of total hazing: H(1)+(2) k2 -H(1)+(2) k1 ≥ 0.
- Injectivity of total hazing: (H(1) k1 ,H(2) k1 ) ̸= (H(1) k2 ,H(2) k2 ).
Proof Sketch. The first two properties follow from stability and the fact that each γt ∈ γ is maximum social welfare. The third property exploits the observation that we can remove segments of the hazing period between repeated pairs of total hazing values without compromising stability.
Although MINHAZING is not obviously in NP in general (e.g., optimal stable sequences can have exponentially long hazing periods), MAXWELFAREMINHAZING is indeed in NP under some weak additional structural assumptions.
Theorem 25. MAXWELFAREMINHAZING(Γ, γ,B) (in its decision version) is in NP for classes of games Γ, goal sequence γ ∈ Ar with |A| = n and r = poly(n), and B such that either one of the following conditions is satisfied:
- There is a stable sequence with goal sequence γ with total hazing poly(n), e.g., B = poly(n).
- There exists a stable sequence with at most poly(n) action pairs with negative hazing value for either player.
Proof Sketch. The first sufficient condition follows from the second and third properties of Lemma 24 (or Theorem 27). The second condition follows from the fact that, as long as the threshold for some a ∈ A is met at some time step t and it does not contribute negative hazing to either player, it can be inserted at time step t without disrupting stability. This allows for clustering all such a ∈ A into consecutive runs, yielding hazing sequences with succinct representations.
Remark 26. The first part of Theorem 25 holds when the utilities in Γ are bounded by poly(n) and there exists a ∈ A such that v(i) γ > d(i) a for i ∈ [2]. Indeed, byTheorem12, since the threshold for γ is poly(n), repeating a ∈ A for poly(n) iterations, followed by cycling through γ, results in a stable sequence with goal sequence γ and poly(n) total hazing.
Finally, we give a dynamic programming algorithm for solving MAXWELFAREMINHAZING (Algorithm 1) and prove that it runs in pseudo-polynomial time (Theorem 27).
We start by giving an overview of Algorithm 1. Given as input the tuples of thresholds and hazing costs for each action pair, the threshold for the goal sequence, and the upper bound B on the total hazing, the algorithm will first construct an empty queue, Q, and a matrix, memo, indexed by all possible pairs of hazing values (rationals with denominator r between 0 and B from Remark 20). The algorithm will start with a total hazing value of 0 for each player (i.e., starts at the upper left entry of memo), and, from that pair of hazing values, it will consider all possible action pairs available to the agents. For each action pair that satisfies the conditions of Lemma 24 and whose threshold is met, the algorithm will compute the new reachable total hazing for each player by adding the hazing cost of that action pair to the the total hazing of each player so far. That will "move" the algorithm to a different entry in memo, and the algorithm will enqueue that entry to be explored later. The algorithm then proceeds in a breadthfirst-search manner, dequeuing pairs of hazing values from Q (i.e., "visiting" entries in memo) and considering all other entries in memo that can be reached by taking "valid" action pairs. While visiting each entry in memo, the algorithm keeps track of the minimum total hazing value pair encountered so far that satisfies the goal threshold, as well as the appropriate information to reconstruct the minimum hazing sequence. The algorithm terminates when Q is empty. Recall that we use h(1)+(2) as shorthand denoting h(1) +h(2) (see Section 2).
Theorem27. MAXWELFAREMINHAZING(Γ, γ,B) is solvable in O(poly(n)r2B2 ) time and O(r2B2 ) space, where |A| = n and γ ∈ Ar .
Proof Sketch. We use the structure of the min-hazing sequence shown in Lemma 24 to upper bound the size of memo that needs to be searched to find that sequence. This allows us to bound the time and space complexity of the algorithm.
Note that while Algorithm 1 minimizes H(1)+(2) as written, it can be modified to minimize any function of the hazing costs H(1) , H(2) by modifying Steps 10 and 24 accordingly.
6 RandomPlayer Reassignment
In this section, we consider a variant of our framework, where the roles of players may switch after a rematch. Indeed, in other settings, it has been shown that such role-switching can promote cooperation [Moon and Conitzer, 2016]. As before, we assume each player is required to play at least one round of the game with their partner, and can choose to leave after any round. When reassigned to a new relationship, they take on each of the two possible player roles with probability 1/2. We introduce the analogous notion of stability below.
Definition 28 (Stable Sequences, Random Player Reassignment). We call a sequence σ = (σ(1) t , σ(2) t )t∈N ∈ AN stable if no player can increase their expected discounted utility by deviating at any timestep. This means for all k ∈ N and i ∈ [2] we have ∑k-1 t=0 βt p(i) (σt) + βk d(i) σk + ∑∞t=0 βk+1+t p(i) (σt)+p(-i) (σt) 2 ≤ ∑∞t=0 βt p(i) (σt).
With Definition 2, defecting multiple times was profitable only if defecting once was as well. This remains true here and follows from an argument similar to Proposition 4.
Just as before, instances of MAXWELFAREMINHAZING and MINHAZING are induced by this variant of the repeated games framework (each action pair has a threshold value, hazing value, etc.). It is not hard to show that the same NP-hardness result holds (by the same construction as in Theorem 21), and Algorithm 1 still solves MAXWELFAREMINHAZING in pseudo-polynomial time.
Algorithm 1 Dynamic Programming Algorithm for
- MAXWELFAREMINHAZING 1: Input: (1.) Goal sequence threshold θ := (θ(1) , θ(2) ) ∈ ( 1r · Z)2 , (2.) action pair hazing costs and threshold {(h(1) a , h(2) a , t(1) a , t(2) a )}a∈A ∈ (( 1r · Z)4 )|A| , and (3.) initial total hazing bound B. 2: Output: Hazing sequence, σ∗ ∈ Aℓ , and total hazing H(1) ∗ +H(2) ∗ ∈ 1r · Z. 3: Create an empty queue, Q 4: memo ← [] × [] {Indexed by pairs in [0, B] × [0, B]} 5: (H(1) ∗ ,H(2) ∗ ) ← (B,B) {Min. hazing above θ so far} 6: Enqueue(0, 0, none, none) {Hazing pairs to process} 7: while Q is not empty do 8: (H(1) ,H(2) , p, ap) ← Dequeue(Q) {H(i) is current hazing for player i} 9: memo[H(1) ,H(2) ] = (p, ap) {Parent (hazing, action)} 10: if H(i) > θ(i) ∀i ∈ [2] and H(1)+(2) < H(1)+(2) ∗ then 11: (H(1) ∗ ,H(2) ∗ ) ← (H(1) ,H(2) ) {Update optimal} 12: continue 13: for a := (a(1) , a(2) ) ∈ A do 14: if ∃i ∈ [2] s.t. H(i) < t(i) a or (H(1) +h(1) a ,H(2) + h(2) a ) ∈ memo then 15: continue {Thresh. unsatisfied or redundant} 16: if H(1)+(2) + h(1)+(2) a > B or ∃i ∈ [2] s.t. H(i) + h(i) a < 0 then 17: continue {Invalid or irrelevant hazing pair} 18: Enqueue((H(1) +h(1) a ,H(2) +h(2) a , (H(1) ,H(2) ), a) 19: σ∗ ← () 20: (H(1) ,H(2) ) ← (H(1) ∗ ,H(2) ∗ ) 21: while memo[H(1) ,H(2) ][2] ̸= none do 22: σ∗.prepend(memo[H(1) ,H(2) ][3]) {Rebuild σ∗} 23: (H(1) ,H(2) ) ←memo[H(1) ,H(2) ][2] 24: return: σ∗,H(1)+(2) ∗
7 Directions for FutureWork
There are several interesting directions for future work. One avenue is to permit mixed strategies. How would agents verify whether their opponent adhered to their assigned strategy or deviated to another strategy with the same support? Cryptographic protocols, such as those in Blum [1983], are a good candidate approach for strategy verification.
Another direction is to extend our algorithmic results beyond maximum social welfare goal sequences. The main difficulty in this general setting is that net "unhazing" is now possible, so total hazing is no longer monotonic.
A third direction is to extend our work to fixed discount factors β. While some of our results hold for large enough β (e.g., Theorem 12 and Corollary 13), our algorithmic approach does not; for fixed β, the thresholds for actions depend on the time they are played.
Our results extend to games with any number of players, although Algorithm 1's runtime scales exponentially.
Acknowledgements
We are grateful to Tuomas Sandholm and Brian Hu Zhang for their valuable feedback on an early manuscript and George Z. Li for helpful discussions in the early stages of this project. We also thank our IJCAI'25 reviewers for their generous and detailed reviews.
This material is based upon work supported by the National Science Foundation Graduate Research Fellowship Program under Grant No. DGE2140739. Any opinions, findings, and conclusions or recommendations expressed in this material are those of the author(s) and do not necessarily reflect the views of the National Science Foundation.
R.E.B. thanks the Cooperative AI Foundation, Macroscopic Ventures (formerly Polaris Ventures / the Center for Emerging Risk Research) and Jaan Tallinn's donor-advised fund at Founders Pledge for financial support. R.E.B. is also supported by the Cooperative AI PhD Fellowship.
@inproceedings{ijcai2025p430,
  title     = {Beyond Symmetry in Repeated Games with Restarts},
  author    = {Fleischmann, Henry and Fragkia, Kiriaki and Berker, Ratip Emin},
  booktitle = {Proceedings of the Thirty-Fourth International Joint Conference on
               Artificial Intelligence, {IJCAI-25}},
  publisher = {International Joint Conferences on Artificial Intelligence Organization},
  editor    = {James Kwok},
  pages     = {3866--3873},
  year      = {2025},
  month     = {8},
  note      = {Main Track},
  doi       = {10.24963/ijcai.2025/430},
  url       = {https://doi.org/10.24963/ijcai.2025/430},
}
TY - CPAPER TI - Beyond Symmetry in Repeated Games with Restarts AU - Fleischmann, Henry AU - Fragkia, Kiriaki AU - Berker, Ratip Emin T2 - Proceedings of the Thirty-Fourth International Joint Conference on Artificial Intelligence, IJCAI-25 PB - International Joint Conferences on Artificial Intelligence Organization PY - 2025 SP - 3866 EP - 3873 DO - 10.24963/ijcai.2025/430 UR - https://doi.org/10.24963/ijcai.2025/430 ER -Copied
Machine-readable versions of this paper, for tools and AI agents:





