
Viral Marketing and Convergence Properties in Generalised Voter Model
Proceedings of the Thirty-Fourth International Joint Conference on Artificial Intelligence. Main Track. Pages 3970-3978.
https://doi.org/10.24963/ijcai.2025/442
Keywords
- Multidisciplinary Topics and Applications: MTA: Web and social networks
- Data Mining: DM: Networks
- Data Mining: DM: Mining graphs
- Game Theory and Economic Paradigms: GTEP: Computational social choice
Abstract
Consider a social network where each node (user) is blue or red, corresponding to positive or negative opinion on a topic. In the voter model, in discrete time rounds, each node picks a neighbour uniformly at random and adopts its colour. Despite its significant popularity, this model does not capture some fundamental real-world characteristics such as the difference in the strengths of connections, individuals with no initial opinion, and users who are reluctant to update. To address these issues, we introduce a generalisation of the voter model.
We study the problem of selecting a set of seed blue nodes to maximise the expected number of blue nodes after some rounds. We prove that the problem is NP-hard and provide a polynomial time approximation algorithm with the best possible approximation guarantee. Our experiments on real-world and synthetic graph data demonstrate that the proposed algorithm outperforms other algorithms.
We also prove that the process could take an exponential number of rounds to converge. However, if we limit ourselves to strongly connected graphs, the convergence time is polynomial and the convergence period (size of the stationary configuration) is bounded by the highest common divisor of cycle lengths in the network.
- [Abdullah and Draief, 2015] Mohammed Amin Abdullah and Moez Draief. Global majority consensus by local ma- jority polling on graphs of a given degree sequence. Dis- crete Applied Mathematics, 180:1-10, 2015.
- [Auletta et al., 2018] Vincenzo Auletta, Diodato Ferraioli, and Gianluigi Greco. Reasoning about consensus when opinions diffuse through majority dynamics. In IJCAI, pages 49-55, 2018. IJCAI
- [Auletta et al., 2019] Vincenzo Auletta, Angelo Fanelli, and Diodato Ferraioli. Consensus in opinion formation pro- cesses in fully evolving environments. In Proceedings of the AAAI Conference on Artificial Intelligence, volume 33, pages 6022-6029, 2019.
- [Bharathi et al., 2007] Shishir Bharathi, David Kempe, and Mahyar Salek. Competitive influence maximization in so- cial networks. In Internet and Network Economics: Third International Workshop, pages 306-311. Springer, 2007.
- [Bredereck and Elkind, 2017] Robert Bredereck and Edith Elkind. Manipulating opinion diffusion in social networks. In IJCAI International Joint Conference on Artificial Intel- ligence. International Joint Conferences on Artificial Intel- ligence, 2017. IJCAI
- [Bredereck et al., 2021] Robert Bredereck, Lilian Jacobs, and Leon Kellerhals. Maximizing the spread of an opin- ion in few steps: opinion diffusion in non-binary networks. In Proceedings of the Twenty-Ninth International Confer- ence on International Joint Conferences on Artificial In- telligence, pages 1622-1628, 2021. IJCAI
- [Brill et al., 2016] Markus Brill, Edith Elkind, Ulle Endriss, and Umberto Grandi. Pairwise diffusion of preference rankings in social networks. In International Joint Con- ference on Artificial Intelligence (IJCAI 2016), pages 130- 136, 2016. IJCAI
- [Centeno et al., 2011] Carmen C Centeno, Mitre C Dourado, Lucia Draque Penso, Dieter Rautenbach, and Jayme L Szwarcfiter. Irreversible conversion of graphs. Theoret- ical Computer Science, 412(29):3693-3700, 2011.
- [Chen, 2009] Ning Chen. On the approximability of influ- ence in social networks. SIAM Journal on Discrete Math- ematics, 23(3):1400-1415, 2009.
- [Chistikov et al., 2020] Dmitry Chistikov, Grzegorz Lisowski, Mike Paterson, and Paolo Turrini. Con- vergence of opinion diffusion is pspace-complete. In Proceedings of the AAAI Conference on Artificial Intelligence, volume 34, pages 7103-7110, 2020.
- [Even-Dar and Shapira, 2007] Eyal Even-Dar and Asaf Shapira. A note on maximizing the spread of influence in social networks. In Internet and Network Economics: Third International Workshop, pages 281-286. Springer, 2007.
- [Fagen and Lehrer, 1958] R. E. Fagen and T. A. Lehrer. Ran- dom walks with restraining barrier as applied to the biased binary counter. Journal of the Society for Industrial and Applied Mathematics, 6(1):1-14, 1958.
- [Faliszewski et al., 2022] Piotr Faliszewski, Rica Gonen, Martin Kouteckỳ, and Nimrod Talmon. Opinion diffusion and campaigning on society graphs. Journal of Logic and Computation, 32(6):1162-1194, 2022. IJCAI
- [Frischknecht et al., 2013] Silvio Frischknecht, Barbara Keller, and Roger Wattenhofer. Convergence in (social) influence networks. In Distributed Computing: 27th International Symposium, DISC 2013, Jerusalem, Israel, October 14-18, 2013. Proceedings 27, pages 433-446. Springer, 2013.
- [Gauy et al., 2025] Marcelo Matheus Gauy, Anna Abramishvili, Eduardo Colli, Tiago Madeira, Fred- erik Mallmann-Trenn, Vinícius Franco Vasconcelos, and David Kohan Marzagão. Voter model meets rumour spreading: A study of consensus protocols on graphs with agnostic nodes [extended version], 2025.
- [Hassin and Peleg, 1999] Yehuda Hassin and David Peleg. Distributed probabilistic polling and applications to pro- portionate agreement. In Jirí Wiedermann, Peter van Emde Boas, and Mogens Nielsen, editors, Automata, Lan- guages and Programming, pages 402-411, Berlin, Heidel- berg, 1999. Springer Berlin Heidelberg.
- [Kempe et al., 2003] David Kempe, Jon Kleinberg, and Éva Tardos. Maximizing the spread of influence through a so- cial network. In Proceedings of the ninth ACM SIGKDD international conference on Knowledge discovery and data mining, pages 137-146, 2003.
- [Khuller et al., 1999] Samir Khuller, Anna Moss, and Joseph Seffi Naor. The budgeted maximum coverage prob- lem. Information processing letters, 70(1):39-45, 1999.
- [Lesfari et al., 2022] Hicham Lesfari, Frédéric Giroire, and Stéphane Pérennes. Biased majority opinion dynam- ics: Exploiting graph k-domination. In IJCAI 2022- International Joint Conference on Artificial Intelligence, 2022. IJCAI
- [Leskovec and Krevl, 2014] Jure Leskovec and Andrej Krevl. SNAP Datasets: Stanford large network dataset collection. http://snap.stanford.edu/data, June 2014. Link
- [Li et al., 2018] Yuchen Li, Ju Fan, Yanhao Wang, and Kian- Lee Tan. Influence maximization on social graphs: A sur- vey. IEEE Transactions on Knowledge and Data Engi- neering, 30(10):1852-1872, 2018.
- [Lin and Lui, 2015] Yishi Lin and John CS Lui. Analyzing competitive influence maximization problems with partial information: An approximation algorithmic framework. Performance Evaluation, 91:187-204, 2015.
- [Lu et al., 2015] Wei Lu, Wei Chen, and Laks VS Laksh- manan. From competition to complementarity: Compara- tive influence diffusion and maximization. Proceedings of the VLDB Endowment, 9(2), 2015.
- [Manohara and Zehmakan, 2024] Abhiram Manohara and Ahad N. Zehmakan. A generalisation of voter model: In- fluential nodes and convergence properties, 2024.
- [Myers and Leskovec, 2012] Seth A Myers and Jure Leskovec. Clash of the contagions: Cooperation and competition in information diffusion. In 2012 IEEE 12th international conference on data mining, pages 539-548. IEEE, 2012.
- [Nemhauser et al., 1978] George L Nemhauser, Laurence A Wolsey, and Marshall L Fisher. An analysis of approxima- tions for maximizing submodular set functions-i. Math- ematical programming, 14:265-294, 1978.
- [Noorazar, 2020] Hossein Noorazar. Recent advances in opinion propagation dynamics: A 2020 survey. The Eu- ropean Physical Journal Plus, 135:1-20, 2020.
- [Petsinis et al., 2023] Petros Petsinis, Andreas Pavlogiannis, and Panagiotis Karras. Maximizing the probability of fix- ation in the positional voter model. In Proceedings of the AAAI Conference on Artificial Intelligence, volume 37, pages 12269-12277, 2023.
- [Poljak and Turzík, 1986] Svatopluk Poljak and Daniel Turzík. On pre-periods of discrete influence systems. Discrete Applied Mathematics, 13(1):33-39, 1986.
- [Wilczynski, 2019] Anaëlle Wilczynski. Poll-confident vot- ers in iterative voting. In Proceedings of the AAAI Con- ference on Artificial Intelligence, volume 33, pages 2205- 2212, 2019.
- [Zehmakan et al., 2024] Ahad N Zehmakan, Xiaotian Zhou, and Zhongzhi Zhang. Viral marketing in social networks with competing products. In Proceedings of the 23rd In- ternational Conference on Autonomous Agents and Multi- agent Systems, pages 2047-2056, 2024.
- [Zehmakan, 2024] Ahad N Zehmakan. Majority opinion diffusion: when tie-breaking rule matters. Autonomous Agents and Multi-Agent Systems, 38(1):21, 2024.
References were extracted automatically from the PDF and may contain errors.
Full text extracted automatically from the PDF; figures, tables and equations may differ. The PDF is the version of record.
1 Introduction
Humans constantly form and update their opinions on different topics, from minor subjects such as which movie to watch and which new caf´e to try to major matters such as which political party to vote for and which company to invest in. In the process of making such decisions, we tend to rely not only on our own personal judgement and knowledge, but also that of others, especially those whose opinion we value and trust. As a result, opinion diffusion and influence propagation can affect different aspects of our lives, from economy and defence to fashion and personal affairs.
Recent years have witnessed a booming development of online social networking platforms like Facebook, WeChat, and Instagram. The enormous popularity of these platforms has led to fundamental changes in how humans share and form opinions. Social phenomena such as disagreement and polarisation that have existed in human societies for millennia, are now taking place in an online virtual world and are tightly woven into everyday life, with a substantial impact on society. As a result, there has been a growing demand for a quantitative understanding of how opinions form and diffuse because of the existence of social ties among a community's members. Within the field of computer science, especially computational social choice, there has been a rising interest in developing and analysing mathematical models which simulate the opinion diffusion in a network of individuals, cf. [Bredereck and Elkind, 2017; Faliszewski et al., 2022; Bredereck et al., 2021].
A very popular opinion diffusion model is the Voter Model (VM) [ [Hassin and Peleg, 1999]]. Consider a social network G, where each node (user) is either blue or red. In each round, every node picks a neighbour at random and adopts its colour. Red and blue can, for example, represent a positive/negative opinion about a topic/product. This captures the setup where switching colours is free or inexpensive; for example, changing opinions about a controversial topic or switching from one grocery store chain to another.
First Contribution: Model Generalisation. Despite being simple and intuitive, VM has some fundamental shortcomings. Firstly, it assumes the underlying graph is undirected and unweighted. We allow the graph to be directed (modelling one-directional relations such as following in Instagram) and weighted (modelling the strengths of the relationships). Self loops indicate inertia against changing their opinion, thus modelling situations where switching is expensive. Secondly, unlike VM, our model permits for users which have no initial opinion (uncoloured nodes) who can then gain an opinion through interaction. Thirdly, our model considers the users who may be stubborn and don't update their opinions as a result of interaction with their neighbours.
Second Contribution: Adoption Maximisation. In viral marketing, one aims to convince a subset of users to adopt a positive opinion about a product (i.e., become blue) with the goal that this results in a further adoption of blue colour by many other users later in the propagation process. Motivated by this application, we study the optimisation problem of maximising the expected number of blue nodes after some rounds by selecting a fixed number of initial blue nodes. We prove that the problem cannot be approximated better than (1-1/e), unless a fundamental complexity hypothesis is violated. While the proof uses a classical reduction construction from the Maximum Coverage problem, the main difficulty that we need to overcome using novel techniques, is handling the randomness involved in the process. We believe some of the tools developed can be of interest to a wider set of problems. We then provide a polynomial time algorithm with such approximation ratio. While the algorithm follows a simple greedy approach, the proof of submodularity and polynomial calculation of the objective function require novel techniques from graph theory and linear algebra. Furthermore, our experiments on different real-world graph data demonstrate that our proposed algorithm outperforms other methods.
Third Contribution: Convergence Properties. How long does it take for our model to converge in expectation (the convergence time) and how many states/colouring are in a converged configuration (convergence period)? (Please see Section 2 for formal definitions.) Leveraging techniques from Markov chain analysis and combinatorics, we prove that both convergence time and period can be exponential in the general case. However, we provide polynomial bounds for special classes of graphs, such as strongly connected graphs, in terms of the number of nodes and the highest common divisor of cycle lengths in the graph.
2 Preliminaries
Graph Definitions. A weighted directed graph G is an ordered triple (V,E, ω) where elements of V are nodes and E ⊂ V ×V is a set of ordered pairs of nodes called edges and ω : E → R+ is a function that assigns a positive weight to each edge. We define n := |V | and m := |E|. For two nodes v1, v2 ∈ V , we say v1 is an in-neighbour of v2 (and v2 is an out-neighbour of v1) when (v1, v2) ∈ E. Furthermore, we say there is an edge from v1 to v2. Let N+(v1) := {v ∈ V : (v1, v) ∈ E} and N-(v1) := {v ∈ V : (v, v1) ∈ E} be the set of out-neighbours and in-neighbours of v1 respectively and d+(v1) := |N+(v1)| and d-(v1) := |N-(v1)| be the out degree and in degree. Graph G is said to be normalised if ∑u∈N+(v) ω((v, u)) = 1 for every node v ∈ V .
A path is a list of distinct nodes P = p0, p1, p2, ..., pl for 0 ≤ l < n such that (pi, pi+1) ∈ E for any 0 ≤ i < l. The length of a path l is the number of edges in the path. For any two nodes S, T ⊂ V , an S-T path (or a path from S to T) is a path P such that S ∩ P = {p0} and T ∩ P = {pl}. A graph is strongly connected if for any two nodes v1, v2 ∈ V , there exists a path from v1 to v2. The distance µ(v1, v2) is the length of the shortest path from v1 to v2. The diameter of a graph is the largest distance between any two nodes.
Model Definitions. A colouring is a function S : V → {r, b, u} where r stands for red, b for blue and u for uncoloured (a node who hasn't adopted an opinion yet). We say a node is coloured if it is not uncoloured (i.e., is either blue or red). Define BS+(v) to be the nodes in N+(v) which are blue in S. We write B+(v) when S is clear from the context.
We also introduce the notion of stubbornness, where some nodes are fixed on their opinion and not willing to change it. The following definition makes it clear that we capture this notion through nodes with out degree 0.
Definition 1 (Generalised Voter Model). In the GENERALISED VOTER MODEL (GVM) on a graph G = (V,E, ω) and an initial colouring S0, nodes update their colour simultaneously. In each discrete-time round t, let the colouring be St. St+1 is decided node-wise as follows: each node v picks an out-neighbour proportional to the weight of the edge to that node and adopts that colour if it is red or blue. If it is uncoloured or if v has no out-neighbours v retains its colour. Say v picks some w ∈ N+(v); then, St+1(v) = St(w) if St(w) ̸= u, and St+1(v) = St(v), otherwise.
The nodes with no out-neighbours will retain their initial colour after each round, emulating stubbornness (or loyalty). Note that under our model, uncoloured represents nodes who are yet to be introduced to either idea. A stubborn uncoloured node represents someone who has no opinion and refuses to get one. In the setting of elections, it may be someone who dislikes politics and will abstain from voting.
If a node v was not already blue in round t, the probability of turning blue in round t + 1 is the probability of picking a blue neighbour. Since the choice of neighbour is determined by the weights, this comes to be (∑u∈BSt + (v) ω((v, u)))/(∑u∈N+(v) ω((v, u))). If St(v) = b, we have to add the probability of picking an uncoloured neighbour since in that case v remains blue. A similar argument applies to red and uncoloured case. Note that if we normalise the graph by dividing the weight of each outgoing edge for a node v by ∑u∈N+(v) ω((v, u)), the probabilities of picking each neighbour is not affected and hence our model is not affected. Furthermore, if ω′ given by ω′ ((v,w)) := ω((v,w))/(∑u∈N+(v) ω((v, u))) for all (v,w) ∈ E are the normalised weights, the probability of picking a neighbour is the weight of the edge to that neighbour. For example, the aforementioned probability can be rewritten as ∑u∈BSt + (v) ω′ ((v, u)). Going forward, we will assume that all graphs are normalised.
Our model reduces to the original VM [Hassin and Peleg, 1999], when there are no stubborn nodes, the graph is unweighted and undirected, and all nodes are either blue or red (no uncoloured nodes).
Since this is a probabilistic process, at each time t > 0, node v has a probability of being in each colour. Thus, by misusing the notation, we represent St(v) as a vector of length 3 indicating probability of being coloured r, b, and u at time t, when it's clear from the context. Further, assuming an ordering of the nodes, we represent St itself as a n×3 matrix where each row is the vector for one node. For 1 ≤ i ≤ n and c ∈ {r, b, u}, we shall use St(vi, c) to refer to the probability of vi having colour c at time t.
Adoption Maximisation. Now, we are ready to introduce our viral marketing problem.
Definition 2 (Adoption Maximisation (AM) Problem). Let Ω = (G = (V, E, ω), S) be a system. For A ⊂ V define ΩA to be (G, S′ ) where S′ is given by S′ (v) = b for v ∈ A and S′ (v) = S(v) for v ∈ V \ A and Fτ (A) = ∑v∈V SΩA τ (v, b) is the expected number of blue nodes at time τ. For a system
Ω, a time τ and a budget k the AM problem is to find
Convergence Properties. Our model corresponds to a Markov chain, where the states correspond to all possible 3n colourings and there is an edge from one state to another if there is a non-zero transition probability. Consider the directed graph of the Markov chain with the node (state) set S. A strongly connected component is a maximal node set such the subgraph induced by the node set is strongly connected. The node set S can be partitioned to strongly connected components. On contracting these components to single nodes, we get the component graph CG of the graph. CG then has a topological ordering. The absorbing strongly connected components are the components that correspond to nodes with out degree 0 in CG and we shall call them the leaves of the graph. The process is said to converge when it enters one of the leaves of CG. The number of rounds the process needs to enter a leaf is the convergence time and the size of the leaf component (number of states) is the period of convergence.
3 RelatedWork
Models. Numerous opinion diffusion models have been developed to understand how members of a community form and update their opinions through social interactions with their peers, cf. [Noorazar, 2020; Brill et al., 2016; Wilczynski, 2019]. As mentioned, our main focus is on the generalisation of Voter Model, which was introduced originally in [Hassin and Peleg, 1999], and has been studied extensively afterwards, cf. [Petsinis et al., 2023] [Gauy et al., 2025].
We first give a short overview of some of the most popular opinion diffusion models. The Independent Cascade (IC) model, popularised by the seminal work of [Kempe et al., 2003], has obtained substantial attention to simulate viral marketing, cf. [Li et al., 2018]. In this model, initially each node is uncoloured (inactive), except a set of seed nodes which are coloured (active). Once a node is coloured, it gets one chance to colour each of its out-neighbours. Different extensions of the IC model have been introduced, cf. [Lin and Lui, 2015; Myers and Leskovec, 2012]. The IC model aims to simulate the spread of influence or the adoption of novel technology (with no competitor). In the Threshold model, each node v has a threshold τ (v). From a starting state, where each node is either coloured or uncoloured, an uncoloured node becomes coloured once τ(v) fraction of its out-neighbours are coloured. In the Majority model. cf. [Chistikov et al., 2020; Zehmakan, 2024], in every round each node updates its colour to the most frequent colour in its out-neighbourhood. Unlike the IC or Threshold model, here a node can switch back and forth between red and blue (similar to ours).
Adoption Maximisation. For various models, the problem of finding a seed set of size k which maximises the expected number of nodes coloured with a certain colour after some rounds have been studied extensively. This problem is proven to be NP-hard in most scenarios, and thus the previous works have resorted to approximation algorithms for general case (see [Lu et al., 2015]) or exact algorithms for special cases (see [Bharathi et al., 2007]). For example, for the Threshold model, the problem cannot be approximated within the ratio of O(2log1-ϵ n ), for any constant ϵ > 0, unless NP ⊆ DTIME(npolylog(n) ) [Chen, 2009]. However, the problem is traceable for trees [Centeno et al., 2011] and there is a (1 - 1/e)-approximation algorithm for the Linear Threshold (LT) model, where the threshold τ(v) is chosen uniformly at random in [0, 1], cf. [Kempe et al., 2003].
For the Voter Model, it was proven that the final fraction of blue nodes is equal to the summation of the degree of all initially blue nodes divided by the summation of all degrees [Hassin and Peleg, 1999]. Thus, a simple algorithm which picks the nodes with the highest degree solves the problem in polynomial time. However, as we will prove, the problem is computationally much harder in our more general setup. The problem also has been proven to be NP-hard, by [Even-Dar and Shapira, 2007], when each node has a cost and the goal is to maximise the expected number of blue nodes in round τ of the Voter Model for a given cost.
Convergence Properties. The convergence time is arguably one of the most well-studied characteristic of dynamic processes, cf. [Auletta et al., 2018; Auletta et al., 2019]. For the Majority model on undirected graphs, it is proven by [Poljak and Turz´ık, 1986] that the process converges in O(n2 ) rounds (which is tight up to some poly-logarithmic factor [Frischknecht et al., 2013]). The convergence properties have also been studied for directed acyclic graphs [Chistikov et al., 2020] and when the updating rule is biased [Lesfari et al., 2022]. It has recently also been studied for general directed graphs under the voter model [[Gauy et al., 2025]]. For the Voter Model, an upper bound of O(n3 log n) has been proven in [Hassin and Peleg, 1999] using reversible Markov chain argument. [Abdullah and Draief, 2015] considered a model similar to the Voter Model with two alternatives, where in each round every node picks k of its neighbours at random and adopts the majority colour among them. They proved that starting from a random initial colouring, the process converges in O(logk logk n) rounds in expectation.
4 MaximumAdoption Problem
4.1 Innaproximability
Theorem 4.1. There is no polynomial time (1 - 1e + ϵ)-approximation algorithm (for any constant ϵ > 0) for the Adoption Maximisation problem, unless NP ⊆ DT IME(nO(log log n) ).
Proof Sketch. (The detailed proof is presented in the full version of this paper, available at [Manohara and Zehmakan, 2024].) We will prove this by reducing any instance of the Maximum Coverage problem (cf. [Khuller et al., 1999]) to an instance of the Adoption Maximisation Problem. Consider an instance of the Maximum Coverage problem. Let O = {O1, O2, · · · Om} be the set and S = {S1, S2, · · · Sl} be the collection of subsets of O. We need to find A ⊂ S of size k that maximises ⋃S∈A S. If k = 0, the answer is 0. If k ≥ l we just pick all the subsets and if ∃ O /∈ ⋃S∈S S, it can't be covered, so we can safely ignore it. Thus, assume 0 < k < l (this implies that l ≥ 2 since k is an integer) and ⋃S∈S S = O. If k ≥ m, there is a solution of size m since for each object, we can pick a subset which includes it. So assume k < m. A similar argument yields that the optimal value is at least k.
Now consider node sets VO := {o1, · · · om} and VS := {s1, · · · sl}. Add edges (oi, sj) if and only if Oi ∈ Sj. Additionally, for each 1 ≤ j ≤ m, we introduce d = max(⌈ 1ϵ ⌉ ,m) more nodes o1j , · · · odj , and edges (o1j , oj), · · · (odj , oj). All edges have weight 1 (before normalisation) and all nodes are initially uncoloured. We also set τ = ld + 1. This completes the construction of an instance of our problem from the Maximum Coverage problem. (We also observe that (1 - 1e + ϵ) must be at most 1. Thus, ϵ < 1e and ⌈ 1ϵ ⌉ ≥ 2.)
Lemma 4.2. For the above choices of parameters, the following inequalities hold:
Lemma 4.3. Let A′ be a solution to the instance of our problem such that A′ ̸⊂ VS, then there is a strictly better solution A such that A ⊂ VS .
The above lemma implies that any solution A′ ̸⊂ VS can be improved (in fact, in linear time, as discussed in the proof) to a strictly better solution which has only nodes from VS. Particularly, the optimal solution picks only nodes from VS. In the following, we use this lemma to focus on the solutions where the seed set A is a subset of VS.
Let am be the value of a solution A ⊂ VS of size k in our problem and mc be the corresponding value for the Maximum Coverage problem, where set Sj is picked if and only if sj ∈ A. We establish a connection between am and mc. Firstly, it's trivial that am ≤ k + mc + d mc since by our construction at most k + mc + d mc nodes are made blue by A, regardless of τ. Secondly, exactly mc nodes v in VO satisfy |N+(v) ∩ A| ̸= 0. Then, k nodes are blue with probability 1, mc nodes are blue with probability at least 1 - (1- 1l )τ and d mc nodes are blue with probability at least 1 - (1- 1l )τ-1 . By linearity, we have k + mc (1 - (1 - 1l )τ ) + d mc (1 - (1 - 1l )τ-1) ≤ am. Using the two aforementioned inequalities and some simple calculations, we can establish a connection between am and
mc, as presented in the lemma below.
Lemma 4.4.
We'll need one last result before we prove the theorem.
Lemma 4.5. Suppose A ⊂ VS gives the optimal solution for the Adoption Maximisation problem, then the corresponding set {Sj : sj ∈ A} is an optimal solution for the Maximum Coverage problem.
Consider a polynomial time algorithm ALGAM with approximation ratio of (1 - 1e + ϵ) for the Adoption Maximisation problem and some ϵ > 0. Then, we design an algorithm ALGMC which transforms a given instance of the Maximum Coverage problem to an instance of the Adoption Maximization following our polynomial time construction, runs ALGAM on this construction, and translates the outcome to a solution of the Maximum Coverage as explained above. We claim that ALGMC has an approximation ratio better than 1 - 1e , which we know to not be possible unless NP ⊆ DTIME(nO(log logn) ), cf. [Khuller et al., 1999]. Thus, it remains to prove this claim.
Let AM be the solution produced by ALGAM and MC be the solution produced by ALGMC as described above. Also, let AM and MC denote the optimal solutions. We then can use Lemma 4.4 to connect the values of AM and MC, and additionally Lemmas 4.3 and 4.5 to establish the connection between AM and MC. Leveraging these two connections and some small calculations (please see the full version for omitted calculations in the rest of the proof), we get
Furthermore, by using the inequalities in Lemma 4.2 and some calculations, we get
Finally, by applying Equation (2) and the fact that the LHS of Equation (2) is positive according to Lemma 4.2 (B), we can show that the RHS of Equation (1) is larger than (1 - 1/e)MC. Thus, we can conclude that MC > (1 - 1e ) MC, that is, the polynomial time algorithm ALGMC has an approximation ratio better than 1 - 1/e. □
4.2 Greedy Algorithm
In this section, we provide a greedy algorithm whose approximation ratio matches the lower bound proven in the previous section and runs in polynomial time when τ = poly(n). Let us start by proving some properties of the objective function Ft(A).
Theorem 4.6. Ft(A) is monotone and submodular.
Proof. To prove this, we will introduce the notation of pick sequence, inspired by [Zehmakan et al., 2024].
Definition 3 (Pick Sequence). A pick sequence of length τ is a function PSτ : V × [1, τ] ∩ N → V where PSτ(v, t) is the node that node v picks at round t. Rτ is the set of all pick sequences of length τ.
Let Pr[PSτ ] be the probability that the picks made by the nodes in the first τ rounds follow the pick sequence PSτ . For A ⊂ V let BPSτ (A) and F PSτ τ (A) = |BPSτ (A)| be the set of blue nodes and the number of blue nodes at time τ for the systemΩA if the pick sequence PSτ is followed. Then,
Since monotonicity and submodularity are preserved under linear combinations, it suffices to show that for each PSτ , F P Sτ τ is monotone and submodular.
Definition 4 (Node Sequence). For a pick sequence PSτ and each time 0 ≤ t ≤ τ , the node sequence up to t is the function γt : V → V 2t defined recursively by γ0(v) = v ∀ v ∈ V and γt(v) = γt-1(PSτ(v, t))||γt-1(v) where || stands for concatenation.
The node sequence captures the idea of tracking the neighbouring node selected in each round and the nodes selected by the neighbouring node in previous rounds to get the colour of the node at round t. The following lemma formalises this idea. Its proof follow a simple inductive argument detailed in the full version.
Lemma 4.7. The colour of a node at time t is the time 0 colour of the first coloured node in its node sequence. A node is uncoloured if all the nodes in its node sequence were initially uncoloured.
To prove monotonicity, consider A ⊂ A′ ⊂ V . For any node v, if v ∈ BPSτ (A), then there is some node u in γτ (v) that is blue, and all nodes before it are uncoloured. Then, either u ∈ A or u is blue in Ω and all nodes before u are uncoloured in Ω and not in A. Since A ⊂ A′ , u ∈ A′ so u is blue in ΩA′ and all nodes before u are either in A′ in which case they are blue in ΩA′ or not in A′ in which case they are uncoloured in ΩA′ . Thus, there exists a coloured node in γτ(v) according to ΩA′ and the first coloured node is blue. Thus, v ∈ BPSτ (A′ ). Since v was arbitrary, BPSτ (A) ⊂ BPSτ (A′ ) and in particular, F PSτ τ (A) ≤ F PSτ τ (A′ ).
For submodularity, consider A ⊂ A′ ⊂ V and any node w. By our previous result, BPSτ (A) ⊆ BPSτ (A′ ), BPSτ (A ∪ {w}), and BPSτ (A′ ∪ {w}). Consider a node v ∈ BPSτ (A′ ∪ {w}) \ BPSτ (A). We claim that it is in at least one of BPSτ (A ∪ {w}) or BPSτ (A′ ). To see this, consider γτ(v). There is some u which is blue in ΩA′∪{w} and all nodes before it are uncoloured. u is either in A′ ∪ {w} or it is blue in Ω. All nodes before it are not in A′ ∪ {w} and are uncoloured in Ω. If u is blue in Ω, then all nodes until u are not in A since A ⊂ A′ ∪ {w} and the first uncoloured node in γτ(v) is blue, so v ∈ BPSτ (A) contradicting our assumption. Hence, u ∈ A′ ∪ {w}. Since A′ ∪ {w} = A′ ∪ (A ∪ {w}), u is in one of A ∪ {w} or A′ . All nodes before u are in neither since they are both subsets of A′ ∪ {w}. Thus, v belongs to one of BPSτ τ (A ∪ {w}) or BP Sτ τ (A′ ). By our assumption, it isn't inBPSτ (A). So it's in one of BPSτ τ (A∪{w})\BPSτ (A) or BPSτ (A′ )\BPSτ (A). Because v was arbitrary, BPSτ (A′ ∪ {w}) \ BPSτ (A) ⊂ (BPSτ (A′ ) \ BPSτ (A) ∪ BPSτ (A ∪ {w}) \ BPSτ (A)). Since by our monotonicity result, BPSτ (A) is a subset of all the other 3, we get F PSτ τ (A′ ∪ {w}) - F PSτ τ (A) ≤ (F P Sτ τ (A′ ) -F PSτ τ (A)) + (F PSτ τ (A∪ {w}) -F PSτ τ (A)).
Rearranging, we get F PSτ τ (A′ ∪ {w}) - F PSτ τ (A′ ) ≤ F P Sτ τ (A ∪ {w}) - F PSτ τ (A), thus proving submodularity. This concludes the proof of the theorem □
Computing Objective Function. Before discussing the greedy algorithm, we need to explain how to compute Fτ (A) for a set A. The idea of fixing picks was good for theory, but since the number of pick sequences grows exponentially in time, it very quickly becomes impractical to compute. We instead bring back the notion of probability vector St. We can then calculate the probability of picking colour blue at round t as Pt(v, b) = ∑w∈N+(v) ω(v, w)St-1(w, b) and analogously for red and uncoloured. This is just the dot product of the row vector of v in the (normalised) adjacency matrix H of the graph and the blue column of St-1. Thus, we can obtain the colour distribution probability for all the nodes as Pt = H × St-1 where row i of Pt is the triple Pt(vi, b), Pt(vi, r), Pt(vi, u) in round t. Since the picking is independent across rounds, these probabilities are independent of St-1(v) and we can find St(v). For example, St(v, b) = St-1(v, b)(1-Pt(v, r))+(1-St-1(v, b))Pt(v, b). This concludes one round, and repeating this procedure τ times can give us Sτ , starting from ΩA. Then we can add the blue column of Sτ to get Fτ(A). Multiplying an n × n matrix with an n × 3 matrix can be done in O(n2 ) and calculating St from Pt can be done in O(n). Thus, one step of calculations costs O(n2 ). Doing this τ times to calculate Sτ costs O(n2 τ). Then, we can add the blue column in O(n). Thus, the overall cost of calculating Fτ (A) is O(n2 τ).
Proposed Algorithm. The greedy algorithm works by iteratively selecting and adding the node which gives the highest increase to the expected number of blue nodes in time τ. In each iteration, the algorithm needs to compute the value of Fτ(·) if each non-selected node was added to the seed set. Since there are at most n such nodes to be checked, we have k iterations overall, and computing Fτ(·) takes O(n2 τ) as discussed above, we can conclude that the run time of the algorithm is O(n3kτ ), which is polynomial when τ = poly(n). Furthermore, as the objective function is both monotone and submodular, the greedy algorithm achieves an approximation ratio of 1 - 1/e, cf. [Nemhauser et al., 1978].
4.3 Experimental Comparison
Data. We have used real-world social network data available on SNAP database [Leskovec and Krevl, 2014], including Facebook 0 (n = 347, m = 5, 038), Twitter (n = 475, m = 13, 289), Facebook 414 (n = 685, m = 3, 386), Wikipedia (n = 4, 592, m = 119, 882), Bitcoin OTC (n = 6, 005, m = 35, 592), Gnutella (n = 6, 300, m = 20, 777), and Bitcoin Alpha (n = 7, 604, m = 24, 186).
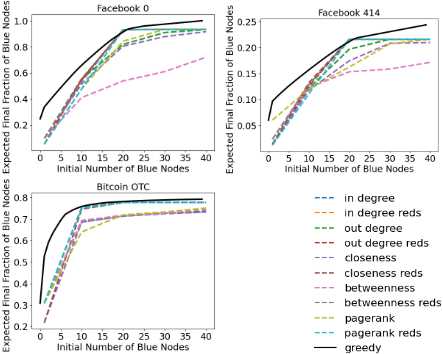
Comparison. We compare the performance of our proposed greedy algorithm against the following centrality-based methods, where we pick the nodes with: the highest in degree, highest out degree, highest closeness centrality, highest betweenness centrality, and highest (pagerank) centrality. A suffix of "red" to any of the strategies implies that the strategy prioritises converting the red nodes to blue, so selects the highest ranked red nodes.
We observe that our algorithm not only enjoys a theoretical guarantee (as proven in the previous section), but also outperforms other algorithms on real-world data. Please see Figure 1 for Facebook 0, Facebook 414, and Bitcoin OTC. The results for other networks are similar and are given in the full version.
5 Convergence Properties
So far, we let the number of rounds be an input parameter τ. But what kind of configurations does our model converge to, and how long does it take to reach convergence? In this section, we study the convergence period and convergence time of our process (please see Section 2 for their formal definition).
5.1 Convergence Period
We show that if G is strongly connected, the period is smaller than the HCF (highest common divisor) of the length of all cycles in G. However, the period can be exponential if strong connectivity condition is relaxed.
Strongly Connected Graphs
Theorem 5.1. Let the period γ of a graph be the HCF of the lengths of all its cycles. For a strongly connected graph G, the period of convergence divides γ.
Proof. First, we cover the case of γ = 1 in Lemma 5.2. (the proofs of lemmas in this proof are given in the full version). To prove this lemma, we show that there is a path from any non-monochromatic colouring to a monochromatic one. Then, any strongly connected component that does not contain a monochromatic colouring can't be absorbing. However, the monochromatic colourings have out degree 0, thus are singleton strongly connected components that are also absorbing, thus, these are the only absorbing strongly connected components of CG (please see Section 2 for the definition of CG). Thus, the period is 1. The proof uses a combinatorial argument, building on the Extended Euclidean algorithm.
Lemma 5.2. A system with a strongly connected aperiodic graph (γ = 1) will reach a consensus.
Let us now consider graphs of period γ ≥ 2. The period classes of a graph are the equivalence classes of V given by the relation u ∼ v ⇔ distance from u to v is a multiple of γ. Recall that µ(u, v) denotes the distance from u to v
Lemma 5.3. The relation u ∼ v ⇔ γ|µ(u, v) is an equivalence relation in a strongly connected graph with period γ.
To prove the above lemma, we show that all three properties reflexivity, symmetry, and transitivity hold following some standard techniques. Building on this lemma and establishing a connection between the above relation ∼ and a newly defined relation ∼v (with respect to an arbitrary node v), we provide the below lemma.
Lemma 5.4. The graph obtained by contracting the period classes to single nodes is a single directed cycle of length γ.
For a periodic graph with period γ, consider a period class Γ ⊂ V . Define the graph GΓ with nodes Γ and edges (u, v) for u, v ∈ Γ if and only if there is a u-v path of length γ in G, with weight
where P γ (u,v) is the set of all u-v paths of length γ. The weight of an edge thus defined to be the probability of u adopting v's colour after γ rounds. Then, one round in GΓ exactly depicts the set Γ after γ rounds in the process on G.
Lemma 5.5. The graph GΓ defined above is strongly connected and aperiodic.
Then, by Lemma 5.2, Γ reaches a consensus. So each period class will be monochromatic. Then, γ rounds later, they will have the same colour again, adopting the consensus of the previous period class at each round. So the period of convergence divides γ.
General Graphs
For a strongly connected graph G, we provided the upper bound of γ ≤ n, but there is no such bound in the general case. In particular, there is a family of graphs for which the period of convergence is as big as 2n-2 , which is exponential.
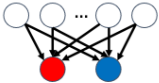
Consider nodes 1 to n with edges (i, 1) and (i, 2) of weight 0.5 each for 3 ≤ i ≤ n. Initially colour node 1 blue, node 2 red, and the rest uncoloured. Please see Figure 2 (left). Nodes 1 and 2 will keep their colour unchanged forever, since they have out degree 0 (i.e., are stubborn). On the other hand, all nodes from 3 to n will switch between blue and red independently in each round. In the Markov chain, there is an edge from every state S with S(1) = b, S(2) = r to every other such state and no edges to any other state. Thus, this is an absorbing strongly connected component of size 2n-2 . This implies that the period of convergence in this setup is at least 2n-2
5.2 Convergence Time
If G is strongly connected, we provide a polynomial upper bound on the convergence time, but in the general case the convergence time can be exponentially large.
Strongly Connected Graphs
For strongly connected graphs of period γ (the HCF of the length of all cycles), the number of rounds required for all uncoloured nodes to be coloured is in O(n2 log(n)), following a proof from [Zehmakan et al., 2024]. How long does it take for the process to converge after all nodes are coloured? Similar to our proof of Theorem 5.1, we consider individual period classes Γi, |Γi| = ni, ∑i ni = n and their derived graphs GΓi . The derived graph is strongly connected and aperiodic, which means that it converges in O(n3i log(ni)), following the proof from [Hassin and Peleg, 1999]. By our construction, each round in this graph is γ rounds in the original graph. The period class Γi is expected to converge in O(γn3i log(ni)). There are γ such classes, which converge independently. The system is said to converge when all classes have converged. So we need the maximum of all their convergence times. Since the convergence time is a positive random variable, we can upper bound the maximum convergence time by the sum of all convergence times. Then, by linearity of expectation, the expected convergence time is O(∑i γn3i log(ni)). Since f(x) = x3 log(x) is convex, ∑i f(ni) ≤ f(∑i ni) for positive ni. Also, remember ∑i ni = n. So the expected stopping time is O(γn3 log(n)).
General Graphs
Consider the graph G on n nodes v1 · · · vn with edges (vi+1, vi) for every 1 ≤ i ≤ n - 1 and (vi, vj) for 2 ≤ i < j ≤ n where the first node is stubborn and blue, and all the other nodes are initially red. All edges are of weight 1 before normalisation. Please see Figure 2 (right) for an example.
It is straightforward to observe that this process eventually converges to a fully blue colouring, where all nodes are blue. Thus, the convergence time is the number of rounds the process needs to reach such a colouring. We establish a connection between our process and so-called Gambler's ruin with a soft hearted adversary process [Fagen and Lehrer, 1958], which then allows us to bound the convergence time.
We observe that the first time a node turns blue has to be by picking the previous node when it was blue, since no node after it can be blue without it having been blue. Furthermore, if every node after some v turns red at any point, then v can again only become blue by picking the previous node after that node turns blue. Let us consider the sequence X(t) = maxSt(vi)=b i. We know that for the whole graph to turn blue at round t, we must have X(t) = n. And for the n-th node to turn blue, we need the n2 -th node to turn blue. Thus, a lower bound on t for which X(t) = n/2 gives us a lower bound on the convergence time.
By monotonicity, the expected time from any colouring St is at least the time from the colouring where the first X(t) nodes are blue. We use this to design a simpler process. Consider a Gambler's ruin set-up with n nodes where the state at time t is X(t). Thus, from a state i, it moves ahead when vi+1 picks vi. That is, with probability 1 n-i . For i ≤ n2 , this is < 2n . It stays in the same state when vi+1 doesn't pick vi, but vi picks vi-1. Since the events are independent, this happens with probability n-i-1 n-i· 1 n-i+1 . Again, for i ≤ n2 , this
is less than 4(n-2) n2 . Otherwise, state decreases. Again, we bound it by saying the state only decreases by 1, while the model can actually have all nodes pick the last node and go back to the initial state. In fact, let us be generous and say that if we didn't decrease, we will increase. Then, for the first n2 rounds, we have that the probability of moving ahead, p ≤ 2n + 4(n-2) n2 = 6n-8 n2 < 6n . Further, let us consider p = 6n and the probability of moving backwards, q = n-6 n .
Using the fact that we are interested in a lower bound, we could introduce the above, much simpler process, which is at least as fast as the original process. Thus, any lower bound on this process applies to our original convergence time. This simplified process corresponds to the Gambler's ruin studied in [Fagen and Lehrer, 1958] whose analysis gives us the bound of Ω(nn + n2 ), which is growing exponentially.
6 Conclusion
We studied a generalisation of the popular Voter Model, by extension to directed weighted graphs and the introduction of stubborn agents and agents with no initial opinion. We proved the Adoption Maximisation problem is computationally hard. However, we provided a polynomial time algorithm which not only has the best possible theoretical approximation guarantee but also outperforms other algorithms on realworld data. Furthermore, we gave bounds on the period of the process in terms of graph parameters such as number of nodes, and the highest common divisor of cycle lengths.
While our proposed algorithm is polynomial, it can't handle massive graphs appearing in the real-world. Can we design faster algorithms without significant sacrifice on accuracy? Furthermore, we proved that both convergence period and convergence time can be exponential in general graphs (with tighter bounds for special graphs). What about graphs appearing in the real world? We have done some foundational studies, reported in the full version, but a deeper study of this question is left for the future work. Finally, we have checked that our hardness and algorithmic findings, very easily extend to more setups such as (1) where the users in the selected seed set are loyal, that is, keep their colour unchanged, (2) when the goal is to optimise the average number of adoptions over the whole process rather than a fixed time τ. However, the convergence properties fall short in covering a wider collection of setups. Thus, it would be interesting to study convergence properties under various scenarios, especially for different agent types.
@inproceedings{ijcai2025p442,
  title     = {Viral Marketing and Convergence Properties in Generalised Voter Model},
  author    = {Manohara, Abhiram and N. Zehmakan, Ahad},
  booktitle = {Proceedings of the Thirty-Fourth International Joint Conference on
               Artificial Intelligence, {IJCAI-25}},
  publisher = {International Joint Conferences on Artificial Intelligence Organization},
  editor    = {James Kwok},
  pages     = {3970--3978},
  year      = {2025},
  month     = {8},
  note      = {Main Track},
  doi       = {10.24963/ijcai.2025/442},
  url       = {https://doi.org/10.24963/ijcai.2025/442},
}
TY - CPAPER TI - Viral Marketing and Convergence Properties in Generalised Voter Model AU - Manohara, Abhiram AU - N. Zehmakan, Ahad T2 - Proceedings of the Thirty-Fourth International Joint Conference on Artificial Intelligence, IJCAI-25 PB - International Joint Conferences on Artificial Intelligence Organization PY - 2025 SP - 3970 EP - 3978 DO - 10.24963/ijcai.2025/442 UR - https://doi.org/10.24963/ijcai.2025/442 ER -Copied
Machine-readable versions of this paper, for tools and AI agents:





