
Optimal Transport on Categorical Data for Conterfactuals Using Compositional Data and Dirichlet Transport
Proceedings of the Thirty-Fourth International Joint Conference on Artificial Intelligence. Main Track. Pages 5136-5144.
https://doi.org/10.24963/ijcai.2025/572
Keywords
- Uncertainty in AI: UAI: Causality, structural causal models and causal inference
- Machine Learning: ML: Causality
- AI Ethics, Trust, Fairness: ETF: Fairness and diversity
- Uncertainty in AI: UAI: Tractable probabilistic models
Abstract
Recently, optimal transport-based approaches have gained attention for deriving counterfactuals, e.g., to quantify algorithmic discrimination. However, in the general multivariate setting, these methods are often opaque and difficult to interpret. To address this, alternative methodologies have been proposed, using causal graphs combined with iterative quantile regressions or sequential transport to examine fairness at the individual level, often referred to as "counterfactual fairness." Despite these advancements, transporting categorical variables remains a significant challenge in practical applications with real datasets. In this paper, we propose a novel approach to address this issue. Our method involves (1) converting categorical variables into compositional data and (2) transporting these compositions within the probabilistic simplex of the Euclidean space. We demonstrate the applicability and effectiveness of this approach through an illustration on real-world data, and discuss limitations.
- [Aitchison, 1982] John Aitchison. The statistical analysis of compositional data. Journal of the Royal Statistical Soci- ety: Series B (Methodological), 44(2):139-160, 1982.
- [Baxendale and Wong, 2022] Peter Baxendale and Ting- Kam Leonard Wong. Random concave functions. The Annals of Applied Probability, 32(2):812-852, 2022.
- [Becker and Kohavi, 1996] Barry Becker and Ronny Ko- havi. Adult. UCI Machine Learning Repository, 1996.
- [Black et al., 2020] Emily Black, Samuel Yeom, and Matt Fredrikson. Fliptest: fairness testing via optimal trans- port. In Proceedings of the 2020 Conference on Fairness, Accountability, and Transparency, pages 111-121, 2020.
- [Brenier, 1991] Yann Brenier. Polar factorization and mono- tone rearrangement of vector-valued functions. Communi- cations on pure and applied mathematics, 44(4):375-417, 1991.
- [Brualdi, 2006] Richard A Brualdi. Combinatorial matrix classes, volume 13. Cambridge University Press, 2006.
- [Charpentier et al., 2023] Arthur Charpentier, Emmanuel Flachaire, and Ewen Gallic. Optimal transport for coun- terfactual estimation: A method for causal inference. In Optimal Transport Statistics for Economics and Related Topics, pages 45-89. Springer, 2023.
- [Chayes, 1971] Felix Chayes. Ratio correlation. University of Chicago Press, 1971.
- [Cheng et al., 2010] Weiwei Cheng, Eyke Hüllermeier, and Krzysztof J Dembczynski. Bayes optimal multilabel clas- sification via probabilistic classifier chains. In Proceedings of the 27th international conference on machine learning (ICML-10), pages 279-286, 2010.
- [De Lara et al., 2024] Lucas De Lara, Alberto González- Sanz, Nicholas Asher, Laurent Risser, and Jean-Michel Loubes. Transport-based counterfactual models. Journal of Machine Learning Research, 25(136):1-59, 2024.
- [Egozcue et al., 2003] Juan José Egozcue, Vera Pawlowsky- Glahn, Glòria Mateu-Figueras, and Carles Barcelo-Vidal. Isometric logratio transformations for compositional data analysis. Mathematical geology, 35(3):279-300, 2003.
- [Fernandes Machado et al., 2025] Agathe Fernan- des Machado, Arthur Charpentier, and Ewen Gallic. Sequential conditional transport on probabilistic graphs for interpretable counterfactual fairness. Proceedings of the AAAI Conference on Artificial Intelligence, 39(18):19358-19366, Apr. 2025.
- [Hallin and Konen, 2024] Marc Hallin and Dimitri Ko- nen. Multivariate quantiles: Geometric and measure- transportation-based contours. In Applications of Optimal Transport to Economics and Related Topics, pages 61-78. Springer, 2024.
- [Hallin et al., 2021] Marc Hallin, Eustasio Del Barrio, Juan Cuesta-Albertos, and Carlos Matrán. Distribution and quantile functions, ranks and signs in dimension d: A measure transportation approach. The Annals of Statistics, 49(2):1139-1165, 2021.
- [Higham, 2008] Nicholas J Higham. Functions of matrices: theory and computation. SIAM, 2008.
- [Hofmann, 1994] H. Hofmann. German Credit Data. UCI Machine Learning Repository, 1994.
- [Imai et al., 2022] Kosuke Imai, Santiago Olivella, and Evan T.R. Rosenman. Addressing census data problems in race imputation via fully bayesian improved surname geocoding and name supplements. Science Advances, 8(49):eadc9824, 2022.
- [Kantorovich, 1942] Leonid V Kantorovich. On the translo- cation of masses. In Doklady Akademii Nauk USSR, vol- ume 37, pages 199-201, 1942.
- [King et al., 2004] Gary King, Martin A Tanner, and Ori Rosen. Ecological inference: New methodological strate- gies. Cambridge University Press, 2004.
- [Kusner et al., 2017] Matt J Kusner, Joshua Loftus, Chris Russell, and Ricardo Silva. Counterfactual fairness. In I. Guyon, U. V. Luxburg, S. Bengio, H. Wallach, R. Fer- gus, S. Vishwanathan, and R. Garnett, editors, Advances in Neural Information Processing Systems 30, pages 4066- 4076. NIPS, 2017.
- [McCann, 1997] Robert J McCann. A convexity princi- ple for interacting gases. Advances in mathematics, 128(1):153-179, 1997.
- [Monge, 1781] Gaspard Monge. Mémoire sur la théorie des déblais et des remblais. Histoire de l'Académie Royale des Sciences de Paris, 1781.
- [Naeini et al., 2015] Mahdi Pakdaman Naeini, Gregory Cooper, and Milos Hauskrecht. Obtaining well calibrated probabilities using bayesian binning. In Proceedings of the AAAI conference on artificial intelligence, volume 29, 2015.
- [Pal and Wong, 2016] Soumik Pal and Ting-Kam Leonard Wong. The geometry of relative arbitrage. Mathematics and Financial Economics, 10:263-293, 2016.
- [Pal and Wong, 2018] Soumik Pal and Ting-Kam Leonard Wong. Exponentially concave functions and a new infor- mation geometry. The Annals of probability, 46(2):1070- 1113, 2018.
- [Pal and Wong, 2020] Soumik Pal and Ting-Kam Leonard Wong. Multiplicative schrödinger problem and the dirich- let transport. Probability Theory and Related Fields, 178(1):613-654, 2020.
- [Pal, 2024] Soumik Pal. On the difference between entropic cost and the optimal transport cost. The Annals of Applied Probability, 34(1B):1003-1028, 2024.
- [Pawlowsky-Glahn and Egozcue, 2001] Vera Pawlowsky- Glahn and Juan José Egozcue. Geometric approach to statistical analysis on the simplex. Stochastic Envi- ronmental Research and Risk Assessment, 15:384-398, 2001.
- [Pearl, 2009] Judea Pearl. Causality. Cambridge university press, 2009.
- [Peyré et al., 2019] Gabriel Peyré, Marco Cuturi, et al. Com- putational optimal transport: With applications to data sci- ence. Foundations and Trends in Machine Learning, 11(5- 6):355-607, 2019.
- [Pistone and Shoaib, 2024] Giovanni Pistone and Muham- mad Shoaib. A unified approach to aitchison's, dually affine, and transport geometries of the probability simplex. Axioms, 13(12):823, 2024.
- [Plečko and Meinshausen, 2020] Drago Plečko and Nicolai Meinshausen. Fair data adaptation with quantile preserva- tion. Journal of Machine Learning Research, 21(242):1- 44, 2020.
- [Plečko et al., 2024] Drago Plečko, Nicolas Bennett, and Nicolai Meinshausen. Fairadapt: Causal reasoning for fair data preprocessing. Journal of Statistical Software, 110(4):1-35, 2024.
- [Santambrogio, 2015] Filippo Santambrogio. Optimal trans- port for applied mathematicians. Springer, 2015.
- [Villani, 2003] Cédric Villani. Topics in optimal transporta- tion, volume 58. American Mathematical Society, 2003.
- [Zadrozny and Elkan, 2001] Bianca Zadrozny and Charles Elkan. Obtaining calibrated probability estimates from de- cision trees and naive bayesian classifiers. In Proceedings of the Eighteenth International Conference on Machine Learning, ICML '01, page 609-616, San Francisco, CA, USA, 2001.
References were extracted automatically from the PDF and may contain errors.
Full text extracted automatically from the PDF; figures, tables and equations may differ. The PDF is the version of record.
1 Introduction
1.1 Counterfactuals
Counterfactual analysis, the third level in [Pearl, 2009]'s causal hierarchy, is widely used in machine learning, policy evaluation, economics and causal inference. It involves reasoning about "what could have happened" under alternative scenarios, providing insights into causality and decisionmaking effectiveness. An example could be the concept of counterfactual fairness, as introduced by [Kusner et al., 2017], that ensures fairness by evaluating how decisions would change under alternative, counterfactual conditions. Counterfactual fairness focuses on mitigating bias by ensuring that sensitive attributes, such as race, gender, or socioeconomic status, do not unfairly influence outcomes. 1
In the counterfactual problem, we consider data {(si, xi), i = 1, · · · , n}, where s denotes a binary "treatment" (taking values in {0, 1}). With generic notations, the counterfactual version of (0, x) can be constructed as
1 Extended Paper: https://arxiv.org/abs/2501.15549. Replication codes: https://github.com/fer-agathe/transport-simplex
(1, T ⋆ (x)), where T ⋆ is the optimal transport (OT) mapping from X|S = 0 to X|S = 1, as discussed in [Black et al., 2020], [Charpentier et al., 2023] and [De Lara et al., 2024]. Unfortunately, this multivariate mapping is usually both complicated to estimate, and hard to interpret. If x is univariate, it is simply a quantile interpretation: if x is associated to rank probability u within group s = 0, then its counterfactual version should be associated with the same rank probability in group s = 1 (mathematically, T ⋆ = F -1 1 ◦ F0, where Fj : R → [0, 1], j = {0, 1} denotes the cumulative distribution in group j, and F -1 j is the generalized inverse, i.e., the quantile function). In higher dimensions, one could consider multivariate quantiles, as in [Hallin et al., 2021] or [Hallin and Konen, 2024], but the heuristics is still hard to interpret. While OT-based counterfactual methods have been proposed to assess counterfactual fairness [Black et al., 2020; De Lara et al., 2024], an alternative approach introduced by [Pleˇcko and Meinshausen, 2020] is grounded in causal graphs (DAGs). In this framework, the outcome y depends on variables (s, x), where the sensitive attribute s "is a source" (a vertex without parents) and y is a "sink" (a vertex without outgoing edges). Recently, [Fernandes Machado et al., 2025] unified these approaches by introducing sequential transport aligned with the "topological ordering" of a DAG.
For example, to test whether a predictor ̂m(x) is genderneutral; let the sensitive attribute s be gender (binary genders for simplicity); compare its output on a woman's features x with that on her mutatis mutandis male counterpart. Unlike a ceteris paribus change, which flips s while holding all other features fixed, a mutatis mutandis intervention also adjusts any xj causally influenced by s. Thus, if x1 is height, the counterfactual of a 5'4" woman would not be a 5'4" man but, say, a 5'10" man, via an OT map. While OT handles continuous attributes naturally, categorical features (e.g. occupation or neighbourhood) lack a canonical distance. As a result, generating counterfactuals (e.g. the male counterpart of a female nurse, or where a Black resident of X would live if they were White) becomes particularly challenging.
1.2 The Case of Categorical Variables
For absolutely continuous variables, the approaches of [Pleˇcko and Meinshausen, 2020; Pleˇcko et al., 2024] on the one hand (based on quantile regressions) and [Black et al., 2020; Charpentier et al., 2023; De Lara et al., 2024;
Fernandes Machado et al., 2025] (based on OT) are quite similar.
If [Pleˇcko and Meinshausen, 2020] considered quantile regressions for absolutely continuous variables, the case of ordered categorical variables is considered (at least with some sort of meaningful ordering) in the section related to "Practical aspects and extensions." Discrete optimal transport between two marginal multinomial distributions is considered, but as discussed, it suffers multiple limitations. Here, we will consider an alternative approach, based on the idea of transforming categorical variables into continuous ones, coined "compositional variables" in [Chayes, 1971], and then, using "Dirichlet optimal transport," on those compositions.
While motivated by counterfactual fairness, the primary aim of this study is to present the core of a method for deriving counterfactuals for categorical data, applicable to any context requiring counterfactual analysis. Here, for simplicity, we have set aside considerations related to the assumption of a known Structural Causal Model (SCM). 2
1.3 Agenda
After recalling notations on OT in Section 2, we discuss how to transform categorical variables with d categories into variables taking values in the simplex Sd in Rd , i.e., compositional variables, in Section 3. In Section 4, we review the topological and geometrical properties of the probability simplex Sd ⊂ Rd . In Section 5, we introduce the first methodology, which transports distributions within Sd via Gaussian OT. This approach relies on an alternative representation of probability vectors in the Euclidean space Rd-1 and assumes approximate normality in the transformed space. In Section 6, we present a second methodology, which operates directly on Sd using a tailored cost function instead of the standard quadratic cost. Theoretical aspects of this "Dirichlet transport" framework are discussed in Section 6.1, while empirical strategies for matching categorical observations are developed in Section 6.2. Section 7 provides two empirical illustrations using the German Credit and Adult datasets.
Our main contributions can be summarized as follows:
- We propose a novel method to handle categorical variables in counterfactual modeling by using optimal transport directly on the simplex. This approach transforms categorical variables into compositional data, enabling the use of probabilistic representations that preserve the geometric structure of the simplex.
- By integrating optimal transport techniques on this domain, the method ensures consistency with the properties of compositional data and offers a robust framework for counterfactual analysis in real-world scenarios.
- Our approach does not require imposing an arbitrary order on the labels of categorical variables.
2 Optimal Transport
Given two metric spaces X0 and X1, consider a measurable map T : X0 → X1 and a measure µ0 on X0. The pushforward of µ0 by T is the measure µ1 = T#µ0 on X1 defined by T#µ0(B) = µ0 (T -1 (B)), ∀B ⊂ X1. For all measurable and bounded φ : X1 → R,
2 Details on how the method can be integrated within an SCM are discussed in Appendix C of the extended version of the paper.
For our applications, if we consider measures X0 = X1 as a compact subset of Rd , then there exists T such that µ1 = T#µ0, when µ0 and µ1 are two measures, and µ0 is atomless, as shown in [Villani, 2003] and [Santambrogio, 2015]. Out of those mappings from µ0 to µ1, we can be interested in "optimal" mappings, satisfying Monge problem, from [Monge, 1781], i.e., solutions of
for some positive ground cost function c : X0 ×X1 → R+. In general settings, however, such a deterministic mapping T between probability distributions may not exist (in particular if µ0 and µ1 are not absolutely continuous, with respect to Lebesgue measure). This limitation motivates the Kantorovich relaxation of Monge's problem [Kantorovich, 1942],
with our cost function c, where Π(µ0, µ1) is the set of all couplings of µ0 and µ1. This problem focuses on couplings rather than deterministic mappings It always admits solutions referred to as OT plans. Observe that T ⋆ is an "increasing mapping," in the sense of being the gradient of a convex function, from [Brenier, 1991]). Finally, one should have in mind the the cost function c is related to the geometry of sets X.
3 FromCategorical to Compositional Data
Using the notations of the introduction, consider a dataset {s, x} where features x are either numerical (assumed to be "continuous"), or categorical. In the latter case, suppose that xj takes values in {xj,1, · · · , xj,dj }, or more conveniently, [[dj]] = {1, · · · , dj}, corresponding to the dj categories (as in the standard "One Hot" encoding).
The aim is to transform a categorical variable x, which takes values in [[d]], into a numerical one in the simplex Sd. To achieve this, we suggest using a probabilistic classifier. This classifier is based on the other features in x, denoted by X-x.Mathematically, we consider a mapping from X-x to Sd (and not to [[d]] as in a standard multiclass classifier). The most natural model for this transformation is the Multinomial Logistic Regression (MLR), which is based on the "softmax" loss function. To normalize the output of the classifier into the simplex, we define the closure operator C : Rd+ → Sd as
or shortly
Algorithm 1 From categorical variables into compositions.
| x | ˜xC | ˜xE | ˜xO |
|---|---|---|---|
| E | 18.38% | 61.56% | 20.06% |
| C | 40.86% | 42.38% | 16.76% |
| E | 19.41% | 70.82% | 9.77% |
| C | 47.04% | 26.83% | 26.13% |
| x ˜xC | ˜xE | ˜xO |
|---|---|---|
| E 9.22% | 75.92% | 14.86% |
| C 46.80% | 24.06% | 29.14% |
| E 11.23% | 79.07% | 9.71% |
| C 50.74% | 26.98% | 22.28% |
| ˜xC | ˜xE | ˜xO |
|---|---|---|
| 23.68% | 46.32% | 30.00% |
| 34.68% | 36.42% | 28.90% |
| 16.87% | 76.51% | 6.63% |
| 53.16% | 26.84% | 20.00% |
| ˜xC | ˜xE | ˜xO |
|---|---|---|
| 11.25% | 68.51% | 20.24% |
| 61.14% | 13.10% | 25.76% |
| 12.48% | 75.58% | 11.94% |
| 51.12% | 25.17% | 23.71% |
Table 1: Mappings from the purpose categorical variable x to the compositional one ˜x, (in the german credit dataset), for the first four individuals of the dataset. The first two models are GAM-MLR (multinomial model with splines for continuous variables), then, a random forest, and a boosting algorithm.
where 1 is a vector of ones in Rd . Then, in the MLR model, the transformation ̂ T : X-x → Sd is given by
where ̂β2, . . . , ̂βd are the estimated coefficients for each category, and the first category is taken as the reference. This procedure is described in Algorithm 1.
As an illustration, consider the purpose variable from the German dataset. For simplicity, this variable has been reduced to three categories: C, E,O (representing cars, equipment, and other, respectively). More details on the dataset are provided in Section 7.1. The purpose variable is converted into a continuous variable using four models: (i) a GAM-MLR with splines for three continuous variables, (ii) a GAM-MLR incorporating these variables and seven categorical ones, (iii) a random forest, and (iv) a gradient boosting model. Table 1 presents the observed values in the first column for each model, along with the estimated scores for each category in the three remaining columns, corresponding to the transformed values T ⋆ (x).
Note that if we want to go back from compositions to categories, the standard approach is based on the majority (or argmax) rule.
In the rest of the paper, given a dataset {s, x}, all categorical variables are transformed into compositions, so that X is a product space of sets that are either R for numerical variables or Sd (type) for compositions (d will change according to the number of categories).
In fact, for privacy issues, a classical strategy is to consider aggregated data on small groups (usually on a geographic level, per block, or per zip code), even if there is an ecological fallacy issue (that occurs when conclusions about individual behaviour or characteristics are incorrectly drawn based on aggregate data for a group, see [King et al., 2004]). Hence, using "compositional data" is quite natural in many cases, as unobserved categorical variables can often be represented as compositions predicted from observed variables serving as proxies. For example, in U.S. datasets, racial information about individuals may not always be available. However, the proportions of groups such as "White and European," "Asian," "Hispanic and Latino," "Black or African American," etc., within a neighbourhood may be observed instead (see, e.g., [Cheng et al., 2010], [Naeini et al., 2015] and [Zadrozny and Elkan, 2001] for more general discussions, or [Imai et al., 2022] about the use of predicted probabilities when categories are not observed).
4 Topology and Geometry of the Simplex
The standard simplex of Rd is the regular polytope Sd = {x ∈ Rd+ ∣∣ x⊤1 = 1 }, but for convenience, consider the open version of that set,
Following [Aitchison, 1982], define the inner product
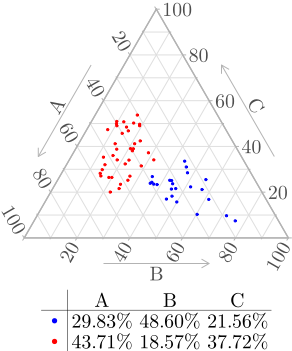
and the simplex becomes a metric vector space if we consider the associated "Aitchison distance," as coined in [PawlowskyGlahn and Egozcue, 2001]. Figure 1 shows n = 61 points in S3. Each point x can be seen as a probability vector over {A, B, C}, drown either from a distribution P0 for red points or P1 for blue points.
If we define the binary operator ⋄ on Sd,
then (Sd, ⋄) is a commutative group, with identity element d-11, and the inverse of x is
5 Using an Alternative Representation of Simplex Data
A first strategy to define a transport mapping could be to use some isomorphism, h : Sd → E and then define the inverse mapping h-1 : E → Sd, where E is some Euclidean space, classically Rd-1 , where the standard quadratic cost can be considered. This idea corresponds to the dual transport problem in [Pal and Wong, 2018].
5.1 Classical Transformations
The additive log ratio (alr) transform is an isomorphism where alr : Sd → Rd-1 , given by
Its inverse is, for any z ∈ Rd-1 ,
Such a map, from Sd to Rd-1 is related to the so-called "exponential coordinate system" of the unit simplex, in [Pal, 2024]. The center log ratio (clr) transform is both an isomorphism and an isometry where clr : Sd → Rd ,
where xg denotes the geometric mean of x. Observe that the inverse of this function is the softmax function, i.e.,
Finally, the isometric log ratio (ilr) transform, defined in [Egozcue et al., 2003], is both an isomorphism and an isometry where ilr : Sd → Rd-1 ,
for some orthonormal base {⃗e1, · · · ,⃗ed-1,⃗ed} of Rd . One can consider some matrix M, d×(d-1) such that MM⊤ = Id-1 and M⊤M = Id + 1d×d. Then
and
5.2 GaussianMapping in the Euclidean Representation
Given a random vector X in Sd, we say that x follows a "normal distribution on the simplex" if, for some isomorphism h, the vector of orthonormal coordinates, Z = h(X) follows a multivariate normal distribution on Rd-1 . If we suppose that both X0 and X1, taking values in Sd, follow "normal distributions on the simplex," then we can use standard Gaussian optimal transport, between Z0 and Z1. For convenience, suppose that the same isomorphism is used for both distributions (but that assumption can easily be relaxed). Hence, if Z0 ∼ N(µ0,Σ0) and Z1 ∼ N(µ1,Σ1), the optimal mapping is linear,z1 = T ⋆ (z0) = µ1 + A(z0 - µ0), (4)
where A is a symmetric positive matrix that satisfies AΣ0A = Σ1, which has a unique solution given by A = Σ-1/2 0 (Σ1/2 0 Σ1Σ1/2 0 )1/2Σ-1/2 0 , where M1/2 is the square root of the square (symmetric) positive matrix M based on the Schur decomposition (M1/2 is a positive symmetric matrix), as described in [Higham, 2008]. Interestingly, it is possible to derive McCann's displacement interpolation, from [McCann, 1997], to have some sort of continuous mapping
Algorithm 2 Gaussian Based Transport of x0 on Sd
Input: x0 (∈ Sd)
Parameter: {x0,1, · · · , x0,n0 } and {x1,1, · · · , x1,n1 } in Sd;
isomorphic transformation h : Sd → Rd-1
Output: x1
end for
end for
S0 ← empirical variance matrix of {z0,1, · · · , z0,n0 }
S1 ← empirical variance matrix of {z1,1, · · · , z1,n1 }
T ⋆ t such that T ⋆ 1 = T ⋆ and T0 = Id, and so that Zt = T ⋆ t (Z0) has distribution N (µt, Σt) where µt = (1 - t)µ0 + tµ1 and
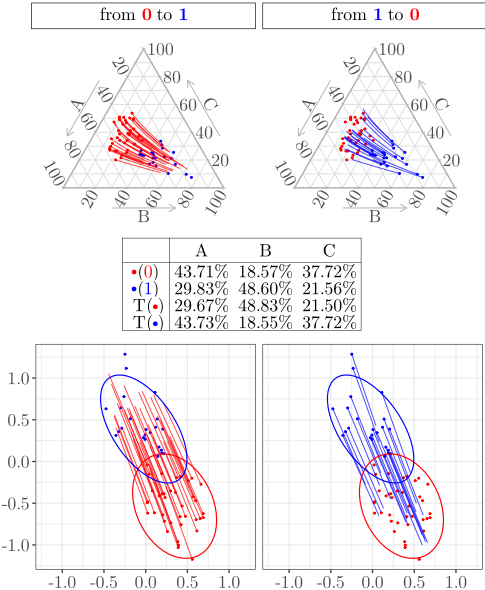
Empirically, this can be performed using Algorithm 2, and a simulation can be visualized in Figure 2, where h = clr. On the left, we can visualize the mapping of red points to the blue distribution, and on the right, the "inverse mapping" of blue points to the red distribution. Transformed points z = h(x), that are plotted at the bottom, are supposed to be normally distributed, and a multivariable Gaussian Optmial Transport mapping is used. Hence, T ⋆ t is linear in Rd-1 , as given by expression 4, as well as displacement interpolation, corresponding to red and blue segments. But, as we can see on top of Figure 2, in the original space, t ↦→ xt := h-1 (zt) will be nonlinear. Tables are average values of the three components of x's and T ⋆ (x)'s.
6 Optimal Transport for Measures on Sd
6.1 Theoretical Properties
A function ψ : Sd → R is exponentially concave if exp[ψ] : Sd → R+ is concave. As a consequence, such a function ψ is differentiable almost everywhere. Let ∇ψ and ∇⃗uψ denote, respectively, its gradient, and its directional derivative. Following [Pal and Wong, 2016; Pal and Wong, 2018; Pal and Wong, 2020], define an allocation map generated by ψ, πψ : Sd → Sd defined as
where {⃗e1, · · · ,⃗ed} is the standard orthonormal basis of Rd . Consider the optimal transport problem with the following cost function, on Sd ×Sd, i.e., the L-divergence corresponding to the cross-entropy,
called "Dirichlet transport" in [Baxendale and Wong, 2022]. See [Pistone and Shoaib, 2024] for a discussion about the connections with the distance induced by Aitchsion's inner product of Equation (3). From Theorem 1 in [Pal and Wong, 2020], for this cost function, there exists an exponentially concave function ψ⋆ : Sd → R such that
defines a push-forward from P0 to P1, and the coupling (x, T ⋆ (x)) is optimal for problem (1), and is unique if P0 is absolutely continuous. Observe that if y = T ⋆ (x),
where z = x-1 .
One can also consider an interpolation,
where πt = (1-t)d-11+tπψ⋆ (even if this approach differs fromMcCann's displacement interpolation).
Note that a classical distribution on Sd is Dirichlet distribution, with density
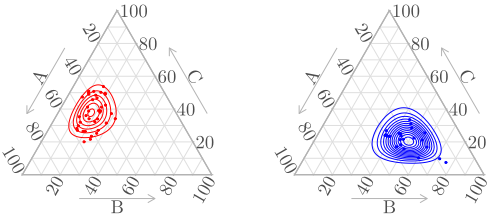
for some α = (α1, . . . , αd) ∈ Rd+, and a normalizing constant denoted B(α). Level curves of the density of Dirichlet distributions fitted on our toy dataset can be visualized in Figure 3. Unfortunately, unlike the multivariate Gaussian distribution, there is no explicit expression for the optimal mapping between Dirichlet distribution (regardless of the cost). Therefore, to remain within Sd and avoid the Rd-1 representation, numerical techniques should be considered.
6.2 Matching
Consider two samples in the Sd simplex, {x0,1, · · · , x0,n0 } and {x1,1, · · · , x1,n1 }. The discrete version of the Kantorovich problem (corresponding to Equation 2) is
where, as in [Brualdi, 2006], U(n0, n1) is the set of n0 × n1 matrices corresponding to the convex transportation polytope
and where C denotes the n0 × n1 cost matrix, Ci,j = c(xi, xj), associated with cost from Equation (5).
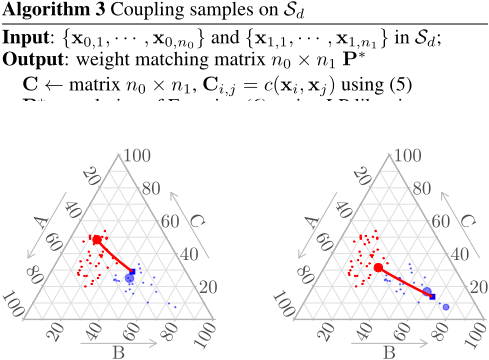
In Algorithm 3, we recall how this procedure works, which is the one explained in [Peyr´e et al., 2019], with a specific cost function (from Equation (5)). In the toy dataset, this can be visualized for two specific observations x0,i in Figure 4 (big red dots). If n0 ̸= n1, it is not a one-to-one coupling, and "the counterfactual" (blue square) is in fact a weighted average of x1,j's (blue dots), where weights are given in row P⋆i = [P⋆i,1 , · · · ,P⋆i,n1 ] ∈ Sn1 .
7 Application on Sequential Transport for Counterfactuals
Variables xj in tabular data are either continuous or categorical. If xj is continuous, since xj ∈ R, transporting from observed xj|s = 0 to counterfactual xj|s = 1 is performed using standard (conditional) monotonic mapping, as discussed in [Fernandes Machado et al., 2025], using classical F -1 1 ◦F0. If xj is categorical, with d categories, consider some fitted model ̂m(xj|x-j), using some multinomial loss, and let ̂xj = ̂m(xj|x-j) denote the predicted scores, so that ̂xj ∈ Sd. Then use Algorithm 2, with a Gaussian mapping in an Euclidean representation space, to transport from observed ̂xj |s = 0 to counterfactual ̂xj |s = 1, in Sd.
7.1 German Credit: Purpose
In the popular German Credit dataset, from [Hofmann, 1994], the variable Purpose described the reason an individual took out a loan. This variable is an important predictor for explaining potential defaults. The original variable is based on ten categories, that are merged here into three main classes, cars, equipment and other, in order to visualize the transport in a ternary plot (or Gibbs triangle). The sensitive variable s is here Sex.
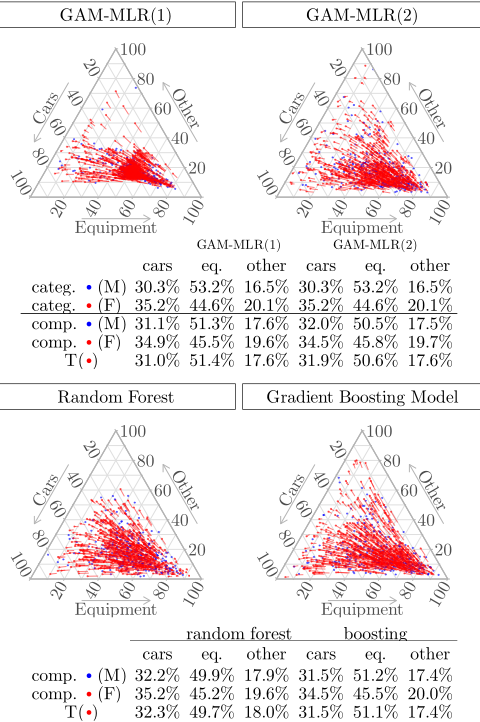
We aim to construct a counterfactual value for the loan purpose, assuming the individuals were of a different sex. To achieve this, we apply our suggested procedure from to represent the purpose categorical variable as a compositional variable, using the same four models outlined in Section 3 and then apply Gaussian mapping from Section 5.2. The results provided by all of the models, shown in Figure 5, suggest that, had the individuals been of a different sex, the purpose of the loan would have changed. Specifically, if the average scores in each group (cars, equipment, and other) were approximately [35%, 45%, 20%] in the female population, after transporting to obtain the counterfactuals, the average scores become [31%, 51%, 18%], which closely resemble the actual frequencies of each category in the original male population.
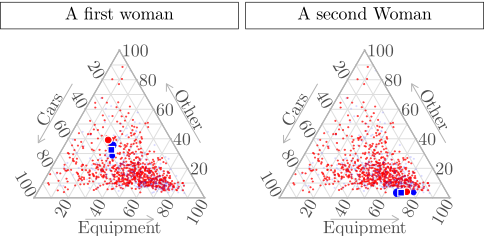
One can also consider our second approach, using matching in S3. Consider individual i among women, e.g., the left of Figure 6, x0,i = "other." Using a MLR model, we obtain composition x0,i, here [36.98%, 23.81%, 39.2%]. Using Algorithm 3, three points x1,j's are matched, respectively with weights [0.226, 0.548, 0.226]. For those three points, the propensity for the purpose to be "cars' is the highest ([39.9%, 36.3%, 42.3%]). Therefore, the counterfactual version of woman i with an "other" credit is a man with the purpose "cars". In fact, using Gaussian transport (blue square), we obtain T ⋆ (x0,i) = [38.47%, 29.05%, 32.49%].
7.2 Adult: Marital Status
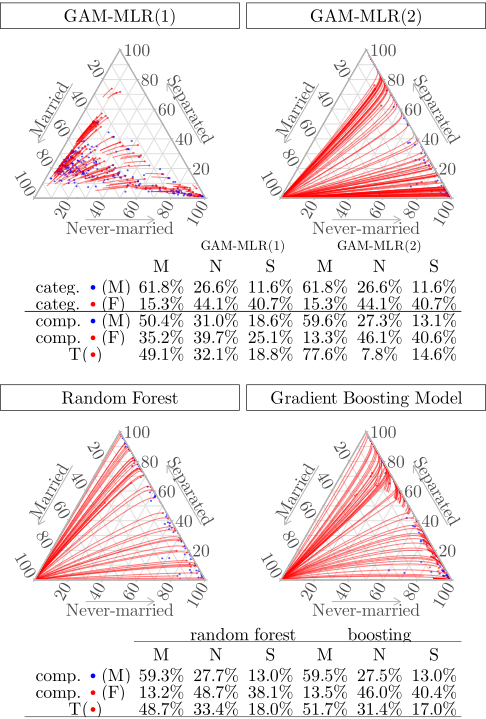
Following the numerical applications in [Pleˇcko et al., 2024] and [Fernandes Machado et al., 2025], we consider here the Adult dataset, from [Becker and Kohavi, 1996]. We regrouped categories of the Marital Status variable to create three generic ones (that can be visualized in a ternary plot, as in Figure 7), namely Married (M), Never-married (N) and Separated (S). This example is interesting because if we compare status with respect to the Sex variable, proportions are quite different. In the dataset, proportions for married, never married, and separated are (roughly) [62%, 27%, 12%] for men, [14%, 44%, 41%] for women (more precise values are at the top of the table in Figure 7). Thus, the counterfactual of a "separated" woman is more likely to be a "married" man than a "separated" man. Four models are used to convert the categorical variable Marital Status into a composition, as previously. The first MLR is based on three variables: a categorical variable, occupation, and two continuous ones, age, and hours per week, modeled nonlinearly using b-splines (hence, it is referred to as a logistic GAM). This model is clearly underfitted. Therefore, observations x0,i's for women and x1,i's for men clearly are in the interior of Sd. In contrast, the more complex MLR (which uses additional features), as well as the random forest and boosting models, can produce predictions near the simplex boundary, ∂Sd.
For the underfitted model (top left), transported scores have a distribution very close to the ones in the population of men. For the more accurate MLR model (top right), proportions are very close to the actual proportions (which is not surprising since GLMs are usually well calibrated), but the transported scores are slightly different than the proportions of categories (proportions were [62%, 27%, 12%] while average transported scores are [67%, 25%, 8%]). At least, we are different from the original ones, but the mapping is not as accurate as it should be. This might come from the fact that when the points xi are close to the border ∂Sd, it is quite unlikely that the sample zi is Gaussian.
8 Conclusion
In this article, we introduce a novel approach for constructing counterfactuals for categorical data by transforming them into compositional data using a probabilistic classifier. Our approach avoids imposing arbitrary assumptions about label ordering. However, our methodology is not without limitations. OT computations, particularly on the simplex, can be computationally intensive for large-scale datasets, posing challenges in high-dimensional settings. Additionally, the reliance on a probabilistic classifier in the initial step introduces potential vulnerabilities. Biases may arise from a poorly calibrated or inaccurate classifier, impacting the quality of the subsequent analysis-especially with scarce categories that may need grouping to apply the proposed method.
Ethical Statement
There are no ethical issues.
Acknowledgments
Agathe Fernandes Machado acknowledges that the project leading to this publication has received funding from OBVIA. Arthur Charpentier acknowledges funding from the SCOR Foundation for Science and the National Sciences and Engineering Research Council (NSERC) for funding (RGPIN2019-07077). Ewen Gallic acknowledges funding from the French government under the "France 2030" investment plan managed by the French National Research Agency (reference: ANR-17-EURE-0020) and from Excellence Initiative of Aix-Marseille University - A*MIDEX.
@inproceedings{ijcai2025p572,
  title     = {Optimal Transport on Categorical Data for Conterfactuals Using Compositional Data and Dirichlet Transport},
  author    = {Fernandes Machado, Agathe and Gallic, Ewen and Charpentier, Arthur},
  booktitle = {Proceedings of the Thirty-Fourth International Joint Conference on
               Artificial Intelligence, {IJCAI-25}},
  publisher = {International Joint Conferences on Artificial Intelligence Organization},
  editor    = {James Kwok},
  pages     = {5136--5144},
  year      = {2025},
  month     = {8},
  note      = {Main Track},
  doi       = {10.24963/ijcai.2025/572},
  url       = {https://doi.org/10.24963/ijcai.2025/572},
}
TY - CPAPER TI - Optimal Transport on Categorical Data for Conterfactuals Using Compositional Data and Dirichlet Transport AU - Fernandes Machado, Agathe AU - Gallic, Ewen AU - Charpentier, Arthur T2 - Proceedings of the Thirty-Fourth International Joint Conference on Artificial Intelligence, IJCAI-25 PB - International Joint Conferences on Artificial Intelligence Organization PY - 2025 SP - 5136 EP - 5144 DO - 10.24963/ijcai.2025/572 UR - https://doi.org/10.24963/ijcai.2025/572 ER -Copied
Machine-readable versions of this paper, for tools and AI agents:





