
Indirect Online Preference Optimization via Reinforcement Learning
Proceedings of the Thirty-Fourth International Joint Conference on Artificial Intelligence. Main Track. Pages 538-546.
https://doi.org/10.24963/ijcai.2025/61
Keywords
- Agent-based and Multi-agent Systems: MAS: Multi-agent learning
- Agent-based and Multi-agent Systems: MAS: Agent theories and models
- AI Ethics, Trust, Fairness: ETF: AI and law, governance, regulation
Abstract
Human preference alignment (HPA) aims to ensure Large Language Models (LLMs) responding appropriately to meet human moral and ethical requirements. Existing methods, such as RLHF and DPO, rely heavily on high-quality human annotation, which restrict the efficiency of iterative online model refinement.
To address the inefficiencies of human annotation acquisition, iterated online strategy advocates the use of fine-tuned LLMs to self-generate preference data. However, this approach is prone to distribution bias, because of differences between human and model annotations, as well as modeling errors between simulators and real-world contexts. To mitigate the impact of distribution bias, we adopt the principles of adversarial training, framing a zero-sum two-player game with a protagonist agent and an adversarial agent. With the adversarial agent challenging the alignment of protagonist agent, we continuously refine the protagonist’s performance. By utilizing min-max equilibrium and Nash equilibrium strategies, we propose Indirect Online Preference Optimization (IOPO) mechanism that enables the protagonist agent to converge without bias while maintaining linear computational complexity. Extensive experiments across three real-world datasets demonstrate that IOPO outperforms state-of-the-art alignment methods in both offline and online scenarios, evidenced by standard alignment metrics and human evaluations. This innovation reduces the time required for model iterations from months to one week, alleviates distribution shifts, and significantly cuts annotation costs.
- [Achiam et al., 2023] Josh Achiam, Steven Adler, Sandhini Agarwal, Lama Ahmad, Ilge Akkaya, Florencia Leoni Aleman, Diogo Almeida, Janko Altenschmidt, Sam Alt- man, Shyamal Anadkat, et al. Gpt-4 technical report. arXiv preprint arXiv:2303.08774, 2023.
- [Azar et al., 2024] Mohammad Gheshlaghi Azar, Zhao- han Daniel Guo, Bilal Piot, Remi Munos, Mark Rowland, Michal Valko, and Daniele Calandriello. A general theo- retical paradigm to understand learning from human pref- erences. In International Conference on Artificial Intelli- gence and Statistics, pages 4447-4455. PMLR, 2024.
- [Bai et al., 2022a] Yuntao Bai, Andy Jones, Kamal Ndousse, Amanda Askell, Anna Chen, Nova DasSarma, Dawn Drain, Stanislav Fort, Deep Ganguli, Tom Henighan, et al. Training a helpful and harmless assistant with reinforce- ment learning from human feedback. arXiv preprint arXiv:2204.05862, 2022.
- [Bai et al., 2022b] Yuntao Bai, Saurav Kadavath, Sandipan Kundu, Amanda Askell, Jackson Kernion, Andy Jones, Anna Chen, Anna Goldie, Azalia Mirhoseini, Cameron McKinnon, et al. Constitutional ai: Harmlessness from ai feedback. arXiv preprint arXiv:2212.08073, 2022.
- [Bos, 1980] Henk JM Bos. Newton, leibniz and the leib- nizian tradition. From the calculus to set theory, pages 1630-1910, 1980.
- [Bradley and Terry, 1952] Ralph Allan Bradley and Milton E Terry. Rank analysis of incomplete block designs: I. the method of paired comparisons. Biometrika, 39(3/4):324- 345, 1952.
- [Cheng et al., 2024] Pengyu Cheng, Yifan Yang, Jian Li, Yong Dai, Tianhao Hu, Peixin Cao, Nan Du, and Xiao- long Li. Adversarial preference optimization: Enhancing your alignment via rm-llm game. In Findings of the As- sociation for Computational Linguistics ACL 2024, pages 3705-3716, 2024.
- [Christiano et al., 2017] Paul F Christiano, Jan Leike, Tom Brown, Miljan Martic, Shane Legg, and Dario Amodei. Deep reinforcement learning from human preferences. Advances in neural information processing systems, 30, 2017.
- [Ethayarajh et al., 2024] Kawin Ethayarajh, Winnie Xu, Niklas Muennighoff, Dan Jurafsky, and Douwe Kiela. Kto: Model alignment as prospect theoretic optimization. arXiv preprint arXiv:2402.01306, 2024.
- [Haarnoja et al., 2018] Tuomas Haarnoja, Aurick Zhou, Pieter Abbeel, and Sergey Levine. Soft actor-critic: Off-policy maximum entropy deep reinforcement learning with a stochastic actor. In International conference on ma- chine learning, pages 1861-1870. PMLR, 2018.
- [Kakade and Langford, 2002] Sham Kakade and John Lang- ford. Approximately optimal approximate reinforcement learning. In Proceedings of the Nineteenth International Conference on Machine Learning, pages 267-274, 2002.
- [Konda and Tsitsiklis, 1999] Vijay Konda and John Tsitsik- lis. Actor-critic algorithms. Advances in neural informa- tion processing systems, 12, 1999.
- [Kumar et al., 2020] Aviral Kumar, Aurick Zhou, George Tucker, and Sergey Levine. Conservative q-learning for offline reinforcement learning. Advances in Neural Infor- mation Processing Systems, 33:1179-1191, 2020.
- [Levine et al., 2020] Sergey Levine, Aviral Kumar, George Tucker, and Justin Fu. Offline reinforcement learning: Tu- torial, review, and perspectives on open problems. arXiv preprint arXiv:2005.01643, 2020.
- [Littman, 1994] Michael L Littman. Markov games as a framework for multi-agent reinforcement learning. In Ma- chine learning proceedings 1994, pages 157-163. Else- vier, 1994.
- [Liu et al., 2023] Tianqi Liu, Yao Zhao, Rishabh Joshi, Misha Khalman, Mohammad Saleh, Peter J Liu, and Jialu Liu. Statistical rejection sampling improves preference op- timization. arXiv preprint arXiv:2309.06657, 2023.
- [Ouyang et al., 2022] Long Ouyang, Jeffrey Wu, Xu Jiang, Diogo Almeida, Carroll Wainwright, Pamela Mishkin, Chong Zhang, Sandhini Agarwal, Katarina Slama, Alex Ray, et al. Training language models to follow instruc- tions with human feedback. Advances in neural informa- tion processing systems, 35:27730-27744, 2022.
- [Pinto et al., 2017] Lerrel Pinto, James Davidson, Rahul Sukthankar, and Abhinav Gupta. Robust adversarial re- inforcement learning. In International conference on ma- chine learning, pages 2817-2826. PMLR, 2017.
- [Rafailov et al., 2024] Rafael Rafailov, Archit Sharma, Eric Mitchell, Christopher D Manning, Stefano Ermon, and Chelsea Finn. Direct preference optimization: Your lan- guage model is secretly a reward model. Advances in Neu- ral Information Processing Systems, 36, 2024.
- [Schulman et al., 2017] John Schulman, Filip Wolski, Pra- fulla Dhariwal, Alec Radford, and Oleg Klimov. Prox- imal policy optimization algorithms. arXiv preprint arXiv:1707.06347, 2017.
- [Tokdar and Kass, 2010] Surya T Tokdar and Robert E Kass. Importance sampling: a review. Wiley Interdisciplinary Reviews: Computational Statistics, 2(1):54-60, 2010.
- [Touvron et al., 2023] Hugo Touvron, Louis Martin, Kevin Stone, Peter Albert, Amjad Almahairi, Yasmine Babaei, Nikolay Bashlykov, Soumya Batra, Prajjwal Bhargava, Shruti Bhosale, et al. Llama 2: Open foundation and fine-tuned chat models. arXiv preprint arXiv:2307.09288, 2023.
- [Xiong et al., 2024] Wei Xiong, Hanze Dong, Chenlu Ye, Ziqi Wang, Han Zhong, Heng Ji, Nan Jiang, and Tong Zhang. Iterative preference learning from human feed- back: Bridging theory and practice for rlhf under kl- constraint. In Forty-first International Conference on Ma- chine Learning, 2024.
- [Xu et al., 2024] Shusheng Xu, Wei Fu, Jiaxuan Gao, Wen- jie Ye, Weilin Liu, Zhiyu Mei, Guangju Wang, Chao Yu, and Yi Wu. Is dpo superior to ppo for llm alignment? a comprehensive study. arXiv preprint arXiv:2404.10719, 2024.
- [Yang et al., 2023] Aiyuan Yang, Bin Xiao, Bingning Wang, Borong Zhang, Ce Bian, Chao Yin, Chenxu Lv, Da Pan, Dian Wang, Dong Yan, et al. Baichuan 2: Open large- scale language models. arXiv preprint arXiv:2309.10305, 2023.
- [Yuan et al., 2024] Weizhe Yuan, Richard Yuanzhe Pang, Kyunghyun Cho, Sainbayar Sukhbaatar, Jing Xu, and Ja- son Weston. Self-rewarding language models. arXiv preprint arXiv:2401.10020, 2024.
- [Zoph, 2016] B Zoph. Neural architecture search with re- inforcement learning. arXiv preprint arXiv:1611.01578, 2016.
References were extracted automatically from the PDF and may contain errors.
Full text extracted automatically from the PDF; figures, tables and equations may differ. The PDF is the version of record.
1 Introduction
LLMs, such as GPT-4 [Achiam et al., 2023] and Baichuan2 [Yang et al., 2023], exhibit impressive reasoning capabilities and advanced functionalities. However, a significant challenge arises in how to ensure that LLMs respond appropriately in special domains to meet human moral and ethical requirements, particularly in politics and racial affairs related to safety. Adjusting the bias of LLMs to align with human preferences is referred to as Human preference alignment[Ouyang et al., 2022].
∗Corresponding Author
To address the above challenges, researchers have explored various algorithms to inject desired behaviors into LLMs. Reinforcement learning from human feedback (RLHF) [Bai et al., 2022a] advocates for training multiple LLMs while using a reward model to score policy learning. Rafailov et al. propose a Direct Preference Optimization (DPO) algorithm reducing reliance on reward models[Rafailov et al., 2024]. However, all methods encounter a significant bottleneck: the need for high-quality human preference comparisons, which consists of paired model outputs with human annotations indicating preference alignment.
For the challenge of this inefficient acquisition of highquality preference comparisons, iterated online strategy advocates the use of fine-tuned LLMs, to construct preference data through self-questioning and self-answering periodically [Ouyang et al., 2022; Bai et al., 2022b; Bai et al., 2022a; Rafailov et al., 2024; Xu et al., 2024]. However, this framework suffers from distribution bias. On one hand, there are differences between human annotation and model annotation. Touvron et al.[Touvron et al., 2023] note that sampling distribution shift in online procedure incurs these differences and modeling errors: a distribution gap emerges between modelgenerated preference data and human annotation preference data after a few iterations. On the other hand, any established LLMs (simulator) may differ from the real environment. If the learned policies are not robust enough to account for modeling errors, transferring these policies from the simulator to the real world often fails [Pinto et al., 2017]. Therefore, although LLMs that have gone fine-tuned LLMs own extensive vertical domain knowledge, high-quality preference data annotated by them often fail to generalize to real scenarios.
We propose Indirect Online Preference Optimization (IOPO) to address distributional bias without additional annotations. Theoretical Foundations: Our dual-agent architecture employs inverse reward design within a rigorously formalized two-player zero-sum game framework [Littman, 1994]. Through joint optimization of both agents' reward functions, the system guarantees convergence to Nash equilibrium with provable stability. Symmetrically-Constrained Bias Mitigation: The Nash equilibrium in our framework naturally counteracts bias via adversarial dynamics. Building upon RARL [Pinto et al., 2017], our zero-sum constraints effectively recast the agent's bias as adversarial perturbations, thereby achieving systematic bias reduction. The key innovation lies in our symmetric reward formulation, which unlike conventional adversarial training, imposes balanced constraints on both agents' reward structures. This prevents pathological collapse into biased strategies while maintaining the adversarial agent's role in continuously refining the protagonist's policy alignment. The resulting IOPO mechanism ensures bias-free convergence while preserving computational efficiency with linear complexity.
Our framework necessitates careful consideration of two key challenges: (1) dual-agent computational overhead and (2) convergence instability in zero-sum games. We reformulate the Bradley-Terry model via importance sampling (IS) [Tokdar and Kass, 2010] to quantify adversarial influence, and propose a clipped IS scheme that ensures: (i) proximal policy approximation, (ii) bounded policy trajectories, while preserving IS benefits (efficiency, policy compatibility, unbiasedness). This achieves reliable adversarial optimization.
In summary, this paper makes the following contributions:
- We propose a novel indirect online preference optimization (ORL) framework that simulates the real environment with no bias, without increasing annotation costs.
- In light of excessive computational resource consumption and slow-or-no convergence problem in ORL, we impose a simple clipping on IS weight to perform proximal approximation calculations.
- Our approach outperforms the SOTA approach method DPO in three real world datasets. Online evaluations validate that the iterated online strategy with few human annotations exhibits issues related to distribution shift in online preference optimization, while our method reduces thousands of expenses and time in month in annotation process.
2 RelatedWork
2.1 Reinforcement learning onMarkov
The Markov process of standard reinforcement learning (RL) is represented by a tuple (AGENT,ENV ) ≡
(S,A,P, r, γ). Here, AGENT is the entity making decisions and learning, ENV is the external system. The actions of AGENT influence the environment, thereby allowing the AGENT to receive feedback. S is a set of states, A is a set of actions, P : S ×A× S → R is the transition probability, r : S × A → R is the reward, γ is the discount factor. Main procedure of AGENT, such as Actor-Critic [Konda and Tsitsiklis, 1999] and PPO [Schulman et al., 2017], is to learn a stochastic policy πθ : S ×A → R that maximizes the cumulative discounted reward ∑T-1 t=0 γ t r(st, at), where θ denotes the parameters for the policy π at time-step t. Levine et al. [Levine et al., 2020] delineate key distinctions: online RL involves ENV - AGENT iterations absent in offline RL, while on-policy RL unifies behavior and learning in a single policy versus off-policy's separation.
Extending RARL [Christiano et al., 2017], we introduce a clipped IS-weighted zero-sum game to reduce HPA bias.
2.2 Human Preference Fine-Tuning
Human preference alignment [Ouyang et al., 2022] seeks to align LLMs with human expectations. Notably, Bai et al. introduce Reinforcement Learning from Human Feedback (RLHF) to develop a helpful and harmless assistant [Bai et al., 2022a], utilizing self-questioning and self-answering techniques [Bai et al., 2022b]. RLHF faces challenges, including significant computational costs, complex complementary procedures, and instability due to reward hacking. To enhance sampling efficiency and stability, Rafailov et al. propose Direct Preference Optimization (DPO) as a means to bridge the gap between reward functions and policy [Rafailov et al., 2024]. RSO [Liu et al., 2023] improves the estimation of the optimal policy by integrating SLiC with DPO. Addressing overfitting and generalization issues, IPO [Azar et al., 2024] mathematically critiques DPO's limitations and suggests a comprehensive objective for learning from human preferences. KTO-PAIR [Ethayarajh et al., 2024] advances this by directly optimizing human-aware losses (HALOs) instead of merely maximizing the log-likelihood of preferences, using a Kahneman-Tversky model of human utility. Nonetheless, most existing fine-tuning methods pose a need for highquality human preference comparisons, which restricts continuous model updates, underscoring the need for further research in this domain.
Recently, iterated online strategy has emerged as a solution for continuous fine-tuning [Ouyang et al., 2022; Bai et al., 2022b; Bai et al., 2022a; Rafailov et al., 2024; Xu et al., 2024]. Self-Reward [Yuan et al., 2024] proposes that LLMs utilize a Judge-Prompt mechanism to generate their own rewards during training. Iter-FineTuning [Xiong et al., 2024] introduces an iterative version of Direct Preference Optimization for online settings and a multi-step rejection sampling strategy for offline scenarios, effectively enhancing policy learning. APO [Cheng et al., 2024] suggests an alternating update approach for LLMs and reward models through a min-max game using high-quality data. While existing online methods have partially mitigated the limitations of offline approaches, sampling distribution issues continue to impede alignment efficiency [Touvron et al., 2023], necessitating additional human annotations. For instance, DPO's effectiveness is contingent upon high-quality data, and RLH(A)F reward models require real-time updates.
Our dual-agent architecture implements inverse reward design within a formal two-player zero-sum game framework [Littman, 1994], guaranteeing Nash equilibrium convergence with provable stability. Extending with [Pinto et al., 2017], we develop a bias-reducing zero-sum two-player game.
3 SystemModel and ProblemFormulation
The fine-tuning pipeline consists of three stages: 1) unsupervised pretraining of LLMs, 2) LLMs aligned through supervised fine-tuning (SFT), and 3) LLMs optimized with RL algorithms, commonly REINFORCE [Zoph, 2016], proximal policy optimization (PPO) [Schulman et al., 2017], DPO [Rafailov et al., 2024], or their variants.
For DPO, given a tuple (x, yl, yw) sampled from dataset D = {x(i) , y(i) w , y(i) l }N i=1 , the preference is denoted as yw ≻ yl | x, where yw and yl represent the preferred and less preferred completions, respectively.
where Q(yw ≻ yl | x) or P (yw ≻ yl | x) calculated based on the Bradley-Terry mathematical model[Bradley and Terry, 1952]. The optimization of the reward model rϕ(x, y) can be formulated as maximizing the negative log-likelihood loss:
Following policy optimization problem as formulating:
where β is a hyper parameter, controlling the deviation from model policy πθ to reference policy πref , with πθ is also initialized to πSFT.
To simplify the pipeline, motivated by [Rafailov et al., 2024], we deduce the policy πθ from the objective function:
where we rename the derivation outcome as πr(y | x). Subsequently, the reward model r(x, y) is presented as follows:
Substituting Eq.(5) into Eq.(1), here is reward function:
Therefore, policy objective and the gradient of the loss function are shown below:
where ˆ rθ(x, y) = β log πθ(y|x) πref (y|x) , denoting reward implicitly defined by πθ(y|x) and πref (y|x).
4 Methodology
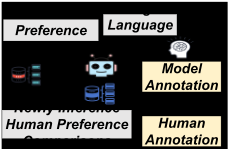
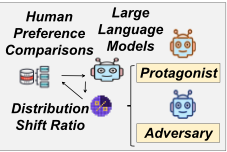
The original fine-tuning as Fig.1 (left) poses additional annotation cost caused by sampling distribution shifts: LLMs, via DPO (RLHF), will infer new Preference Comparison Completions to continuously update their models or reward models. In contrast, we employ a two-players zero-sum game to calculate distribution shift ratio as Fig.1 (right).
4.1 Formulations of Indirect Online Preference Optimization
Both players observe the state st and take actions aµt ∼ µ(st) or aνt ∼ µ(st), where µ and ν represent the strategies of protagonist and adversary, respectively. We note that aµt ∼ µ(st) and aνt ∼ µ(st) denote preferences as yw ≻ yl | x and yl ≻ yw | x. The state transitions st+1 = P(st, aµt , aνt ) are given by π(µ, ν), and a reward rt = r(st, aµt , aνt ) is defined as rµ t = rt while the adversary gets a reward rν t = -rt. Reward function optimization is evaluated as follows:
As for computation costs, rt (θ) quantifies the distribution shift caused by protagonist πµ and adversary πν. RARL [Pinto et al., 2017] demonstrated that the notions of minmax equilibrium and Nash equilibrium are equivalent for this game, with an optimal equilibrium reward denoted as Qµ∗ .
Similarly, the adversary aims to maximize its own reward through Qν ≡ Qν (µ, ν) = -Qµ (µ, ν). And we observe that πµ(yt l | xt ) ≡ πν(ytw | xt ):
We should emphasize that rtµ (θ) = 0 represents overfitting in pipeline, while rtµ → ∞ situations where learning the data features is difficult.
Due to the slow-or-no convergence problem, we employ a simple clip proximal calculation on rtµ (θ) to penalize significant deviations staying away from the ratio of norm.
Given the constraint ∑y π(y|x) = 1, we perform Lagrange differentiation on Eq.(9) to derive the policy πµ:
Therefore, using Eq.(13), we can transform Eq.(7) into Eq.(14) and Eq.(8) into Eq.(15), respectively.
which consist of the objective function and its backward derivative formula for the protagonist.
4.2 Indirect Online Preference Optimization Outline
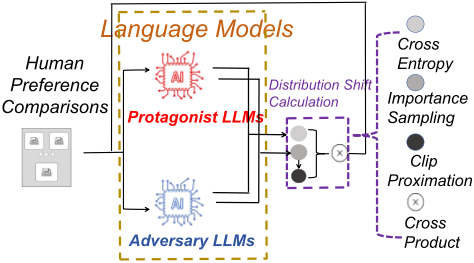
The model structure is illustrated in Fig.2, where human preference comparisons inform our models. Over Nµ iterations, adversarial LLMs supply the protagonist LLMs with a softmax output πν(yt | xt ). This output is used by the protagonist LLMs to compute a binary cross-entropy loss and an IS weight with clipping. The product of the cross-entropy loss and the clipped IS weight forms the foundation of the reverse iteration process, as detailed in Eq.(15). During Nν iterations, the adversarial LLMs derive the cross-product of the binary cross-entropy loss and the clipped IS weight from the softmax output of the protagonist LLMs.
Pipeline is as Algorithm.1: 1) initialize policy models µ and ν via SFT; 2) In practice, we carry out an iterative twostep optimization procedure. First, for Nµ iterations, the parameters of the adversary θt-1 ν are held constant and serve as the ENV , while the parameters θtµ of the protagonist AGENT are optimized to maximize the reward function Eq.(14). For the next step of Nν iterations, the parameters of the protagonist are held constant, and the parameters of the adversary θtν are optimized via Eq.(15).
Algorithm 1 Indirect Online Preference Optimization
5 Theoretical Analysis
Theorem 1. When t → ∞, our Q(µ, ν) that is a zero-sum two-player game, is monotonic and converge.
Proof. When t →∞, Q(µ, ν) is a zero-sum game as follow:
where Qtµ denotes mean-value of protagonist at t iteration. Therefore, we deduce from Eq.(16) to Eq.(17):
Similarly, there is (Qtν - Qt-1 ν ) = (Qt+1 µ - Qtµ ). By this equation and Eq.17, we have :
Eq.(18) indicates that the reward function Q forms an arithmetic progression. Given that Q ∈ range(Qtµ ∗ (1/rt (θ))), where Qtµ ∈ [0, 1] and rt (θ) is constant, we conclude that our algorithm converges based on Theorem (1).
Theorem 2. With rt (θ) is constant, our Qµ converge faster. Proof. We note that for Nµ iteration:
where rtµ (θ) is constant in Nµ iteration. Transforming Eq.(18) with Eq.(19) into Eq.(20):
| Datasets | Baselines | Win rate (IOPO vs.) by Ziya | Win rate (IOPO vs.) by ERNIE-3.5 |
|---|---|---|---|
| safe world view | SFT DPO HING IPO KTO-PAIR | - - - - - | 44.8% vs. 21.6% vs. 33.6% 50.4% vs. 21.2% vs. 28.4% 49.2% vs. 20% vs. 30.8% 44.8% vs. 22% vs. 33.2% 48% vs. 21.6% vs. 30.4% |
| distilabel-capybara-dpo | SFT DPO RSO or HINGE IPO KTO-PAIR | 13%vs. 75%vs.12% 12%vs. 78% vs. 10% 10% vs. 78% vs. 12% 12%vs. 76% vs. 12% 12% vs. 78% vs. 10% | 65% vs. 3% vs. 32% 50% vs. 8% vs. 42% 53%vs. 18% vs. 39% 51% vs. 7% vs. 42% 48% vs. 7% vs. 46% |
| orpo-dpo-mix-4ok | SFT DPO HING IPO KTO-PAIR | 65%vs.0%vs.35% 53% vs. 0% vs. 47% 48% vs. o% vs. 52% 54% vs. 0% vs. 46% 65% vs. o% vs. 35% | 48% vs. 42% vs. 10% 50% vs. 34% vs. 16% 48% vs. 36% vs. 16% 46% vs. 32% vs. 22% 45% vs. 35% vs. 20% |
First, the ratio (πtµ (yw|x)/πtµ (yl|x)) resembles a function f(k) = k/(1 - k), where πtµ (yw|x) or k ∈ [0, 1]. The series Newton-Leibniz formula [Bos, 1980] expansion of f(k) is k + kΛ2 + kΛ3 + ... and the derivation of f(k), for k ∈ [0, 1] is positive. Our evaluations show that 1/2 < πtµ (yw|x) <= πt+1 µ (yw|x) is generally true, implying that (πtµ (yw|x)/πtµ (yl|x)) increases as πtν (yw|x) increases.
Second, the ratio πt+1 ν (yw|x)/πt+1 ν (yl|x) πtν (yw|x)/πtν (yl|x) remains constant.
Additionally, πt+1 ν (yw|x)/πt+1 ν (yl|x) πtν (yw|x)/πtν (yl|x) ≤ 1, similar to the aforementioned inequality, but with the opposite inequality sign when πtν (yw|x) ≥ πt+1 ν (yw|x).
In conclusion, (Qtµ -Qt-1 µ )/(Qt+1 µ -Qtµ ) <= 1 denotes that Qµ converge faster with rt (θ).
Theorem 3. As for sampling errors[Touvron et al., 2023], with high probability ≥ 1 - δ, in each iteration of Niter, for all (x, yw, yl) ∈ D , our reward function Q have a bound
where Cr,delta1 is a constant dependent on the concentration properties (variance) of r(x, yw, yl), CT,delta2 is a constant dependent on the concentration properties (variance) of T(xt+1 |xt , ytw , yt l ), α = ∏Nt=1 (1/rt (θ)) and |Q(yw > yl|x)| ≤ R(∀(x, yw, yl)).
Proof. We know that |r(s, a)| ≤ R(∀(s, a)) and then Q(s, a) ≤ R 1-γ with Bellman Iteration[Kakade and Langford, 2002] . We deduce that Qµ(yw ≻ yl | x) ≤ R 1-α , where |Q(yw > yl|x)| ≤ R(∀(x, yw, yl)) and α = ∏Nt=1 (1/rt (θ)).
For i iteration, r(θ)) < 1, we have ∏Nt=1 (1/rt (θ)) <= ∏Nt=i (1/rt (θ)).
Same as SAC [Haarnoja et al., 2018] or Conservative QLearning for Offline Reinforcement Learning[Kumar et al., 2020], for all (x, yw, yl) ∈ D , with high probability≥ 1-δ1,
where Cr,delta1 is a constant dependent on the concentration properties of r(x, yw, yl) and δ1 ∈ (0, 1), ˆ rθ(x, y) = β log πµ(y|x) πν(y|x) , ˆ rθ(x, y) and rθ(x, y) denote empirical distribution function and iterative stable empirical distribution function. Motivated by Eq.(21), we have
where CT,δ2 is a constant related to the concentration properties of T(xt+1 |xt , ytw , yt l ) with δ2 ∈ (0, 1). ˆ T (xt+1 |xt , ytw , yt l ) and T (xt+1 |xt , ytw , yt l ) represent the empirical and iterative stable empirical distribution function of the next action under policy π(µ, ν) at state (x, yw, yl).
Here are deductions with high probability ≥ 1 - δ:
| Baselines | Test set of safe world view | 250 pieces real-life online data | ||
|---|---|---|---|---|
| Margin reward | Pairwise accuracy | Win rate by ERNIE-3.5 | Mean value scored by human | |
| SFT | - | - | 13 : 204 : 10 : 23 | 2.156 |
| DPO | 23.75 | 0.9286 | 13 : 203 : 11 : 23 | 2.164 |
| Iter-DPO | 7.6875 | 0.961 | 13 : 204 : 11 : 22 | 2.152 |
| IOPO | 11.875 | 0.9659 | - | 2.176 |
6 Experiments
Our evaluations indicate that it performs well in assessing response quality for single-turn dialogues in single settings, multi-turn dialogues across multiple domains, and for both single-turn and multi-turn dialogues in multiple domains.
6.1 Datasets & Setting
There are three real-world data sets for the evaluation:
- safe world view contains 44k single-turn comparisons about world view demands, which is a real-world dataset sourced from Baidu.
- distilabel-capybara-dpo contains 7.56k multi-turn comparison data spanning math, medicine, computer science, history, and literature, among others. 1 .
- The orpo-dpo-mix-40k dataset contains 44.2k single and multi-turn comparisons across math, medicine, CS, history, and literature. It includes toxic-dpo-v0.2 to train models to reject illegal queries. Created via rule-based filtering (removing 2,206 GPTisms from argilla, unalignment, M4-ai, and jondurbin), it's suitable for highquality ORPO/DPO training. 2
We use Baichuan2-7B (base/chat) with standard SFT parameters. Training: learning rate lr = 2∗exp-7 , batchsize = 32, β = 0.1. IOPO matches DPO's sensitivity to hyperparameters except clipping, and is robust to ϵ(set to 0.3).
6.2 Comparison Algorithms &Metrics
To provide a comprehensive evaluation of our proposed method, we have designed a series of experiments involving several methods, as outlined below 3 :
- DPO [Rafailov et al., 2024]: Given preference data, DPO fits a binary classifier based on the Bradley-Terry model. DPO propose a sigmoid loss on the normalized likelihood by fitting a logistic log-sigmoid function.
- RSO or HINGE [Liu et al., 2023]: RSO proposes using a hinge loss on the normalized likelihood derived from the methodologies of SLiC and DPO.
2 https://hf-mirror.com/datasets/mlabonne/orpo-dpo-mix-40k
3 DPO, RSO, IPO, and KTO-PAIR code is detailed on HuggingFace at https://hf-mirror.com/docs/trl/dpo trainer.
- IPO [Azar et al., 2024]: IPO is also based on the reciprocal of the gap between the log-likelihood ratios of the chosen versus rejected completion pairs.
- KTO-PAIR [Ethayarajh et al., 2024]: Using a Kahneman-Tversky model of human utility, KTO-PAIR directly optimizes with human-aware losses (HALOs).
- SFT: The SFT model is optimized by training on datasets D = {(x(i) , y(i) w )}N i=1 .
- Iter-DPO: Building on prior works [Ouyang et al., 2022; Yuan et al., 2024; Xiong et al., 2024; Cheng et al., 2024], we employ LLMs (via DPO tuning) to generate preference comparison completions, annotated by ERNIE4.0 for iterative DPO learning: (i) Generate 40K-80K weekly samples using baidu's internal data; (ii) Annotate 250K completions ($0.0174/K tokens); (iii) Train on 50K samples (1:5 quality ratio, $1K); (iiii) Complete in 1-2 months.
We evaluate algorithms by measuring their Win rate (RWin vs RTie vs RLose) against a baseline policy, using sampling temperature 0.8 for generation and 0 for human-annotated ranking (scores 0-3). Proxies like ERNIE-3.5 and ZiyaLLaMA-7B-Reward assess dialogue quality. A 'bad case' is defined as human-rated 0 for both answers. Win rates are computed from toxic comparison datasets with out-ofdistribution model responses.
For better online performance evaluation, we split the safe world view dataset into two parts: 40k and 4k, using the 4k set for testing margin reward and pairwise accuracy. The margin reward is defined as the difference r(x, yw ) - r(x, yl ) for preference triplets, while pairwise accuracy is defined as r(x, yw ) > r(x, yl ).
6.3 Main Analysis
Shown as Table 1, our IOPO achieves the best performance (measured by win rate (RWin vs RTie vs RLose) among all methods, particularly with ERNIE-3.5. A more comparison details analysis via ERNIE-3.5 shown in appendix 4 .
While RSO/HING outperform IOPO on Ziya-7B in distilabel-capybara-dpo and orpo-dpo-mix-40k, IOPO performs better on ERNIE-3.5 due to: (1) Ziya's limited domain coverage (only 8.2% of its 40K training data comes from external sources), and (2) its smaller model size. Rationale for
4 https://arxiv.org/submit/6429160/view
(a) safe world view
(b) distilabel-capybara-dpo
Baseline Retention show as: Despite these limitations, we continue to use it as the baseline evaluator due to its exceptional ability to recognize toxic data and its official acknowledgment in GPT-4's benchmark.
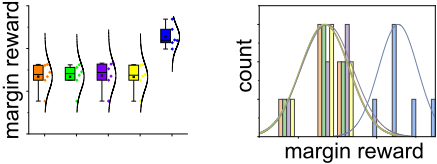
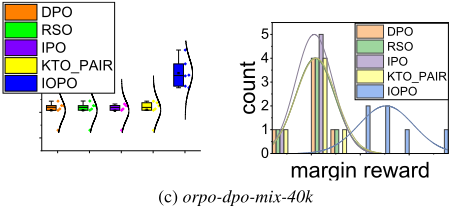
A more detailed analysis is presented in Fig.3, distribution shift is reflected in normal distribution and distribution of margin reward, where it shows that the margin reward of training procedure for three datasets. For distilabelcapybara-dpo, depicted in Fig.3(b), the small scale of the dataset and the multi-domain (especially math) hinder the margin reward from increasing and stabilizing. For orpodpo-mix-40k, depicted in Fig.3(c) the margin reward increases compared to other methods but exhibits scatter. All in all, distribution in Table.3 with win rate of IOPO vs. baseline in Table.1, highlights the superiority of our IOPO method.
6.4 Ablation Analysis
We conduct an ablation evaluation with IOPO and Iter-DPO starting from the LLMs after DPO to isolate external factors. The SFT model is trained on Baichuan2-7B-base, and the DPO model builds on this SFT model. Human evaluations of 250 data pieces yield mean scores: SFT via Baichuan27B-base scores 2.156, DPO via Baichuan2-7B-base scores 2.164, SFT via Baichuan2-7B-chat scores 2.148, and DPO
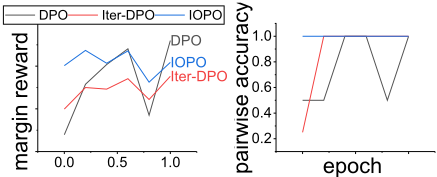
via Baichuan2-7B-chat also scores 2.148. To effectively implement the Iter-DPO algorithm and manage the high ranking costs of ERNIE-4.0 (approximately 50k high-quality inference data), we select Baichuan2-7B-base as the base model, filtering 50k inference data points at a 1:5 ratio of highquality to low-quality.
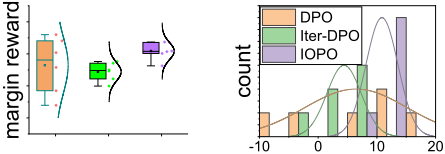
As shown in Table.2, our method outperforms all other methods. While the DPO model excels in margin reward, it lags behind Iter-DPO and IOPO in pairwise accuracy during testing due to its poor generalization performance. Additionally, human evaluations highlight that Iter-DPO encounters differences and modeling errors, resulting in lower mean value scored by human than the DPO model but higher pairwise accuracy than DPO. In factual and safety evaluations, our IOPO achieves a better win rate based on human annotations and scored the highest mean value scored by human at a temperature of 0. The training procedure as depicted in Fig.4, DPO and Iter-DPO scatter more divergently in margin reward on safe world view than IOPO. As depicted in Fig.5, our method's performances on margin reward and pairwise accuracy on test set of safe world view much more better than others. All in all, our method perform the best among all the methods in online evaluations.
7 Conclusions
In conclusion, we propose the Indirect Online Preference Optimization (IOPO) algorithm, which mitigates distribution shifts and modeling errors while preserving linear complexity. Experiments on three real-world datasets show that IOPO surpasses state-of-the-art methods, reducing iteration time from months to one week and significantly lowering annotation costs-especially in online scenarios.
Acknowledgments
This work is supported in part by National Key R&D Program of China under Grant Nos. 2022YFB3103700 and 2022YFB3103702, and National Natural Science Foundation of China under Grant Nos. 62272193, 62472194 and 62472196, and Jilin Science and Technology Research Project 20230101067JC.
@inproceedings{ijcai2025p61,
  title     = {Indirect Online Preference Optimization via Reinforcement Learning},
  author    = {Wang, En and Lin, Xingyu and Su, Du and Bao, Chenfu and Lv, Zhonghou and Yang, Funing and Xu, Yuanbo and Liu, Wenbin},
  booktitle = {Proceedings of the Thirty-Fourth International Joint Conference on
               Artificial Intelligence, {IJCAI-25}},
  publisher = {International Joint Conferences on Artificial Intelligence Organization},
  editor    = {James Kwok},
  pages     = {538--546},
  year      = {2025},
  month     = {8},
  note      = {Main Track},
  doi       = {10.24963/ijcai.2025/61},
  url       = {https://doi.org/10.24963/ijcai.2025/61},
}
TY - CPAPER TI - Indirect Online Preference Optimization via Reinforcement Learning AU - Wang, En AU - Lin, Xingyu AU - Su, Du AU - Bao, Chenfu AU - Lv, Zhonghou AU - Yang, Funing AU - Xu, Yuanbo AU - Liu, Wenbin T2 - Proceedings of the Thirty-Fourth International Joint Conference on Artificial Intelligence, IJCAI-25 PB - International Joint Conferences on Artificial Intelligence Organization PY - 2025 SP - 538 EP - 546 DO - 10.24963/ijcai.2025/61 UR - https://doi.org/10.24963/ijcai.2025/61 ER -Copied
Machine-readable versions of this paper, for tools and AI agents:





