
Improving Generalization in Meta-Learning via Meta-Gradient Augmentation
Proceedings of the Thirty-Fourth International Joint Conference on Artificial Intelligence. Main Track. Pages 6388-6396.
https://doi.org/10.24963/ijcai.2025/711
Keywords
- Machine Learning: ML: Few-shot learning
- Machine Learning: ML: Classification
- Machine Learning: ML: Ensemble methods
- Machine Learning: ML: Meta-learning
Abstract
Meta-learning methods typically follow a two-loop framework, where each loop potentially suffers from notorious overfitting, hindering rapid adaptation and generalization to new tasks. Existing methods address this by enhancing the mutual-exclusivity or diversity of training samples, but these data manipulation strategies are data-dependent and insufficiently flexible. This work proposes a data-independent Meta-Gradient Augmentation (MGAug) method from the perspective of gradient regularization. The key idea is first to break the rote memories by network pruning to address memorization overfitting in the inner loop, then use the gradients of pruned sub-networks to augment meta-gradients, alleviating overfitting in the outer loop. Specifically, we explore three pruning strategies, including random width pruning, random parameter pruning, and a newly proposed catfish pruning that measures a Meta-Memorization Carrying Amount (MMCA) score for each parameter and prunes high-score ones to break rote memories. The proposed MGAug is theoretically guaranteed by the generalization bound from the PAC-Bayes framework. Extensive experiments on multiple few-shot learning benchmarks validate MGAug's effectiveness and significant improvement over various meta-baselines.
- [Amit and Meir, 2018] Ron Amit and Ron Meir. Meta- learning by adjusting priors based on extended pac-bayes theory. In ICML, volume 80, pages 205-214, 2018.
- [Chen et al., 2019] Wei-Yu Chen, Yen-Cheng Liu, Zsolt Kira, Yu-Chiang Frank Wang, and Jia-Bin Huang. A closer look at few-shot classification. In ICLR, 2019.
- [D. A. McAllester, 2013] D. A. McAllester. A pac-bayesian tutorial with a dropout bound. CoRR, abs/1307.2118, 2013.
- [Finn et al., 2017] Chelsea Finn, Pieter Abbeel, and Sergey Levine. Model-agnostic meta-learning for fast adaptation of deep networks. In ICML, volume 70, pages 1126-1135, 2017.
- [Frankle and Carbin, 2019] Jonathan Frankle and Michael Carbin. The lottery ticket hypothesis: Finding sparse, trainable neural networks. In ICLR, 2019.
- [Frankle et al., 2021] Jonathan Frankle, Gintare Karolina Dziugaite, Daniel Roy, and Michael Carbin. Pruning neu- ral networks at initialization: Why are we missing the mark? In ICLR, 2021.
- [Gastaldi, 2017] Xavier Gastaldi. Shake-shake regulariza- tion. CoRR, abs/1705.07485, 2017.
- [Goldblum et al., 2020] Micah Goldblum, Liam Fowl, and Tom Goldstein. Adversarially robust few-shot learning: A meta-learning approach. In NeurIPS, 2020.
- [Guiroy et al., 2019] Simon Guiroy, Vikas Verma, and Christopher J. Pal. Towards understanding generalization in gradient-based meta-learning. CoRR, abs/1907.07287, 2019.
- [He et al., 2016] Kaiming He, Xiangyu Zhang, Shaoqing Ren, and Jian Sun. Deep residual learning for image recog- nition. In CVPR, pages 770-778, 2016.
- [Hospedales et al., 2021] Timothy M. Hospedales, Antreas Antoniou, Paul Micaelli, and Amos J. Storkey. Meta- learning in neural networks: A survey. IEEE Trans. Pat- tern Anal. Mach. Intell., PP(99):1-1, 2021.
- [Jamal and Qi, 2019] Muhammad Abdullah Jamal and Guo- Jun Qi. Task agnostic meta-learning for few-shot learning. In CVPR, pages 11719-11727, 2019.
- [Koh and Liang, 2017] Pang Wei Koh and Percy Liang. Un- derstanding black-box predictions via influence functions. In ICML, volume 70, pages 1885-1894, 2017.
- [Lee and Choi, 2018] Yoonho Lee and Seungjin Choi. Gradient-based meta-learning with learned layerwise met- ric and subspace. In ICML, volume 80, pages 2933-2942, 2018.
- [Lee et al., 2019] Namhoon Lee, Thalaiyasingam Ajanthan, and Philip H. S. Torr. Snip: single-shot network pruning based on connection sensitivity. In ICLR, 2019.
- [Lee et al., 2020] Haebeom Lee, Taewook Nam, Eunho Yang, and Sung Ju Hwang. Meta dropout: Learning to perturb latent features for generalization. In ICLR, 2020.
- [Li et al., 2017] Zhenguo Li, Fengwei Zhou, Fei Chen, and Hang Li. Meta-sgd: Learning to learn quickly for few shot learning. CoRR, abs/1707.09835, 2017.
- [Li et al., 2020] Weizhi Li, Gautam Dasarathy, and Visar Berisha. Regularization via structural label smoothing. In AISTATS, volume 108, pages 1453-1463, 2020.
- [Liu et al., 2020] Jialin Liu, Fei Chao, and Chih-Min Lin. Task augmentation by rotating for meta-learning. CoRR, abs/2003.00804, 2020.
- [Martins et al., 2023] Vinicius Eiji Martins, Alberto Cano, and Sylvio Barbon Junior. Meta-learning for dynamic tun- ing of active learning on stream classification. Pattern Recognit., 138:109359, 2023.
- [Ni et al., 2021] Renkun Ni, Micah Goldblum, Amr Sharaf, Kezhi Kong, and Tom Goldstein. Data augmentation for meta-learning. In ICML, volume 139, pages 8152-8161, 2021.
- [Rajendran et al., 2020] Janarthanan Rajendran, Alexander Irpan, and Eric Jang. Meta-learning requires meta- augmentation. In NeurIPS, 2020.
- [Selvaraju et al., 2020] Ramprasaath R. Selvaraju, Michael Cogswell, Abhishek Das, Ramakrishna Vedantam, Devi Parikh, and Dhruv Batra. Grad-cam: Visual explanations from deep networks via gradient-based localization. Int. J. Comput. Vis., 128(2):336-359, 2020.
- [Snell et al., 2017] Jake Snell, Kevin Swersky, and Richard S. Zemel. Prototypical networks for few-shot learning. In NIPS, pages 4077-4087, 2017.
- [Srivastava et al., 2014] Nitish Srivastava, Geoffrey E. Hin- ton, Alex Krizhevsky, Ilya Sutskever, and Ruslan Salakhutdinov. Dropout: a simple way to prevent neu- ral networks from overfitting. J. Mach. Learn. Res., 15(1):1929-1958, 2014.
- [Tabealhojeh et al., 2023] Hadi Tabealhojeh, Peyman Adibi, Hossein Karshenas, Soumava Kumar Roy, and Mehrtash Harandi. RMAML: riemannian meta-learning with or- thogonality constraints. Pattern Recognit., 140:109563, 2023.
- [Tanaka et al., 2020] Hidenori Tanaka, Daniel Kunin, Daniel L. K. Yamins, and Surya Ganguli. Pruning neural net- works without any data by iteratively conserving synaptic flow. In NeurIPS, 2020.
- [Tian et al., 2020] Hongduan Tian, Bo Liu, Xiao-Tong Yuan, and Qingshan Liu. Meta-learning with network pruning. In ECCV, volume 12364, pages 675-700, 2020.
- [Tseng et al., 2020] Hung-Yu Tseng, Yi-Wen Chen, Yi- Hsuan Tsai, Sifei Liu, Yen-Yu Lin, and Ming-Hsuan Yang. Regularizing meta-learning via gradient dropout. In ACCV, volume 12625, pages 218-234, 2020.
- [Vinyals et al., 2016] Oriol Vinyals, Charles Blundell, Tim Lillicrap, Koray Kavukcuoglu, and Daan Wierstra. Match- ing networks for one shot learning. In NIPS, pages 3630- 3638, 2016.
- [Wah et al., 2011] Catherine Wah, Steve Branson, Peter Welinder, Pietro Perona, and Serge Belongie. The caltech- ucsd birds-200-2011 dataset. Technical Report CNS-TR- 2011-001, California Institute of Technology, 2011.
- [Wang et al., 2020] Chaoqi Wang, Guodong Zhang, and Roger B. Grosse. Picking winning tickets before training by preserving gradient flow. In ICLR, 2020.
- [Wang et al., 2022] Ren Wang, Haoliang Sun, Xiushan Nie, and Yilong Yin. Snip-fsl: Finding task-specific lot- tery jackpots for few-shot learning. Knowl. Based Syst., 247:108427, 2022.
- [Witt, 2019] Jessica K Witt. Introducing hat graphs. Cogn. Res. Princ. Implic., 4(1):1-17, 2019.
- [Xu et al., 2021] Hui Xu, Jiaxing Wang, Hao Li, Deqiang Ouyang, and Jie Shao. Unsupervised meta-learning for few-shot learning. Pattern Recognit., 116:107951, 2021.
- [Yamada et al., 2019] Yoshihiro Yamada, Masakazu Iwa- mura, Takuya Akiba, and Koichi Kise. Shakedrop reg- ularization for deep residual learning. IEEE Access, 7:186126-186136, 2019.
- [Yang et al., 2020] Taojiannan Yang, Sijie Zhu, and Chen Chen. Gradaug: A new regularization method for deep neural networks. In NeurIPS, 2020.
- [Yao et al., 2021] Huaxiu Yao, Long-Kai Huang, Linjun Zhang, Ying Wei, Li Tian, James Zou, Junzhou Huang, and Zhenhui Li. Improving generalization in meta- learning via task augmentation. In ICML, volume 139, pages 11887-11897, 2021.
- [Yin et al., 2020] Mingzhang Yin, George Tucker, Mingyuan Zhou, Sergey Levine, and Chelsea Finn. Meta-learning without memorization. In ICLR, 2020.
- [Yoo et al., 2020] Jaejun Yoo, Namhyuk Ahn, and Kyung- Ah Sohn. Rethinking data augmentation for image super- resolution: A comprehensive analysis and a new strategy. In CVPR, pages 8372-8381, 2020.
- [Zhang et al., 2023] Yukun Zhang, Xiansheng Guo, Henry Leung, and Lin Li. Cross-task and cross-domain SAR tar- get recognition: A meta-transfer learning approach. Pat- tern Recognit., 138:109402, 2023.
References were extracted automatically from the PDF and may contain errors.
Full text extracted automatically from the PDF; figures, tables and equations may differ. The PDF is the version of record.
1 Introduction
Meta-learning aims to rapidly adapt to unseen tasks by observing learning processes over a wide range of tasks [Hospedales et al., 2021], and has been applied to various scenarios, including few-shot learning [Jamal and Qi, 2019; Xu et al., 2021], continual learning [Martins et al., 2023], transfer learning [Zhang et al., 2023], etc. Current prevalent meta-learning methods follow a unified two-loop framework [Goldblum et al., 2020]. In the outer loop, a meta-learner explores meta-knowledge from numerous tasks. Based on the meta-knowledge, base learners in the inner loop are expected to quickly fine-tune and adapt to new tasks.
∗Corresponding author
As indicated in [Guiroy et al., 2019; Yao et al., 2021], the two-loop framework potentially suffer from meta-overfitting in two aspects: memorization overfitting and learner overfitting. Memorization overfitting [Rajendran et al., 2020] means that the base learner handles tasks merely based on meta-knowledge rather than task-specific fine-tuning in the inner loop. In this way, meta-knowledge degenerates into rote memorization, which hinders rapid adaptation to new tasks. Learner overfitting [Yin et al., 2020] occurs when the metalearner overfits to insufficient training tasks, typically manifested by a meta-learner that can adapt quickly but still fails on new tasks. Those two forms of overfitting greatly degrade the generalization and robustness of meta-learning methods.
Data manipulation is a simple yet efficient strategy to tackle these two overfitting issues [Ni et al., 2021; Yao et al., 2021], including constructing mutually-exclusive tasks and conducting task-level augmentation. The former works on addressing memorization overfitting, where training tasks are independently assigned class labels to avoid the metalearner using rote memorization to handle tasks [Yin et al., 2020]. The latter aims to alleviate learner overfitting by augmenting the training tasks [Liu et al., 2020]. To simultaneously alleviate these two forms of overfitting, MetaMix [Yao et al., 2021] linearly combines features and labels of samples to increase the mutual-exclusivity and diversity of training tasks. However, these data manipulation strategies are manually designed for specific data or tasks, resulting in a lack of flexibility and generality in real-world applications. For example, most strategies that improve mutual-exclusivity and diversity for classification tasks are difficult to extend to regression tasks [Yin et al., 2020; Jamal and Qi, 2019; Yao et al., 2021]. More importantly, our experiments in Sec. 5.3 show that improving mutual-exclusivity is effective but short-lived, which means that simply increasing task mutualexclusivity is insufficient to combat memorization overfitting.
In this work, we improve generalization in meta-learning following the gradient regularization perspective and propose a data-independent Meta-Gradient Augmentation (MGAug). Considering that the meta-gradient is derived from the innerloop fine-tuning of base learners, our key idea is to first overcome memorization overfitting in the inner loop by breaking the rote memorization state, and then yield diversity gradients as the meta-gradient augmentation to alleviate learner overfitting in the outer loop. Specifically, memorization breaking is achieved by pruning the base learner before each inner loop. We explore three different levels of pruning strategies, named random width pruning (WP), random parameter pruning (PP), and catfish pruning (CP) 1 , respectively. The first two are based on random strategies and inspired by typical GradAug [Yang et al., 2020] and Dropout [Srivastava et al., 2014], respectively, while CP is a newly proposed unstructured pruning strategy that measures a Meta-Memorization Carrying Amount (MMCA) score for each parameter and prunes those with high scores to break the rote state more effectively. Once the rote memorization is removed, the pruned sub-network has to re-fine-tune the remaining parameters to handle new tasks, thus alleviating memorization overfitting. With different pruning rates, sub-networks produce gradients containing diverse task information as a high-quality metagradient augmentation to ultimately reduce learner overfitting. Contributions can be summarized in three aspects:
- We propose a novel data-agnostic meta-regularization via meta-gradient augmentation (MGAug), which can alleviate both memorization and learner overfitting in the two-loop meta-learning framework.
- We explore three pruning strategies to break rote memorization, including two existing random prunings and a new catfish pruning that measures a Meta-Memorization Carrying Amount (MMCA) score for each parameter.
- We deduce a PAC-Bayes-based generalization bound for two-loop meta-learning with inner-loop pruning and conduct extensive experiments on both mutuallyexclusive and non-mutually-exclusive tasks, providing theoretical guarantees and experimental validation.
2 RelatedWork
Regularization techniques prevent the model from overfitting the training data and can be roughly divided into data augmentation, label regularization, and internal changes. Data augmentation [Yoo et al., 2020] and label regularization [Li et al., 2020] modify the input and labels, respectively, using various transformations (e.g., flipping and noise addition) to increase sample diversity. In contrast, internal variation [Yang et al., 2020] emphasizes parameter diversity. The well-known Dropout [Srivastava et al., 2014] and its variants randomly remove some neurons to force the learner to capture more features. Shake-Shake [Gastaldi, 2017] and ShakeDrop [Yamada et al., 2019] are designed for a specific residual structure, giving different weights to each residual branch. The network pruning adopted in our MGAug belongs to an internal variation that prunes parameters to break the rote memorization state.
Meta regularization is specially designed for meta-learning to solve learner and memorization overfitting [Tabealhojeh et al., 2023]. For learner overfitting, well-designed task augmentation [Liu et al., 2020] remains an effective solution by increasing task diversity. Meta-MaxUp [Ni et al., 2021] splits the meta-framework and further explores various data augmentation combinations. In contrast, memorization overfitting occurs in the inner loop with only a few updates, invalidating most conventional regularization strategies [Yao et al., 2021]. Although constructing mutually-exclusive tasks [Lee et al., 2020] shows promise against memorization overfitting, the task-dependent property makes it difficult to extend mutual-exclusivity to regression and reinforcement learning scenarios [Yin et al., 2020]. MetaPruning [Tian et al., 2020] ignores inner loops and improves meta-generalization through data-agnostic network pruning. Instead, we argue that redundant memories in inner loops are the key cause of memorization overfitting [Guiroy et al., 2019]. MR-MAML [Yin et al., 2020] and TAML [Jamal and Qi, 2019] develop explicit meta-regularization terms to constrain the parameter scale and the base learner behavior, respectively. Unlike them, we directly break the rote memorization fetter via proposed catfish pruning and alleviate learner overfitting using derived augmented meta-gradients, which can also be considered an enhanced DropGrad [Tseng et al., 2020].
1 Catfish pruning is named after the "catfish effect", which forces sardines to reactivate by putting in catfish to avoid suffocation during transport. Here, sardines are base learner parameters that are forced to fine-tune tasks to avoid rote states by catfish pruning.
3 Meta Learning
Meta-learning is generally trained and tested on several tasks (here, we omit validation for brevity). To avoid confusion, we use the terms "support set" and "query set" to refer to training and test samples in a single task, leaving "training set" and "testing set" to the meta-learner. Given a set of training tasks {Tt = (Ds t , Dq t )} sampled from the task distribution p(T ), where Ds t = (xst , ys t ) is the support set containing support samples xst and corresponding labels ys t , and Dq t = (xqt , yq t ) is the query set containing query samples xqt and labels yq t . The goal of meta-learning is to produce a base learner that can quickly handle new tasks Tnew = (Dsnew ,Dqnew ), that is, fine-tune the support data (xsnew , ysnew ) and then accurately predict yqnew for xqnew . Considering the difficulty of constructing a large number of routine tasks, meta-learning algorithms are usually validated on few-shot tasks. When applied to classification scenarios, this is commonly described as a N-way K-shot task, indicating K samples in the support set, with class labels ys , yq ∈ {1, . . . ,N}.
Most meta-learning methods follow a two-loop framework [Goldblum et al., 2020]. The outer loop first involves sampling a batch of tasks {Tt}Tt=1 ∼ p(T ), and then updating meta-parameters based on the feedback derived from the inner loop over these tasks. In each inner loop, with the given meta-parameter ω and fine-tuning policy F, the base parameters are updated from θ(ω) to θt(ω) on support samples Ds t for the t-th task: θt(ω) = F(θ(ω),Ds t ). Therefore, the feedback is usually defined as the loss on query sample Dq t derived from the fine-tuned θt(ω). Let Louter denote the loss function in the outer loop, and metaparameters are finally optimized by minimizing empirical risk, i.e., argminω ∑t Louter(θt(ω),Dq t ). Without loss of generality, using the gradient descent, meta-update in the oth outer loop can be further formalized as
where β is the meta-learning rate and t is the task index.
Note that different meta-parameter deployments θ(ω) and fine-tuning algorithms F motivate different branches of metalearning methods. The well-known gradient-based metalearning (GBML) [Lee and Choi, 2018] takes ω as the initialization of base parameters θ and fine-tunes them by gradient descent, such as MAML [Finn et al., 2017], Meta-SGD [Li et al., 2017] etc. Formally, let Linner denote the loss in the inner loop, then F ≜ argminθ Linner(θ(ω),Ds t ). Similarly, after the o-th outer loop, the initialization and the i-th update of the base learner are
where α is the base learning rate. An alternative metric-based meta-learning (MBML) [Snell et al., 2017] meta-learns feature extractors and freezes them in inner loops, i.e., θt(ω) = θ(ω) = ω. This paper focuses on these two meta-learning branches, but MGAug can also be used for other branches [Goldblum et al., 2020] derived from two-loop framework.
4 Meta-Gradient Augmentation
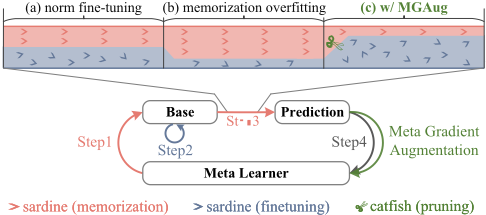
This work proposes MGAug to mitigate meta overfitting issues in a data-independent manner. The overall idea is to first overcome memorization overfitting using network pruning and then alleviate learner overfitting with derived augmented meta-gradients. Fig.1 shows the illustration of our MGAug with the proposed catfish pruning. Let's start by decomposing the meta-update into four steps: step 1 initializes base parameters θ(ω) based on ω; step 2 fine-tunes θ(ω) to θt(ω) on the support set of the t-th task; step 3 predicts the query sample based on θt(ω) and calculates loss values; step 4 updates ω once based on the average query error over a batch of tasks. Obviously, the query error is the key feedback for the update of meta-parameters and should be inferred jointly by metaknowledge (i.e., ω) and task-specific fine-tuning (Fig. 1 (a)). Memorization overfitting occurs as ω is trained enough to directly memorize query predictions while ignoring fine-tuning (Fig. 1 (b)), implying a degradation of rapid adaptability.
To avoid this, MGAug removes the parameters that carry the most meta-memorization using the proposed catfish pruning to enforce base learner re-fine-tune to the support set (Fig. 1 (c)). Each pruning is like throwing a catfish into sardines (i.e., base parameters), resulting in different subnetworks and fine-tuning results. The higher the pruning rate, the more significant the memorization break, and the more fine-tuning is required. After several independent pruning and fine-tuning stages, we obtain a set of augmented metagradients containing diversity task information, which are ultimately used to update the meta-learner. Taking the GBML as an example, the rest of this section details the inner and outer loops using our MGAug.
4.1 Inner-Loop with Network Pruning
Observe the inner loop process after the o-th outer loop, where the base parameters are initialized by the latest metalearned parameters, i.e., θ(ω) ≜ θo,0 = ωo . Let Fρ denote the pruning criterion. We can obtain the pruned sub-network parameters θo,0 ρ = Fρ(θo,0 , ρ) with a given pruning rate ρ, and rewrite the i-th update on the t-th task in (2) as
where α is the learning rate in the inner loop. For the pruning criterion Fρ, we explored three specific strategies whose ability to break rote memorization gradually increases at the same pruning rate. For brevity, we omit the superscripts of the inner and outer loops below.
Random width pruning (WP) is a structural pruning strategy that prunes the neurons in each layer of the network to meet the given pruning rate. Without loss of generality, we use the l-th convolutional layer parameter θ(l) ∈ Rdin×dout×k×k for illustration, where k represents the convolution kernel size and din and dout represent the number of input and output channels, respectively. For example, din is the channel number of input images in the first layer, and dout is the number of corresponding convolution kernels. The number of trainable parameters in this layer is n(l) = dout × k × k. With the pruning rate ρ ∈ [0, 1], the parameter of the corresponding layer in sub-networks is θρ,(l), where ∣∣θρ,(l) ∣∣ = n(l)(1 - ρ). Inspired by [Yang et al., 2020], we sampled the first (1-ρ)×100% from the entire model as the sub-network, that is, θρ,(l) ∈ Rdin×(1-ρ)dout×k×k .
Random parameter pruning (PP) is an unstructured pruning, where each parameter may be removed individually. Specifically, we introduce an indication mask m ∈ Rn consistent with the shape of base parameters θ, where n is the number of parameters and the value of m is randomly selected from the set {0, 1}. A position with a value of 0 in m indicates that the corresponding parameter is pruned, otherwise it is retained. Afterwards, the pruned parameters can be expressed as θρ = m⊙θ, where |m| ≤ n(1-ρ) and ⊙ is the Hadamard product. Compared to WP, PP achieves parameterlevel changes, enabling more flexible memorization breaking.
Catfish pruning (CP) is a novel task-oriented pruning strategy that enables stronger memorization breaking based on the current task and parameter state. Like PP, CP also needs an indicator mask m. The difference is that the mask value in CP reflects the amount of memory contained in each parameter rather than being randomly generated. Thus, we define the meta-memorization carrying amount and design a memorization-breaking pruning criterion.
Definition 1. (Meta-Memorization Carrying Amount). Let θ ∈ Rn denote the base learner parameter and e(j) be the indicator vector for the j-th parameter θ(j), whose value is zero everywhere except that index j is one. Keeping everything else constant, we measure the query loss difference in the t-th task before and after pruning parameter θ(j) to get the following Meta-Memorization Carrying Amount (MMCA):
where 1 is a vector of all ones with m dimension and ⊙ denotes the Hadamard product.
MMCA essentially measures the sensitivity of parameter θ(j) in solving task t. It is reasonable to represent the amount of memorization carried out here since the base parameters are initialized before each inner-loop by the meta parameters derived from the previous outer-loop. However, computing MMCA directly for each discrete parameter is prohibitively expensive as it requires n + 1 forward passes (n is the number of parameters). By relaxing the binary constraint on the indicator variable, we obtain an approximation of MMCA.
Proposition 1. For any task Tt = (Ds t , Dq t ), the change of loss value on Dq t before and after removing the j-th parameter θ(j) can be approximated by
We defer the proof to Appendix A. Similar approximation strategies [Koh and Liang, 2017; Lee et al., 2019] have also been used to measure the impact of a data point or connection on the loss. The key difference is that we leverage the fact that the query loss depends on meta-knowledge. Based on this MMCA score, we further compute the value of the binary mask m by the designed memorization-breaking pruning criterion. Similar to PP, the parameters θ(l) in the l-th layer are then pruned by θρ,(l) = m(l) ⊙θ(l), where ||m(l)||0/n(l) ≤ ρ, where n(l) is the number of parameters in the l-th layer.
Definition 2. (Memorization-breaking pruning criterion). Given a MMCA score mask, the parameters corresponding to the high score positions are removed to break the memorization state as much as possible, i.e.,
(6)
where (j, l) refers to the j-th parameter in the l-th layer.
Thus, we obtain a layer-level binary mask and can further compute the sub-network predictions via forwarding propagation. During backward propagation, we apply the same mask to the gradient so that the pruned parameters are no longer updated while the others are trained normally.
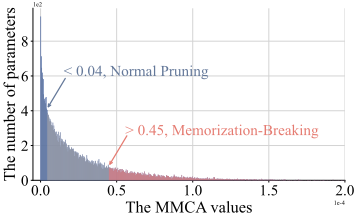
Remark 1. CP breaks rote memorization to combat memorization overfitting and generates augmented meta-gradients containing diversity task information, with two differences from connection-sensitivity-based network pruning methods [Koh and Liang, 2017; Tanaka et al., 2020; Frankle et al., 2021]. One is that CP prunes in the inner loop, so the criterion is based on the query set rather than the regular training samples [Wang et al., 2020]. Another essential difference is that normal pruning usually removes insensitive parameters for accuracy preservation, which is even the exact opposite of our memorization-breaking criterion [Frankle and Carbin, 2019; Wang et al., 2022]. We highlight this difference in Fig. 2 by visualizing the MMCA distribution of the last layer parameters in the Conv-4 backbone with a 20% pruning rate.
4.2 Outer-loop with AugmentedMeta-Gradients
We now obtain two group gradients with respect to the metaparameters wo : one is the (original) meta-gradients obtained by backward-propagation on the full network, and the other is derived from several pruned sub-networks. The former retains full meta-knowledge to speed the training process and avoid underfitting at the early learning stage. The latter is the meta-gradient augmentation resulting from network pruning. The meta-parameters are finally updated by accumulating these two-group gradients and formalized as
where U is a hyper-parameter representing the number of sub-networks in each task and θu,t(ω) is the parameter of the u-th sub-network for the t-th task. Since the meta-learner is trained with shared initialization parameters, it naturally shares diversity attention across all sub-networks, which is the key to combating learner overfitting. The entire procedure of MGAug is provided in Appendix C.
Remark 2. MGAug is designed for the two-loop metaframework and is quite different from the Dropout-style approaches [Srivastava et al., 2014; Tseng et al., 2020]. The former prunes base parameters before each inner loop in order to break the rote memorization state, while the latter directly prunes meta-parameters in the outer loop, essentially to alleviate learner overfitting.
Remark 3. The augmented meta-gradients derived from CP in MGAug are based on the task response rather than directly changing training tasks, which is also essentially different from the gradient noise strategy [Tseng et al., 2020].
4.3 A PAC-Bayes Generalization Bound
We provide a PAC-Bayes-based generalization bound [D. A. McAllester, 2013] for the two-loop meta-learning framework with inner-loop pruning, which gives a theoretical guarantee to our MGAug. To simplify the analysis, we prune a subnetwork for each task (i.e., U = 1). Following the PACBayes meta-learning framework [Amit and Meir, 2018], let P and Q be the hyper-prior and hyper-posterior of the metalearner, and assume that loss function is bounded to the interval [0, 1]. For a given pruning rate ρ ∈ [0, 1] and pruned initial parameters ωt of the base learner on task t, we take the pruned parameters distribution Qρ,ωt as posterior distribution and the corresponding Qρ,0 ∼ Q as the prior distribution.
Theorem 1. (Meta-learning PAC-Bayes bound with innerloop pruning). Let er(Q) and ˆ er(Qρ,ω, T ) be the expected and empirical errors in meta-learning, and let mt denote the number of samples in the t-th task. Then for any δ ∈ (0, 1] the following inequality holds uniformly for all hyper-posterior distributions Q with probability at least 1 - δ,
The expected error is bounded by the empirical multi-task error plus two complexity terms. The first is the average of task-complexity terms for observed tasks, and the second is the environment-complexity term [Amit and Meir, 2018]. MGAug prunes parameters in the inner loop, reducing the complexity cost of base learners by a factor of 1 - ρ and further reducing the task-complexity terms. Appendix B provides proof of Theorem 1.
5 Experiments
5.1 Experimental Settings
Datasets. We conduct experiments with two widely-used datasets: mini-ImageNet [Vinyals et al., 2016] and CUB [Wah et al., 2011]. Mini-ImageNet consists of 100 classes of natural images, with 600 images per class. It is split into non-overlapping 64, 16, and 20 classes for training, validation, and testing. The CUB contains 200 species of birds and 11, 788 images in total. We randomly select 100 classes as the training set, and the others are equally divided for validation and testing. Experiments involve 5-way 1-shot and 5shot tasks in both mutually exclusive (ME) and non-mutuallyexclusive (NME) settings [Yin et al., 2020].
Backbones. We use three backbones with different depths, including Conv-4, ResNet-10, and ResNet-18. The Conv-4 contains four convolution blocks, each block is concatenated by convolution, BatchNorm, nonlinear activation (ReLU), and max pooling layers. The ResNet-10 is a simplified ResNet-18 [He et al., 2016] where only one residual building block is used in each layer. Following previous works [Chen et al., 2019; Yang et al., 2020], we respectively resize images to 84×84 and 224×224 before feeding the Conv and ResNet backbones and randomly scale to [84, 64, 48] and [224, 192, 160, 140] as the basic augmentation.
Baselines. We choose MAML [Finn et al., 2017] and Prototypical Network [Snell et al., 2017] (abbreviated as ProtoNet) as GBML and MBML instance baselines, respectively. For MAML, we implement a first-order approximation FoMAML for efficiency [Finn et al., 2017]. We further take the transformations designed in Baseline++ [Chen et al., 2019] as the data regularization baseline and mark it with 'Aug'. Below, we mark the pruning strategy with "-XX" and make MGAugCP as the default setting, abbreviated as MGAug.
Implementation details. For 1-shot tasks, we respectively train 4800 and 1600 epochs for GBML and MBML methods, and each epoch includes 100 episodes. For 5-shot tasks, the number of epochs is halved. All results are average results over 600 episodes with confidence intervals of radius one standard error. Following the training procedure of [Chen et al., 2019], all methods are trained from scratch and use the Adam optimizer with 10-3 learning rate.
5.2 Comparison with existing meta-regularization
MBML-based strategies. The results of ProtoNet baseline with different meta-regularization methods are listed in Table 1, where the best results are marked in bold and the second-best with an underline. In addition to Aug [Chen et al., 2019], we also compare two state-of-the-art regularization methods designed for the MBML branch, including TaskAug [Liu et al., 2020], Meta-MaxUp [Ni et al., 2021]. Results show that memorization-breaking and augmented diversity gradients greatly improve classification accuracy. For example, in the 5-way 1-shot + ResNet-10 scenario, MGAug improves the accuracy by 6.96% and 6.67% on CUB and mini-ImageNet, respectively.
GBML-based strategies. Table 2 gives the results of FoMAML baseline with different meta-regularization methods, where the best results are marked in bold and the second with an underline. We compare four state-of-the-art regularization methods designed for the GBML branch, including MR [Yin et al., 2020], TAML [Jamal and Qi, 2019], MetaMix [Yao et al., 2021] and GradDrop [Tseng et al., 2020]. The former two design explicit regularization terms to address memorization and task bias issues in fast adaptation, respectively. The latter two are typical methods of data and gradient regularization, where MetaMix mixes the input and its features using the MixUp strategy and GradDrop randomly drops metagradients to increase its diversity. Compared to random-based strategies, gradient diversity in MGAug is learned by different sub-networks on the same task, which leads to self-guided augmentation and higher classification accuracy.
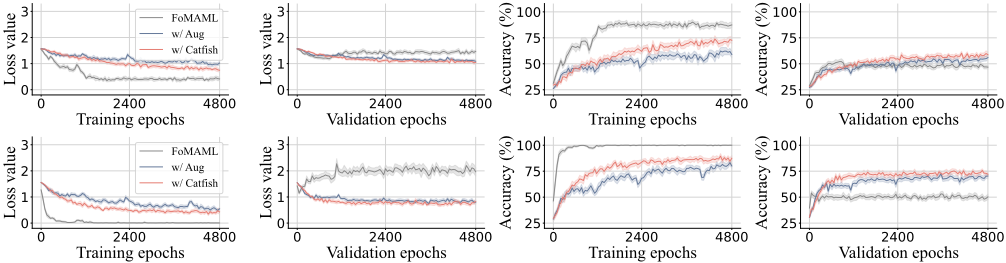
Besides accuracy, we plot the loss and accuracy curves in Fig. 3 to observe meta-overfitting in FoMAML baseline, Aug, and MGAug. Among them, the FoMAML baseline has the lowest loss and the highest accuracy during training, especially in CUB, while it performs the worst over validation epochs. This inversion is powerful evidence of overfitting. In contrast, Aug and MGAug do not significantly overfit the training task and generalize better to unseen tasks. Another interesting trend is the trade-off between training loss and validation accuracy. The training loss of MGAug is always lower than Aug, but it yields more accurate predictions. This phenomenon means that MGAug learns more generalizable meta-knowledge during training.
| CUB | miniImageNet | |||||||
|---|---|---|---|---|---|---|---|---|
| 5-way 1-shot | 5-way 5-shot | 5-way 1-shot | 5-way 5-shot | |||||
| Conv-4 | ResNet-10 | Conv-4 | ResNet-10 | Conv-4 | ResNet-10 | Conv-4 | ResNet-10 | |
| ProtoNet + Aug | 45.26±0.90 55.18±0.97 | 50.29±0.89 71.61±0.87 | 66.25±0.71 75.93±0.67 | 71.41±0.67 84.26±0.53 | 31.37±0.62 44.79±0.82 | 43.54±0.80 51.65±0.83 | 65.10±0.72 65.98±0.72 | 63.29±0.67 74.02±0.65 |
| + TaskAug +Meta-MaxUp | 57.64±0.97 59.79±0.90 | 73.44±0.89 75.20±0.85 | 78.21±0.65 78.86±0.57 | 85.78±0.50 86.02±0.42 | 42.55±0.78 45.47±0.82 | 56.33±0.89 57.52±0.82 | 63.97±0.76 66.22±0.72 | 74.79±0.65 74.83±0.60 |
| +MGAug-WP +MGAug-PP +MGAug-CP | 62.35±0.97 61.28±0.98 63.00±0.95 | 76.30±0.88 76.01±0.88 78.57±0.92 | 79.57±0.62 79.06±0.61 80.33±0.62 | 85.19±0.49 85.74±0.49 87.09±0.46 | 46.79±0.84 47.68±0.83 48.77±0.86 | 57.87±0.86 55.26±0.86 58.32±0.86 | 67.31±0.70 67.84±0.71 67.99±0.73 | 74.26±0.64 75.53±0.64 75.77±0.63 |
5.3 Behavioral Analysis of MGAug
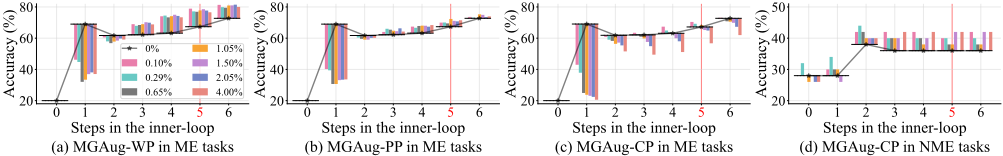
Rote memorization breaking. We observe the behavior of the base learner to investigate the memorization breaking in the inner loop. To this end, we visualize the gap in finetuning accuracy between the full-network and sub-networks with different pruning rates via a modified hat graph [Witt, 2019]. Fig. 4 shows the average accuracy of FoMAML with MGAug using ResNet-10 on 100 tasks sampled from CUB. Results for the full-network are indicated by the dashed line with asterisks. The histogram reflects the gap between the accuracy of sub-networks and the full-network, i.e., the upward bar indicates higher accuracy than the full-network and vice versa. The trend in Fig. 4 reflects whether fine-tuning relies on rote memorization or rapid adaptation of meta-knowledge.
- NME tasks suffer from severe memorization overfitting. Observing Fig. 4 (c) and (d), due to label mutual exclusion, each ME task cannot be handled solely on memorization, i.e., the accuracy at step-0 is similar to random classification and improves rapidly after fine-tuning. In contrast, for NME tasks, there is rote memorization in meta-learned parameters that resulted in
- 28% classification accuracy without fine-tuning (at step0) and further limited the fine-tuning performance.
- The ME setting is short-lived for solving memorization issues. Although the ME setting avoids the reliance on memorization at step-0, the accuracy increases sharply after only one step and remains almost unchanged until the step-5 (fine-tuning five steps by default [Finn et al., 2017]). This trend means that memorization is almost recovered with just one iteration and still prevents subsequent fine-tuning.
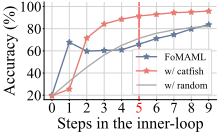
- Our MGAug breaks rote memorization. Unlike constructing ME tasks, MGAug directly breaks memorization and inhibits its recovery. An intuitive phenomenon is that accuracy slowly increases during fine-tuning, even with only a 0.1% pruning rate. Following the same ME setting, Fig. 5 visualizes fine-tuning curves to verify whether fine-tuning is reactivated with broken memorization, which is the key to overcoming memorization overfitting. Further, we plotted the curve fine-tuned from random initialization as a baseline with no memory at all. Clearly, the accuracy of MGAug has a consistent trend with random initialization but improves faster, indicating that the memorization issue is significantly alleviated and fine-tuning is reactivated to rapidly adapt to new tasks.
- CP has stronger breaking capability than WP and PP. All three prunings hindered memorization recovery, CP was the most effective, followed by PP, and finally WP (see step-1 in Fig. 4 (a), (b), and (c)).
| CUB | miniImageNet | |||||||
|---|---|---|---|---|---|---|---|---|
| 5-way 1-shot | 5-way 5-shot | 5-way 1-shot | 5-way 5-shot | |||||
| Conv-4 | ResNet-10 | Conv-4 | ResNet-10 | Conv-4 | ResNet-10 | Conv-4 | ResNet-10 | |
| FoMAML + Aug | 53.21±0.48 53.98±0.48 | 54.69±0.51 68.14±0.50 | 69.08±0.39 73.66±0.36 | 64.49±0.43 78.17±0.36 | 43.50±0.39 44.41±0.40 | 46.79±0.46 52.16±0.47 | 59.28±0.38 60.82±0.38 | 57.86±0.39 66.93±0.38 |
| 56.11±0.54 55.64±0.85 | 69.54±0.52 70.22±0.81 69.03±0.52 70.38±0.44 | 74.73±0.45 75.39±0.74 74.88±0.38 76.24±0.40 | 79.26±0.40 78.72±0.69 80.59±0.34 80.83±0.35 | 44.57±0.41 45.72±0.30 45.57±0.37 46.06±0.44 | 52.65±0.56 51.78±0.53 52.30±0.47 53.32±0.49 | 61.15±0.38 61.93±0.36 62.35±0.38 62.86±0.38 | 68.20±0.51 67.01±0.77 67.33±0.38 68.81±0.41 | |
| + MR | ||||||||
| + TAML | ||||||||
| + GradDrop + MetaMix | 55.39±0.51 | |||||||
| 57.53±0.53 | ||||||||
| +MGAug-WP | 56.85±0.50 | 70.73±0.46 | 75.89±0.42 | 81.53±0.44 | 45.65±0.32 | 52.97±0.45 | 61.34±0.40 | 67.53±0.39 |
| +MGAug-PP +MGAug-CP | 55.35±0.47 58.19±0.49 | 71.17±0.47 72.14±0.51 | 76.16±0.36 76.28±0.35 | 81.47±0.35 81.97±0.33 | 45.77±0.30 45.95±0.41 | 54.53±0.45 54.70±0.46 | 62.10±0.41 62.41±0.40 | 68.95±0.38 69.27±0.38 |
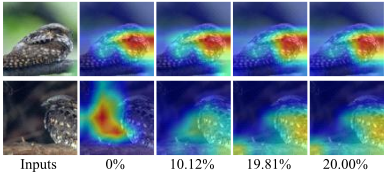
Augmented meta-gradients. We empirically infer that the effectiveness of the meta-gradient augmentation derived from pruned sub-networks is twofold. One is the improvement from resolving memorization overfitting, which has been verified in the previous subsection. The other is the diversity of attention introduced by sub-networks with different pruning rates, even for the same task. To verify this, Fig. 7 visualizes the attention regions of different sub-networks using Grad-CAM [Selvaraju et al., 2020] and lists representative examples. Interestingly, attention changes seem to occur more often in samples containing insignificant objects (bottom). Conversely, for the salient ones (top), the learner is more confident in the predictions.
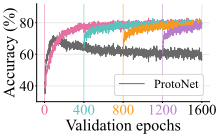
Plug-and-play property. In addition, MGAug can also improve meta-generalization in a flexible plug-and-play way. Fig. 6 shows the results of training with MGAug starting from epochs 0, 400, 800, and 1200 on 5-way 5-shot CUB tasks. Both train and test curves show that MGAug consistently improves ProtoNet baseline performance and avoids meta-overfitting, even if it is only used for the last 400 epochs.
6 Conclusion
This work proposes a data-independent meta-regularization method, termed MGAug, which alleviates both memorization and learner overfitting in the two-loop meta-learning framework. Unlike existing task augmentation and explicit regularization terms, the key idea is to first solve the rote memorization issue in the inner loop via network pruning and then alleviate learner overfitting with augmented meta-gradients derived from pruned sub-networks. We explore two random pruning strategies and propose a novel catfish pruning that achieves the most significant memorization breaking. We deduce a PAC-Bayes-based generalization bound for MGAug. Extensive experimental results show that MGAug significantly outperforms existing meta-learning baselines. We believe that MGAug's ideas can inspire and drive the development of regularization strategies in conventional learning.
Acknowledgments
The work is supported by Natural Science Foundation of Shandong Province (No. ZR2024MF101, ZR2024MF092), Young Expert of Taishan Scholars (No. tsqn202312026), Shandong Sci-tech SMEs Innovation Project (No. 2024TSGC0740), and Natural Science Foundation of China (No. U23A20389).
@inproceedings{ijcai2025p711,
  title     = {Improving Generalization in Meta-Learning via Meta-Gradient Augmentation},
  author    = {Wang, Ren and Sun, Haoliang and Lin, Yuxiu and Zhang, Xinxin and Yin, Yilong},
  booktitle = {Proceedings of the Thirty-Fourth International Joint Conference on
               Artificial Intelligence, {IJCAI-25}},
  publisher = {International Joint Conferences on Artificial Intelligence Organization},
  editor    = {James Kwok},
  pages     = {6388--6396},
  year      = {2025},
  month     = {8},
  note      = {Main Track},
  doi       = {10.24963/ijcai.2025/711},
  url       = {https://doi.org/10.24963/ijcai.2025/711},
}
TY - CPAPER TI - Improving Generalization in Meta-Learning via Meta-Gradient Augmentation AU - Wang, Ren AU - Sun, Haoliang AU - Lin, Yuxiu AU - Zhang, Xinxin AU - Yin, Yilong T2 - Proceedings of the Thirty-Fourth International Joint Conference on Artificial Intelligence, IJCAI-25 PB - International Joint Conferences on Artificial Intelligence Organization PY - 2025 SP - 6388 EP - 6396 DO - 10.24963/ijcai.2025/711 UR - https://doi.org/10.24963/ijcai.2025/711 ER -Copied
Machine-readable versions of this paper, for tools and AI agents:





