
From End-to-end to Step-by-step: Learning to Abstract via Abductive Reinforcement Learning
Proceedings of the Thirty-Fourth International Joint Conference on Artificial Intelligence. Main Track. Pages 6515-6523.
https://doi.org/10.24963/ijcai.2025/725
Keywords
- Machine Learning: ML: Multiagent Reinforcement Learning
- Machine Learning: ML: Neuro-symbolic methods/Abductive Learning
Abstract
Abstraction is a critical technique in general problem-solving, allowing complex tasks to be decomposed into smaller, manageable sub-tasks. While traditional symbolic planning relies on predefined primitive symbols to construct structured abstractions, its reliance on formal representations limits applicability to real-world tasks. On the other hand, reinforcement learning excels at learning end-to-end policies directly from sensory inputs in unstructured environments but struggles with compositional generalization in complex tasks with delayed rewards. In this paper, we propose Abductive Abstract Reinforcement Learning (A2RL), a novel neuro-symbolic RL framework bridging the two paradigms based on Abductive Learning (ABL), enabling RL agents to learn abstractions directly from raw sensory inputs without predefined symbols.
A2RL induces a finite state machine to represent high-level, step-by-step procedures, where each abstract state corresponds to a sub-algebra of the original Markov Decision Process (MDP). This approach not only bridges the gap between symbolic abstraction and sub-symbolic learning but also provides a natural mechanism for the emergence of new symbols. Experiments show that A2RL can mitigate the delayed reward problem and improve the generalization capability compared to traditional end-to-end RL methods.
- [Andre and Russell, 2002] David Andre and Stuart Russell. State abstraction for programmable reinforcement learn- ing agents. In Eighteenth National Conference on Arti- ficial Intelligence, page 119-125, Alberta, Canada, 2002. American Association for Artificial Intelligence.
- [Arjona-Medina et al., 2019] Jose A. Arjona-Medina, Michael Gillhofer, Michael Widrich, Thomas Unterthiner, Johannes Brandstetter, and Sepp Hochreiter. Rudder: Return decomposition for delayed rewards. In Advances in Neural Information Processing Systems, volume 32.
- Curran Associates, Inc., 2019.
- [Bai et al., 2016] Aijun Bai, Siddharth Srivastava, and Stuart Russell. Markovian state and action abstractions for mdps via hierarchical MCTS. In Proceedings of the Twenty-Fifth International Joint Conference on Artificial Intelligence, pages 3029-3039, New York, NY, 2016. IJCAI/AAAI Press. IJCAI
- [Chen et al., 2021] Lili Chen, Kevin Lu, Aravind Ra- jeswaran, Kimin Lee, Aditya Grover, Misha Laskin, Pieter Abbeel, Aravind Srinivas, and Igor Mordatch. Decision transformer: Reinforcement learning via sequence model- ing. In Advances in Neural Information Processing Sys- tems, volume 34, pages 15084-15097, 2021.
- [Chevalier-Boisvert et al., 2023] Maxime Chevalier- Boisvert, Bolun Dai, Mark Towers, Rodrigo de Lazcano, Lucas Willems, Salem Lahlou, Suman Pal, Pablo S. Castro, and Jordan Terry. Minigrid & miniworld: Modular & customizable reinforcement learning environments for goal-oriented tasks. In Advances in Neural Information Processing Systems, volume 36, New Orleans, LA, 2023.
- [Croonenborghs et al., 2007] Tom Croonenborghs, Kurt Driessens, and Maurice Bruynooghe. Learning relational options for inductive transfer in relational reinforcement learning. In Proceedings of the 17th International Con- ference on Inductive Logic Programming, page 88-97, 2007.
- [Dai and Muggleton, 2021] Wang-Zhou Dai and Stephen H. Muggleton. Abductive knowledge induction from raw data. In Proceedings of the Thirtieth International Joint Conference on Artificial Intelligence, pages 1845-1851, Montreal, Canada, 2021. ijcai.org. IJCAI
- [Dai et al., 2019] Wang-Zhou Dai, Qiu-Ling Xu, Yang Yu, and Zhi-Hua Zhou. Bridging machine learning and logi- cal reasoning by abductive learning. In Advances in Neu- ral Information Processing Systems 32, pages 2811-2822.
- Curran Associates, Inc., 2019.
- [Delfosse et al., 2023] Quentin Delfosse, Hikaru Shindo, Devendra Dhami, and Kristian Kersting. Interpretable and explainable logical policies via neurally guided symbolic abstraction. In Advances in Neural Information Process- ing Systems, volume 36, pages 50838-50858, 2023.
- [Dietterich, 2000] Thomas G. Dietterich. Hierarchical re- inforcement learning with the MAXQ value function de- composition. Journal of artificial intelligence research, 13(1):227-303, 2000.
- [Furelos-Blanco et al., 2023] Daniel Furelos-Blanco, Mark Law, Anders Jonsson, Krysia Broda, and Alessandra Russo. Hierarchies of reward machines. In Proceedings of the Fortieth International Conference on Machine Learn- ing, ICML'23, Honolulu, Hawaii, 2023. JMLR.org.
- [Gold and Shadlen, 2007] Joshua I. Gold and Michael N. Shadlen. The neural basis of decision making. Annual review of neuroscience, 30:535-74, 2007.
- [Ha and Schmidhuber, 2018] David Ha and Jürgen Schmid- huber. Recurrent world models facilitate policy evolution. In Advances in Neural Information Processing Systems, volume 31, 2018.
- [Hasselt et al., 2016] Hado van Hasselt, Arthur Guez, and David Silver. Deep reinforcement learning with double q- learning. In Proceedings of the Thirtieth AAAI Conference on Artificial Intelligence, AAAI'16, page 2094-2100, Phoenix, Arizona, 2016. AAAI Press.
- [Jiang and Luo, 2019] Zhengyao Jiang and Shan Luo. Neu- ral logic reinforcement learning. In Proceedings of the Thirty-Six International Conference on Machine Learning, volume 97, pages 3110-3119, 2019.
- [Jiang et al., 2019] YiDing Jiang, Shixiang (Shane) Gu, Kevin P Murphy, and Chelsea Finn. Language as an ab- straction for hierarchical deep reinforcement learning. In Advances in Neural Information Processing Systems, vol- ume 32, 2019.
- [K et al., 2023] Namasivayam K, Himanshu Singh, Vishal Bindal, Arnav Tuli, Vishwajeet Agrawal, Rahul Jain, Parag Singla, and Rohan Paul. Learning neuro-symbolic programs for language guided robot manipulation. In 2023 IEEE International Conference on Robotics and Automa- tion (ICRA), pages 7973-7980, 2023.
- [Kahneman, 2011] Daniel Kahneman. Thinking, fast and slow. Farrar, Straus and Giroux, New York, 2011.
- [Kersting et al., 2004] Kristian Kersting, Martijn Van Ot- terlo, and Luc De Raedt. Bellman goes relational. In Pro- ceedings of the Twenty-First International Conference on Machine Learning, page 59, 2004.
- [Korf, 1987] Richard E. Korf. Planning as search: a quanti- tative approach. Artificial Intelligence, 33(1):65-68, 1987.
- [Ladosz et al., 2022] Pawel Ladosz, Lilian Weng, Minwoo Kim, and Hyondong Oh. Exploration in deep reinforce- ment learning: A survey. Information Fusion, 85:1-22, 2022.
- [Levy et al., 2019] Andrew Levy, George Konidaris, Robert Platt, and Kate Saenko. Learning multi-level hierarchies with hindsight. In The Seventh International Conference on Learning Representations, 2019.
- [Liu et al., 2024] Jung-Chun Liu, Chi-Hsien Chang, Shao- Hua Sun, and Tian-Li Yu. Integrating planning and deep reinforcement learning via automatic induction of task substructures. In The Twelfth International Conference on Learning Representations, 2024.
- [Mnih et al., 2015] Volodymyr Mnih, Koray Kavukcuoglu, David Silver, Andrei A. Rusu, Joel Veness, Marc G. Belle- mare, Alex Graves, Martin Riedmiller, Andreas K. Fid- jeland, Georg Ostrovski, Stig Petersen, Charles Beattie, Amir Sadik, Ioannis Antonoglou, Helen King, Dharshan Kumaran, Daan Wierstra, Shane Legg, and Demis Has- sabis. Human-level control through deep reinforcement learning. Nature, 518(7540):529-533, 2015.
- [Parać et al., 2024] Roko Parać, Lorenzo Nodari, Leo Ar- don, Daniel Furelos-Blanco, Federico Cerutti, and Alessandra Russo. Learning robust reward machines from noisy labels. In Proceedings of the Twenty-first Interna- tional Conference on Principles of Knowledge Represen- tation and Reasoning, KR '24, Hanoi, Vietnam, 2024.
- [Pateria et al., 2021] Shubham Pateria, Budhitama Sub- agdja, Ah-hwee Tan, and Chai Quek. Hierarchical rein- forcement learning: A comprehensive survey. ACM Com- puting Surveys(CSUR), 54(5), 2021.
- [peng et al., 2022] shaohui peng, Xing Hu, Rui Zhang, Ke Tang, Jiaming Guo, Qi Yi, Ruizhi Chen, xishan zhang, Zidong Du, Ling Li, Qi Guo, and Yunji Chen. Causality- driven hierarchical structure discovery for reinforcement learning. In Advances in Neural Information Processing Systems, volume 35, pages 20064-20076, 2022.
- [Ratcliff and McKoon, 2008] Roger Ratcliff and Gail McK- oon. The diffusion decision model: Theory and data for two-choice decision tasks. Neural Computation, 20:873- 922, 2008.
- [Russell, 2015] Stuart Russell. Unifying logic and probabil- ity. Communications of the ACM, 58(7):88-97, 2015.
- [Schulman et al., 2017] John Schulman, Filip Wolski, Pra- fulla Dhariwal, Alec Radford, and Oleg Klimov. Proximal policy optimization algorithms. CoRR, abs/1707.06347, 2017.
- [Sutton and Barto, 2018] Richard S. Sutton and Andrew G. Barto. Reinforcement Learning: An Introduction. A Brad- ford Book, Cambridge, MA, 2018.
- [Towers et al., 2024] Mark Towers, Ariel Kwiatkowski, Jor- dan Terry, John U Balis, Gianluca De Cola, Tristan Deleu, Manuel Goulão, Andreas Kallinteris, Markus Krimmel, Arjun KG, et al. Gymnasium: A standard interface for reinforcement learning environments. arXiv preprint arXiv:2407.17032, 2024.
- [Unruh and Rosenbloom, 1989] Amy Unruh and Paul S. Rosenbloom. Abstraction in problem solving and learning. In Proceedings of the 11th International Joint Conference on Artificial Intelligence -Volume 1, pages 681-687, CA, USA, 1989. IJCAI
- [Morgan Kaufmann. Wang et al., 2016] Ziyu Wang, Tom Schaul, Matteo Hes- sel, Hado Van Hasselt, Marc Lanctot, and Nando De Fre- itas. Dueling network architectures for deep reinforce- ment learning. In Proceedings of the Thirty-Third Inter- national Conference on International Conference on Ma- chine Learning -Volume 48, ICML'16, page 1995-2003, New York, NY, 2016. JMLR.org.
- [Yang et al., 2018] Fangkai Yang, Daoming Lyu, Bo Liu, and Steven Gustafson. Peorl: Integrating symbolic plan- ning and hierarchical reinforcement learning for robust decision-making. In Proceedings of the Twenty-Seventh International Joint Conference on Artificial Intelligence, IJCAI-18, pages 4860-4866, 2018. IJCAI
- [Zhou and Huang, 2021] Zhi-Hua Zhou and Yu-Xuan Huang. Abductive learning. In Pascal Hitzler and Md. Kamruzzaman Sarker, editors, Neuro-Symbolic Artificial Intelligence: The State of the Art, volume 342 of Frontiers in Artificial Intelligence and Applications, pages 353-369. IOS Press, 2021.
- [Zhou, 2019] Zhi-Hua Zhou. Abductive learning: towards bridging machine learning and logical reasoning. Science China Information Sciences, 62(7), 2019.
- [Zhu et al., 2020] Shengyu Zhu, Ignavier Ng, and Zhitang Chen. Causal discovery with reinforcement learning. In The Eighth International Conference on Learning Repre- sentations, 2020.
References were extracted automatically from the PDF and may contain errors.
Full text extracted automatically from the PDF; figures, tables and equations may differ. The PDF is the version of record.
1 Introduction
Abstraction is a powerful skill in problem-solving, which is able to reduce exponential problems to linear complexity [Korf, 1987]. It divides a difficult task into a set of subgoals, which are organized and solved step-by-step according to their dependencies. In traditional planning, a task abstraction is usually represented as a procedure and defined with formal languages [Unruh and Rosenbloom, 1989], while relying on predefined symbolic predicates and operators to model the abstract structures, which strongly limits their application in many real tasks having only sub-symbolic inputs.
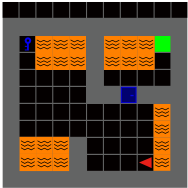
In contrast, reinforcement learning (RL), especially Deep Reinforcement Learning (DRL), learns end-to-end policies and value functions directly from sensory inputs [Sutton and Barto, 2018; Mnih et al., 2015], allowing it to adapt to diverse and unstructured environments without relying on predefined symbols or abstractions. This flexibility has led to (D)RL's success in a wide range of domains where abstractions might not be immediately available or easily defined. However, when the task is too complicated and the reward is delayed, this end-to-end feature of modern RL methods limits their compositional and sequential generalization capabilities [Arjona-Medina et al., 2019; Ladosz et al., 2022].
For instance, Figure 1 illustrates a task that presents challenges for many standard DRL methods. The environment is a grid world generated by Minigrid [Chevalier-Boisvert et al., 2023], where an agent must navigate towards the goal while avoiding lava blocks . Additionally, the environment may feature a locked door , obstructing the path to the goal. To proceed, the agent might need to acquire a key to unlock the door. Since the positive reward is only granted when the agent reaches the goal , actions such as obtaining or unlocking do not offer immediate feedback to the RL algorithm. As a result, without incorporating any inductive bias, learning a successful end-to-end policy in this environment becomes challenging.
This paper aims to bridge the gap between sub-symbolic RL and symbolic abstraction. We introduce the Abductive Abstract Reinforcement Learning (A2RL) framework, which employs an impasse-driven abstraction strategy [Unruh and Rosenbloom, 1989] to decompose a complex Markov Decision Process (MDP) into a series of sub-tasks, where each of them is modelled as a sub-MDP of the original problem. A2RL then constructs an Abstract State Machine (ASM) to formally represent the abstract procedure for solving these sub-tasks step-by-step. Finally, using the induced ASM structure, it trains end-to-end policies for each sub-MDP within the Abductive Learning (ABL) framework [Dai et al., 2019; Zhou, 2019].
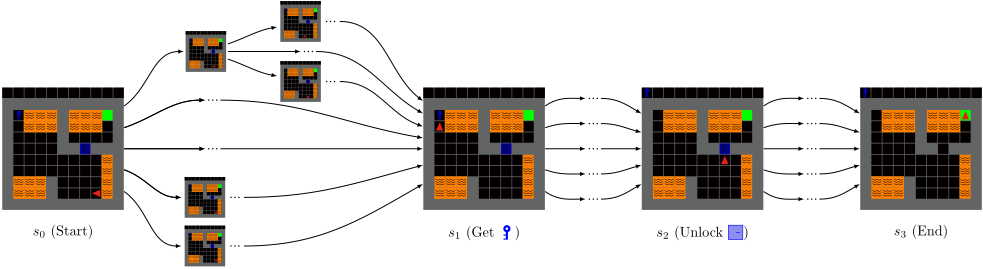
Another motivation of this paper is to explore the possibility of defining an "open-universe language that can infer the existence of objects from raw data (such as pixels, strings, etc.) that contain no explicit object references" [Russell, 2015]. We demonstrate that by transforming an end-toend MDP into a step-by-step ASM, the transitions between abstract states naturally reveal new symbols from raw data, as shown in Figure 2. We conducted experiments on two sets of benchmark tasks, and the results showed that A2RL effectively learned the abstract structure, improving performance and easing the challenge of learning from delayed feedback. Additionally, a series of randommap tests show that the policies learned by A2RL exhibit better generalization ability, as they can be easily reused and adapted to unseen tasks.
The rest of the paper is organized as follows. Section 2 covers the preliminaries, while Sections 3 and 4 formally define the Abductive Abstract Reinforcement Learning (A2RL) framework and explain its implementation. Section 5 presents the experiments and discussion, Section 6 reviews related work that inspired this study, and Section 7 concludes.
2 Preliminaries
Markov Decision Process. A Markov Decision Process (MDP) M is a tuple ⟨S, A, P, R, γ⟩, where S is state space; A is the action space; P : S ×A× S → [0, 1] is the transition probability function. P(s′ |s, a) is the probability of transitioning to state s′ from state s after taking action a; R : S × A → R is the reward function. R(s, a, s′ ) is the immediate reward received after taking action a in state s and reach s′ ; and γ ∈ [0, 1] is the discount factor, which represents the difference in importance between future rewards and present rewards. The objective in an MDP is to find a policy π : S → A, which maximizes the expected sum of discounted rewards over time, defined as the value function V π (s) = Eπ [∑∞t=0 γ tR(st, at) | s0 = s], where at = π(st).
State Abstraction. State abstraction is a process that groups a large amount of low-level ground states into a smaller set of high-level abstract states [Kersting et al., 2004]. Formally, given a MDP with a raw state space S, an abstract state σ ⊆ S is a set of ground states. All abstract states form a countable set Σ = {σ0, σ1, σ2, . . .}.
An abstraction function ϕ is an indicator function, where ϕ(s) = j iff s ∈ σj .
Abductive Learning. Abductive Learning (ABL) [Zhou, 2019; Zhou and Huang, 2021] is a hybrid neuro-symbolic (NeSy) framework that combines machine learning and logical reasoning through a defined interface. The machine learning model processes raw environmental data and translates it into logical facts, which the reasoning model uses for inference. If inconsistencies arise-when the perceived facts fail to deduce correct outputs-a hybrid optimization process adjusts the flawed perceptions and uses these corrections to retrain the machine learning model [Dai et al., 2019]. When the logical knowledge base is incomplete (e.g., missing rules to reason about the facts), the framework can also induce the missing rules while jointly training the perception model [Dai and Muggleton, 2021].
Previous work in ABL has focused primarily on classification problems, where machine learning models classify raw inputs and produce probabilistic monadic logical facts like "0.9 :: one( )" [Dai et al., 2019; Dai and Muggleton, 2021]. This paper extends this paradigm by modelling machine learning models as dyadic predicates, representing atomic procedures for constructing complex strategies for RL. Additionally, the reasoning model provides an openuniverse language (i.e., the primitive symbols are unknown), allowing the agent to build a rule-based, step-by-step procedure from scratch. For example, a two-step policy could be expressed as:π∗ (a, b) ← π0→1(a, c) ∧ π1→2(c, b)
where π∗ /2 and πi→j/2 in bold font are dyadic predicates representing the state-transition procedures derived from policy functions π∗ and πi→j; their arguments a, b, c are states in the raw state space S. The above rule can be translated to natural language as "Applying policy π∗ to transition from state a to state b can be divided into two steps: execute π0→1 from a to c, and then apply π1→2 from c to b".
3 Framework
In this section, we introduce the Abductive Abstract Reinforcement Learning (A2RL) framework, which is formalized based on the Abstract State Machine (ASM).
Definition 1 (Abstract State Machine). For a ground MDP M = ⟨S,A, P,R, γ⟩, a step-by-step abstraction for M is an Abstract State Machine ∆ = ⟨Σ, T , P,R′ , γ⟩, where Σ = {σ | σ ⊆ S} is a countable set of abstract states; T = {τi→j | τi→j = t(σi) ∩ s(σj)} is a countable set of abstract state transitions; s(σ) and t(σ) are the subsets of initial states and terminate states of σ, respectively; R′ = {R}∪{Rσ 0 , Rσ 1 , . . .} is a set of augmented reward functions, and each Rσ i is associated with abstract state σi. 1
Figure 3a illustrates an example of MDP abstraction. The key idea is to segment an RL agent's trajectory into sequential steps. This divide-and-conquer strategy reflects human decision-making. We employ automatic, intuitive processing (System 1) for simple tasks, relying on learned responses like "muscle memory". For complex tasks, we engage deliberate, analytical processing (System 2'), decomposing the task into sub-tasks. If a sub-task is sufficiently simple, we revert to System 1; otherwise, we further decompose it [Kahneman, 2011]. A2RL adopts this approach and models abstracted steps as sub-MDPs solved by atomic policy functions.
1 This paper uses Latin letters to denote ground states and actions, while abstract states and transitions are denoted by Greek letters.
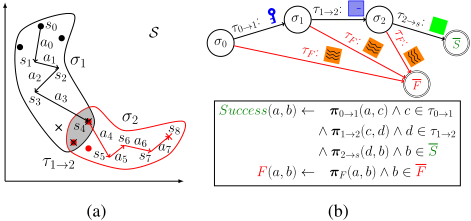
Definition 2 (Sub-MDP and Atomic Policy). Given an ASM ∆ = ⟨Σ, T, P,R′ , γ⟩, the sub-MDP for an abstract state σi is a MDP Mσi = ⟨σi,A, P,Rσ i , γ⟩, whose objective is to learn Atomic Policy functions π : σi → A that navigates the agent from s(σi) to t(σi) while maximising the accumulated reward, which is calculated with the augmented reward function Rσ i : σi ×A→R.
To ensure proper execution of the abstract plan, the transition τi→j enforces the nose-to-tail constraint betweenMσi andMσj , represented by logic rules or a graph model such as Figure 3b. If an abstract state σj serves as a terminal state, then τ∗→i = s(σi) = t(σi), where "∗" represents "any number in N". Since sub-MDP goals usually offer no rewards in the original MDP, a mental reward θi is introduced to define the augmented reward function Rσ i . Formally,
Note that there might be multiple j satisfying τi→j ⊆ t(σi), i.e., σi has more than one outgoing edge, soMσi could have multiple atomic policies as its options [Bai et al., 2016].
Next, we formally define the Abductive Abstract Reinforcement Learning (A2RL) task.
Definition 3 (Abductive Abstract Reinforcement Learning). Given a ground MDP M = ⟨S,A, P,R, γ⟩, the target for Abductive Abstract Reinforcement Learning is to:
- Discover a set of abstract states Σ = {σ0, . . .} to construct the ASM ∆ = ⟨Σ, T , P, R′ , γ⟩;
- Induce the abstract transition model T ;
- Learn a set of state abstraction functions Φ, where each ϕi : S → {T, F} such that ϕi(s) = T iff s ∈ σi;
- Solve the sub-MDPs derived from∆ by training atomic policy πi→j for each state transition option τi→j.
As we can see, target I and II correspond to the logic reasoning model in the ABL framework, while target III and IV belong to the machine learning part. Specifically, target I requires the agent to infer the existence of logic symbols from raw data; target II learns a perception model mapping raw input to the logic symbols; target III induces a set of first-order logic rules to establish the relations between the discovered symbols; target IV learns a set of dyadic neural predicates to interface the logic rules with the sub-symbolic environment.
Note that A2RL only provides a language-first-order logic-to construct the ASM. Most of the symbols, including the abstract states and the primitive predicates for constructing the transition rules, are undefined and have to be discovered from raw data.
Object Discovery. Let's rethink the question in [Russell, 2015]: can machine learning infer the existence of objects from raw data that contain no explicit object references? A2RL tries to answer it positively by defining object as an
1 - pexploit
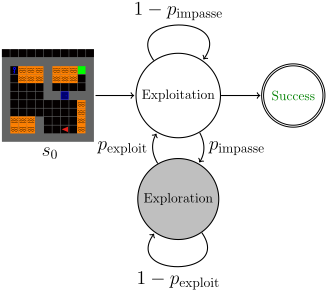
Figure 4: The impasse-driven exploration-exploitation of A2RL.
abstract state transition function that generalises across domains. For example, a key is an object that unlocks another object blocking the agent's way. In other words, the function of key is the most important thing for this concept, since it helps the agent change from a blocked state to unblocked, no matter it is a in Minigrid, a bomb in The Legend of Zelda, or a rune stone in Tomb Raider. As shown in Figure 2 and 3b, one can easily learn the visual representation of an object and define the concept with logic rules from the state transitions of an ASM, which is induced from raw data.
Recursion. From an algebraic perspective, a sub-MDP forms a subalgebra of the original MDP, as its state space is a subset of the original and preserves the original MDP's algebraic structure. This definition enables the recursive division of sub-MDPs until it is trivial to solve. It not only simplifies the problem space but also maintains expressive completeness (with the aid of first-order logic language). Moreover, this recursive framework potentially offers a robust mathematical structure for further analysis and exploration.
4 Implementation
This section introduces a preliminary implementation for A2RL. Firstly, it tries to discover the novel abstract state σi using an impasse-driven strategy [Unruh and Rosenbloom, 1989]. Then it samples trajectories of σi by exploring the environment. Finally, abductive learning is applied to update the state abstraction function ϕ, the transition model T , and learns the associated atomic policies πi→j .
4.1 Abstract State Discovery
As illustrated in Figure 2, a sample of ground MDP trajectories is required to discover the abstract state from raw inputs. In this paper, the data is collected through an impasse-driven exploitation-exploration procedure, as illustrated in Figure 4.
Exploitation. The exploitation is straightforward. Given an ASM ∆ = ⟨Σ, T , P, R′ , γ⟩ and an input ground state st, the state abstraction function ϕ is called to identify its abstract state σ. A2RL then uses the abstract state transition T to calculate the optimal abstract plan Π∗-a path from σi to the target abstract state. Finally, the plan Π∗ is executed step-bystep in the sub-symbolic environment by calling the atomic policies πi→j in this path. The abstract plan Π∗ always exists, since each πi→j is the best policy that maximises the reward in sub-MDPMσi , and the transition rules τi→j are correct.
Impasse. Nevertheless, when the current ASM ∆ = ⟨Σ, T , P, R′ , γ⟩ represents an incomplete abstraction, the existing atomic policies may fail to construct an abstract plan capable of reaching the goal state from the initial state s0. For example, in the Minigrid task illustrated in Figure 1, if the ASM contains only a single abstract state σ0 = {s | door is open in s}, the state abstraction function ϕ, implemented by a computer vision model, will classify any state s ∈ S as σ0 since it is the sole option. Under the state transition rule Success(a, b) ←π0→goal(a, b) ∧ (b = agent at ), the optimal plan Π∗ includes only one end-to-end atomic policy, π0→goal. This policy, however, is unlikely to successfully navigate the agent to the goal in environments where the door is closed. In such cases, we say that ∆ encounters an impasse.
In this paper, we employ the Drift Diffusion Model (DDM) to determine whether an agent is trapped in an impasse. The DDM is a widely used framework for simulating binary choice tasks-such as right or wrong judgments and left or right selections-in cognitive science and computational neuroscience [Ratcliff and McKoon, 2008; Gold and Shadlen, 2007]. It posits that decisions are made by progressively accumulating evidence until a certain threshold is reached. The DDM is typically formalized as a stochastic differential equation: dx = v·dt+σ·dWt, where x represents the accumulated evidence, v is the drift rate, σ denotes the noise intensity, and Wt signifies standard Brownian motion.
We simply apply the DDM to identify impasses during agent-environment interactions. As the agent keeps operating without obtaining any reward or fails, the evidence x will accumulate and will trigger the agent to change from exploitation to exploration with the impasse probability pimpasse ∝ x.
Exploration. The exploration strategy for A2RL is a random policy that randomly chooses a valid action in A, and restarts if the agent fails (e.g., walks into in Minigrid environment). During the rollout process, the state abstraction model ϕ is called to determine whether the sampled ground state s belongs to a known abstract state. We use DDM to make the choice, here the accumulating evidence x = maxi P(ϕ(s) = i), and the strategy change from exploration to exploitation is triggered with probability pexploit ∝ x.
4.2 Abductive Learning
This section describes how to update the ASM ∆ via abductive learning. In logic, abduction is the process of inferring the best explanation for a set of observations.
The impasse-driven exploration and exploitation rollout generates numerous ground trajectories as observations. Each trajectory can be explained as a step-by-step procedure, segmented into exploration and exploitation phases. The exploitation phases are further divided based on their corresponding abstract states. For the exploration segments, a clustering model is applied to the ground states, using raw images and neighbouring abstract states to group them and define a new abstract state, σnew.
Then, the trajectory segments of σnew are used for constructing s(σnew), t(σnew) and τnew→old, where σold is a known abstract state in Σ. After adding a mental reward θnew, a subMDP Mσnew is created, from which the new atomic policies are trained. Meanwhile, the new state abstraction function ϕnew is trained using the visited ground states. Finally, The elements ∆ is updated as follows:
5 Experiment
Experiments 2 are designed to answer the following questions: 1: Is A2RL able to infer the existence of abstract states from raw data? 2: Does ASM improve the performance of RL in challenging environments(e.g., those with delayed rewards or sparse reward signals)? 3: Does A2RL learn abstraction and atomic policies that generalize in unseen tasks?
5.1 Experimental Setup
Environments. Experiments are conducted in two types of benchmark environments having delayed reward feedback: (1) Minigrid [Chevalier-Boisvert et al., 2023]: Minigrid, implemented in Gymnasium [Towers et al., 2024], is a suite of easily configurable grid world environments specifically designed for RL research. In Minigrid, we generated maps with different sizes: Minigrid-small and Minigrid-large. We further introduced two difficulty levels within the Minigrid-small environment: Easy-small and Difficult-small. (2) Taxi [Dietterich, 2000]: In Taxi, the taxi must pick up the passenger, drive to the destination, and drop them off to end the episode.
2 The code is available at https://github.com/sporeking/A2RL.
The input states contain solely raw pixels. This design choice demonstrates our method's capability to extract symbolic representations directly from raw inputs, aligning more closely with the requirements of real-world tasks.
Policy Learning. We employed two end-to-end DRL algorithms as base models for learning policy functions: (1) PPO2 [Schulman et al., 2017]: PPO2 is a model-free policy gradient method, the crux of which lies in Proximal Policy Optimization. Utilizing importance sampling, PPO2 effectively constrains the divergence between the old and new policies. (2) D3QN [Wang et al., 2016; Hasselt et al., 2016]: D3QN is a RL algorithm that amalgamates the strengths of the Dueling Network Architecture and Double Q-Learning, aiming to learn and evaluate Q-values more accurately.
Baselines. We compare A2RL with the following baselines: (1) GT (Ground Truth): utilizes a handcrafted ASM with predefined symbols to set a performance upper-bound for A2RL. Its precise subtask decomposition means GT can be regarded as a Hierarchical Reinforcement Learning (HRL) approach [Levy et al., 2019]. (2) RUDDER: A typical RL approach designed for tackling the delayed reward issue[Arjona-Medina et al., 2019]. RUDDER was implemented on top of the TRPO-based policy gradient method PPO; therefore, it was only compared with the PPO baselines;
(3) RL: Vanilla end-to-end DRL methods, without the assistance of symbolic reasoning.
Tasks. In Minigrid, three levels of progressively increasing difficulty were designed. On the one hand, the tasks in Minigrid are relatively complex, making it difficult for pure RL methods to converge; on the other hand, we can evaluate the effectiveness of our method in dynamic environments and its ability to learn new symbols by setting up this curriculum. We trained the agent sequentially on three levels. For GT, since it has already defined all prior knowledge needed in the environment, we directly used GT to train the final level to evaluate its performance. In Taxi, instead of curriculum learning, we trained the agent to learn abstraction directly from complete tasks.
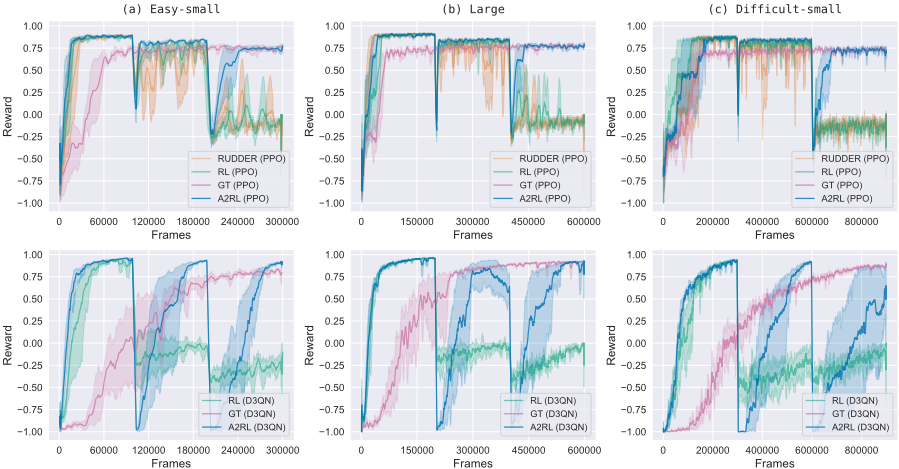
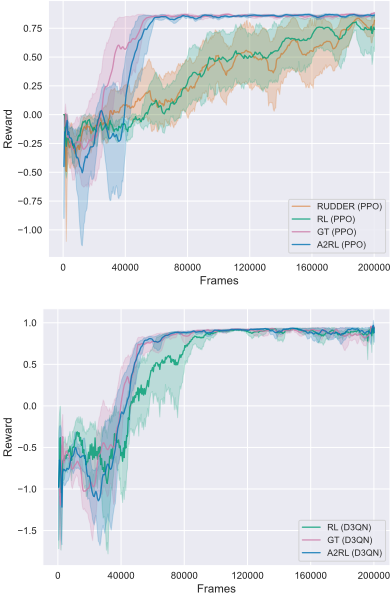
Metrics. We recorded the average reward per episode for each batch. Mean results are shown as learning curves, smoothed with a 10-window moving average applied to the batch average rewards. Shaded areas indicate the 95% confidence interval of these average rewards.
5.2 Experimental Results
The experimental results for MiniGrid are shown in Figure 5. It can be observed that the performance of pure RL and RUDDER is not satisfactory, as they fail to converge directly in the final levels. For RUDDER, due to the high input dimensionality of the environment, it negatively impacts the training of the LSTM, resulting in poor performance in such a complex environment. GT starts training directly from the most challenging final level, and with a clear symbolic structure, it converges quickly and stably.
For A2RL, when the difficulty level begins/changes, the prior ASM initially struggles, reflected in very low rewards. A2RL then discovers new states and updates the ASM with new symbols, causing its performance to rapidly improve. It converges stably across maps of varying difficulty, demonstrating its ability to discover new states and effectively adapt to new environments. Additionally, the abstracted symbolic structures allow A2RL to outperform vanilla RL, which answers the questions 1 and 2 at the beginning of this section.
The experimental results for Taxi are shown in Figure 6. Vanilla RL matches GT-level performance but is significantly slower than A2RL, which rapidly abstracts passenger symbols and achieves similar results in fewer training steps. Addressing question 2, vanilla RL's single network struggles with prioritizing multiple objectives (e.g., passenger pick-up vs. destination) due to its limited capacity. In contrast, A2RL decomposes complex tasks into sub-tasks, allowing its individual atomic policies to master simpler objectives, thereby improving performance on more complex tasks.
5.3 Out-of-distribution Generalization
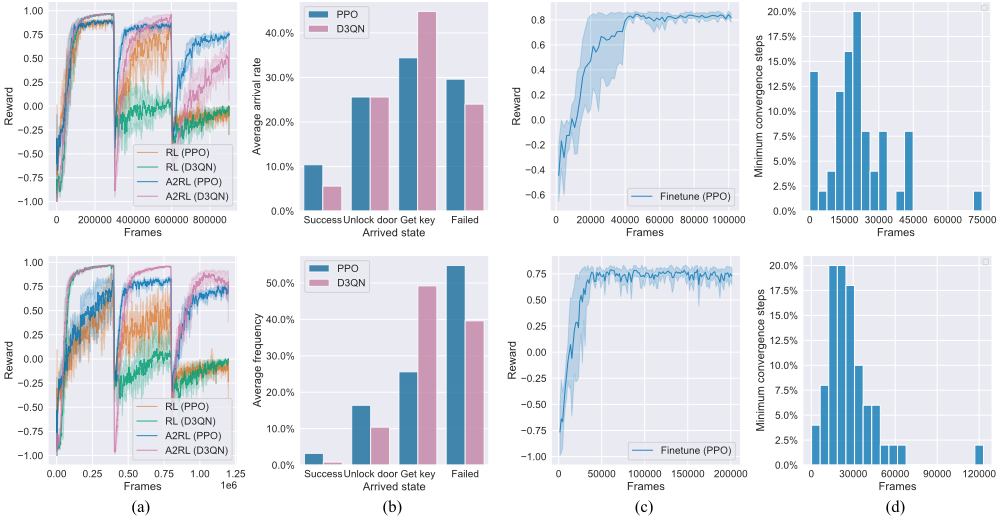
To address question 3, we conducted a series of ablation experiments: We replicated the setup in Section 5.2 but trained agents on procedurally generated random maps throughout the entire curriculum, and subsequently evaluated and finetuned on 50 unseen maps of comparable difficulty after training. We generated two distinct sets of Minigrid test maps: Minigrid-small and Minigrid-large.
Figure 7 shows that despite a slight decline in reward convergence speed and policy performance when training on test maps, the agent still achieves high performance. The generalization success rate on these test maps is below 10% (Generalization remains a significant challenge in DRL), yet learned atomic policies can complete some sub-tasks on many maps, as shown in Figure 7 (b). Furthermore, Figure 7 (c) and (d) illustrate that fine-tuning on test maps enables the agent to converge rapidly, typically within 50,000 steps, demonstrating strong generalization capabilities. These findings directly address question 3: A2RL enhances RL generalization by leveraging learned task structures and symbolic representations to generalize to similarly structured tasks. In comparison, vanilla DRL methods failed to converge on unseen maps.
6 RelatedWork
State Abstraction in RL. Early methods relied on expertdefined mappings to discrete state spaces [Dietterich, 2000; Andre and Russell, 2002], yet these struggle in continuous environments. End-to-end deep RL avoids explicit abstraction at the cost of reduced interpretability and limited generalization. To address this, Quentin et al. proposed NeSy to extract symbolic logic from neural strategies [Delfosse et al., 2023], and Jiang et al. introduced NLRL, which leverages first-order logic to enhance both interpretability and task transferability [Jiang and Luo, 2019]. Other approaches learn abstractions from data [Furelos-Blanco et al., 2023;
Para´c et al., 2024], but all depend on predefined symbols or labeled data, making automatic abstraction difficult. In contrast, A2RL can perform symbolic abstraction within the environment without predefined symbolic knowledge.
Knowledge Discovery in RL. Agents should infer "causal rule" knowledge from interacting with the environment. Some approaches use graph models or attention mechanisms to infer causal relations [peng et al., 2022; Zhu et al., 2020]; Ha et al. proposed world models for virtual trial-anderror [Ha and Schmidhuber, 2018], but struggle to acquire reliable rule-based knowledge and suffer from poor generalization. Existing methods fail to autonomously form symbols or discover causality in non-symbolic settings, and their probabilistic models lack logical reliability and expressive power. A2RL can autonomously discover new symbols within the environment and establish connections with existing symbols.
RL with Formal Knowledge. There are RL systems that use symbolic rule knowledge to decompose tasks through reward decomposition [Pateria et al., 2021]. Recent efforts employ natural language instructions or Transformer architectures to guide HRL and capture long-range dependencies [Jiang et al., 2019; K et al., 2023; Chen et al., 2021]. Alternative approaches combine classical planning with HRL to reduce its sample complexity [Yang et al., 2018; Liu et al., 2024]. Croonenborghs et al. investigated transfer learning within Relational Reinforcement Learning, which leverages existing knowledge to accelerate learning in target tasks; however, it is limited to tasks characterized by symbolic feature spaces [Croonenborghs et al., 2007]. Most current methods encode knowledge as rewards without rulebased frameworks, and cannot dynamically acquire or revise symbolic knowledge. In contrast, A2RL can update symbolic structures through exploration within the environment.
7 Conclusion
In this paper, we present Abductive Abstract Reinforcement Learning (A2RL), a novel framework that integrates the strengths of symbolic abstraction with RL. A2RL enables agents to decompose complex tasks into manageable subtasks and perform abstractions directly from sub-symbolic environments without relying on predefined symbols. It is important to note that this work provides only a preliminary implementation of A2RL. Future research will focus on enhancing the abstraction mechanisms and expanding the application of A2RL to a wider range of real-world scenarios, such as training large language model (LLM)-based reasoners with a formal step-by-step reasoning module. Through the continued development of A2RL, we aim to further unify symbolic reasoning with learning, advancing the creation of more reliable and efficient AI systems capable of addressing complex and unstructured challenges.
Acknowledgements
The authors thank the anonymous reviewers of IJCAI 2025 for their valuable feedback. This research was supported by NSFC (62206124), Jiangsu Science Foundation Leadingedge Technology Program (BK20232003) and Major Program (JD) of Hubei Province (2023BAA024). This work is also funded by Nanjing University-China Mobile Communications Group Co., Ltd. Joint Institute.
Contribution Statement
∗Wang-Zhou Dai is the corresponding author.
- †Zilong Wang and Jiongda Wang contributed equally to this work and are considered co-first authors.
@inproceedings{ijcai2025p725,
  title     = {From End-to-end to Step-by-step: Learning to Abstract via Abductive Reinforcement Learning},
  author    = {Wang, Zilong and Wang, Jiongda and Chen, Xiaoyong and Wang, Meng and Ma, Ming and Wang, Zhipeng and Zhou, Zhenyu and Yang, Tianming and Dai, Wang-Zhou},
  booktitle = {Proceedings of the Thirty-Fourth International Joint Conference on
               Artificial Intelligence, {IJCAI-25}},
  publisher = {International Joint Conferences on Artificial Intelligence Organization},
  editor    = {James Kwok},
  pages     = {6515--6523},
  year      = {2025},
  month     = {8},
  note      = {Main Track},
  doi       = {10.24963/ijcai.2025/725},
  url       = {https://doi.org/10.24963/ijcai.2025/725},
}
TY - CPAPER TI - From End-to-end to Step-by-step: Learning to Abstract via Abductive Reinforcement Learning AU - Wang, Zilong AU - Wang, Jiongda AU - Chen, Xiaoyong AU - Wang, Meng AU - Ma, Ming AU - Wang, Zhipeng AU - Zhou, Zhenyu AU - Yang, Tianming AU - Dai, Wang-Zhou T2 - Proceedings of the Thirty-Fourth International Joint Conference on Artificial Intelligence, IJCAI-25 PB - International Joint Conferences on Artificial Intelligence Organization PY - 2025 SP - 6515 EP - 6523 DO - 10.24963/ijcai.2025/725 UR - https://doi.org/10.24963/ijcai.2025/725 ER -Copied
Machine-readable versions of this paper, for tools and AI agents:





