
Problem-dependent Regret for Lexicographic Multi-Armed Bandits with Adversarial Corruptions
Proceedings of the Thirty-Fourth International Joint Conference on Artificial Intelligence. Main Track. Pages 6776-6784.
https://doi.org/10.24963/ijcai.2025/754
Keywords
- Machine Learning: ML: Multi-armed bandits
- Machine Learning: ML: Robustness
- Machine Learning: ML: Online learning
- Uncertainty in AI: UAI: Sequential decision making
Abstract
This paper studies lexicographic multi-armed bandits (MAB), where after selecting an arm, the agent observes a reward vector including multiple objectives, each with a different level of importance. Although previous literature has proposed the algorithm for lexicographic MAB, their algorithm suffers from several limitations: (1) it exhibits poor adversarial robustness due to its reliance on stochastic rewards, (2) its regret bound is suboptimal compared to single-objective counterparts, and (3) the regret bound does not adapt to specific problem instances. To address these limitations, we study lexicographic MAB with adversarial corruptions, where an adversary might corrupt the stochastic rewards with a corruption budget of C. First, when the value of C is known, we propose an algorithm achieving a problem-dependent regret bound of O(∑(log T / Δⁱ(a) + C)) for the i-th objective (i ∈ [M]), where Δⁱ(a) is the reward gap for arm a on the i-th objective, and M is the number of objectives. In the purely stochastic setting (C=0), this regret bound approaches optimality. Second, we introduce another algorithm that does not require value of C but incurs a less favorable regret bound of O(∑(γ_T / Δⁱ(a) + γ_T)) for the i-th objective, where γ_T = O((log T)² + KC(log T)²). Finally, we conduct experiments on both synthetic and real-world datasets to verify the effectiveness of our algorithms.
- [Altschuler et al., 2019] Jason Altschuler, Victor-Emmanuel Brunel, and Alan Malek. Best arm identification for con- taminated bandits. Journal of Machine Learning Research, 20(91):1-39, 2019.
- [Ararat and Tekin, 2023] Cagin Ararat and Cem Tekin. Vec- tor optimization with stochastic bandit feedback. In Pro- ceedings of the 26th International Conference on Artificial Intelligence and Statistics, pages 2165-2190, 2023.
- [Auer et al., 2002] Peter Auer, Nicolò Cesa-Bianchi, and Paul Fischer. Finite-time analysis of the multiarmed bandit problem. Machine Learning, 47(2-3):235-256, 2002.
- [Auer et al., 2016] Peter Auer, Chao-Kai Chiang, Ronald Ortner, and Madalina Drugan. Pareto front identification from stochastic bandit feedback. In Proceedings of the 19th International Conference on Artificial Intelligence and Statistics, pages 939-947, 2016.
- [Auer, 2002] Peter Auer. Using confidence bounds for exploitation-exploration trade-offs. Journal of Machine Learning Research, 3(11):397-422, 2002.
- [Balasubramanian et al., 2024] Rishab Balasubramanian, Ji- awei Li, Prasad Tadepalli, Huazheng Wang, Qingyun Wu, and Haoyu Zhao. Adversarial attacks on combinatorial multi-armed bandits. In Proceedings of the 41st Inter- national Conference on Machine Learning, pages 2505- 2526, 2024.
- [Bogunovic et al., 2020] Ilija Bogunovic, Andreas Krause, and Jonathan Scarlett. Corruption-tolerant gaussian pro- cess bandit optimization. In Proceedings of the 23rd Inter- national Conference on Artificial Intelligence and Statis- tics, pages 1071-1081, 2020.
- [Bubeck and Cesa-Bianchi, 2012] Sébastien Bubeck and Nicolò Cesa-Bianchi. Regret analysis of stochastic and nonstochastic multi-armed bandit problems. Foundations and Trends in Machine Learning, 5(1):1-122, 2012.
- [Cai et al., 2023] Xin-Qiang Cai, Pushi Zhang, Li Zhao, Bian Jiang, Masashi Sugiyama, and Ashley J. Llorens. Distributional pareto-optimal multi-objective reinforce- ment learning. In Advances in Neural Information Pro- cessing Systems 36, pages 15593-15613, 2023.
- [Cheng et al., 2024] Ji Cheng, Bo Xue, Jiaxiang Yi, and Qingfu Zhang. Hierarchize pareto dominance in multi- objective stochastic linear bandits. Proceedings of the 38th AAAI Conference on Artificial Intelligence, pages 11489- 11497, 2024.
- [Chowdhury and Gopalan, 2021] Sayak Ray Chowdhury and Aditya Gopalan. No-regret algorithms for multi-task Bayesian optimization. In Proceedings of the 24th International Conference on Artificial Intelligence and Statistics, pages 1873-1881, 2021.
- [Deb and Jain, 2014] Kalyanmoy Deb and Himanshu Jain. An evolutionary many-objective optimization algorithm using reference-point-based nondominated sorting ap- proach, part i: Solving problems with box con- straints. IEEE Transactions on Evolutionary Computation, 18(4):577-601, 2014.
- [Ding et al., 2022] Qin Ding, Cho-Jui Hsieh, and James Sharpnack. Robust stochastic linear contextual bandits un- der adversarial attacks. In Proceedings of the 25th Interna- tional Conference on Artificial Intelligence and Statistics, pages 7111-7123, 2022.
- [Drugan and Nowe, 2013] Madalina M. Drugan and Ann Nowe. Designing multi-objective multi-armed bandits al- gorithms: A study. In The 2013 International Joint Con- ference on Neural Networks, pages 1-8, 2013.
- [Ehrgott, 2005] Matthias Ehrgott. Multicriteria Optimiza- tion. Springer-Verlag, Berlin, Heidelberg, 2005.
- [Groetzner and Werner, 2022] Patrick Groetzner and Ralf Werner. Multiobjective optimization under uncertainty: A multiobjective robust (relative) regret approach. European Journal of Operational Research, 296(1):101-115, 2022.
- [Guan et al., 2020] Ziwei Guan, Kaiyi Ji, Donald J. Bucci Jr., Timothy Y. Hu, Joseph Palombo, Michael Liston, and Yingbin Liang. Robust stochastic bandit algorithms under probabilistic unbounded adversarial attack. In Proceedings of the 34th AAAI Conference on Artificial Intelligence, pages 4036-4043, 2020.
- [Gupta et al., 2019] Anupam Gupta, Tomer Koren, and Ku- nal Talwar. Better algorithms for stochastic bandits with adversarial corruptions. In Proceedings of the 32nd Con- ference on Learning Theory, pages 1562-1578, 2019.
- [He et al., 2022] Jiafan He, Dongruo Zhou, Tong Zhang, and Quanquan Gu. Nearly optimal algorithms for lin- ear contextual bandits with adversarial corruptions. In Advances in Neural Information Processing Systems 35, pages 34614-34625, 2022.
- [Hüyük and Tekin, 2021] Alihan Hüyük and Cem Tekin. Multi-objective multi-armed bandit with lexicographically ordered and satisficing objectives. Machine Learning, 110(6):1233-1266, 2021.
- [Jee et al., 2007] Kyung-Wook Jee, Daniel L. McShan, and Benedick A. Fraass. Lexicographic ordering: intuitive multicriteria optimization for imrt. Physics in Medicine & Biology, 52:1845-1861, 2007.
- [Kaliszewski, 2000] Ignacy Kaliszewski. Using trade-off in- formation in decision-making algorithms. Computers & Operations Research, 27(2):161-182, 2000.
- [Kang et al., 2023] Yue Kang, Cho-Jui Hsieh, and Thomas Chun Man Lee. Robust lipschitz bandits to adversarial corruptions. In Advances in Neural Information Process- ing Systems 36, pages 10897-10908, 2023.
- [Keeney, 2002] Ralph L. Keeney. Common mistakes in mak- ing value trade-offs. Operations Research, 50(6):935-945, 2002.
- [Khansa et al., 2021] Ali Al Khansa, Raphael Visoz, Yezekael Hayel, and Samson Lasaulce. Resource alloca- tion for multi-source multi-relay wireless networks. In Ubiquitous Networking, pages 62-75, 2021.
- [Kone et al., 2023] Cyrille Kone, Emilie Kaufmann, and Laura Richert. Adaptive algorithms for relaxed pareto set identification. In Advances in Neural Information Process- ing Systems 36, pages 35190-35201, 2023.
- [Li et al., 2015] Ke Li, Kalyanmoy Deb, Qingfu Zhang, and Sam Kwong. An evolutionary many-objective opti- mization algorithm based on dominance and decomposi- tion. IEEE Transactions on Evolutionary Computation, 19(5):694-716, 2015.
- [Lu et al., 2019] Shiyin Lu, Guanghui Wang, Yao Hu, and Lijun Zhang. Multi-objective generalized linear bandits. In Proceedings of the 28th International Joint Conference on Artificial Intelligence, pages 3080-3086, 2019. IJCAI
- [Lu et al., 2021] Shiyin Lu, Guanghui Wang, and Lijun Zhang. Stochastic graphical bandits with adversarial cor- ruptions. In Proceedings of the 35th AAAI Conference on Artificial Intelligence, pages 8749-8757, 2021.
- [Lykouris et al., 2018] Thodoris Lykouris, Vahab Mirrokni, and Renato Paes Leme. Stochastic bandits robust to ad- versarial corruptions. In Proceedings of the 50th Annual ACM SIGACT Symposium on Theory of Computing, page 114-122, 2018.
- [Miettinen, 1999] Kaisa Miettinen. Nonlinear Multiobjec- tive Optimization. Kluwer Academic Publishers, Boston, USA, 1999.
- [Mukherjee et al., 2021] Arpan Mukherjee, Ali Tajer, Pin- Yu Chen, and Payel Das. Mean-based best arm identi- fication in stochastic bandits under reward contamination. In Advances in Neural Information Processing Systems 34, pages 9651-9662, 2021.
- [Munro et al., 2021] Alasdair P S Munro, Leila Janani, Vic- toria Cornelius, and et al. Safety and immunogenicity of seven covid-19 vaccines as a third dose (booster) fol- lowing two doses of chadox1 ncov-19 or bnt162b2 in the uk (cov-boost): a blinded, multicentre, randomised, con- trolled, phase 2 trial. The Lancet, 398:2258-2276, 2021.
- [Nowak and Trzaskalik, 2022] Maciej Nowak and Tadeusz Trzaskalik. A trade-off multiobjective dynamic program- ming procedure and its application to project portfolio se- lection. Annals of Operations Research, 311(2):1155- 1181, 2022.
- [Robbins, 1952] Herbert Robbins. Some aspects of the se- quential design of experiments. Bulletin of the American Mathematical Society, 58(5):527-535, 1952.
- [Schwartz et al., 2017] Eric Schwartz, Eric Bradlow, and Pe- ter Fader. Customer acquisition via display advertising us- ing multi-armed bandit experiments. Marketing Science, 36(2):500-522, 2017.
- [Tekin and Turgay, 2018] Cem Tekin and Eralp Turgay. Multi-objective contextual multi-armed bandit with a dominant objective. IEEE Transactions on Signal Process- ing, 66(14):3799-3813, 2018.
- [Trisna et al., 2016] Trisna Trisna, Marimin Marimin, Yan- dra Arkeman, and Titi Sunarti. Multi-objective optimiza- tion for supply chain management problem: A literature review. Decision Science Letters, 5(6):283-316, 2016.
- [Turgay et al., 2018] Eralp Turgay, Doruk Oner, and Cem Tekin. Multi-objective contextual bandit problem with similarity information. In Proceedings of the 21st Interna- tional Conference on Artificial Intelligence and Statistics, pages 1673-1681, 2018.
- [Villar et al., 2015] Sofía S. Villar, Jack Bowden, and James Wason. Multi-armed bandit models for the optimal design of clinical trials: Benefits and challenges. Statistical Sci- ence, 30(2):199 -215, 2015.
- [Wang et al., 2023] Yifan Wang, Weizhi Ma, Min Zhang, Yiqun Liu, and Shaoping Ma. A survey on the fairness of recommender systems. ACM Transactions on Information Systems, 41(3):1-43, 2023.
- [Weber et al., 2002] Enrico Weber, Andrea Emilio Rizzoli, Rodolfo Soncini-Sessa, and Andrea Castelletti. Lexico- graphic optimisation for water resources planning: the case of lake verbano, italy. pages 235-240, 2002.
- [Wilbur and Zhu, 2009] Kenneth Wilbur and Yi Zhu. Click fraud. Marketing Science, 28(2):293-308, 2009.
- [Xu and Klabjan, 2023] Mengfan Xu and Diego Klabjan. Pareto regret analyses in multi-objective multi-armed ban- dit. In Proceedings of the 40th International Conference on International Conference on Machine Learning, pages 38499-38517, 2023.
- [Xue et al., 2024] Bo Xue, Ji Cheng, Fei Liu, Yimu Wang, and Qingfu Zhang. Multiobjective lipschitz bandits un- der lexicographic ordering. Proceedings of the 38th AAAI Conference on Artificial Intelligence, pages 16238-16246, 2024.
- [Xue et al., 2025] Bo Xue, Xi Lin, Xiaoyuan Zhang, and Qingfu Zhang. Multiple trade-offs: An improved approach for lexicographic linear bandits. Proceedings of the 39th AAAI Conference on Artificial Intelligence, pages 21850- 21858, 2025.
References were extracted automatically from the PDF and may contain errors.
Full text extracted automatically from the PDF; figures, tables and equations may differ. The PDF is the version of record.
1 Introduction
Multi-armed bandits (MAB) has emerged as a prominent framework in the field of sequential decision-making [Robbins, 1952], where at each round, an agent first chooses one of K arms and then receives a reward related to the chosen arm. The goal of the agent is to maximize the cumulative rewards over T rounds. MAB has found applications in various domains, including online advertising [Schwartz et al., 2017], clinical trials [Villar et al., 2015], and resource allocation [Khansa et al., 2021]. Despite its power, many real-world applications encounter the trade-off between different objectives. For example, supply chain management aims to maximize revenue while minimizing costs [Trisna et al., 2016], and recommender systems strive to maximize the user engagement while ensuring the fairness [Wang et al., 2023]. These applications have motivated the development of multi-objective bandits, where the observed reward is a vector containing multiple objectives [H¨uy¨uk and Tekin, 2021; Groetzner and Werner, 2022; Xu and Klabjan, 2023; Cai et al., 2023; Cheng et al., 2024; Xue et al., 2025].
∗Qingfu Zhang is the corresponding author.
Most research on multi-objective bandits employs Pareto regret to evaluate algorithms, which assumes all objectives carry equal importance [Turgay et al., 2018; Lu et al., 2019; Cai et al., 2023]. However, some real-world applications require different levels of importance among objectives. For instance, in radiation treatment for cancer patients, target coverage takes precedence over proximity to organs at risk [Jee et al., 2007]. Similarly, water resource planning prioritizes objectives such as flood protection, irrigation supply shortages, and electricity generation [Weber et al., 2002]. Moreover, Theorem 4.1 in Xu and Klabjan [2023] states that Pareto regret is lower than the individual regret of any objective. Therefore, optimizing any single objective among the multiple objectives achieves the optimal Pareto regret bound, while the other objectives still suffer linear regret bounds of O(T).
To address this issue, lexicographic order is proposed [Ehrgott, 2005], which distinguishes objectives through their importance. Precisely, in a lexicographic bandit problemwith M objectives, the i-th objective is more important than the jth objective if i < j and i, j ∈ [M]1 . As the most related work, H¨uy¨uk and Tekin [2021] investigated multi-objective multi-armed bandits (MOMAB) under lexicographic order and defined a metric called priority-based regret. Precisely, let I(·) be the indicator function, and µi (a) ∈ R be the expected reward of arm a ∈ [K] on the objective i ∈ [M]. The priority-based regret for the objective i ∈ [M] is
where ∆i (a) = µi (a∗)-µi (a) is the expected reward gap, at is the arm chosen at the t-th round, and a∗ is the lexicographic optimal arm (which will be defined in Section 3). Based on this metric, H¨uy¨uk and Tekin [2021] developed an algorithm whose regret bound is ˜O((KT)2/3 ).
1 For any positive integer N, [N] denotes the set {1, 2, . . . ,N}.
Although this work [H¨uy¨uk and Tekin, 2021] establishes a foundational framework for addressing the lexicographic bandit problem, it has four limitations: (1) It assumes that rewards are stochastic, which may be violated in some practical scenarios, such as click fraud in pay-per-click online advertising [Wilbur and Zhu, 2009] and malicious reviews in recommendation systems [Lykouris et al., 2018]. (2) The regret bound ˜O((KT)2/3 ) is suboptimal, as the problem-dependent lower bound and minimax lower bound for single-objective MAB are Ω (∑∆(a)>0 log T ∆(a) ) and Ω(√KT), respectively [Bubeck and Cesa-Bianchi, 2012]. (3) Its regret bound cannot adapt to specific problem instances. (4) The priority-based regret is inaccurate in certain cases. For example, if µ1 (at) < µ1 (a∗), then I(µj (at) = µj (a∗), ∀j ∈ [i - 1]) = 0 for i ≥ 2. Therefore, the instantaneous gap ∆i (at) for i ≥ 2 is ignored because ∆i (at) · I(µj (at) = µj (a∗), ∀j ∈ [i - 1]) = 0.
To address these limitations, we study the lexicographic MOMAB with adversarial corruptions, whose most rewards are stochastic, but a small fraction can be contaminated by an adversary [Lykouris et al., 2018]. With a budget of corruptions C, our main contributions are summarized as follows:
- We adopt a more accurate metric to evaluate lexicographic MAB algorithms, which is a natural extension of the regret in single-objective bandits [Auer et al., 2002], i.e.,
- If C is known, we propose an algorithm that enjoys a regret bound of O (∑∆i (a)>0 ( log T ∆i (a) +C )) for the i-th objective, i ∈ [M]. In the stochastic setting (C = 0), this regret bound becomes O (∑∆i (a)>0 log T ∆i (a) ), which matches the lower regret bound of MAB [Bubeck and Cesa-Bianchi, 2012] and improves upon the existing regret bound ˜O((KT)2/3 ) [H¨uy¨uk and Tekin, 2021].
- If C is unknown, we employ the multi-instance technique [Lykouris et al., 2018] to design a new algorithm that has a regret bound of O (∑∆i (a)>0 ( γT ∆i (a) + γT )) for the i-th objective, where γT = O((logT)2 + KC(logT)2 ). When C = 0, this regret bound becomes O (∑∆i (a)>0 ( (log T )2 ∆i (a) + (logT)2)), which also improves the existing lexicographic bandit algorithm [H¨uy¨uk and Tekin, 2021].
- We conduct two sets of experiments to validate our theoretical findings. The first set consists of synthetic experiments, while the second utilizes a real-world dataset related to COVID-19 vaccines. Results from both sets of experiments demonstrate that our algorithms can effectively optimize multiple objectives simultaneously.
2 RelatedWork
In this section, we review the research on corruption-tolerant bandits and multi-objective bandits.
2.1 Corruption-tolerant Bandits
Lykouris et al. [2018] first introduced this new bandit model called MAB with adversarial corruptions, and proposed two basic ideas for this model. If the budget C is known, Lykouris et al. [2018] utilized enlarged confidence intervals to achieve a regret bound of O (∑∆(a)>0 log T +C ∆(a) ). 2 If C is unknown, Lykouris et al. [2018] proposed the multi-instance technique which dynamically adapts to the corruptions and achieved a regret bound of O (∑∆(a)>0 KC(log T )2+(log T )2 ∆(a) ). Later, Gupta et al. [2019] further improved this regret bound to O (KC + ∑∆(a)>0 log(T ) log(log T ) ∆(a) ) by randomly selecting arms from a specially designed distribution. Gupta et al. [2019] also established a lower bound that exhibits a linear relationship with the budget C. Subsequent research has advanced the corruption-tolerant MAB into various directions, including stochastic linear bandits [He et al., 2022; Ding et al., 2022], Lipschitz bandits [Kang et al., 2023], graph bandits [Lu et al., 2021], combinatorial bandits [Balasubramanian et al., 2024] and Gaussian bandits [Bogunovic et al., 2020]. Beyond the budget-bounded setting, several papers have focused on a similar scenario in which an adversary attacks with a certain probability at each round, and these attack values can be unbounded [Altschuler et al., 2019; Guan et al., 2020; Mukherjee et al., 2021].
2.2 Multi-objective Bandits
Drugan and Nowe [2013] initially formalized the MOMAB problem and proposed two algorithms that exhibit regret bounds of O (∑∆(a)>0 ( log T ∆(a) +∆(a))) for scalarized regret and Pareto regret, respectively. Turgay et al. [2018] devoted into the multi-objective contextual bandits and proposed a zooming-based algorithm that achieves a Pareto regret bound of ˜O(T (dp+1)/(dp+2) ), where dp is Pareto zooming dimension. Lu et al. [2019] explored the multi-objective generalized linear bandits and provided a regret bound of ˜O(√T). Chowdhury and Gopalan [2021] studied multiobjective bandit learning from the perspective of nonparametric Bayesian optimization. Another line of research is the Pareto set identification, whose goal is to analyze the cost of identifying all Pareto optimal arms [Auer et al., 2016; Ararat and Tekin, 2023; Kone et al., 2023]. Tekin and Turgay [2018] initially examined lexicographic contextual bandits, establishing a regret bound of ˜O(T (dc+2)/(dc+3) ), where dc is the dimension of context information. However, their study was limited to scenarios with two objectives. Xue et al. [2024] later extended the number of objectives beyond two in the Lipschitz bandit setting, deriving a regret bound of ˜O(T (diz +1)/(diz +2) ) for the i-th objective, where diz is the zooming dimension and i ∈ [M]. The most related work is by H¨uy¨uk and Tekin [2021], which studied the lexicographic MOMAB and achieved a regret bound of ˜O((KT)2/3 ).
2 For the single-objective setting, ∆1 (a) is simplified as ∆(a).
Existing algorithms for lexicographic bandits can only handle stochastic rewards, which lacks robustness against adversarial attacks. Meanwhile, their regret bounds fail to adapt to specific problem instances. Therefore, we propose new algorithms for lexicographic MOMAB with adversarial corruptions and establish problem-dependent regret bounds.
3 Preliminaries
This paper studies lexicographic MOMAB with adversarial corruptions. Let M be the number of objectives and K be the number of arms. At each round t = 1, 2, . . . , T, the formal protocol between the agent and adversary is as follows:
- The environment assigns each arm a ∈ [K] a stochastic reward rt(a) = [r1 t (a), . . . , rM t (a)] ∈ RM , whose expectation is µ(a) = [µ1 (a), . . . , µM (a)]. For any objective i ∈ [M] and any arm a ∈ [K], µi (a) is bounded in [0, 1] and ri t (a) satisfies the 1-sub-Gaussian property, i.e.,
- The adversary observes the stochastic reward of any arm a ∈ [K] and corrupts it to ˜ rt(a) = [˜ r1 t (a), . . . , ˜ rM t (a)] , where the corruptions are bounded, such that
- The agent chooses an arm at and then observes the corrupted reward vector ˜ rt(at).
Following the previous studies on the corruption-tolerant bandits [Lykouris et al., 2018; Gupta et al., 2019], we assume the total corruptions of each objective are bounded by C, i.e.,
Next, we introduce the lexicographic order so as to compare different arms by their expected rewards.
Definition 1 (Lexicographic Order). Let u, v ∈ RM be two vectors. u is said to lexicographically dominate v if and only if there exists some i∗ ∈ [M], such that ui = vi for any i ∈ [i∗ - 1] and ui∗ > vi∗ .
Lexicographic order is a total order allowing the comparison of any two vectors, thereby deciding the lexicographic optimal arm.
Definition 2 (Lexicographic Optimal Arm). An arm a∗ is lexicographic optimal if and only if its expected reward is not lexicographically dominated by that of any other arms in [K].
Finally, we introduce a concept termed local trade-off, which is similar to the established notion called global tradeoff [Miettinen, 1999, Definition 2.8.5].
Definition 3 (Local Trade-off). A positive real number λ0 is the local trade-off parameter of a MOMAB problem if and only if it is the smallest λ > 0 that satisfies the condition: for any i ≥ 2 and a ∈ [K],
(b) Single Optimal Arm on 𝜇𝜇ଵ
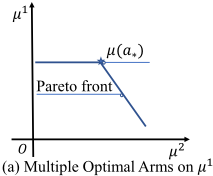
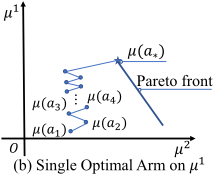
Figure 1: (a) There exist multiple optimal arms for the first objective, thus a lexicographic bandit algorithm is necessary to identify the lexicographic optimal arm a∗. (b) There exists only one optimal arm for the first objective, thus running a single-objective bandit algorithm on the first objective is sufficient to determine the arm a∗. However, focusing on the first objective only cannot optimize the second objective.
The trade-off parameter λ0 is a ratio indicating when transitioning from the lexicographic optimal arm a∗ to other arms, how much the value of the i-th objective will increase per unit decrease in the preceding i - 1 objectives. Due to the inherent conflicts among different objectives, employing the information about trade-offs is common in multiobjective optimization [Kaliszewski, 2000; Keeney, 2002; Nowak and Trzaskalik, 2022].
4 Effective Scenarios of Lexicographic Bandit Algorithms
Before introducing our algorithms, we present two typical lexicographic bandit problems in Figure 1(a) and Figure 1(b), highlighting scenarios where our algorithms are effective.
In Figure 1(a), multiple arms attain the maximum expected reward on the first objective. Therefore, executing a singleobjective bandit algorithm based solely on the rewards of the first objective cannot identify the lexicographic optimal arm a∗, and taking a lexicographic bandit algorithm is necessary.
In contrast, Figure 1(b) depicts a scenario where only one arm a∗ attains the maximum expected reward on the first objective. Here, identifying the optimal arm for the first objective is equivalent to identifying the lexicographic optimal arm a∗. This raises a natural question:
Can a single-objective bandit algorithm replace lexicographic bandit algorithms in the scenario of Figure 1(b)?
The answer is no. As depicted in Figure 1(b), applying a single-objective bandit algorithm, such as UCB [Auer, 2002], to the first objective yields a sequence of chosen arms {a1, a2, . . . , at, . . .}. By the theoretical guarantee of UCB, the sequence of expected rewards for the first objective, {µ1 (a1), µ1 (a2), . . . , µ1 (at), . . .}, converges to the optimal expected reward µ1 (a∗), ensuring a sublinear regret bound for the first objective, as shown in Figure 1(b). However, the sequence of expected rewards for the second objective, {µ2 (a1), µ2 (a2), . . . , µ2 (at), . . .}, may deviate significantly from the optimal value µ2 (a∗), potentially resulting in linear regret for the second objective. Therefore, singleobjective algorithms cannot optimize multiple objectives simultaneously in the scenario like Figure 1(b), thus cannot replace the lexicographic bandit algorithms.
Algorithm 1 Corruption-tolerant Multi-objective Bandits with Known Budget (CMOB-KB)
Input: δ ∈ (0, 1), λ ≥ λ0
- 1: Initialize empirical mean rewards ˆµi (a) = 0, counters n(a) = 0, and confidence terms w(a) = +∞ for i ∈ [M] and a ∈ [K]
- 2: Initialize exploration index s = 1 and arm set As = [K]
- 3: for t = 1, 2, . . . do
- 4: Invoke Algorithm 2 to select an arm, update the exploration index and candidate arm set: at, s,As = AELO (s, As, { ˆµi (a), w(a)}i∈[M] a∈As )
- 5: Play the arm at and observe the reward vector ˜ rt(at)
- 6: Update the empirical rewards and counter by Eq. (8)
- 7: Update the confidence term by Eq. (9)
- 8: end for
5 Algorithms
In this section, we first propose a budget-dependent algorithm, and then present a budget-free algorithm to remove the requirement on the budget value C.
5.1 Budget-dependent Method: CMOB-KB
As a warm-up, we introduce a straightforward algorithm that requires the value of budget C, called Corruption-tolerant Multi-objective Bandits with Known Budget (CMOB-KB).
At the start, CMOB-KB initializes the empirical mean rewards ˆµi (a) and the counter n(a) for any objective i ∈ [M] and any arm a ∈ [K] as zero, where the counter is used to track the number of times each arm is played. The confidence term w(a) for any arm a ∈ [K] is initialized as infinity. In addition, CMOB-KB initializes an exploration index s = 1 and a candidate arm set As = [K]. With these initializations, CMOB-KB is ready to start decision-making. To balance the trade-off across different objectives, we design a novel decision-making method called Arm Elimination under Lexicographic Ordering (AELO), as outlined in Algorithm 2.
AELO is a repeated-until loop which iteratively eliminates arms in As until an arm is chosen. If there is an arm a ∈ As whose confidence term w(a) is greater than 2-s , AELO chooses the arm with the fewest number of plays, i.e., at = argmina∈As n(a), and terminates the loop. If no arm satisfies this condition, AELO sequentially eliminates arms from the first objective to the last objective so as to balance the exploration and exploitation across different objectives.
Let A0s = As be the initialized candidate arms. For the objective i ∈ [M], AELO first selects the arm ˆait fromAi-1 s that maximizes the upper confidence bound of this objective, i.e., ˆait = argmaxa∈Ai-1 s ˆµi (a) + w(a). Then, AELO keeps the arms whose upper confidence bound is greater than or equal to the upper confidence bound of ˆait minus a term depending on the objective order and the exploration index, i.e.,
This step eliminates arms that are less promising. After eliminating arms on the last objective M, AELO sets As+1 as
Algorithm 2 AELO
Input: s,As, { ˆµi (a),w(a)}i∈[M]
a∈As 1: repeat 2: if w(a) > 2-s for some a ∈ As then 3: Choose the arm at = argmina∈As n(a) 4: else 5: Initialize the arm set A0s = As 6: for i = 1, 2, . . . ,M do 7: ˆait = argmaxa∈Ai-1 s ˆµi (a) +w(a) 8: Ais = {a ∈ Ai-1 s |ˆµi (a) + w(a) ≥ ˆµi (ˆait ) + w(ˆait ) - (2 + 4λ + . . . + 4λi-1 ) · 2-s } 9: end for 10: Update As+1 = AMs and s = s +1 11: end if 12: until an arm at is chosen 13: Return at, s and AsAMs and s as s + 1. AELO repeats the above steps until an arm is chosen. Finally, AELO returns the chosen arm at, the updated index s and arm set As.
Once CMOB-KB obtains the arm returned by AELO, it plays at and receives the reward ˜ rt(at). Then, CMOB-KB updates the empirical mean rewards of all objectives and the counter n(at), i.e.,
Finally, CMOB-KB computes w(at) based on the updated n(at), i.e.,
where α(at) = 4 log(4MKn(at)/δ). After all these updates, CMOB-KB has finished the current trial and is prepared to make the next decision.
We provide the following theorem for CMOB-KB.
Theorem 1. Suppose (3), (4) and (5) hold. If CMOB-KB is run with λ ≥ λ0, then with probability at least 1 - δ, for any objective i ∈ [M], its regret satisfies
where αT = 4 ln(4MKT/δ) and Λi (λ) = 1+λ+. . .+λi-1 . Remark 1. Theorem 1 states that CMOB-KB achieves a regret bound of O (∑∆i (a)>0 ( αT (Λi (λ))2 ∆i (a) +Λi (λ)C )). Notably, Λ1 (λ) = 1, thus the regret bound of the first objective is O (∑∆1 (a)>0 ( αT ∆1 (a) + C )), which aligns with the regret bound of the single-objective corruption-tolerant bandit algorithm [Lykouris et al., 2018]. Therefore, CMOB-KB does not degrade the performance of the most important objective (i = 1) when optimizing multiple objectives simultaneously. Although subsequent objectives may have higher regrets, it is acceptable for lower-priority objectives to experience greater Algorithm 3 Corruption-tolerant multi-objective Bandits with Unknown Budget (CMOB-UB)
Input: δ ∈ (0, 1), λ ≥ λ0, T ∈ N+
- 1: Compute instance number L = ⌈log2 T⌉
- 2: Initialize empirical mean rewards ˆµiℓ (a) = 0, counters nℓ(a) = 0, and confidence terms wℓ(a) = +∞ for i ∈ [M], a ∈ [K] and ℓ ∈ [L]
- 3: Initialize exploration index sℓ = 1 and candidate arm set Aℓ = [K] for ℓ ∈ [L]
- 4: for t = 1, 2, . . . , T do
- 5: Sample instance ℓt ∈ [L] with probability 2-ℓt , with the remaining probability sampling ℓt = 1
- 6: if Aℓt ̸= ∅ then
- 7: Invoke Algorithm 2 to select an arm, update exploration index and candidate arm set: at, sℓt ,Asℓt = AELO (sℓt , Asℓt , { ˆµiℓt (a), wℓt (a)}i∈[M] a∈Asℓt )
- 8: Update the arm set for previous instances: for ℓ < ℓt, Asℓ = Asℓ ∩ Asℓt
- 9: Play the arm at and observe the rewards ˜ rt(at)
- 10: Update empirical rewards and counter by Eq. (10)
- 11: Update the confidence term by Eq. (11)
- 12: else
- 13: Find the minimum instance ℓ′t ≥ ℓt such that Aℓ′t ̸= ∅ and randomly play an arm from Aℓ′t
- 14: end if
- 15: end for
regrets. This effect is typically modest given that most multiobjective problems involve two or three objectives [Deb and Jain, 2014; Li et al., 2015].
Remark 2. In the setting of stochastic rewards (C = 0), the above regret bound reduces to O (∑∆i (a)>0 αT (Λi (λ))2 ∆i (a) ), which matches the problem-dependent lower bound of singleobjective bandits in terms of ∆i (a) [Bubeck and CesaBianchi, 2012]. This is a considerable improvement since the existing regret bound of lexicographic MOMAB work is ˜O((KT)2/3 ) [H¨uy¨uk and Tekin, 2021], which deviates from the minimax regret bound ˜O(√KT) of the single-objective bandit algorithm [Bubeck and Cesa-Bianchi, 2012]. Furthermore, we adopt the general regret (2) as the metric, which is more accurate than the priority-based regret (1) used in [H¨uy¨uk and Tekin, 2021], as discussed in Section 1.
Remark 3. Regarding the budget value C, Gupta et al. [2019] established a budget-dependent lower bound Ω(C), which indicates that our regret bound is optimal concerning the budget C. Meanwhile, CMOB-KB is an anytime algorithm which does not take T as input,distinguishing it from existing methods [Lykouris et al., 2018; Gupta et al., 2019].
5.2 Budget-free Method: CMOB-UB
To remove the dependence on C, a commonly used approach is the multi-instance technique [Lykouris et al., 2018; Kang et al., 2023], which involves constructing multiple corruption-tolerant instances like CMOB-KB first, and then randomly picking an instance to run in each round. Since each instance has a different tolerance level against corruption and the more resilient one is less likely to be chosen, this approach enables automatic adaptation to the unknown value C. Leveraging this technique, we design a budget-free algorithm called Corruption-tolerant Multi-objective Bandits with Unknown Budget (CMOB-UB).
At the start, CMOB-UB calculates L = ⌈log2 T⌉, which is the number of instances. Afterward, CMOB-UB initializes the empirical mean rewards ˆµiℓ (a), the counters nℓ(a), and the confidence terms wℓ(a) for each objective i ∈ [M], arm a ∈ [K], and instance ℓ ∈ [L]. Meanwhile, CMOB-UB initializes the exploration index sℓ = 1 and the candidate arm set Aℓ = [K] for each instance ℓ ∈ [L].
With all these preparations, CMOB-UB proceeds to the decision-making process from t = 1 to T. In the t-th round, CMOB-UB first samples an instance ℓt with probability 2-ℓt for ℓt ∈ [L], with the remaining probability sampling ℓt = 1. If the candidate arm set Aℓt is not empty, CMOB-UB employs AELO (Algorithm 2) to select an arm at. The inputs for AELO are the recorded information of the sampled instance ℓt, such as the exploration index sℓt , the candidate arm set Asℓt , the empirical rewards ˆµiℓt (a), and the confidence terms wℓt (a) for all a ∈ Aℓt .
Once an arm is selected, CMOB-UB eliminates arms of previous instances by intersecting the candidate arm sets Aℓ and Aℓt for all ℓ ≤ ℓt. This step ensures that the candidate arms from previous instances are contained in subsequent ones, such that A1 ⊆ A2 · · · ⊆ AL. CMOB-UB then plays the chosen arm at and receives the corresponding rewards [˜ r1 t (at), ˜ r2 t (at), . . . , ˜ rm t (at)]. It updates the empirical mean rewards and the counter as follows:
Finally, CMOB-UB updates the confidence term wℓt (at), such that,
where αℓt (at) = 4 ln(4MKnℓt (at)/δ).
Otherwise, if the candidate arm set Aℓt is empty, CMOBUB finds the minimum instance ℓ′t ≥ ℓt such that Aℓ′t ̸= ∅ and randomly plays an arm from Aℓ′t . In this case, CMOBUB does not update the estimated rewards and confidence terms, thus the corruptions does not attack the parameter estimation of CMOB-UB.
We provide the following regret bound for CMOB-UB.
Theorem 2. Suppose (3), (4) and (5) hold. If CMOB-UB is run with λ ≥ λ0, then with probability at least 1-5δ, for any objective i ∈ [M], its regret satisfies
where Λi (λ) = 1 + λ + . . . + λi-1 , αT = 4 ln(4MKT/δ) and βT = 4KC ln(T/δ) + 2 log2 T .
Remark 4. Theorem 2 states that CMOB-UB achieves a regret bound of O (∑∆i (a)>0 γT ( (Λi (λ))2 ∆i (a) +Λi (λ))), where γT = O((KC logT + logT) log(MKT)). Compared to CMOB-KB, CMOB-UB removes the dependence on the prior knowledge C at the cost of O(K logT) increase in the regret bound. Compared to the budget-free method for single-objective bandits [Lykouris et al., 2018], CMOBUB achieves comparable regret bounds in the leading terms ∆i (a) and T for multiple objectives simultaneously.
Remark 5. In the case of C = 0, the regret bound in Theorem 2 is O (∑∆i (a)>0 (log(T ))2 ( (Λi (λ))2 ∆i (a) +Λi (λ))), which outperforms the existing lexicographic MOMAB regret bound of ˜O((KT)2/3 ) [H¨uy¨uk and Tekin, 2021]. In cases where C is non-zero, the regret bound of CMOB-UB is linear in terms of C, which matches the existing lower bound of corruption-tolerant bandits [Gupta et al., 2019].
6 Experiments
In this section, we conduct experiments on synthetic and realworld datasets to verify the effectiveness of our algorithms.
To demonstrate the robustness of our algorithms, we compare them with PF-LEX, a lexicographic MOMAB method for stochastic rewards [H¨uy¨uk and Tekin, 2021], and two single-objective corruption-tolerant MAB methods [Lykouris et al., 2018]. Specifically, we refer to the first and third methods from Lykouris et al. [Lykouris et al., 2018] as CSOBKB and CSOB-UB, respectively. CSOB-KB takes the prior knowledge of the budget value C as input, while CSOB-UB removes this dependence.
6.1 Synthetic Dataset
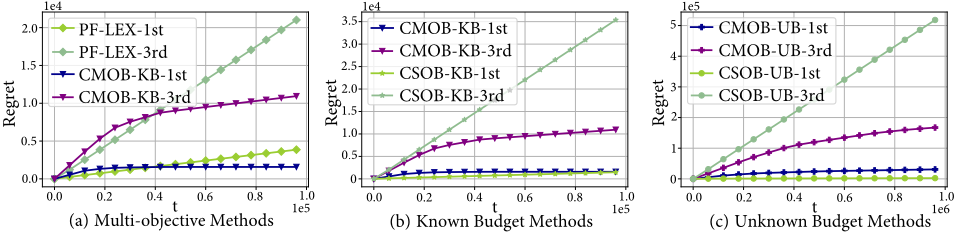
In the synthetic dataset, the number of arms is K = 20, and the number of objectives is M = 3. We evaluate two levels of corruptions: C = 0 for the non-corrupted case and C = 300 for the corrupted case. Each algorithm is executed 10 times, and we present the average regrets for the first and third objectives. More details are provided in the appendix.
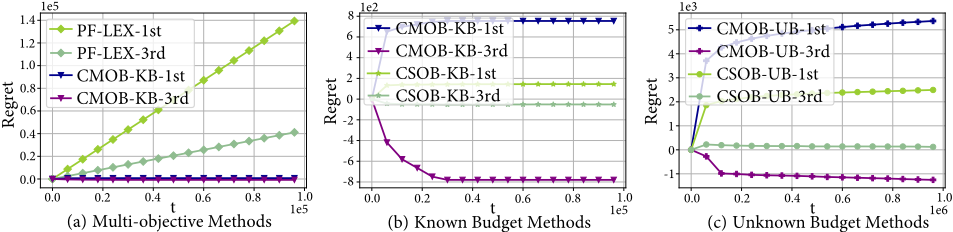
Figure 2 illustrates the non-corrupted case (C = 0). In Figure 2(a), we display the performance of PF-LEX and CMOBKB. It can be observed that CMOB-KB outperforms PF-LEX in both the first and third objectives, which aligns with the theoretical guarantees that CMOB-KB exhibits a lower regret bound than PF-LEX. The regret curve of CMOB-KB eventually flattens, indicating that it successfully identifies the optimal arm. Moving to Figure 2(b), we present the performance of the known budget methods, CMOB-KB and CSOB-KB. Although CMOB-KB and CSOB-KB achieve comparable performance on the first objective, CMOB-KB outperforms CSOB-KB on the third objective, showcasing the effectiveness of CMOB-KB for optimizing multiple objectives. Figure 2(c) presents the results of the unknown budget methods. Similar to Figure 2(b), the multi-objective method CMOBUB achieves comparable performance to the single-objective algorithm CSOB-UB on the first objective but outperforms CSOB-UB on the third objective.
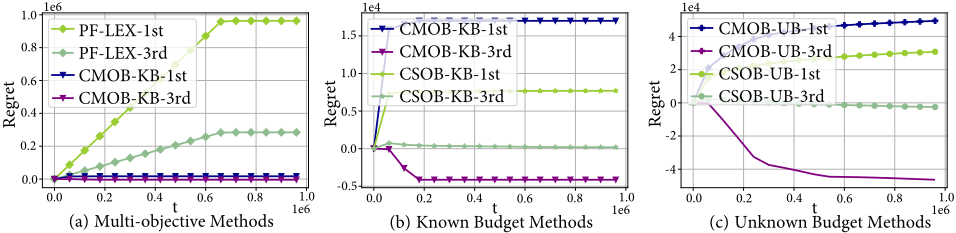
Figure 3 presents the results for the corrupted case (C = 300), with (a), (b), and (c) displaying the multi-objective methods, known budget methods, and unknown budget methods, respectively. The attackers corrupt the rewards and increase the cost of identifying the optimal arm, resulting in the time horizons in Figure 3(a) and Figure 3(b) are 10 times longer than the zero-corruption case. The curves of CMOBKB and CMOB-UB eventually converge for both the first and third objectives, showcasing their ability to identify the optimal arm under adversarial attacks and their ability to optimize multiple objectives simultaneously. In contrast, PFLEX cannot handle corruptions, while CSOB-KB and CSOBUB yield linear regret bounds for the third objective.
6.2 Real-world Dataset
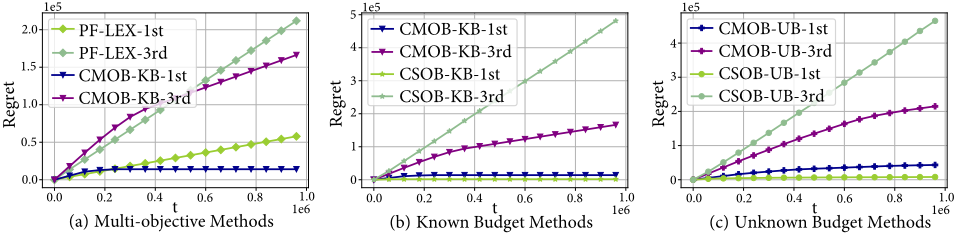
Building upon the prior research [Kone et al., 2023], we assess the performance of our algorithms using a real-world dataset obtained from Covid-19 vaccines [Munro et al., 2021], where K = 20 and M = 3. We set the corruption budget C to 0 and 300, respectively. Each algorithm is executed 10 times, and the average regrets are reported.
Figure 4 illustrates the non-corrupted case (C = 0). In Figure 4(a), the performance of PF-LEX and CMOB-KB reveals that CMOB-KB outperforms PF-LEX in both the first and third objectives. Figures 4(b) and 4(c) present the performance of methods with known and unknown budgets, respectively. Both of our algorithms, CMOB-KB and CMOBUB, demonstrate sublinear regret curves in the the first and third objectives, consistent with our theoretical guarantees. Interestingly, unlike in the synthetic experiments, the singleobjective algorithms CSOB-KB and CSOB-UB also exhibit sublinear regret curves for the third objective. This is because, in the COV-BOOST dataset, the lexicographic optimal arm can be identified solely based on the first objective. Thus, identifying the optimal arm for the first objective is equivalent to identifying the lexicographic optimal arm in this dataset.
Figure 5 presents the results for the corrupted case (C =
300). In comparison to the results in Figure 4, all algorithms exhibit increased regrets due to the attacker corrupts the rewards. Nonetheless, the curves of CMOB-KB and CMOBUB eventually converge for both the first and third objectives, demonstrating their robustness in identifying the optimal arm.
7 Conclusion and FutureWork
We developed two algorithms for lexicographic MAB with adversarial corruptions, enabling the optimization of multiple objectives under attacks. The first algorithm, CMOB-KB, has a regret bound of O (∑∆i (a)>0 ( log(T )(Λi (λ))2 ∆i (a) +Λi (λ)C )) for any objective i ∈ [M], aligning with the single-objective bandit algorithm in terms of ∆i (a), T and C [Lykouris et al., 2018]. In the stochastic reward setting, this regret bound reduces to O (∑∆i (a)>0 log(T )(Λi (λ))2 ∆i (a) ), which improves the existing regret bound ˜O((KT)2/3 ) [H¨uy¨uk and Tekin, 2021]. Although CMOB-KB is simple, its takes the corruption budget C as input. Therefore, we propose the second algorithm, CMOB-UB, which removes the dependence on C and enjoys a regret bound of O (∑∆i (a)>0 γT ( (Λi (λ))2 ∆i (a) +Λi (λ))), where γT = O (KC(logT)2 + (logT)2 ). Finally, we conducted experiments on both synthetic and real-world datasets, verifying the effectiveness of our algorithms in optimizing multiple objectives under corruptions.
One limitation of our algorithms is their reliance on the input value λ ≥ λ0, which may restrict their applicability. Hence, developing an algorithm that does not require prior knowledge of λ0 would be a valuable advancement.
Acknowledgments
The work described in this paper was supported by the Research Grants Council of the Hong Kong Special Administrative Region, China [GRF Project No. CityU 11212524].
@inproceedings{ijcai2025p754,
  title     = {Problem-dependent Regret for Lexicographic Multi-Armed Bandits with Adversarial Corruptions},
  author    = {Xue, Bo and Lin, Xi and Wan, Yuanyu and Zhang, Qingfu},
  booktitle = {Proceedings of the Thirty-Fourth International Joint Conference on
               Artificial Intelligence, {IJCAI-25}},
  publisher = {International Joint Conferences on Artificial Intelligence Organization},
  editor    = {James Kwok},
  pages     = {6776--6784},
  year      = {2025},
  month     = {8},
  note      = {Main Track},
  doi       = {10.24963/ijcai.2025/754},
  url       = {https://doi.org/10.24963/ijcai.2025/754},
}
TY - CPAPER TI - Problem-dependent Regret for Lexicographic Multi-Armed Bandits with Adversarial Corruptions AU - Xue, Bo AU - Lin, Xi AU - Wan, Yuanyu AU - Zhang, Qingfu T2 - Proceedings of the Thirty-Fourth International Joint Conference on Artificial Intelligence, IJCAI-25 PB - International Joint Conferences on Artificial Intelligence Organization PY - 2025 SP - 6776 EP - 6784 DO - 10.24963/ijcai.2025/754 UR - https://doi.org/10.24963/ijcai.2025/754 ER -Copied
Machine-readable versions of this paper, for tools and AI agents:





