
Robust Finite-Memory Policy Gradients for Hidden-Model POMDPs
Proceedings of the Thirty-Fourth International Joint Conference on Artificial Intelligence. Main Track. Pages 8518-8526.
https://doi.org/10.24963/ijcai.2025/947
Keywords
- Machine Learning: ML: Partially observable reinforcement learning and POMDPs
- Planning and Scheduling: PS: POMDPs
- Planning and Scheduling: PS: Learning in planning and scheduling
- Planning and Scheduling: PS: Planning under uncertainty
Abstract
Partially observable Markov decision processes (POMDPs) model specific environments in sequential decision-making under uncertainty. Critically, optimal policies for POMDPs may not be robust against perturbations in the environment. Hidden-model POMDPs (HM-POMDPs) capture sets of different environment models, that is, POMDPs with a shared action and observation space. The intuition is that the true model is hidden among a set of potential models, and it is unknown which model will be the environment at execution time. A policy is robust for a given HM-POMDP if it achieves sufficient performance for each of its POMDPs. We compute such robust policies by combining two orthogonal techniques: (1) a deductive formal verification technique that supports tractable robust policy evaluation by computing a worst-case POMDP within the HM-POMDP, and (2) subgradient ascent to optimize the candidate policy for a worst-case POMDP. The empirical evaluation shows that, compared to various baselines, our approach (1) produces policies that are more robust and generalize better to unseen POMDPs, and (2) scales to HM-POMDPs that consist of over a hundred thousand environments.
- [Aberdeen and Baxter, 2002] Douglas Aberdeen and Jonathan Baxter. Scalable internal-state policy-gradient methods for POMDPs. In ICML, pages 3-10.
- Morgan Kaufmann, 2002.
- Doug Aberdeen. Policy-gradient algo- rithms for partially observable Markov decision processes. PhD thesis, The Australian National University, 2003.
- [Amato et al., 2010] Christopher Amato, Blai Bonet, and Shlomo Zilberstein. Finite-state controllers based on Mealy machines for centralized and decentralized POMDPs. In AAAI, pages 1052-1058. AAAI Press, 2010.
- [Andriushchenko et al., 2021] Roman Andriushchenko, Mi- lan Češka, Sebastian Junges, Joost-Pieter Katoen, and Šimon Stupinský. PAYNT: a tool for inductive synthe- sis of probabilistic programs. In CAV, volume 12759 of LNCS, pages 856-869. Springer, 2021.
- [Andriushchenko et al., 2023] Roman Andriushchenko, Alexander Bork, Milan Češka, Sebastian Junges, Joost- Pieter Katoen, and Filip Macák. Search and explore: Symbiotic policy synthesis in POMDPs. In CAV, 2023.
- [Andriushchenko et al., 2024] Roman Andriushchenko, Mi- lan Češka, Sebastian Junges, and Filip Macák. Policies grow on trees: Model checking families of MDPs. In ATVA, 2024.
- [Chades et al., 2012] Iadine Chades, Josie Carwardine, Tara G. Martin, Samuel Nicol, Régis Sabbadin, and Olivier Buffet. MOMDPs: A solution for modelling adaptive man- agement problems. In AAAI. AAAI Press, 2012.
- [Chatterjee et al., 2016] Krishnendu Chatterjee, Martin Chmelík, Raghav Gupta, and Ayush Kanodia. Optimal cost almost-sure reachability in POMDPs. Artif. Intell., 234:26-48, 2016.
- [Chatterjee et al., 2020] Krishnendu Chatterjee, Martin Chmelík, Deep Karkhanis, Petr Novotný, and Amélie Royer. Multiple-environment Markov decision processes: Efficient analysis and applications. In ICAPS, pages 48-56. AAAI Press, 2020.
- [Chrszon et al., 2018] Philipp Chrszon, Clemens Dubslaff, Sascha Klüppelholz, and Christel Baier. ProFeat: feature- oriented engineering for family-based probabilistic model checking. Formal Asp. Comput., 30(1):45-75, 2018.
- [Cubuktepe et al., 2021] Murat Cubuktepe, Nils Jansen, Se- bastian Junges, Ahmadreza Marandi, Marnix Suilen, and Ufuk Topcu. Robust finite-state controllers for uncertain POMDPs. In AAAI, pages 11792-11800. AAAI Press, 2021.
- [Galesloot et al., 2024] Maris F. L. Galesloot, Marnix Suilen, Thiago D. Simão, Steven Carr, Matthijs T. J. Spaan, Ufuk Topcu, and Nils Jansen. Pessimistic iterative planning for robust POMDPs. CoRR, abs/2408.08770, 2024.
- [Galesloot et al., 2025] Maris F. L. Galesloot, Roman An- driushchenko, Milan Češka, Sebastian Junges, and Nils Jansen. RFPG: Robust finite-memory policy gradients for hidden-model POMDPs. CoRR, abs/2505.09518, 2025.
- [Grand-Clément and Kroer, 2021] Julien Grand-Clément and Christian Kroer. Scalable first-order methods for robust MDPs. In AAAI, pages 12086-12094. AAAI Press, 2021.
- [Heck et al., 2022] Linus Heck, Jip Spel, Sebastian Junges, Joshua Moerman, and Joost-Pieter Katoen. Gradient- descent for randomized controllers under partial observ- ability. In VMCAI, volume 13182 of Lecture Notes in Computer Science, pages 127-150. Springer, 2022.
- [Iyengar, 2005] Garud N. Iyengar. Robust dynamic program- ming. Math. Oper. Res., 30(2):257-280, 2005.
- [Kaelbling et al., 1998] Leslie Pack Kaelbling, Michael L. Littman, and Anthony R. Cassandra. Planning and act- ing in partially observable stochastic domains. Artificial Intelligence, 101(1):99-134, 1998.
- [Kumar et al., 2023] Navdeep Kumar, Esther Derman, Matthieu Geist, Kfir Y. Levy, and Shie Mannor. Policy gradient for rectangular robust Markov decision processes. In NeurIPS, 2023.
- [Lin et al., 2024] Zhenwei Lin, Chenyu Xue, Qi Deng, and Yinyu Ye. A single-loop robust policy gradient method for robust Markov decision processes. In ICML. OpenRe- view.net, 2024.
- [Littman et al., 1997] Michael L. Littman, Anthony R. Cas- sandra, and Leslie Pack Kaelbling. Learning policies for partially observable environments: Scaling up. In Interna- tional Conference on Machine Learning, 1997.
- [Madani et al., 2000] Omid Madani, Steve Hanks, and Anne Condon. On the undecidability of probabilistic planning and infinite-horizon partially observable Markov decision problems. Proceedings of the National Conference on Artificial Intelligence, 02 2000.
- [Meuleau et al., 1999] Nicolas Meuleau, Kee-Eung Kim, Leslie Pack Kaelbling, and Anthony R. Cassandra. Solving POMDPs by searching the space of finite policies. In UAI, pages 417-426.
- Morgan Kaufmann, 1999.
- [Nakao et al., 2021] Hideaki Nakao, Ruiwei Jiang, and Siqian Shen. Distributionally robust partially observable Markov decision process with moment-based ambiguity. SIAM J. Optim., 31(1):461-488, 2021.
- [Ni and Liu, 2013] Yaodong Ni and Zhi-Qiang Liu. Policy iteration for bounded-parameter POMDPs. Soft Comput., 17(4):537-548, 2013.
- [Norman et al., 2017] Gethin Norman, David Parker, and Xueyi Zou. Verification and control of partially observable probabilistic systems. Real-Time Systems, 53(3):354-402, 2017.
- [Osogami, 2015] Takayuki Osogami. Robust partially ob- servable Markov decision process. In ICML, volume 37 of JMLR Workshop and Conference Proceedings, pages 106-115. JMLR.org, 2015.
- [Puterman, 1994] Martin L. Puterman. Markov Decision Pro- cesses: Discrete Stochastic Dynamic Programming. Wiley Series in Probability and Statistics. Wiley, 1994.
- [Qiu et al., 1999] Qinru Qiu, Qing Wu, and Massoud Pedram. Stochastic modeling of a power-managed system: con- struction and optimization. In Proceedings of the 1999 International Symposium on Low Power Electronics and Design, page 194-199. Association for Computing Machin- ery, 1999.
- [Raskin and Sankur, 2014] Jean-Franc ¸ois Raskin and Ocan Sankur. Multiple-environment Markov decision processes. In FSTTCS, volume 29, pages 531-543. Schloss Dagstuhl - Leibniz-Zentrum für Informatik, 2014.
- [Rickard et al., 2024] Luke Rickard, Alessandro Abate, and Kostas Margellos. Learning robust policies for uncertain parametric Markov decision processes. In L4DC, volume 242 of Proceedings of Machine Learning Research, pages 876-889. PMLR, 2024.
- [Saghafian, 2018] Soroush Saghafian. Ambiguous partially observable Markov decision processes: Structural results and applications. J. Econ. Theory, 178:1-35, 2018.
- [Tobin et al., 2017] Josh Tobin, Rachel Fong, Alex Ray, Jonas Schneider, Wojciech Zaremba, and Pieter Abbeel. Domain randomization for transferring deep neural net- works from simulation to the real world. In IROS, pages 23-30. IEEE, 2017.
- [Wang et al., 2023] Qiuhao Wang, Chin Pang Ho, and Marek Petrik. Policy gradient in robust MDPs with global conver- gence guarantee. In ICML, volume 202 of Proceedings of Machine Learning Research, pages 35763-35797. PMLR, 2023.
- [Wiesemann et al., 2013] Wolfram Wiesemann, Daniel Kuhn, and Berc ¸Rustem. Robust Markov decision processes. Math. Oper. Res., 38(1):153-183, 2013.
- [Wu et al., 2019] Bo Wu, Mohamadreza Ahmadi, Suda Bharadwaj, and Ufuk Topcu. Cost-bounded active clas- sification using partially observable markov decision pro- cesses. In ACC, pages 1216-1223. IEEE, 2019.
References were extracted automatically from the PDF and may contain errors.
Full text extracted automatically from the PDF; figures, tables and equations may differ. The PDF is the version of record.
1 Introduction
Partially observable Markov decision processes (POMDPs) [Kaelbling et al., 1998] are the ubiquitous model in decisionmaking where agents have to account for uncertainty over the current state. Policies for POMDPs select actions based on observations, which provide limited information about the state, and require memory to act optimally.
Example 1. Figure 1(a) depicts a POMDP with an agent tasked to reach any of the green cells while avoiding the obstacle in the center. The agent cannot observe its position but can detect if there is an obstacle in its current row. Due to strong wind blowing southward, there is a small chance the agent moves south instead of the intended direction. The optimal policy for this POMDP is straightforward: to always go right.
Robustness. The common assumption that a single, known POMDP model sufficiently captures a system is often unrealistic. Furthermore, the optimal policy for this POMDP may not be optimal or perform well on a slightly perturbed model. Therefore, it may be beneficial to assume that the system's actual model is only known to be within a set of model variations that are critically different but share certain similarities.
Example 2. Figure 1(b) depicts a set of POMDPs comprising three potential obstacle locations. An optimal policy for any of the individual models overfits to that particular obstacle location and fails to solve the task in all three environments.
Hidden-model POMDPs. We introduce hidden-model POMDPs (HM-POMDPs) encapsulating multiple different POMDPs. The ground truth model is assumed to be hidden among the set of POMDPs. Notably, the POMDPs share the same actions and observations, and therefore, policies are compatible with all of the POMDPs. The objective is to compute a policy that is robust in the sense that it optimizes for the worst-case POMDPs within the set. Consequently, a robust policy achieves a lower bound in terms of performance on the set of POMDPs and, therefore, on the ground truth model.
Policy optimization. Computing optimal policies for POMDPs requires infinite memory and is undecidable in general [Madani et al., 2000]. Therefore, we restrict policies to finite memory via finite-state controllers (FSCs) as policy representations [Meuleau et al., 1999]. Computing a robust policy is challenging for HM-POMDPs, as realistic examples may induce large sets of POMDPs, and policies may overfit when optimized for any particular POMDP. To ensure robustness, the policy must be optimized for the worst-case POMDPs. Therefore, we seek an approach that generalizes to the whole set of POMDPs by optimizing it on worst-case POMDPs.
Robust policy evaluation. A robust policy evaluation is necessary to deduct the worst-case POMDPs from the HM-POMDP and, consequently, provide a lower bound on performance. The naive approach is to enumerate all POMDPs, but the set of POMDPs increases rapidly when we encounter many variations in the model, rendering enumeration intractable. Therefore, a key part of our approach is efficiently performing robust policy evaluation on large, finite sets of POMDPs.
1.1 Contributions
We introduce the robust finite-memory policy gradient (RFPG) algorithm. Figure 1(e) provides an overview of the core steps, namely policy optimization on worst-case POMDPs and robust policy evaluation. In RFPG, we represent the policy by an FSC and optimize its parameters through gradient ascent to improve its robust performance. During each iteration, RFPG improves the policy on the worst-case POMDP of the HM-POMDP, akin to subgradient ascent. The worst-case POMDPs are selected during robust policy evaluation. We introduce a novel technique that exploits structural similarities between POMDPs to scale to large sets. We assume that the structural similarity is given by an equivalence relation on the transition and reward functions of the POMDPs and use it to construct a concise representation of the HMPOMDP that enables efficient evaluation via deductive verification. In an extensive experimental evaluation on both simple and complex HM-POMDPs, we showcase the improvement of RFPG over several baselines, both in robust performance and in generalization to unseen models. 1
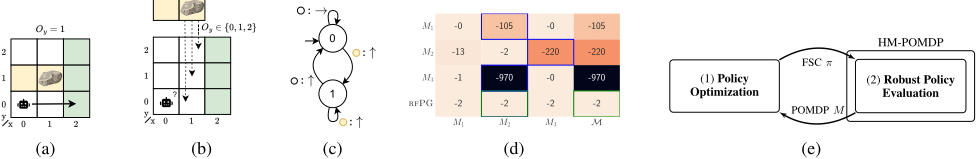
Example 3. Figure 1(c) illustrates a robust policy found by RFPG, with two memory states. It uses memory to deduce the current configuration and solves it close to optimally, moving up at least twice to counter the southward wind.
1.2 RelatedWork
Models for multiple environments. Computing policies for multiple environments has been studied for finite sets of MDPs, known as both hidden-model MDPs (HM-MDPs) [Chades et al., 2012; Wu et al., 2019], multiple environment MDPs (MEMDPs) [Raskin and Sankur, 2014; Chatterjee et al., 2020], and families of MDPs [Andriushchenko et al., 2024]. We emphasize that, similarly to the different terms for MDPs, our definition of HM-POMDPs could also be considered as multiple environment POMDPs (MEPOMDPs). Robust POMDPs (RPOMDPs) [Osogami, 2015] extend robust MDPs (RMDPs) [Iyengar, 2005; Wiesemann et al., 2013] and capture a potentially infinite set of POMDPs. HMPOMDPs form a proper subclass of robust POMDPs, and can approximate RPOMDPs up to finite precision. Methods for RPOMDPs typically assume (local) convexity and independence over state-action pairs in the set of POMDPs, which results in models where the environment can change completely at each step, which can be overly conservative. In contrast, our approach assumes that a worst-case POMDP is picked adversarially at the start and then remains fixed.
1 Code is on Zenodo (https://doi.org/10.5281/zenodo.15479642) and the paper with appendix is on arXiv [Galesloot et al., 2025].
Methods for robust policy optimization. For RMDPs, various works optimize policies through policy gradients [GrandCl´ement and Kroer, 2021; Lin et al., 2024], using subgradients [Kumar et al., 2023; Rickard et al., 2024] or mirror ascent [Wang et al., 2023]. For RPOMDPs, earlier work introduced FSC policy iteration for optimistic (best-case) optimization [Ni and Liu, 2013]. Methods based on value iteration [Osogami, 2015; Saghafian, 2018; Nakao et al., 2021] typically do not scale well to large state spaces. More recent methods optimize robust FSCs through sequential convex programming [Cubuktepe et al., 2021] or by optimizing a recurrent neural network on worst-case POMDPs [Galesloot et al., 2024]. To the best of our knowledge, HM-POMDPs do not yet exist in the literature, and RFPG is the first algorithm for robust policy optimization in HM-POMDPs.
2 Preliminaries
A distribution over a countable set A is a function µ: A → [0, 1], s.t. ∑a µ(a) = 1 and µ(a) ≥ 0 for all a ∈ A. The support of µ is supp(µ) := {a ∈ A | µ(a) > 0} and a ∼ µ denotes a ∈ supp(µ). The set ∆(A) contains all distributions over A. ∇θf denotes the gradient of the function f wrt. variable θ, and projA(·) denotes the projection onto the set A.
Definition 1 (POMDP). A partially observable Markov decision process (POMDP) is a tuple M = ⟨S, s0, A, T, R, Z, O⟩ with a finite set S of states, an initial state s0 ∈ S, a finite set A of actions, a transition function T : S ×A→∆(S), a reward function R: S ×A → R, a finite set Z of observations and a deterministic observation function O : S → Z 2 .
We will write T(s′ | s, a) to denote T(s, a)(s′ ). A Markov decision process (MDP) is a POMDP with a unique observation z ∈ Z for every s ∈ S. A Markov chain (MC) is an MDP with |A| = 1. To simplify notation, MDPs are tuples ⟨S, s0, A, T, R⟩ and MCs are tuples ⟨S, s0, T, R⟩. A path in an MC is a sequence ξ = (s0 , s1 , . . .) of states where s0 = s0 and st+1 ∼ T(st ). R(ξ) := ∑∞t=0 R(st ) denotes the (possibly infinite) cumulative reward for ξ [Puterman, 1994].
Let C = ⟨S, s0, T, R⟩ be an MC. We consider reachability reward objectives: undiscounted infinite-horizon objectives where we accumulate rewards until reaching a set G ⊂ S of goal states [Puterman, 1994]. We assume that every goal state sG ∈ G is absorbing and collects no reward: T(sG | sG) = 1 and R(sG) = 0; we further assume that every path ξ in C terminates in G. This definition encompasses infinite-horizon objectives with discounted rewards. Under the assumptions above, R(ξ) is a well-defined random variable, and its expectation JC := E [R(ξ)] will be referred to as the value of the MC C. This value is obtained from the state-values VC : S → R by setting JC = VC(s0), after finding the least fixed point of the recursive equation: VC(s) = R(s) + ∑s′∈S T(s′ | s)VC(s′ ).
2 Observation functions with a distribution over observations can be encoded by deterministic observation functions at the expense of a polynomial blow-up in the state space [Chatterjee et al., 2016].
To represent observation-based policies for POMDPs, we use finite-state controllers (FSCs). Various types of FSCs exist in the literature [Amato et al., 2010]. In this paper, it is convenient to define FSCs as Mealy machines whose output depends on the current node and the most recent observation.
Definition 2 (Policy). A stochastic policy as represented by a finite-state controller is a tuple π = ⟨N, n0, δ, η⟩ where N is a finite set of memory nodes with the initial node n0 ∈ N, δ : N × Z → ∆(A) is the action function, and η : N × Z → ∆(N) is the memory update function. Policy π has full action support if supp(δ(n, z)) = A for every n ∈ N and z ∈ Z.
Given state s with observation z = O(s), the policy π executes action a ∼ δ(n, z) associated with the current node n and the current observation z. The POMDP evolves to some state s′ ∼ T(s, a), and the policy evolves to node n′ ∼ η(n, z). Imposing a policy π onto POMDP M yields the induced Markov chain M π = (S×N, ⟨s0, n0⟩, T π , Rπ ), with a transition and reward function, using z = O(s), defined as:
The value of a policy π for a POMDP M is the value of the induced MC: J πM := JMπ . In this paper, we assume POMDPs in which the goal states are reachable from any state. This ensures that VMπ is well-defined for any policy π with full action support and is thus differentiable.
3 Hidden-Model POMDPs
We present the main problem statement of the paper. We consider a hidden-model POMDP, which describes an indexed set of POMDPs that share state, action, and observation spaces. Definition 3 (HM-POMDP). Let I be a finite set of indices. A hidden-model POMDP (HM-POMDP) is a tuple M = ⟨S, s0, A, {Ti}i∈I , {Ri}i∈I , Z, O⟩, where S, s0, A, Z, O are as in Definition 1 and {Ti}i∈I and {Ri}i∈I are indexed sets of transition and reward functions, respectively.
Given an index i ∈ I, an instance of an HM-POMDPM is a POMDP Mi = ⟨S, s0, A, Ti, Ri, Z, O⟩. We assume that each POMDP in the HM-POMDP has an initial state (distribution). Still, the assumption of the shared initial state s0 or shared observation function O is non-restrictive, as it can be lifted by introducing intermediate states at a polynomial increase in computational cost. Importantly, the POMDPs described byMdiffer in their transition functions and may thus differ in their topology, i.e., reachable states and observations. Instances inMhave the same set of policies, denoted by ΠM.
Definition 4 (Robust policy performance and optimal policy). Let M be an HM-POMDP. The robust performance J πM of a policy π is defined as the value of the worst instance and is maximized by an optimal robust policy π∗ , defined as:
Then, the key problem tackled in this paper is:
Goal: Given an HM-POMDP M, find a policy π∗ optimizing the robust performance J πM.
Our presentation focuses on the worst-case optimization of reachability rewards, i.e., argmaxmin (or argminmax when minimizing costs). The best-case policy performance and its associated policy are defined analogously (argmaxmax or argminmin), and our method extends to that setting.
The undecidability of the decision variant of this problem follows straightforwardly from the undecidability of infinitehorizon planning for POMDPs [Madani et al., 2000]. Therefore, we focus on a sound algorithm that aims to find a policy achieving a high robust performance within a reasonable time.
Example 4. We demonstrate the results of the robust policy evaluation on the example presented in Figure 1(b). We encode the objective (reaching any of the green cells while avoiding the obstacle) as the minimization of reachability reward, where visiting a cell with the obstacle is penalized by the reward of -100. The table in Figure 1(d) reports the expected reward achieved by four policies (rows) on each of the three POMDPs (first three columns); the last column reports the worst-case reward across all POMDPs, i.e., the robust performance. The first three rows correspond to 2-FSCs, each optimizing the performance in an individual POMDP. Naturally, policy πi performs well on POMDPMi. However, it hits the obstacle, on average, at least once for at least one other POMDP in the HM-POMDP. The last row reports the values achieved by the policy produced by RFPG, a method that takes into account many (in this case, all) POMDPs in the HM-POMDP. The robust performance of this policy can be interpreted as hitting the obstacle only once with a probability of at most 2% across all POMDPs in the HM-POMDP.
4 Robust Finite-Memory Policy Gradients
This section presents the robust finite-memory policy gradient (RFPG) algorithm to compute robust policies for HMPOMDPs. We divide the presentation into the following parts. In Section 4.1, we explain the steps of the main loop (recall Figure 1(e)) of RFPG. In Section 4.2, we present the main step in policy optimization, and Section 4.3 explains contributions towards robust policy evaluation on HM-POMDPs with many instances. In Section 4.4, we provide additional details.
4.1 Overview of RFPG
RFPG alternates between the following two main steps:
- Policy optimization, through policy (sub)gradients, and,
- Robust policy evaluation, through deductive verification.
During robust policy evaluation, we select a POMDP whose value coincides with the robust performance J πM.
Definition 5 (Worst-case POMDP). Given a policy π, a worstcase POMDP M is an instance of the HM-POMDPM that is a minimizer of π's robust performance J πM:
Given a policy π, computing its robust performance J πM and a worst-case POMDP M analytically is mathematically tractable since HM-POMDP M has finitely many instances.
During policy optimization, RFPG optimizes the candidate policy π through policy gradient ascent on POMDP M, locally optimizing the candidate policy π for its robust performance. As we represent π by an FSC, we parameterize the action function δθ by θ ∈ Θ ⊆ ∆(A)Z×N and the update function ηϕ by ϕ ∈ Φ ⊆ ∆(N)Z×N . Thus, we simultaneously optimize π to learn what to remember and how to act.
Remark 1. We observe that J πM is non-differentiable in general due to the minimization over the finite set. Thus, it may be infeasible to compute the gradient ∇θ,ϕJ πM to optimize the candidate policy π for robust performance directly. This challenge is circumvented by our iterative approach.
4.2 Policy Optimization for HM-POMDPs
Here, we address the first key component of RFPG- optimization of the candidate policies for robust performance. Our approach builds on subgradients, and we optimize π with a subgradient ∇θ,ϕJ πM , where M is a worst-case POMDP for π as in Definition 5. If there is no unique worst-case POMDP given π, we select one of them arbitrarily. Then, for any k ∈ N, the projected subgradient ascent of the policy's parameters is:
where π(k) = ⟨N, n0, δθ(k) , ηϕ(k)⟩, and αk are the (diminishing) step sizes. By iteratively refining the policy on the worst POMDP via subgradients, we may efficiently learn robust behavior and generalize to other (unseen) POMDPs of the HM-POMDP. Policy gradient ascent on a single POMDP, i.e., for solving argminπ∈ΠM J πM , converges to a local optimum [Meuleau et al., 1999; Aberdeen, 2003]. The situation is more complex for HM-POMDPs since we are maximizing for the minimum across a set of POMDPs. In particular, ∇J πM does not guarantee the ascent of J πM, i.e., robust performance at each step may not improve monotonically. This is in part due to the fact that there can exist multiple worst-case POMDP, i.e., there might exist multiple subgradients for a policy π. However, the subgradients still provide a meaningful direction for optimizing the robust performance. Yet, similar to the case of POMDPs, we may not provide global optimality guarantees. To combat the non-monotonicity, RFPG returns the best robust policy found over all iterations until a time-out is reached. In the following, we detail how we compute the gradients ∇J πM for worst-case POMDPs M that we use to optimize the candidate policy π.
Policy gradients on POMDPs with FSCs. For a worstcase POMDP M, computing the gradient of the objective ∇ϕ,θJ πM with respect to the policy's parameters ϕ and
θ enables us to climb the gradient and improve the policy [Meuleau et al., 1999]. To ensure the gradients are well-defined, the partial derivatives: ∂ηϕ(n′ |n,z)/∂ϕn,z,n′ , and, ∂δθ(a|n,z)/∂θn,z,a, as well as the ratios: ∣∣∣∣ ∂ηϕ(n′ |n,z) ∂ϕn,z,n′ ∣∣∣∣/ηϕ(n′ |n,z), and, ∣∣∣ ∂δθ (a|n,z) ∂θn,z,a ∣∣∣/δθ(a|n,z), must be uniformly bounded [Ab-
erdeen and Baxter, 2002].
These conditions are satisfied under a softmax parameterization. We have that the parameters can range over the real numbers, i.e., we set Φ ⊆ RN×Z×N and Θ ⊆ RN×Z×A, making the projections projΘ and projΦ trivial. The softmax function σ transforms any finite set of real numbers to a categorical distribution over the set. Given parameters ϕ ∈ Φ, the probabilities ηϕ(n′ | n, z) are given, for all n, z, n′ ∈ N ×Z ×N, based on the exponential function exp: ηϕ(n′ | n, z) = σn′(ϕn,z) = exp (ϕn,z,n′ )/∑m exp (ϕn,z,m), The partial derivative of a softmax probability with respect to a particular parameter input is:
Recall that the value of the policy J πM = VMπ(⟨s0, n0⟩) is given by the value of the initial state of the induced MCM π . Then, for ϕ and ηϕ, the expression for the partial derivatives of our objective with respect to the individual parameters is:
and similarly for θ and δθ. Then, the gradient ∇J πM is comprised of the partial derivatives for the individual parameters:
By computing ∇J πM , we optimize the parameters of the policy for the POMDPs M selected during robust policy evaluation.
4.3 Robust Policy Evaluation
The robust performance J πM of a given policy π (see Def. 4) can be computed by enumerating every POMDP Mi, i ∈ I, applying π to obtain the induced MC M π i and computing its value. In this section, we develop a methodology that avoids this enumeration and makes our approach scale to HMPOMDPs that describe many instances. The key to such a methodology is a concise representation of HM-POMDPs, namely a succinct representation of a set of transition {Ti}i∈I and reward {Ri}i∈I functions.
To compactly describe a set of (structurally similar) transition functions, we merge transitions that are shared between multiple instances. For instance, in the HM-POMDP from Figure 1(b), in the initial position (x = 0, y = 0) of the agent, all actions have the same immediate effect regardless of the particular instance. On the other hand, when executing an action from state (x = 1, y = 0), the agent receives a penalty of -100 in the instance (Oy = 0), but receives no penalty in all other POMDPs. Formally, let s,a∼ be the equivalence relation on I defined as i s,a∼j iff Ti(s, a) = Tj(s, a) and Ri(s, a) = Rj(s, a), i.e., executing action a in POMDPs Mi and Mj has the same effect and yields the same reward. I/ s,a∼ denotes the corresponding equivalence partitioning of I wrt. s,a∼. Then, to compactly describe a set of structurally similar POMDPs, we introduce a quotient POMDP, which is an extension of quotient MDPs (a mild variation of feature MDPs [Chrszon et al., 2018]) used in [Andriushchenko et al., 2024] to reason about families of MDPs. Intuitively, the quotient POMDP is a POMDP that can execute action a in state s from an arbitrary Mi, i ∈ I.
Definition 6 (Quotient POMDP). Given HM-POMDP M = ⟨S, s0,A, {Ti}i∈I, {Ri}i∈I,Z,O⟩, the quotient POMDP associated with M is a POMDP QM = ⟨S, s0, AQ, T Q, RQ, Z, O⟩ with actions AQ = A × 2I . Let (a, I) be denoted as aI. We define T Q(s′ | s, aI) = Ti(s′ | s, a) and RQ(s, aI ) = Ri(s, a) where i ∈ I (arbitrarily).
While for POMDPs in Definition 1 we assume that every action is available in every state, in our implementation, we assume w.l.o.g. that every state s is associated with some set A(s) ⊆ A of available actions, i.e., the transition function T : S ×A↛∆(S) is partial. Then, in the quotient POMDP, we assume that AQ(s) = {aI | a ∈ A(s), I ∈ I/ s,a∼}, i.e., in state s an agent chooses to play a specific variant of action a available in any Mi, i ∈ I. This allows us to efficiently encode an HM-POMDP where there are actions a ∈ A that coincide in many instances Mi, i ∈ I.
We lift the notion of the induced Markov chain (Section 2) from POMDPs to quotient POMDPs: The induced quotient MDP defines the set of MCs describing behavior of π in the POMDPs captured by the quotient POMDP. Intuitively, in the current state (s, n) of the induced quotient MDP, using z = O(s), an action a ∼ δ(n, z) is selected and the system transitions to an intermediate state (s, n, a), in which a specific variant of action a is selected from the set I/ s,a∼; then, the state is updated according to T Q(s, aI) and the memory is updated according to η(n, z).
Definition 7 (Induced quotient MDP). Given quotient POMDP QM = ⟨S, s0, AQ, T Q, RQ, Z, O⟩ and policy π = ⟨N, n0, δ, η⟩. Let A∅ := A ⊔ {∅} where ∅ is a fresh action. The induced quotient MDP associated with QM and π is an MDP LπM = ⟨S × N × A∅, (s0, n0, ∅), AL, T L, RL⟩ where AL = {∅} ⊔ 2I with available actions AL(·, ·, ∅) = {∅} and AL(s, ·, a) = I/ s,a∼. The transition and reward functions are defined as follows, where, using z = O(s):
Given such a quotient MDP compactly describing a family {M π i }i∈I of induced MCs, we can use deductive formal verification techniques implemented in the tool PAYNT [Andriushchenko et al., 2021] to efficiently identify an MC with the minimal value of J πMi = J πM, obtaining the robust performance of π and an associated worst-case POMDP M.
Algorithm 1: The RFPG algorithm
Input :An HM-POMDPM, a set G of goal states Output :A policy π∗ achieving the best J π∗ M Global :number of GA steps GASTEPS, step sizes αk 1 N ← SIZEOFFSC(M) ▷ See App. B 2 θ(0) , ϕ(0) ← INIT(Θ,Φ,N), k ← 0, ν ∗ ←-∞ 3 π(0) ← ⟨N, n0, δθ(0) , ηϕ(0)⟩ ▷ Build policy 4 QM← QUOTIENTPOMDP(M) ▷ Def.6 5 while TIMEOUT IS NOT REACHED do 6 Lπ(k) M ← INDUCEDMDP (QM, π(k) ) ▷ Def. 7 7 M (k) , J π(k) M ← PAYNT(Lπ(k) M ,G) ▷ Sec. 4.3 8 if J π(k) M > ν ∗ then π∗ ← π(k) , ν ∗ ←J π(k) M 9 for j ← k to k + GASTEPS - 1 do 10 θ(j+1) ← projΘ (θ(j) + αj∇θ(j) J π(j) M(k) ) 11 ϕ(j+1) ← projΦ (ϕ(j) + αj∇ϕ(j) J π(j) M(k) ) 12 π(j+1) ← ⟨N, n0, δθ(j+1) , ηϕ(j+1) ⟩ 13 k ← k + GASTEPS 14 return π∗4.4 RFPG Algorithm
Algorithm 1 outlines the key steps of RFPG. First, we determine the number of nodes for the policy π. Determining the optimal size is undecidable [Madani et al., 2000], therefore, we apply a heuristic that solves a small sample set of POMDPs fromM to determine an adequate size (Line 1, see Appendix B). We then initialize the gradient ascent parameters (Line 2, see Appendix A) and build the corresponding policy π (Line 3). Finally, we build the quotient POMDP QM (Line 4, see Definition 6) that compactly represents the set of POMDPs in the given HM-POMDP M.
The main loop runs until the given timeout is reached. We first construct for the current policy π the induced quotient MDP Lπ(k) M (Line 6, see Definition 7). The tool PAYNT [Andriushchenko et al., 2021] takes this MDP Lπ(k) M and the given goal states G to compute a worst-case POMDP M (k) and the robust performance J π(k) M (Line 7, see Section 4.3). We then update the running optimum (Line 8). Finally, we run GASTEPS gradient ascent steps to update parameters ϕ and θ of the policy π, now on POMDP M (k) (Line 9, see Section 4.2). GASTEPS is a hyperparameter that should be tuned based on the size of the HM-POMDP: having many instances |I| slows down the policy evaluation, while many states |S| slows down the gradient update steps. In our experiments, we picked GASTEPS = 10, such that at most 75% of the computation time is spent on policy evaluation.
5 Experimental Evaluation
In this section, we evaluate RFPG on the following questions.
- (Q1) Does RFPG produce policies with higher robust performance compared to several baselines?
- (Q2) Can RFPG generalize to unseen environments?
- (Q3) How does the POMDP selection affect performance?
5.1 Experimental Setting
Benchmarks. We extend four POMDP benchmarks [Littman et al., 1997; Norman et al., 2017; Qiu et al., 1999] and one family of MDPs [Andriushchenko et al., 2024] to HM-POMDPs. These benchmarks together encompass a varied selection of different complexities of HM-POMDPs, i.e., different numbers of POMDPs and sizes thereof, as reported in Table 1. Appendix C gives a detailed description of the benchmarks.
Baselines. For (Q1), we compare our approaches (1) to the POMDP solver SAYNT [Andriushchenko et al., 2023], which provides competitive performance to other state-ofthe-art tools that compute FSCs, and (2) standard FSC policy gradient ascent (GA) for POMDPs [Aberdeen, 2003; Heck et al., 2022]. We create four different baselines by using the following two strategies to compute robust policies:
- Enumeration: SAYNT-E/GA-E runs SAYNT/GA independently on each of the POMDPs in the HM-POMDP and selects the policy with the best robust performance.
- Union: SAYNT-U/GA-U runs SAYNT/GA on the union POMDP, constructed from the disjoint union of the POMDPs described by the HM-POMDP, with a uniform distribution over the initial states of these POMDPs.
Set-up. Due to their size, executing the baselines on the complete sets of POMDPs described by our benchmark suite of HM-POMDPs is infeasible. Moreover, we are interested in assessing the generalizability of our method (Q2). Therefore, we design the following experiment: (1) Pick a random subset of ten POMDPs from the full HM-POMDP, (2) compute a robust policy for this smaller sub-HM-POMDP using the four baselines and RFPG (referred to as RFPG-S), (3) compare the achieved robust performance of RFPG to the baselines on this sub-HM-POMDP (Q1). To further study the scalability and generalization of RFPG to large HM-POMDPs, we extend the experiment with the following steps: (4) compute a robust policy for the full HM-POMDP using RFPG, and (5) compare the robust performance of the resulting six policies on the full HMPOMDP using the policy evaluation method from Section 4.3. From this experiment, we can not only assess the scalability of our approach compared to the baselines but, moreover, the ability to generalize to unseen environments (Q2). Additionally, we can see if RFPG produces a better robust performance than RFPG-S, indicating whether it is essential to assess all POMDPs within an HM-POMDP. All methods have a onehour timeout to compute a policy; in case of a timeout, we report the robust performance of a uniform random policy. To report statistically significant results, each experiment was carried out on 10 different subsets obtained using stratified sampling from the full HM-POMDP. Appendix D provides information on the infrastructure used to run the experiments.
5.2 Overview of the Experimental Results
We present three experimental artifacts that report the key results of the experimental evaluation.
The table in Figure 2 reports, similar to Example 4, the values achieved by the policies on one particular subset of the Obstacles(8,5) HM-POMDP. The table shows the performance of the baseline methods except for GA-E, whose results are M1 M2 M3 M4 M5 M6 M7 M8 M9 M10 M
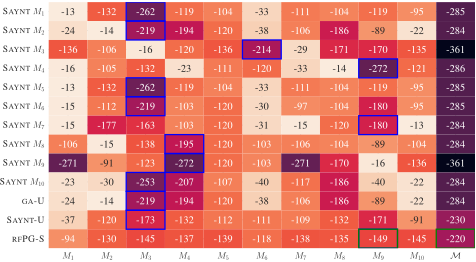
Figure 2: Performance (maximizing) of SAYNT-E (first 10 rows), SAYNT-U, GA-U, and RFPG-S for a sub-HM-POMDP of Obstacles(8,5). In the first 10 columns, corresponding to the evaluation of the individual POMDPs, we highlight the worst-case value of each method in blue and the best worst-case value among these in green. Independently, we highlight the highest value on the full HMPOMDPM(last column) in green. For comparison, RFPG achieves a value of -206 on M, surpassing the baselines.
generally worse and are reported in Appendix E. The rightmost column shows the results for the full HM-POMDP. It provides details in this particular environment on how (Q1) RFPG compares to the baselines on the subset of POMDPs and how (Q2) RFPG generalizes to the full HM-POMDP.
Table 1 summarizes the main results, including all algorithms and benchmarks to provide substantial evidence to answer (Q1) and (Q2). The upper part of the table contains less complex HM-POMDPs, describing a modest number of POMDPs, while the lower part includes more complex problems. The left part of the table presents the results for the sub-HM-POMDPs, and the values are normalized wrt. the value obtained using RFPG-S. The right part presents the results for the full HMPOMDP with the values normalized wrt. the value obtained using RFPG. We average values over 10 seeds; the extended Tables 2 and 3 in Appendix E include standard errors. Values below 1 indicate how much the baselines lag behind RFPG-S (the left part) and by RFPG (the right part), respectively.
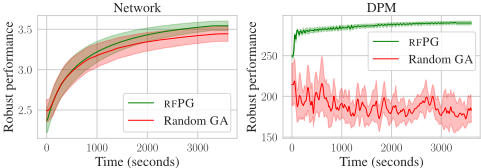
The learning curves in Figure 3 show the robust performance over time for the policies computed by RFPG and by the variant of the GA optimization that in every iteration of Algorithm 1 selects a random POMDP, similar to domain randomization [Tobin et al., 2017], to answer (Q3). We report curves for two selected benchmarks, a simpler and a harder one; learning curves for all benchmarks are reported in Appendix E. We consider the full HM-POMDP and plot the average values over 10 seeds with 95% confidence intervals.
5.3 Analysis of the Experimental Results
(Q1) Comparison to baselines
Detailed evaluation via Obstacles(8,5). As expected, the table in Figure 2 shows that the policy optimized for a particular POMDP achieves excellent relative value on this POMDP, but generally performs poorly on other POMDPs. The best robust performance of SAYNT-E is achieved with the policy optimized for POMDP M7, yielding a value of -180 for the subset and -284 for the HM-POMDP. The baselines using the union POMDP provide more robust policies. GA-U outperforms SAYNT-U in both settings, although SAYNT-E outperforms GA-E. While SAYNT-U achieves a better average, its robust performance is worse than GA-U. Being the best baseline on this benchmark, GA-U computes a policy achieving a value of -173 on the subset and -230 for the HM-POMDP. Our approach significantly improves these values: RFPG-S finds a policy with a value of -149 on the subset and -220 on the HM-POMDP, and RFPG finds a policy with a value of -206 on the HM-POMDP (not reported in the table).
| Model | Dimensions | Full HM-POMDP | ||||||||||||
|---|---|---|---|---|---|---|---|---|---|---|---|---|---|---|
| |I| | |S| | |Z| | |A| | Subset of SAYNT-E | |I| = 10 SAYNT-U | POMDPs | GA-E | GA-U | SAYNT-E | SAYNT-U | GA-E | GA-U | RFPG-S | |
| Obstacles(10,2) Network Avoid | 81 140 | 299 4k | 14 20 | 8 7 | 0.76 1.06 | 0.81 1.05 | 0.92 0.93 | 0.95 0.96 | 0.19 1.04 | 0.71 1.07 | 0.21 0.72 | 0.94 1.02 | 0.99 1.02 | |
| 86 | 18 | 6 | 0.85 | 0.98 | ||||||||||
| 1600 | 13k | 11 | 10 | 1.05 | 0.10 | 0.52 | 0.18 | 0.18 | 0.08 | 1.10 | 1.23 | |||
| Rover | 6k | 0.88 | 0.88 | 0.85 | 0.75 | 0.80 | 0.75 | 0.80 | 0.83 | |||||
| Obstacles(8,5) | 12k | 380 | 25 | 10 | 0.79 | 0.67 | 0.71 | 0.68 | 0.62 | 0.72 | 0.25 | 0.81 | 0.84 | |
| DPM | 131k | 737 | 3 | 5 | 0.80 | 0.61 | 0.95 | 0.61 | 0.54 | 0.64 | 0.46 | 0.62 | 0.91 | |
Comparison on the whole benchmark suite. Table 1 shows that our approach generally outperforms the baselines. Below, we analyze the left and right parts of the table in more detail.
Subsets. The results demonstrate the benefits of our approach already for the subsets of POMDPs, especially for the more complex benchmarks. In 4 (out of 6) benchmarks, the best policies produced by the baselines are behind the policies found by RFPG. We also observe that the relative performance of the particular baselines significantly varies among the benchmarks. This shows that (i) already small subsets require generalization in the policies for particular POMDPs to obtain robust performance and (ii) the union POMDP, which "averages" the individual POMDPs in the subset, does not necessarily provide an adequate abstraction and provides worse results than the enumeration even when it is tractable to solve it.
Full HM-POMDPs. We observe similar trends to the previous setting; however, our approach's benefits are even more significant. GA-U and SAYNT-U are sometimes competitive with RFPG on the three benchmarks with smaller I, as it is more probable that useful POMDPs end up in the union. For the more complex benchmarks with large I, in most cases, the baselines cannot produce policies with a value better than 80% of the value produced by RFPG. For the most complex benchmark, DPM, the gap between RFPG and the best baseline (SAYNT-U) is 36%. We also observe that RFPG considerably improves RFPG-S on these benchmarks, which demonstrates the scalability of our approach: RFPG can effectively reason about HM-POMDPs describing over 130000 environments.
(Q2) Generalization Recall Table 1 to compare RFPG-S and the baselines. These results show how well the policies optimized for the same subset can generalize to unseen POMDPs in the HM-POMDP. Except for the Network benchmark, RFPG-S provides much better generalization to the full HM-POMDP. The most complex benchmark, DPM, shows a gap of 26% between RFPG-S and the best baseline.
(Q3) Ablation with random POMDP selection The learning curves in Figure 3 demonstrate the role of robust policy evaluation within our approach. For the Network benchmark with a modest number of POMDPs, the random selection of the POMDP has a decent chance of sampling useful POMDPs for policy optimization, which is similar to what we observed for GA-U and SAYNT-U. Therefore, the performance is competitive with RFPG, yet RFPG performs slightly better on average. On the other hand, for DPM, the HM-POMDP describes over a hundred thousand POMDPs, and the learning curve clearly shows that robust policy evaluation is essential for more complex problems with more POMDPs: random selection leads to policies that achieve significantly worse values with very high fluctuation of values during the learning process.
6 Conclusion
HM-POMDPs encapsulate sets of POMDPs, with the assumption that the true model is hidden within the set. The problem is to find a robust policy for all POMDPs. We separated the concerns of robust policy evaluation to pick worst-case POMDPs and perform gradient ascent on the set of POMDPs to optimize a policy. The experimental evaluation confirms that our approach has two key benefits compared to the baselines: (1) the policies achieve better generalization to unseen POMDPs, and (2) it scales to HM-POMDPs with over one hundred thousand POMDPs. As such, the paper presents the first approach that can effectively solve HM-POMDPs, an important and practically-relevant subclass of robust POMDPs.
Ethical Statement
There are no ethical issues.
Acknowledgments
This research has been partially funded by the ERC Starting Grant 101077178 (DEUCE), and the project VASSAL: "Verification and Analysis for Safety and Security of Applications in Life" funded by the European Union under Horizon Europe WIDERA Coordination and Support Action/Grant Agreement No. 101160022. Additionally, this work has been partially funded by the NWO VENI Grant ProMiSe (222.147) and the Czech Science Foundation grant GA23-06963S (VESCAA).
@inproceedings{ijcai2025p947,
  title     = {Robust Finite-Memory Policy Gradients for Hidden-Model POMDPs},
  author    = {Galesloot, Maris F. L. and Andriushchenko, Roman and Ceska, Milan and Junges, Sebastian and Jansen, Nils},
  booktitle = {Proceedings of the Thirty-Fourth International Joint Conference on
               Artificial Intelligence, {IJCAI-25}},
  publisher = {International Joint Conferences on Artificial Intelligence Organization},
  editor    = {James Kwok},
  pages     = {8518--8526},
  year      = {2025},
  month     = {8},
  note      = {Main Track},
  doi       = {10.24963/ijcai.2025/947},
  url       = {https://doi.org/10.24963/ijcai.2025/947},
}
TY - CPAPER TI - Robust Finite-Memory Policy Gradients for Hidden-Model POMDPs AU - Galesloot, Maris F. L. AU - Andriushchenko, Roman AU - Ceska, Milan AU - Junges, Sebastian AU - Jansen, Nils T2 - Proceedings of the Thirty-Fourth International Joint Conference on Artificial Intelligence, IJCAI-25 PB - International Joint Conferences on Artificial Intelligence Organization PY - 2025 SP - 8518 EP - 8526 DO - 10.24963/ijcai.2025/947 UR - https://doi.org/10.24963/ijcai.2025/947 ER -Copied
Machine-readable versions of this paper, for tools and AI agents:





