
Spectral Pruning: Compressing Deep Neural Networks via Spectral Analysis and its Generalization Error
Proceedings of the Twenty-Ninth International Joint Conference on Artificial Intelligence. Main track. Pages 2839-2846.
https://doi.org/10.24963/ijcai.2020/393
Keywords
- Machine Learning: Deep Learning
- Machine Learning: Deep-learning Theory
- Machine Learning: Feature Selection; Learning Sparse Models
- Machine Learning: Learning Theory
Abstract
Compression techniques for deep neural network models are becoming very important
for the efficient execution of high-performance deep learning systems on edge-computing devices.
The concept of model compression is also important for analyzing the generalization error of deep learning, known as the compression-based error bound.
However, there is still huge gap between a practically effective compression method and its rigorous background of statistical learning theory. To resolve this issue, we develop a new theoretical framework for model compression
and propose a new pruning method called {\it spectral pruning} based on this framework.
We define the ``degrees of freedom'' to quantify the intrinsic dimensionality of a model
by using the eigenvalue distribution of the covariance matrix across the internal nodes
and show that the compression ability is essentially controlled by this quantity.
Moreover, we present a sharp generalization error bound of the compressed model
and characterize the bias--variance tradeoff induced by the compression procedure.
We apply our method to several datasets to justify our theoretical analyses and show the superiority of the the proposed method.
- [Aghasi et al., 2017] Alireza Aghasi, Afshin Abdi, Nam Nguyen, and Justin Romberg. Net-trim: Convex pruning of deep neural networks with performance guarantee. In Advances in Neural Information Processing Systems 30, pages 3180-3189. 2017.
- [Arora et al., 2018] Sanjeev Arora, Rong Ge, Behnam Neyshabur, and Yi Zhang. Stronger generalization bounds for deep nets via a compression approach. In Proceedings of the 35th International Conference on Machine Learn- ing, volume 80, pages 254-263. PMLR, 2018.
- [Bach, 2017] Francis Bach. On the equivalence between ker- nel quadrature rules and random feature expansions. Jour- nal of Machine Learning Research, 18(21):1-38, 2017.
- [Bartlett et al., 2019] Peter Bartlett, Nick Harvey, Christo- pher Liaw, and Abbas Mehrabian. Nearly-tight VC- dimension and pseudodimension bounds for piecewise lin- ear neural networks. Journal of Machine Learning Re- search, 20(63):1-17, 2019.
- [Caponnetto and de Vito, 2007] Andrea Caponnetto and Ernesto de Vito. Optimal rates for regularized least- squares algorithm. Foundations of Computational Mathematics, 7(3):331-368, 2007.
- [Deng et al., 2009] Jia Deng, Wei Dong, Richard Socher, Li- Jia Li, Kai Li, and Li Fei-Fei. Imagenet: A large-scale hierarchical image database. In Computer Vision and Pat- tern Recognition, 2009, pages 248-255, 2009.
- [Denil et al., 2013] Misha Denil, Babak Shakibi, Laurent Dinh, and Nando de Freitas. Predicting parameters in deep learning. In Advances in neural information processing systems 26, pages 2148-2156, 2013.
- [Denton et al., 2014] Emily L Denton, Wojciech Zaremba, Joan Bruna, Yann LeCun, and Rob Fergus. Exploiting linear structure within convolutional networks for efficient evaluation. In Advances in Neural Information Processing Systems 27, pages 1269-1277. 2014.
- [Dziugaite and Roy, 2017] Gintare Karolina Dziugaite and Daniel M. Roy. Computing nonvacuous generalization bounds for deep (stochastic) neural networks with many more parameters than training data. In Proceedings of the 33rd Conference on Uncertainty in Artificial Intelligence, 2017.
- [Gunasekar et al., 2018] Suriya Gunasekar, Jason D Lee, Daniel Soudry, and Nati Srebro. Implicit bias of gradient descent on linear convolutional networks. In Advances in Neural Information Processing Systems 31, pages 9482- 9491, 2018.
- [Han et al., 2015] Song Han, Huizi Mao, and William J Dally. Deep compression: Compressing deep neural net- works with pruning, trained quantization and Huffman coding. arXiv preprint arXiv:1510.00149, 2015.
- [Hardt et al., 2016] Moritz Hardt, Ben Recht, and Yoram Singer. Train faster, generalize better: Stability of stochas- tic gradient descent. In Proceedings of the 33rd Interna- tional Conference on Machine Learning, volume 48, pages 1225-1234. PMLR, 2016.
- [He et al., 2016] Kaiming He, Xiangyu Zhang, Shaoqing Ren, and Jian Sun. Deep residual learning for image recognition. In Proceedings of the IEEE Conference on Computer Vision and Pattern Recognition, pages 770-778, 2016.
- [He et al., 2017] Yihui He, Xiangyu Zhang, and Jian Sun. Channel pruning for accelerating very deep neural net- works. In Proceedings of the IEEE Conference on Com- puter Vision and Pattern Recognition, pages 1389-1397, 2017.
- [Krause and Golovin, 2014] Andreas Krause and Daniel Golovin. Submodular function maximization. In Tractability, 2014.
- [Krogh and Hertz, 1992] Anders Krogh and John A Hertz. A simple weight decay can improve generalization. In Ad- vances in Neural Information Processing Systems 5, pages 950-957, 1992.
- [Lebedev and Lempitsky, 2016] Vadim Lebedev and Victor Lempitsky. Fast convnets using group-wise brain damage. In Proceedings of the IEEE Conference on Computer Vi- sion and Pattern Recognition, pages 2554-2564, 2016.
- [Luo et al., 2017] Jian-Hao Luo, Jianxin Wu, and Weiyao Lin. ThiNet: a filter level pruning method for deep neural network compression. In Proceedings of the IEEE Interna- tional Conference on Computer Vision, pages 5068-5076, 2017.
- [Maas et al., 2013] Andrew Maas, Awni Hannun, and An- drew Ng. Rectifier nonlinearities improve neural network acoustic models. In ICML Workshop on Deep Learning for Audio, Speech and Language Processing, 2013.
- [Mallows, 1973] Colin L Mallows. Some comments on Cp. Technometrics, 15(4):661-675, 1973.
- [Simonyan and Zisserman, 2014] Karen Simonyan and An- drew Zisserman. Very deep convolutional networks for large-scale image recognition. arXiv preprint arXiv:1409.1556, 2014.
- [Suzuki et al., 2020a] Taiji Suzuki, Hiroshi Abe, Tomoya Murata, Shingo Horiuchi, Kotaro Ito, Tokuma Wachi, So Hirai, Masatoshi Yukishima, and Tomoaki Nishimura. Spectral pruning: Compressing deep neural networks via spectral analysis and its generalization error. arXiv preprint arXiv:1808.08558v2, 2020.
- [Suzuki et al., 2020b] Taiji Suzuki, Hiroshi Abe, and To- moaki Nishimura. Compression based bound for non- compressed network: Unified generalization error analy- sis of large compressible deep neural network. In Interna- tional Conference on Learning Representations, 2020.
- [Suzuki, 2018] Taiji Suzuki. Fast generalization error bound of deep learning from a kernel perspective. In Proceed- ings of the 21st International Conference on Artificial In- telligence and Statistics, volume 84, pages 1397-1406.
- PMLR, 2018.
- [Wager et al., 2013] Stefan Wager, Sida Wang, and Percy S Liang. Dropout training as adaptive regularization. In Advances in Neural Information Processing Systems 26, pages 351-359. 2013.
- [Wan et al., 2013] Li Wan, Matthew Zeiler, Sixin Zhang, Yann Le Cun, and Rob Fergus. Regularization of neu- ral networks using dropconnect. In Proceedings of the 30th International Conference on Machine Learning, vol- ume 28, pages 1058-1066. PMLR, 2013.
- [Wen et al., 2016] Wei Wen, Chunpeng Wu, Yandan Wang, Yiran Chen, and Hai Li. Learning structured sparsity in deep neural networks. In Advances in Neural Information Processing Systems 29, pages 2074-2082. 2016.
- [Yu et al., 2018] Ruichi Yu, Ang Li, Chun-Fu Chen, Jui- Hsin Lai, Vlad I Morariu, Xintong Han, Mingfei Gao, Ching-Yung Lin, and Larry S Davis. NISP: Pruning net- works using neuron importance score propagation. In Pro- ceedings of the IEEE Conference on Computer Vision and Pattern Recognition, pages 9194-9203, 2018.
- [Zhou et al., 2019] Wenda Zhou, Victor Veitch, Morgane Austern, Ryan P. Adams, and Peter Orbanz. Non-vacuous generalization bounds at the imagenet scale: a PAC- bayesian compression approach. In International Confer- ence on Learning Representations, 2019.
References were extracted automatically from the PDF and may contain errors.
Full text extracted automatically from the PDF; figures, tables and equations may differ. The PDF is the version of record.
1 Introduction
Currently, deep learning is the most promising approach adopted by various machine learning applications such as computer vision, natural language processing, and audio processing. Along with the rapid development of the deep learning techniques, its network structure is becoming considerably complicated. In addition to the model structure, the model size is also becoming larger, which prevents the implementation of deep neural network models in edge-computing devices for applications such as smartphone services, autonomous vehicle driving, and drone control. To overcome this problem, model compression techniques such as pruning, factorization [Denil et al., 2013; Denton et al., 2014], and quantization [Han et al., 2015] have been extensively studied in the literature.
Among these techniques, pruning is a typical approach that discards redundant nodes, e.g., by explicit regularization such as ℓ1 and ℓ2 penalization during training [Lebedev and Lempitsky, 2016; Wen et al., 2016; He et al., 2017]. It has been implemented as ThiNet [Luo et al., 2017], Net-Trim [Aghasi et al., 2017], NISP [Yu et al., 2018], and so on [Denil et al., 2013]. A similar effect can be realized by implicit random[Wan et al., 2013],
which randomly removes connections during the training phase. However, only few of these techniques (e.g., Net-Trim [Aghasi et al., 2017]) are supported by statistical learning theory. In particular, it unclear which type of quantity controls the compression ability. On the theoretical side, compressionbased generalization analysis is a promising approach for measuring the redundancy of a network [Arora et al., 2018; Zhou et al., 2019]. However, despite their theoretical novelty, the connection of these generalization error analyses to practically useful compression methods is not obvious.
In this paper, we develop a new compression based generalization error bound and propose a new simple pruning method that is compatible with the generalization error analysis. Our method aims to minimize the information loss induced by compression; in particular, it minimizes the redundancy among nodes instead of merely looking at the amount of information of each individual node. It can be executed by simply observing the covariance matrix in the internal layers and is easy to implement. The proposed method is supported by a comprehensive theoretical analysis. Notably, the approximation error induced by compression is characterized by the notion of the statistical degrees of freedom [Mallows, 1973; Caponnetto and de Vito, 2007]. It represents the intrinsic dimensionality of a model and is determined by the eigenvalues of the covariance matrix between each node in each layer. Usually, we observe that the eigenvalue rapidly decreases (Fig. 1a) for several reasons such as explicit regularization (Dropout [Wager et al., 2013], weight decay [Krogh and Hertz, 1992]), and implicit regularization [Hardt et al., 2016; Gunasekar et al., 2018], which means that the amount of important information processed in each layer is not large. In particular, the rapid decay in eigenvalues leads to a low number of degrees of freedom. Then, we can effectively compress a trained network into a smaller one that has fewer parameters than the original. Behind the theory, there is essentially a connection to the random feature technique for kernel methods [Bach, 2017]. Compression error analysis is directly connected to generalization error analysis. The derived bound is actually much tighter than the naive VC-theory bound on the uncompressed network [Bartlett et al., 2019] and even tighter than recent compression-based bounds [Arora et al., 2018]. Further, there is a tradeoff between the bias and the variance, where the bias is induced by the network compression and the variance is induced by the variation in the training data. In addition, we show the superiority of our method and experimentally verify our theory with extensive numerical experiments. Our contributions are summarized as follows:
- We give a theoretical compression bound which is compatible with a practically useful pruning method, and propose a new simple pruning method called spectral pruning for compressing deep neural networks.
- We characterize the model compression ability by utilizing the notion of the degrees of freedom, which represents the intrinsic dimensionality of the model. We also give a generalization error bound when a trained network is compressed by our method and show that the bias-variance tradeoff induced by model compression appears. The obtained bound is fairly tight compared with existing compression-based bounds and much tighter than the naive VC-dimension bound.
2 Model Compression Problem and its Algorithm
Suppose that the training data Dtr = {(xi, yi)}ni=1 are observed, where xi ∈ Rdx is an input and yi is an output that could be a real number (yi ∈ R), a binary label (yi ∈ {±1}), and so on. The training data are independently and identically distributed. To train the appropriate relationship between x and y, we construct a deep neural network model as
where W (ℓ) ∈ Rmℓ+1×mℓ , b(ℓ) ∈ Rmℓ+1 (ℓ = 1, . . . ,L), and η : R → R is an activation function (here, the activation function is applied in an element-wise manner; for a vector x ∈ Rd , η(x) = (η(x1), . . . , η(xd))⊤). Here, mℓ is the width of the ℓ-th layer such that mL+1 = 1 (output) and m1 = dx (input). Let ̂ f be a trained network obtained from the training data Dtr = {(xi, yi)}ni=1 where its parameters are denoted by ( ˆW (ℓ) ,ˆb(ℓ) )Lℓ=1 , i.e., ̂ f(x) = ( ˆW (L) η(·) + ˆb(L) ) ◦ · · · ◦ ( ˆW (1)x + ˆb(1) ). The input to the ℓ-th layer (after activation) is denoted by φ(ℓ) (x) = η ◦ ( ˆW (ℓ-1) η(·) +ˆb(ℓ-1) ) ◦ · · · ◦ ( ˆW (1)x +ˆb(1) ). We do not specify how to train the network ̂ f, and the following argument can be applied to any learning method such as the empirical risk minimizer, the Bayes estimator, or another estimator. We want to compress the trained network ̂ f to another smaller one f ♯ having widths (m♯ℓ )Lℓ=1 with keeping the test accuracy as high as possible.
To compress the trained network ̂ f to a smaller one f ♯ , we propose a simple strategy called spectral pruning. The main idea of the method is to find the most informative subset of the nodes. The amount of information of the subset is measured by how well the selected nodes can explain the other nodes in the layer and recover the output to the next layer. For example, if some nodes are heavily correlated with each other, then only one of them will be selected by our method. The information redundancy can be computed by a covariance matrix between nodes and a simple regression problem. We do not need to solve a specific nonlinear optimization problem unlike the methods in [Lebedev and Lempitsky, 2016; Wen et al., 2016; Aghasi et al., 2017].
2.1 AlgorithmDescription
Our method basically simultaneously minimizes the input information loss and output information loss, which will be defined as follows.
(i) Input information loss. First, we explain the input information loss. Denote φ(x) = φ(ℓ) (x) for simplicity, and let φJ(x) = (φj(x))j∈J ∈ Rm♯ℓ be a subvector of φ(x) corresponding to an index set J ∈ [mℓ]m♯ℓ , where [m] := {1, . . . ,m} (here, duplication of the index is allowed). The basic strategy is to solve the following optimization problem so that we can recover φ(x) from φJ (x) as accurately as possible:
where ̂E[·] is the expectation with respect to the empirical distribution (̂E[f] = 1n ∑ni=1 f(xi)) and ‖A‖2τ = Tr[AIτA⊤] for a regularization parameter τ ∈ R|J| + and Iτ := diag (τ) (how to set the regularization parameter will be given in Theorem 1). The optimal solution ˆ AJ can be explicitly expressed by utilizing the (noncentered) covariance matrix in the ℓ-th layer of the trained network ̂ f, which is defined as ̂Σ := ̂Σ(ℓ) = 1n ∑ni=1 φ(xi)φ(xi)⊤, defined on the empirical distribution (here, we omit the layer index ℓ for notational simplicity). Let ̂ΣI,I ′ ∈ RK×H for K,H ∈ N be the submatrix of ̂Σ for the index sets I ∈ [mℓ]K and I ′ ∈ [mℓ]H such that ̂ΣI,I ′ = (̂Σi,j)i∈I,j∈I ′ . Let F = {1, . . . ,mℓ} be the full index set. Then, we can easily see that
Hence, the full vector φ(x) can be decoded from φJ(x) as φ(x) ≈ ˆ AJφJ(x) = ̂ΣF,J(̂ΣJ,J + Iτ)-1φJ(x). To measure the approximation error, we define L(A) τ (J) = minA∈Rmℓ×|J| ̂E[‖φ - AφJ‖2 ] + ‖A‖2τ . By substituting the explicit formula ˆ AJ into the objective, this is reformulated as
(ii) Output information loss. Next, we explain the output information loss. Suppose that we aim to directly approximate the outputs Z (ℓ)φ for a weight matrix Z (ℓ) ∈ Rm×mℓ with an output size m ∈ N. A typical situation is that Z (ℓ) = ˆW (ℓ) so that we approximate the output ˆW (ℓ)φ (the concrete setting of Z (ℓ) will be specified in Theorem 1). Then, we consider the objective
where Z (ℓ) j,: means the j-th raw of the matrix Z (ℓ) . It can be easily checked that the optimal solution ˆαJ of the minimum in the definition of L(B) τ is given as ˆαJ = ˆ A⊤J Z (ℓ)⊤ j,: for each j = 1, . . . ,m.
(iii) Combination of the input and output information losses. Finally, we combine the input and output information losses and aim to minimize this combination. To do so, we propose to the use of the convex combination of both criteria for a parameter 0 ≤ θ ≤ 1 and optimize it with respect to J under a cardinality constraint |J| = m♯ℓ for a prespecified width m♯ℓ of the compressed network:
We call this method spectral pruning. There are the hyperparameter θ and regularization parameter τ. However, we see that it is robust against the choice of hyperparameter in experiments (Sec. 5). Let J ♯ ℓ be the optimal J that minimizes the objective. This optimization problem is NP-hard, but an approximate solution is obtained by the greedy algorithm since it is reduced to maximization of a monotonic submodular function [Krause and Golovin, 2014]. That is, we start from J = ∅, sequentially choose an element j ∗ ∈ [mℓ] that maximally reduces the objective L(θ) τ , and add this element j ∗ to J (J ← J ∪ {j ∗ }) until |J| = m♯ℓ is satisfied.
After we chose an index J ♯ ℓ (ℓ = 2, . . . ,L) for each layer, we construct the compressed network f ♯ as f ♯ (x) = (W ♯(L) η(·) + b♯(L) ) ◦ · · · ◦ (W ♯(1)x + b♯(1) ), where W ♯(ℓ) = W (ℓ) J ♯ ℓ+1 ,F ˆ A(ℓ) J ♯ ℓ and b♯(ℓ) = b(ℓ) J ♯ ℓ+1 .
An application to a CNN is given in the appendix of the long version of this paper [Suzuki et al., 2020a]. The method can be executed in a layer-wise manner, thus it can be applied to networks with complicated structures such as ResNet.
3 Compression accuracy Analysis and Generalization Error Bound
In this section, we give a theoretical guarantee of our method. First, we give the approximation error induced by our pruning procedure in Theorem 1. Next, we evaluate the generalization error of the compressed network in Theorem 2. More specifically, we introduce a quantity called the degrees of freedom [Mallows, 1973; Caponnetto and de Vito, 2007;
Suzuki, 2018; Suzuki et al., 2020b] that represents the intrinsic dimensionality of the model and determines the approximation accuracy.
For the theoretical analysis, we define a neural network model with norm constraints on the parameters W (ℓ) and b(ℓ) (ℓ = 1, . . . , L). Let R > 0 and Rb > 0 be the upper bounds of the parameters, and define the norm-constrained model as
where W (ℓ) j,: means the j-th raw of the matrix W (ℓ) , ‖ · ‖ is the Euclidean norm, and ‖ · ‖∞ is the ℓ∞-norm 1 . We make the following assumption for the activation function, which is satisfied by ReLU and leaky ReLU [Maas et al., 2013].
Assumption 1. We assume that the activation function η satisfies (1) scale invariance: η(ax) = aη(x) for all a > 0 and x ∈ Rd and (2) 1-Lipschitz continuity: |η(x) - η(x′ )| ≤ ‖x - x′ ‖ for all x, x′ ∈ Rd , where d is arbitrary.
3.1 Approximation Error Analysis
Here, we evaluate the approximation error derived by our pruning procedure. Let (m♯ℓ )Lℓ=1 denote the width of each layer of the compressed network f ♯ . We characterize the approximation error between f ♯ and ̂ f on the basis of the degrees of freedom with respect to the empirical L2-norm ‖g‖2n := 1n ∑ni=1 ‖g(xi)‖2 , which is defined for a vectorvalued function g. Recall that the empirical covariance matrix in the ℓ-th layer is denoted by ̂Σ(ℓ) . We define the degrees of freedom as
where (ˆµ(ℓ) j )mℓ j=1 are the eigenvalues of ̂Σ(ℓ) sorted in decreasing order. Roughly speaking, this quantity quantifies the number of eigenvalues above λ, and thus it is monotonically decreasing w.r.t. λ. The degrees of freedom play an essential role in investigating the predictive accuracy of ridge regression [Mallows, 1973; Caponnetto and de Vito, 2007; Bach, 2017]. To characterize the output information loss, we also define the output aware degrees of freedom with respect to a matrix Z (ℓ) as
This quantity measures the intrinsic dimensionality of the output from the ℓ-th layer for a weight matrix Z (ℓ) . If the covariance ̂Σ(ℓ) and the matrix Z (ℓ) are near low rank, ˆN ′ ℓ (λ;Z (ℓ) ) becomes much smaller than ˆNℓ(λ). Finally, we define N θ ℓ (λ) := θ ˆNℓ(λ) + (1 - θ) ˆN ′ ℓ (λ; Z (ℓ) ).
To evaluate the approximation error induced by compression, we define λℓ > 0 as
1 We are implicitly supposing R,Rb ≃ 1 so that ‖W (ℓ) ‖F, ‖b(ℓ) ‖ = O(1).
Conversely, we may determine m♯ℓ from λℓ to obtain the theorems we will mention below. Along with the degrees of freedom, we define the leverage score ˜ τ (ℓ) ∈ Rmℓ as ˜ τ (ℓ) j := 1 ˆNℓ(λℓ) [̂Σ(ℓ) (̂Σ(ℓ) + λℓI)-1 ]j,j (j ∈ [mℓ]). Note that ∑mℓ j=1 ˜ τ (ℓ) j = 1 originates from the definition of the degrees of freedom. The leverage score can be seen as the amount of contribution of node j ∈ [mℓ] to the degrees of freedom. For simplicity, we assume that ˜ τ (ℓ) j > 0 for all ℓ, j (otherwise, we just need to neglect such a node with ˜ τ (ℓ) j = 0).
For the approximation error bound, we consider two situations: (i) (Backward procedure) spectral pruning is applied from ℓ = L to ℓ = 2 in order, and for pruning the ℓ-th layer, we may utilize the selected index J ♯ ℓ+1 in the ℓ + 1-th layer and (ii) (Simultaneous procedure) spectral pruning is simultaneously applied for all ℓ = 2, . . . , L. We provide a statement for only the backward procedure. The simultaneous procedure also achieves a similar bound with some modifications. For the complete statement of the theorem, see the appendix of the long version [Suzuki et al., 2020a].
As for Z (ℓ) for the output information loss, we set
nally, we set the regularization parameter τ as τ ← m♯ℓλℓ˜ τ (ℓ) .
Theorem 1 (Compression rate via the degrees of freedom). If we solve the optimization problem (2) with the additional constraint ∑j∈J (˜ τ (ℓ) j )-1 ≤ 5 3 mℓm♯ℓ for the index set J, then the optimization problem is feasible, and the overall approximation error of f ♯ is bounded by
for ¯R = √ˆ cR, where ˆ c is a universal constant, and ζℓ,θ := N θ ℓ (λℓ) (θ maxj∈[mℓ+1 ] ‖ ˆW (ℓ) j,: ‖2 ‖( ˆW (ℓ) )⊤Iq(ℓ) ˆW (ℓ) ‖op + (1 - θ)mℓ)-1 2 .
The proof is given in the appendix of the long version [Suzuki et al., 2020a]. To prove the theorem, we essentially need to use theories of random features in kernel methods [Bach, 2017; Suzuki, 2018]. The main message from the theorem is that the approximation error induced by compression is directly controlled by the degrees of freedom. Since the degrees of freedom ˆNℓ(λ) are a monotonically decreasing function with respect to λ, they become large as λ decreases to 0. The behavior of the eigenvalues determines how rapidly ˆNℓ(λ) increases as λ → 0. We can see that if the eigenvalues ˆµ(ℓ) 1 ≥ ˆµ(ℓ) 2 ≥ . . . rapidly decrease, then the approximation error λℓ can be much smaller for a given model size m♯ℓ . In other words, f ♯ can be much closer to the original network ̂ f if there are only a few large eigenvalues.
2 ‖ · ‖op represents the operator norm of a matrix (the largest absolute singular value).
The quantity ζℓ,θ characterizes how well the approximation error λℓ′ of the lower layers ℓ′ ≤ ℓ propagates to the final output. We can see that a tradeoff between ζℓ,θ and θ appears. By a simple evaluation, N θ ℓ in the numerator of ζℓ,θ is bounded by mℓ; thus, θ = 1 gives ζℓ,θ ≤ 1. On the other hand, the
thus, θ = 1 is not necessarily the best choice to maximize the denominator. From this consideration, we can see that the value of θ that best minimizes ζℓ,θ exists between 0 and 1, which supports our numerical result (Fig. 2b). In any situation, small degrees of freedom give a small ζℓ,θ, leading to a sharper bound.
3.2 Generalization Error Analysis
Here, we derive the generalization error bound of the compressed network with respect to the population risk. We will see that a bias-variance tradeoff induced by network compression appears. As usual, we train a network through the training error ̂Ψ(f) := 1n ∑ni=1 ψ(yi, f(xi)), where ψ : R×R→R is a loss function. Correspondingly, the expected error is denoted by Ψ(f) := E[ψ(Y, f(X))], where the expectation is taken with respect to (X, Y ) ∼ P . Our aim here is to bound the generalization error Ψ(f ♯ ) of the compressed network. Let the marginal distribution of X be PX and that of y be PY. First, we assume the Lipschitz continuity for the loss function ψ.
Assumption 2. The loss function ψ is ρ-Lipschitz continuous: |ψ(y, f) - ψ(y, f ′ )| ≤ ρ|f - f ′ | (∀y ∈ supp(PY), ∀f, f ′ ∈ R). The support of PX is bounded: ‖x‖ ≤Dx (∀x ∈ supp(PX)).
For a technical reason, we assume the following condition for the spectral pruning algorithm.
Assumption 3. We assume that 0 ≤ θ ≤ 1 is appropriately chosen so that ζℓ,θ in Theorem 1 satisfies ζℓ,θ ≤ 1 almost surely, and spectral pruning is solved under the condition ∑j∈J (˜ τ (ℓ) j )-1 ≤ 5 3 mℓm♯ℓ on the index set J.
As for the choice of θ, this assumption is always satisfied at least by the backward procedure. The condition on the linear constraint on J is merely to ensure the leverage scores are balanced for the chosen index. Note that the bounds in Theorem 1 can be achieved even with this condition.
If L∞-norm of networks is loosely evaluated, the generalization error bound of deep learning can be unrealistically large because there appears L∞-norm in its evaluation. However, we may consider a truncated estimator [[ ̂ f(x)]] := max{-M,min{M, ̂ f(x)}} for sufficiently large 0 < M ≤ ∞ to moderate the L∞-norm (if M = ∞, this does not affect anything). Note that the truncation procedure does not affect the classification error for a classification task. To bound the generalization error, we define δ1 and δ2 for (m♯2 , . . . ,m♯L) and (λ2, . . . , λL) satisfying relation (3) as 3
3 log+(x) = max{1, log(x)}.
where ˆR∞ := min{ ¯RLDx + ∑Lℓ=1 ¯RL-ℓ ¯Rb,M}, ˆG := L ¯RL-1Dx + ∑Lℓ=1 ¯RL-ℓ for ¯R = √ˆ cR and ¯Rb = √ˆ cRb with the constants ˆ c introduced in Theorem 1. Let Rn,t := 1n (t + ∑Lℓ=2 log(mℓ)) for t > 0. Then, we obtain the following generalization error bound for the compressed network f ♯ .
Theorem 2 (Generalization error bound of the compressed network). Suppose that Assumptions 1, 2, and 3 are satisfied. Then, the spectral pruning method presented in Theorem 1 satisfies the following generalization error bound. There exists a universal constant C1 > 0 such that for any t > 0, it holds that
uniformly over all choices of m♯ = (m♯1 , . . . , m♯L) with probability 1 - 2e-t .
The proof is given in the appendix of the long version [Suzuki et al., 2020a]. From this theorem, the generalization error of f ♯ is upper-bounded by the training error of the original network ̂ f (which is usually small) and an additional term. By Theorem 1, δ1 represents the approximation error between ̂ f and f ♯ ; hence, it can be regarded as a bias. The second term δ2 is the variance term induced by the sample deviation. It is noted that the variance term δ2 only depends on the size of the compressed network rather than the original network size. On the other hand, a naive application of the theorem implies Ψ([[ ̂ f ]]) - ˆΨ([[ ̂ f]]) ≤ ˜O(√ 1n ∑Lℓ=1 mℓ+1mℓ ) for the original network ̂ f, which coincides with the VC-dimension based bound [Bartlett et al., 2019] but is much larger than δ2 when m♯ℓ ≪ mℓ. Therefore, the variance is significantly reduced by model compression, resulting in a much improved generalization error. Note that the relation between δ1 and δ2 is a tradeoff due to the monotonicity of the degrees of freedom. When m♯ℓ is large, the bias δ1 becomes small owing to the monotonicity of the degrees of freedom, but the variance δ2(m♯ ) will be large. Hence, we need to tune the size (m♯ℓ )Lℓ=1 to obtain the best generalization error by balancing the bias (δ1) and variance (δ2).
The generalization error bound is uniformly valid over the choice of m♯ (to ensure this, the term Rn,t appears). Thus, m♯ can be arbitrary and chosen in a data-dependent manner. This means that the bound is a posteriori, and the best choice of m♯ can depend on the trained network.
4 Relation to ExistingWork
A seminal work [Arora et al., 2018] showed a generalization error bound based on how the network can be compressed. Although the theoretical insights provided by their analysis are quite instructive, the theory does not give a practical compression method. In fact, a random projection is proposed in the analysis, but it is not intended for practical use. The most difference is that their analysis exploits the near low rankness of the weight matrix W (ℓ) , while ours exploits the near low rankness of the covariance matrix ̂Σ(ℓ) . They are not directly comparable; thus, we numerically compare the intrinsic dimensionality of both with a VGG-19 network trained on CIFAR-10. Table 1 summarizes a comparison of the intrinsic dimensionalities. For our analysis, we used ˆNℓ(λℓ) ˆNℓ+1(λℓ+1)k2 for the intrinsic dimensionality of the ℓ-th layer, where k is the kernel size 4 . This is the number of parameters in the ℓ-th layer for the width m♯ℓ ≃ ˆNℓ(λℓ) where λℓ was set as λℓ = 10-3 × Tr[̂Σ(ℓ)], which is sufficiently small. We can see that the quantity based on our degrees of freedom give significantly small values in almost all layers.
| Layer | Original | [Arora et al., 2018] | Spec Prun |
|---|---|---|---|
| 1 | 1,728 | 1,645 | 1,013 |
| 4 | 147,456 | 644,654 | 84,499 |
| 6 | 589,824 | 3,457,882 | 270,216 |
| 9 | 1,179,648 | 36,920 | 50,768 |
| 12 | 2,359,296 | 22,735 | 4,583 |
| 15 | 2,359,296 | 26,584 | 3,886 |
The PAC-Bayes bound [Dziugaite and Roy, 2017; Zhou et al., 2019] is also a promising approach for obtaining the nonvacuous generalization error bound of a compressed network. However, these studies "assume" the existence of effective compression methods and do not provide any specific algorithm. [Suzuki, 2018; Suzuki et al., 2020b] also pointed out the importance of the degrees of freedom for analyzing the generalization error of deep learning but did not give a practical algorithm.
5 Numerical Experiments
In this section, we conduct numerical experiments to show the validity of our theory and the effectiveness of the proposed method.
5.1 Eigenvalue Distribution and Compression Ability
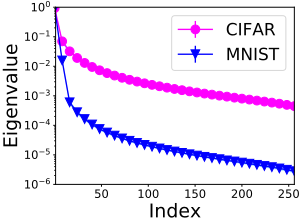
We show how the rate of decrease in the eigenvalues affects the compression accuracy to justify our theoretical analysis. We constructed a network (namely, NN3) consisting of three hidden fully connected layers with widths (300, 1000, 300) following the settings in [Aghasi et al., 2017] and trained it with 60,000 images in MNIST and 50,000 images in CIFAR10. Figure 1a shows the magnitudes of the eigenvalues of the 3rd hidden layers of the networks trained for each dataset
4 We omitted quantities related to the depth L and log term, but the intrinsic dimensionality of [Arora et al., 2018] also omits these factors.
- (b) Approximation error with its s.d. versus the width m♯
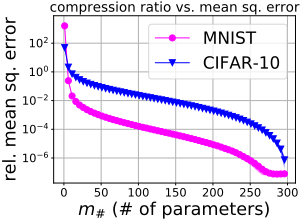
Figure 1: Eigenvalue distribution and compression ability of a fully connected network in MNIST and CIFAR-10.
(plotted on a semilog scale). The eigenvalues are sorted in decreasing order, and they are normalized by division by the maximum eigenvalue. We see that eigenvalues for MNIST decrease much more rapidly than those for CIFAR-10. This indicates that MINST is "easier" than CIFAR-10 because the degrees of freedom (an intrinsic dimensionality) of the network trained on MNIST are relatively smaller than those trained on CIFAR-10. Figure 1b presents the (relative) compression error ‖ ̂ f - f ♯ ‖n/‖ ̂ f‖n versus the width m♯3 of the compressed network where we compressed only the 3rd layer and λ3 was fixed to a constant 10-6 ×Tr[̂Σ(ℓ)] and θ = 0.5. It shows a rapid decrease in the compression error for MNIST than CIFAR-10 (about 100 times smaller). This is because MNIST has faster eigenvalue decay than CIFAR-10.
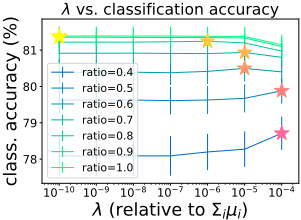
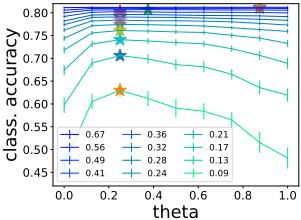
Figure 2a shows the relation between the test classification accuracy and λℓ. It is plotted for a VGG-13 network trained on CIFAR-10. We chose the width m♯ℓ that gave the best accuracy for each λℓ under the constraint of the compression rate (relative number of parameters). We see that as the compression rate increases, the best λℓ goes down. Our theorem tells that λℓ is related to the compression error through (3), that is, as the width goes up, λℓ must goes down. This experiment supports the theoretical evaluation. Figure 2b shows the relation between the test classification accuracy and the hyperparameter θ. We can see that the best accuracy is achieved around θ = 0.3 for all compression rates, which indicates the superiority of the "combination" of input- and output-
- (b) Accuracy versus θ in CIFAR-10 for each compression rate.
Figure 2: Relation between accuracy and the hyper parameters λℓ and θ. The best λ and θ are indicated by the star symbol.
information loss and supports our theoretical bound. For low compression rate, the choice of λℓ and θ does not affect the result so much, which indicates the robustness of the hyperparameter choice.
5.2 Compression on ImageNet Dataset
We applied our method to the ImageNet (ILSVRC2012) dataset [Deng et al., 2009]. We compared our method using the ResNet-50 network [He et al., 2016] (experiments for VGG-16 network [Simonyan and Zisserman, 2014] are also shown in the long version [Suzuki et al., 2020a]). Our method was compared with the following pruning methods: ThiNet [Luo et al., 2017], NISP [Yu et al., 2018], and sparse regularization [He et al., 2017] (which we call Sparse-reg). As the initial ResNet network, we used two types of networks: ResNet-50-1 and ResNet-50-2. For training ResNet-50-1, we followed the experimental settings in [Luo et al., 2017] and [Yu et al., 2018]. During training, images were resized as in [Luo et al., 2017]. to 256 × 256; then, a 224 × 224 random crop was fed into the network. In the inference stage, we center-cropped the resized images to 224 × 224. For training ResNet-50-2, we followed the same settings as in [He et al., 2017]. In particular, images were resized such that the shorter side was 256, and a center crop of 224 × 224 pixels was used for testing. The augmentation for fine tuning was a 224 × 224 random crop and its mirror.
We compared ThiNet and NISP for ResNet-50-1 (we call our model for this situation "Spec-ResA") and Sparse-reg for ResNet-50-2 (we call our model for this situation "SpecResB") for fair comparison. The size of compressed network f ♯ was determined to be as close to the compared network as possible (except, for ResNet-50-2, we did not adopt the "channel sampler" proposed by [He et al., 2017] in the first layer of the residual block; hence, our model became slightly larger). The accuracies are borrowed from the scores presented in each paper, and thus we used different models because the original papers of each model reported for each different model. We employed the simultaneous procedure for compression. After pruning, we carried out fine tuning over 10 epochs, where the learning rate was 10-3 for the first four epochs, 10-4 for the next four epochs, and 10-5 for the last two epochs. We employed λℓ = 10-6 ×Tr[̂Σ(ℓ)] and θ = 0.5.
| Model | Top-1 | Top-5 | # Param. | FLOPs |
|---|---|---|---|---|
| ResNet-50-1 | 72.89% | 91.07% | 25.56M | 7.75G |
| ThiNet-70 | 72.04 % | 90.67% | 16.94M | 4.88G |
| ThiNet-50 | 71.01 % | 90.02% | 12.38M | 3.41G |
| NISP-50-A | 72.68% | - | 18.63M | 5.63G |
| NISP-50-B | 71.99% | - | 14.57M | 4.32G |
| Spec-ResA | 72.99% | 91.56% | 12.38M | 3.45G |
| ResNet-50-2 | 75.21% | 92.21% | 25.56M | 7.75G |
| Sparse-reg wo/ ft | - | 84.2% | 19.78M | 5.25G |
| Sparse-reg w/ ft | - | 90.8% | 19.78M | 5.25G |
| Spec-ResB wo/ ft | 66.12% | 86.67% | 20.69M | 5.25G |
| Spec-ResB w/ ft | 74.04% | 91.77% | 20.69M | 5.25G |
Table 2 summarizes the performance comparison for ResNet-50. We can see that for both settings, our method outperforms the others for about 1% accuracy. This is an interesting result because ResNet-50 is already compact [Luo et al., 2017] and thus there is less room to produce better performance. Moreover, we remark that all layers were simultaneously trained in our method, while other methods were trained one layer after another. Since our method did not adopt the channel sampler proposed by [He et al., 2017], our model was a bit larger. However, we could obtain better performance by combining it with our method.
6 Conclusion
In this paper, we proposed a simple pruning algorithm for compressing a network and gave its approximation and generalization error bounds using the degrees of freedom. Unlike the existing compression based generalization error analysis, our analysis is compatible with a practically useful method and further gives a tighter intrinsic dimensionality bound. The proposed algorithm is easily implemented and only requires linear algebraic operations. The numerical experiments showed that the compression ability is related to the eigenvalue distribution, and our algorithm has favorable performance compared to existing methods.
Acknowledgements
TS was partially supported by MEXT Kakenhi (18K19793, 18H03201 and 20H00576) and JST-CREST, Japan.
@inproceedings{ijcai2020p393,
  title     = {Spectral Pruning: Compressing Deep Neural Networks via Spectral Analysis and its Generalization Error},
  author    = {Suzuki, Taiji and Abe, Hiroshi and Murata, Tomoya and Horiuchi, Shingo and Ito, Kotaro and Wachi, Tokuma and Hirai, So and Yukishima, Masatoshi and Nishimura, Tomoaki},
  booktitle = {Proceedings of the Twenty-Ninth International Joint Conference on
               Artificial Intelligence, {IJCAI-20}},
  publisher = {International Joint Conferences on Artificial Intelligence Organization},
  editor    = {Christian Bessiere},
  pages     = {2839--2846},
  year      = {2020},
  month     = {7},
  note      = {Main track},
  doi       = {10.24963/ijcai.2020/393},
  url       = {https://doi.org/10.24963/ijcai.2020/393},
}
TY - CPAPER TI - Spectral Pruning: Compressing Deep Neural Networks via Spectral Analysis and its Generalization Error AU - Suzuki, Taiji AU - Abe, Hiroshi AU - Murata, Tomoya AU - Horiuchi, Shingo AU - Ito, Kotaro AU - Wachi, Tokuma AU - Hirai, So AU - Yukishima, Masatoshi AU - Nishimura, Tomoaki T2 - Proceedings of the Twenty-Ninth International Joint Conference on Artificial Intelligence, IJCAI-20 PB - International Joint Conferences on Artificial Intelligence Organization PY - 2020 SP - 2839 EP - 2846 DO - 10.24963/ijcai.2020/393 UR - https://doi.org/10.24963/ijcai.2020/393 ER -Copied
Machine-readable versions of this paper, for tools and AI agents:





