
MMT: Multi-way Multi-modal Transformer for Multimodal Learning
Proceedings of the Thirty-First International Joint Conference on Artificial Intelligence. Main Track. Pages 3458-3465.
https://doi.org/10.24963/ijcai.2022/480
Keywords
- Machine Learning: Multi-modal learning
Abstract
The heart of multimodal learning research lies the challenge of effectively exploiting fusion representations among multiple modalities.However, existing two-way cross-modality unidirectional attention could only exploit the intermodal interactions from one source to one target modality. This indeed fails to unleash the complete expressive power of multimodal fusion with restricted number of modalities and fixed interactive direction.In this work, the multiway multimodal transformer (MMT) is proposed to simultaneously explore multiway multimodal intercorrelations for each modality via single block rather than multiple stacked cross-modality blocks. The core idea of MMT is the multiway multimodal attention, where the multiple modalities are leveraged to compute the multiway attention tensor. This naturally benefits us to exploit comprehensive many-to-many multimodal interactive paths. Specifically, the multiway tensor is comprised of multiple interconnected modality-aware core tensors that consist of the intramodal interactions. Additionally, the tensor contraction operation is utilized to investigate intermodal dependencies between distinct core tensors.Essentially, our tensor-based multiway structure allows for easily extending MMT to the case associated with an arbitrary number of modalities. Taking MMT as the basis, the hierarchical network is further established to recursively transmit the low-level multiway multimodal interactions to high-level ones. The experiments demonstrate that MMT can achieve state-of-the-art or comparable performance.
- [Ain et al., 2017] Qurat Tul Ain, Mubashir Ali, Amna Riaz, Amna Noureen, Muhammad Kamran, Babar Hayat, and A Rehman. Sentiment analysis using deep learning tech- niques: a review. Int J Adv Comput Sci Appl, 8(6):424, 2017.
- [Hazarika et al., 2020] Devamanyu Hazarika, Roger Zim- mermann, and Soujanya Poria. Misa: Modality-invariant and-specific representations for multimodal sentiment analysis. In Proceedings of the 28th ACM International Conference on Multimedia, pages 1122-1131, 2020.
- [Liang et al., 2018] Paul Pu Liang, Ziyin Liu, Amir Zadeh, and Louis-Philippe Morency. Multimodal language anal- ysis with recurrent multistage fusion. arXiv preprint arXiv:1808.03920, 2018.
- [Liu et al., 2018] Zhun Liu, Ying Shen, Varun Bharadhwaj Lakshminarasimhan, Paul Pu Liang, Amir Zadeh, and Louis-Philippe Morency. Efficient low-rank multimodal fusion with modality-specific factors. arXiv preprint arXiv:1806.00064, 2018.
- [Nojavanasghari et al., 2016] Behnaz Nojavanasghari, Deepak Gopinath, Jayanth Koushik, Tadas Baltrušaitis, and Louis-Philippe Morency. Deep multimodal fusion for persuasiveness prediction. In Proceedings of the 18th ACM International Conference on Multimodal Interaction, pages 284-288, 2016.
- [Park et al., 2014] Sunghyun Park, Han Suk Shim, Moitreya Chatterjee, Kenji Sagae, and Louis-Philippe Morency. Computational analysis of persuasiveness in social mul- timedia: A novel dataset and multimodal prediction ap- proach. In Proceedings of the 16th International Confer- ence on Multimodal Interaction, pages 50-57, 2014.
- [Pham et al., 2019] Hai Pham, Paul Pu Liang, Thomas Manzini, Louis-Philippe Morency, and Barnabás Póczos. Found in translation: Learning robust joint representations by cyclic translations between modalities. In Proceed- ings of the AAAI Conference on Artificial Intelligence, vol- ume 33, pages 6892-6899, 2019.
- [Poria et al., 2017] Soujanya Poria, Erik Cambria, Deva- manyu Hazarika, Navonil Majumder, Amir Zadeh, and Louis-Philippe Morency. Context-dependent sentiment analysis in user-generated videos. In Proceedings of the 55th annual meeting of the association for computa- tional linguistics (volume 1: Long papers), pages 873- 883, 2017.
- [Rahman et al., 2020] Wasifur Rahman, Md Kamrul Hasan, Sangwu Lee, Amir Zadeh, Chengfeng Mao, Louis- Philippe Morency, and Ehsan Hoque. Integrating mul- timodal information in large pretrained transformers. In Proceedings of the conference. Association for Computa- tional Linguistics. Meeting, volume 2020, page 2359. NIH Public Access, 2020.
- [Rajagopalan et al., 2016] Shyam Sundar Rajagopalan, Louis-Philippe Morency, Tadas Baltrusaitis, and Roland Goecke. Extending long short-term memory for multi- view structured learning. In European Conference on Computer Vision, pages 338-353. Springer, 2016.
- [Soleymani et al., 2017] Mohammad Soleymani, David Gar- cia, Brendan Jou, Björn Schuller, Shih-Fu Chang, and Maja Pantic. A survey of multimodal sentiment analysis. Image and Vision Computing, 65:3-14, 2017.
- [Sun et al., 2020] Zhongkai Sun, Prathusha Sarma, William Sethares, and Yingyu Liang. Learning relationships be- tween text, audio, and video via deep canonical correla- tion for multimodal language analysis. In Proceedings of the AAAI Conference on Artificial Intelligence, volume 34, pages 8992-8999, 2020.
- [Tsai et al., 2018] Yao-Hung Hubert Tsai, Paul Pu Liang, Amir Zadeh, Louis-Philippe Morency, and Ruslan Salakhutdinov. Learning factorized multimodal represen- tations. arXiv preprint arXiv:1806.06176, 2018.
- [Tsai et al., 2019] Yao-Hung Hubert Tsai, Shaojie Bai, Paul Pu Liang, J Zico Kolter, Louis-Philippe Morency, and Ruslan Salakhutdinov. Multimodal transformer for un- aligned multimodal language sequences. In Proceedings of the conference. Association for Computational Linguis- tics. Meeting, volume 2019, page 6558. NIH Public Ac- cess, 2019.
- [Wang et al., 2019] Yansen Wang, Ying Shen, Zhun Liu, Paul Pu Liang, Amir Zadeh, and Louis-Philippe Morency. Words can shift: Dynamically adjusting word represen- tations using nonverbal behaviors. In Proceedings of the AAAI Conference on Artificial Intelligence, volume 33, pages 7216-7223, 2019.
- [Wu et al., 2020] Liangqing Wu, Dong Zhang, Qiyuan Liu, Shoushan Li, and Guodong Zhou. Speaker personality recognition with multimodal explicit many2many interac- tions. In 2020 IEEE International Conference on Multi- media and Expo (ICME), pages 1-6, 2020.
- [Yu et al., 2021] Wenmeng Yu, Hua Xu, Ziqi Yuan, and Jiele Wu. Learning modality-specific representations with self- supervised multi-task learning for multimodal sentiment analysis. arXiv preprint arXiv:2102.04830, 2021.
- [Zadeh et al., 2016] Amir Zadeh, Rowan Zellers, Eli Pincus, and Louis-Philippe Morency. Multimodal sentiment in- tensity analysis in videos: Facial gestures and verbal mes- sages. IEEE Intelligent Systems, 31(6):82-88, 2016.
- [Zadeh et al., 2017] Amir Zadeh, Minghai Chen, Soujanya Poria, Erik Cambria, and Louis-Philippe Morency. Tensor fusion network for multimodal sentiment analysis. arXiv preprint arXiv:1707.07250, 2017.
- [Zadeh et al., 2018a] Amir Zadeh, Paul Pu Liang, Navonil Mazumder, Soujanya Poria, Erik Cambria, and Louis- Philippe Morency. Memory fusion network for multi-view sequential learning. In Proceedings of the AAAI Confer- ence on Artificial Intelligence, volume 32, 2018.
- [Zadeh et al., 2018b] Amir Zadeh, Paul Pu Liang, Soujanya Poria, Prateek Vij, Erik Cambria, and Louis-Philippe Morency. Multi-attention recurrent network for human communication comprehension. In Proceedings of the AAAI Conference on Artificial Intelligence, volume 32, 2018.
References were extracted automatically from the PDF and may contain errors.
Full text extracted automatically from the PDF; figures, tables and equations may differ. The PDF is the version of record.
1 Introduction
Multimodal learning is a very actively growing field of research, which has witnessed many significant advances in sentiment analysis and speaker personality recognition [Ain et al., 2017]. Indeed, the multimodal signals such as text modality, visual modality, and acoustic modality consist of complementarity and consistency. Consequently, the heart of multimodal learning lies the challenge of effectively accounting for the both intra-modality and inter-modality intercorrelations among multiple modalities.
∗Equal contribution
†Corresponding author: Wanzeng Kong
More recently, with the advent of self-attention mechanism, transformer-based fusion frameworks [Soleymani et al., 2017] have been extensively employed for exploiting the long-range dependencies of modalities. For instance, MISA [Hazarika et al., 2020] and MAG [Rahman et al., 2020] leverage self-attention to retrieve the contextual embeddings of textual modality. Note that, the self-attention focuses on highlighting the intra-modality dependencies within the individual modality, leading to a lack of explicit interaction among different modalities. On the basis of conventional selfattention, MulT [Tsai et al., 2019] proposes a novel crossmodality two-way attention component, which benefits the model to directly explore the explicit cross-modality intercorrelations within two-way space. However, the unidirectional cross-modality attention could only exploit the intermodality interactions from one source to one target modality. Therefore, the above architectures have shown the limitation in offering the much more representative capability with the fixed interactive direction and restricted number of involved modalities, e.g., only up to two modalities. This indeed overlooks the complex and essential global interactions among more modalities, which results in the information loss and the deterioration of prediction. Essentially, their model attempt to sequentially stack distinct twoway cross-modality attention blocks into the hierarchical one for the multimodal learning task, ie., (text → visual) → acoustic. Intuitevely, this sequential one-to-one procedure {Modalityi} → {Modalityj} would lead to the significant increase of cost in computation and memory.
To overcome the above underlying research issues, we propose the multi-way multi-modal Transformer (MMT), a method that extends the standard Transformer framework to analyze multiple modalities simultaneously. The core idea of MMT is the tensor-based multiway multimodal attention, which provides an M-dimension Multiway Interactive Dot product
(
)
Multiway Multimodal Attention block
(a) MMT{X1,X2,X3}→{X1,X2,X3}
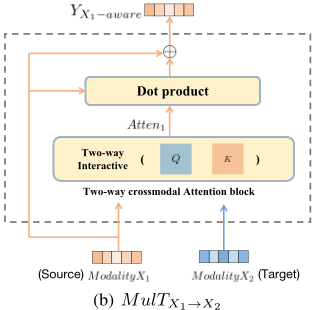
attention space that consists of many-to-many multimodal interactive paths {Modality1, · · · ,ModalityM} → {Modality1, · · · ,ModalityM}, where M indicates the modality number. This naturally contributes to both intramodality and complex inter-modality interactions. Thanks to the low-rank tensor fashion, the proposed module has the superior capability to simultaneously explore the multiway multimodal attention space for each modality within the single attention block rather than multiple stacked crossmodality blocks. Indeed, the presented fashion allows for all the potential and comprehensive multiway interactions, as well as a much lighter model. It is important to note that, compared to the existing two-way attention module, the tensor-based multiway structure naturally provides us the great flexibility to extend MMT to the case associated with an arbitrary number of modalities. Intuitively, MMT is able to scale linearly in the number of modalities. Subsequently, taking MMT as the basis, the hierarchical architecture is established to transmit the low-level multiway multimodal intercorrelations to the high-level sophisticated presentation with the recursive fashion.
2 RelatedWork
2.1 Non-attention basedModel
RMFN [Liang et al., 2018] introduced the RNN to process the data with the multistage fusion method. BC-LSTM [Poria et al., 2017] presented a bi-directional LSTM to exploit the temporal dependencies. MV-LSTM [Rajagopalan et al., 2016] and Self-MM [Yu et al., 2021] utilized the multi-view (multitask) strategy to compute sentiment information. Analogously, ICCN [Sun et al., 2020], DF [Nojavanasghari et al., 2016] and MISA attempt to capture the correlations across multiple modalities via similarity bock. Moreover, tensorbased works such as TFN [Zadeh et al., 2017] and LMF [Liu et al., 2018] proposed a multi-dimension fusion fashion to explicitly highlight multimodal intercorrelations among multiple messages.Nevertheless, the above frameworks fail to effectively draw the long-range temporal dependencies along the sequence.
2.2 Attention-basedModel
Compared to the above models, the attention-based network such as MFM [Tsai et al., 2018] is able to model long-range dependencies of the modality. RAVEN [Wang et al., 2019] proposed a multimodal attention gating block. Similarly, MAG proposed the multimodal attention gating component. MCTN [Pham et al., 2019] utilized the cyclic translation network to investigate multimodal representations. MFN [Zadeh et al., 2018a] leveraged the Delta-memory attention to analyze the private modality portion. On the contrast, MARN [Zadeh et al., 2018b] employed multimodal attention to highlight cross-modality dynamics. MEMI [Wu et al., 2020] introduced the cross-modality attention to measure the twoway interactions. Additionally, MulT presented the two-way cross-modality attention to exploit the inter-modality unidirectional interactions. However, the above manners fail to exploit all the potential and comprehensive multimodal interactions, due to the fixed interactive direction and restricted number of involved modalities (only up to two modalities). Essentially, the existing models attempt to stack multiple crossmodality blocks into the hierarchical one for realizing the multimodal learning task, thus suffering from the significant increase of computational complexity and memory.
3 Methodology
3.1 Preliminaries
In this part, we attempt to introduce the notation of the tensor network utilized in our model, and present in detail the conventional self-attention and cross-modality attention mechanism.
Tensor Network
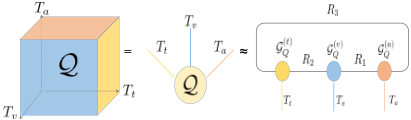
Multi-dimensional array can be represented by tensor. Specifically, an Nth-order tensor S ∈ RI1×···×IN has N dimensions, and the specific entry of S is denoted by si1,i2,··· ,iN = S(i1, i2, · · · , iN), where iN ∈ {1, 2, · · · , IN}. Additionally, the tensor network - Tensor Ring can be further employed to decompose the higher-order tensor S into the low-rank case. That is to say, a set of interconnected lowerrank tensors (core tensors) JG (1) , · · · , G (N) K could be utilized to represent S. Notation JK is a simplified version of tensor ring decomposition. Note that, the hadamard product denoted as ⊛ and the mode-1 Khatri-Rao product denoted as ⊙1 are the essential operators in tensor analysis. Given two tensors A ∈ RI1×I2×I3 and B ∈ RI1×I2×I3 , the hadamard product yieds a 3-order tensor C = A ⊛ B ∈ RI1×I2×I3 with entries C(i1, i2, i3) = A(i1, i2, i3)B(i1, i2, i3). Given two matrixes A ∈ RN×P1 and B ∈ RN×P2 , the mode-1 Khatri-Rao product yieds a matrix C = A ⊙1 B =∈ RN×P1P2 .
Self-attention and Cross-modality Attention
At the heart of Transformer is the self-attention mechanism, which attends to the long-range dependencies within the unimodality sequence. More specifically, Transformer is comprised of query, key and value matrix denoted as Q, K, V respectively. Considering the modalities set {Audio, Video, Text}, the utterance-level presentation are represented as Xa ∈ RTa×da , Xv ∈ RTv×dv , and Xt ∈ RTt×dt , respectively. In practice, Ti is utilized to denote sequence length, and di refers to the feature dimension. The corresponding audio-based self-attention procedure can be written as:Attention(Qa,Ka, Va) = softmax( QaKT a √dk )Va, which only focus on the intra-modality correlations from the unimodality feature space.
On the basis of self-attention mechanism, MulT proposed the cross-modality attention mechanism, which performs the unidirectional cross-modal adaption within the two-way fusion space that consists of two corresponding modalities. For instance, the adaption text(t) → audio(a) can be written as Attention(Qa, Kt, Vt) = sof tmax( QaKT t √dk )Vt, which attends to the inter-modality correlations. Note that, the twoway cross-modality attention requires 4 transformer blocks {MulTt→a, MulTa→t, MulTa→a, MulTt→t} to obtain the cross-modality dependencies that consist of both intramodality and inter-modality interactions. More importantly, the extension of MulT to M modalities would require M 2 transformer blocks, which results in the significant increase of computations and storage.
3.2 Multi-wayMulti-modal Transformer
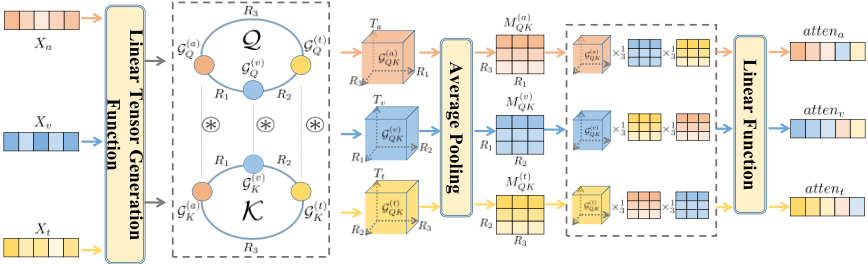
In this paper, tensor-based multi-way multi-modal attention is proposed to produce the rich representations for each modality by simultaneously paying attention to all the potential multiway interactions. Overall, our proposed MMT could accepts multiple inputs {Xa,Xv,Xt}, and produces the modality-aware multiway multimodal fusion outputs {Ya-aware, Yv-aware, Yt-aware}.
Given modality presentation {Xt, Xv, Xa}, we first adopt a tensor-ring based generation function for retrieving the multiway multimodal query tensor Q = JG (t) Q , G (v) Q , G (a) Q K ∈ RTa×Tv×Tt and key tensor K = JG (t) K , G (v) K , G (a) K K ∈ RTa×Tv×Tt . Note that, the tensor ring format naturally provides us the benefit of efficiently measuring the attention score on the low-rank core tensors (G(i) Q ∈ RTi×Rw×Rs , G (i) K ∈ RTi×Rw×Rs ) rather than original large tensors (Q , K), contributing to the great decrease of model storage and complexity, where the index i ∈ {a, v, t}. Note that, Rw and Rs refer to the tensor-ring rank, the index w and s ∈ {1, 2, 3}, and w ̸= s. The above function can be formulated as:
where the linear transformation matrixes {W (1) Qi ∈ Rdi×Rw , W (2) Qi ∈ Rdi×Rs } are utilized to account for the low-rank projection of input. Additionally, the mode-1 Khatri-Rao product ⊙1 is introduced to incorporate the low-rank projections into the modality-aware core tensor G (i) Q . Similarly, the key tensor K is received based on the same generation procedure.
Based on the above query tensor Q and key tensor K with the tensor ring format, the multiway multimodal attention procedure can be presented as follows:
Then, the Hadamard product ⊛ is introduced to analyze the similarity between G (i) Q and G (i) K , which allows for exploiting modality-based attention spaces G (i) QK ∈ RTi×Rw×Rs in parallel. Indeed, above process is analogous to self-attention process (QKT ) in the standard Transformer framework. This naturally results in the multiway multimodal attention tensor QK = JG (t) QK , G (v) QK , G (a) QK K ∈ RTa×Tv×Tt . The attention core tensor G (i) QK are presented as follows:
Subsequently, the corresponding attention pooling matrixes M (i) QK ∈ RRw×Rs are captured by averaging the G (i) QK along the temporal dimension (Ti), where each element of M (i) QK is comprised of the intra-modality temporal dependencies. Notably, the M (i) QK are then transmitted to the next process for integrating the distinct intra-modality attribution into the multi-way multi-modality attention message.
Given the modality-based attention pooling matrixes M (i) QK , we now attempt to explore the modality-aware multiway multimodal attention attent, attenv and attena. The detailed process is formulated as:
where atteni refer to the modality-aware multiway multimodal attention matrix, 'M' is the modality number, i ∈ {a, v, t}, jm ∈ {a, v, t}, and jm ̸= i. Moreover, operation ×mn refers to the mode-(mn ) product (tensor contraction operation). More specifically, the mode -(13 ) product of tensor G (t) QK and matrix M (a) QK , with the common mode R3, yields a 3-order cross-modality attention tensor is of Tt × R2 × R1. Actually, the above process allows us to efficiently compute the cross-modality attention space, e.g., (G (t) QK ×13 M (a) QK ), which effectively highlights the intercorrelations between text and audio modality. Compared to the conventional cross-modality two-way attention that only focuses on the inter-modality interactive path, our method simultaneously attends to the both intra-modality and complex inter-modality interactive paths. Then, the mode -(13 ) product of the above 3-order tensor (G (t) QK ×13 M (a) QK ) and matrix M (v) QK , with the common mode R1, yields a 3-order tensor is of Tt × R2 × R2. Intuitively, above procedure allows the cross-modality tensor further absorb the contribution from video modality, contributing to the comprehensive manyto-many multimodal interactive paths {t, a, v} → {t, a, v}. Note that, {t, a, v} → {t, a, v} is comprised of the comprehensive many-to-many multimodal interactive paths, which could provide intra-modality and complex inter-modality interactions simultaneously. More specifically, Xi → Xi refer to the intra-modality interactions, and Xi → Xj refer to the inter-modality interactions (i ̸= j), where i, j ∈ {t, a, v}. Then, the linear projection function is further applied to retrieve the text-aware multiway multimodality attention matrix attent .
In an addition, the modality-aware multiway multimodality presentation is achieved with the help of corresponding multiway attention matrix and a parameter a. Note that, a is introduced to blend the contribution of modality-aware multiway multimodality message and the original modality information, leading to the much more comprehensive multimodal representation.
Note that, the tensor-ring function allows us to exploit inter-modality attention from low-rank small core tensors rather than original Mth-order large tensor, where M is the number of modality. This indeed significantly reduce the complexity and storage. If tensor-ring function is done after getting attention, the number of parameters of Mth-order tensor grows exponentially with 'M', i.e., parameters = 2 × T1 ×T2×, · · · ,×TM.
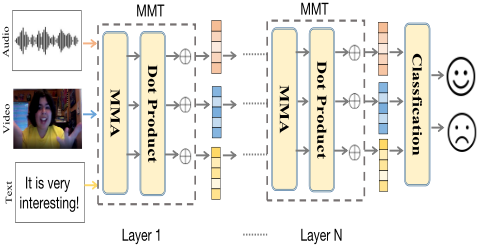
Fig 3: Hierarchical Framework
3.3 Hierarchical Architecture
On the basis of MMT, a hierarchical architecture was proposed for transmitting the low-level multiway multimodal intercorrelations to the much more comprehensive and expressive high-level intercorrelations with the recursive fashion. As illustrated in Figure 4, the proposed framework is comprised of N stacked MMT blocks. Specifically, the first MMT accepts the inputs {Xa,Xv,Xt} and computes the modality-aware multiway multimodal presentation outputs set {Ya-aware, Yv-aware, Yt-aware}. Subsequently, the next MMT takes the outputs of the previous MMT as the inputs, and latently performs the similar multiway multimodal attention procedure. As a result, the much more comprehensive and expressive multimodal intercorrelations can be identified and transmitted to the high-level layer via hierarchical structure. The overall recursive procedure is formulated as follows:
Note that, due to the tensor-based multiway attention strategy, the (i + 1) - th layer of the proposed hierarchical architecture is able to accept the inputs {Y (i) a-aware , Y (i) v-aware , Y (i) t-aware } from the previous i - th layer recursively. That is to say, the presented multiway scheme indeed provides great expressive capability and flexibility of the learning model, giving each layer the strong ability to efficiently perform similar multiway multimodal attention based on the previous multiple outputs.
4 Experiments Setups
4.1 Datasets
The public sentiment benchmark CMU-MOSI [Zadeh et al., 2016] is comprised of the aligned and preprocessed audio, video and text modality. CMU-MOSI consists of 2199 opinion video clips. Each clip is annotated with the corresponding sentiment intensity in the range of [-3, +3], spanning from the strongly negative to the strongly positive sentiments. The 2199 clips are spilt into 1284 train samples, 229 validation samples, and 686 test samples. The POM dataset [Park et al., 2014] contains 903 movie opinion videos, which attends to the speaker trait recognition. Each video is annotated for following speaker traits with the strength score [1, 5] or [1, 7] : confident (con), passionate (pas), dominant (dom), vivid (viv), expertise (exp), entertaining (ent), and etc. The division of the train, validation and test sets is 600, 100 and 203, respectively.
4.2 Features and EvaluationMetrics
The modality features are leveraged in the same way as MEMI and MAG. The evaluation metrics are demonstrated as follows: 1) Mean Absolute Error (MAE) (lower is better); 2) Pearson's correlation (corr); 3) Binary Accuracy (Acc-2); 4) F1-Score (F1); 5)7-class Accuracy (Acc-7). Note that, two distinct manners are introduced to represent Acc-2 and F1: 1) negative/non-negative classification attached with the label [-3, 0) and [0, 3] [Zadeh et al., 2018b] 2) negative/positive classification attached with the label [-3, 0) and (0, 3] [Tsai et al., 2019]. The marker -/- is employed to distinguish the distinct strategies, where the left-side value refer to 1) and the right-side value stands for 2).
4.3 Comparisons
We introduce the non-attention and attention based models as the baselines. Non-attention based: RNN-based multistage fusion network (RMFN), Bi-directional LSTM (BC-LSTM), Multi-view LSTM (MV-LSTM), Interaction Canonical Correlation Network (ICCN), Modality-Invariant and -Specific Representations for Multimodal Sentiment Analysis (MISA), Tensor Fusion Network (TFN), Low-rank Multimodal Fusion (LMF), Deep multimodal fusion (DF). Attention-based: Recurrent Attended Variation Embedding Network (RAVEN), Multimodal Adaptation Gate (MAG), Multimodal Cyclic Translation Network (MCTN), Memory Fusion Network (MFN), Multi-attention Recurrent Network (MARN), Multimodal Factorization Model (MFM), Multimodal Explicit Many2many Interactions(MEMI), Multimodal Transformer (MulT), Self-Supervised Multi-task Multimodal model (SelfMM).
4.4 Training Details andModel Complexity
The grid-search is performed over the hyper-parameters to find the model with the best validation task loss. The range of key hyper-parameters are summarized as follows: layer [2, 7], tensor rank [2, 8], residual parameter α [0.1, 0.7]. The complexity of baselines built upon Bert are summarized as follows: MulT (O(M 2 × d2i × Ti)), TFN (O(dy ∏Mi=1 di)), LMF (O(dy × Rw × ∏Mi=1 di)), MISA(O(M × d2i × Ti)), MAG(O(∏Mi=1 Ti ×di)), ICCN(O(M×Ti ×d2i )). Note that, the complexity of our 'MMT' is O(M ×di ×Ti(Rw +Rs)), where di>Rw(Rs). Note that our approach use smaller model rather than larger model, while achieving better performance.
5 Experiments Results and Analysis
5.1 Performance Comparison with State-of-the-art Models
Firstly, we analyze the performance between our MMT and the state-of-the-art baselines. The bottom rows in Table 1 and Table 2 illustrate the results of our model. Note that ⊗ from [Tsai et al., 2019]; a from [Sun et al., 2020]. As shown in Table 1 (CMU-MOSI), we can find that MMT exceeds the previous best MAG on all metrics. Particularly, our MMT outperforms the previous best MISA on the 'Acc-7' by a margin of 5.9%. It is interesting to observe that, our MMT obtains the much better 'MAE' (lower is better) than the two-way crossmodality attention model MulT (Bert), with a large margin of 20.4%. As shown in Table 2 (POM), MMT exceeds the MulT on the 'Corr' of Con by a margin of 14.3%. This indeed implies the superior expressive capability and efficiency of the proposed multiway multimodality attention mechanism and the hierarchical structure. Compared to the two-way attention model, our presented MMT is capable of exploring the multiway attention space that consists of the many-to-many multimodal interactive path, which naturally benefits the learning model to measure both intermodal and intramodal interactions simultaneously. Essentially, thanks to the low-rank tensor-based strategy, MMT has the ability to effectively perform the multimodal learning task only with a relatively small number of storage and computational complexity.
| Models | CMU-MOSI | ||||
|---|---|---|---|---|---|
| MAE(↓) | Corr(↑) | Acc-2(↑) | F1(↑) | Acc-7(↑) | |
| BC-LSTM | 1.079 | 0.581 | 73.9/- | 73.9/- | 28.7 |
| MV-LSTM | 1.019 | 0.601 | 73.9/- | 74.0/- | 33.2 |
| RMFN ⊗ | 0.922 | 0.681 | 78.4/- | 78.0/- | 38.3 |
| RAV EN ⊗ | 0.915 | 0.691 | 78.0/- | 76.6/- | 33.2 |
| MFN | 0.965 | 0.632 | 77.4/- | 77.3/- | 34.1 |
| MARN | 0.968 | 0.625 | 77.1/- | 77.0/- | 34.7 |
| TFN | 0.970 | 0.633 | 73.9/- | 73.4/- | 32.1 |
| LMF | 0.912 | 0.668 | 76.4/- | 75.7/- | 32.8 |
| MCTN ⊗ | 0.909 | 0.676 | 79.3/- | 79.1/- | 35.6 |
| MFM ⊗ | 0.951 | 0.662 | 78.1/- | 78.1/- | 36.2 |
| Bert | 0.739 | 0.782 | 83.5/85.2 | 83.4/85.2 | - |
| MulT | 0.871 | 0.698 | -/83.0 | -/82.8 | 40.0 |
| T F N (Bert)a | 0.901 | 0.698 | -/80.8 | -/80.7 | 34.9 |
| LMF(Bert)a | 0.917 | 0.695 | -/82.5 | -/82.4 | 33.2 |
| MulT (Bert) | 0.861 | 0.711 | 81.5/84.1 | 80.6/83.9 | - |
| ICCN (Bert) | 0.860 | 0.710 | -/83.0 | -/83.0 | 39.0 |
| MISA (Bert) | 0.783 | 0.761 | 81.8/83.4 | 81.7/83.6 | 42.3 |
| MAG (Bert) | 0.712 | 0.796 | 84.2/86.1 | 84.1/86.0 | - |
| Self-MM (Bert) | 0.713 | 0.798 | 84.0/85.98 | 84.42/85.95 | - |
| MMT (ours) (Bert) | 0.657 | 0.83 | 85.8/87.0 | 85.8/87.0 | 48.2 |
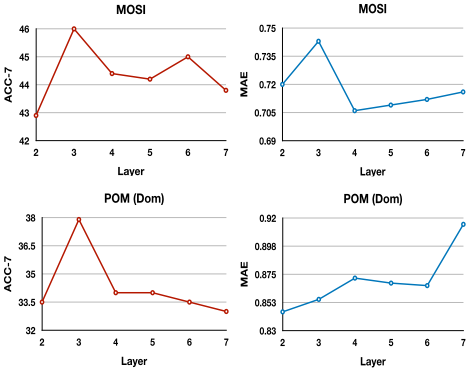
5.2 Effect of the Layer of the Framework
In this part, we attempt to investigate the impact of various layers of the hierarchical framework on the task performance. The layer varies from 2 to 7. As shown in Figure 5, we can observe that MMT reaches the peak value at the layer 3 on the 'Acc-7' on CMU-MOSI. Moreover, the MMT maximizes the performance at the layer 4 on the 'MAE' for the case of CMU-MOSI. As for the Dom of POM benchmark, MMT reaches the highest point at the layer 3 on the 'Acc-7', and the relatively higher performance peak at the layer 2 on the 'MAE'. Intuitively, the relative deeper framework bears the potential to exploit the much more comprehensive and sophisticated sentimental attribution among multiple modality presentations. Subsequently, the deeper cases naturally achieve better performance than the shallow ones. Additionally, the too complex MMT consists of overmuch redundancy message, which may result in the deterioration of the task performance. In conclusion, the experiment results demonstrate that the hierarchical structure indeed is able to provide greater expressive power and efficiency.
| Task Classes | Ent 7 | Con 7 | Pas 7 | Dom 7 | Viv 7 | Exp 5 |
|---|---|---|---|---|---|---|
| Metric | MAE ↓ | |||||
| LSTM | 0.996 | 1.073 | 1.148 | 0.904 | 1.045 | 1.067 |
| BC-LSTM | 0.988 | 1.089 | 1.141 | 0.915 | 1.024 | 1.096 |
| TFN | 1.062 | 1.491 | 1.335 | 1.077 | 1.184 | 1.215 |
| DF | 0.972 | 1.097 | 1.130 | 0.899 | 1.023 | 1.053 |
| MARN | 1.011 | 1.057 | 1.184 | 0.916 | 1.053 | 1.105 |
| MulT | 0.961 | 0.989 | 1.087 | 0.869 | 0.975 | 0.998 |
| MEMI | 0.952 | 0.979 | 1.108 | 0.856 | 0.959 | 0.957 |
| MMT (ours) | 0.911 | 0.941 | 0.987 | 0.845 | 0.944 | 0.934 |
| Metric | Corr ↑ | |||||
| LSTM | 0.176 | 0.233 | 0.179 | 0.201 | 0.172 | 0.153 |
| BC-LSTM | 0.083 | 0.200 | 0.219 | 0.318 | 0.241 | 0.177 |
| TFN | 0.265 | 0.159 | 0.158 | 0.067 | 0.232 | 0.149 |
| DF | 0.254 | 0.164 | 0.353 | 0.314 | 0.296 | 0.153 |
| MARN | 0.020 | 0.219 | 0.102 | 0.130 | 0.065 | -0.008 |
| MulT | 0.267 | 0.294 | 0.332 | 0.282 | 0.286 | 0.319 |
| MEMI | 0.275 | 0.432 | 0.327 | 0.395 | 0.392 | 0.365 |
| MMT (ours) | 0.386 | 0.437 | 0.43 | 0.368 | 0.363 | 0.418 |
| Metric | Acc (%) ↑ | |||||
| LSTM | 30.5 | 25.1 | 25.1 | 31.5 | 29.6 | 27.6 |
| BC-LSTM | 30.0 | 22.2 | 21.7 | 32.0 | 30.0 | 27.1 |
| TFN | 31.0 | 17.2 | 23.2 | 33.0 | 29.1 | 24.1 |
| DF | 27.6 | 25.1 | 21.7 | 31.5 | 28.6 | 27.1 |
| MARN | 32.5 | 28.6 | 24.6 | 34.5 | 31.0 | 27.6 |
| MulT | 31.5 | 25.1 | 31 | 34 | 35 | 27.6 |
| MEMI | 33.5 | 29.6 | 28.1 | 34.5 | 40.9 | 38.4 |
| MMT (ours) | 34.5 | 33.5 | 34 | 39.9 | 39.4 | 35.5 |
5.3 Effect of Tensor Ranks of Tensor-ring Network
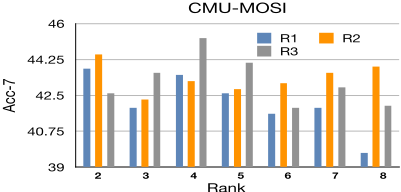
In this test, we are interested to examine how distinct tensor ranks affect the predictive performance of our tensor-based network. For simplicity, we attempt to analyze the performance of each ri separately, while the rest of tensor ranks rj are fixed, where j ̸= i. For instance, as shown in figure 6, r1 varies from 2 to 8, while r2 and r3 are fixed. In Figure 6, we can observe that the case of r1 and r2 achieve the
α
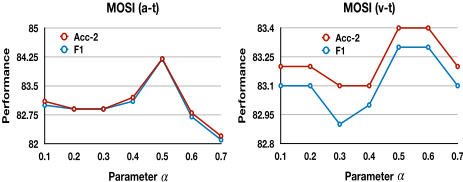
Figure 8: Effect of the residual parameter α on CMU-MOSI.
best performance at rank 2. Similarly, the case of r3 reaches the peak point at the relatively low-rank value rank 4. This implies that the tensor-based fashion indeed gives the learning model sufficient expressive capability to efficiently exploit the task-related representation. Notably, the fairly good results of low-rank cases demonstrate that tensor-based network is able to significantly decrease the computational complexity and storage without the greater deterioration of prediction. The above observations signify the effectiveness and necessity of leveraging the tensor network to deal with the multiway multimodal attention mechanism, when analyzing the case associated with an arbitrary number of modalities.
5.4 Effect of the Number of InvolvedModalities
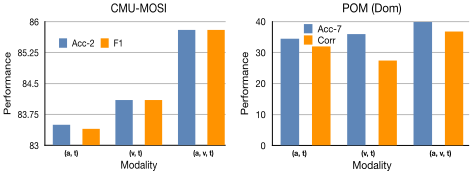
Due to the flexibility of our proposed multimodal learning architecture, we can provide a multiway multimodal attention space based on multiple involved modalities. Consequently, in this part, we attend to analyze the distinct framework design associated with the specific number of modalities. As shown in Figure 7, the multimodal case (a, v, t) performs significantly better than the bi-modality cases {(a, t), (v, t)}. And, the POM depicts similar results. The above performance may indicate that our MMT gives the model strong ability to highlight much more compact consistency and comprehensive complementarity within the multiway multimodal attention space, especially when the model includes much more modality information. Essentially, compared to results of the bi-way cross-modality attention model such as MulT which performed on the multimodal setting (a, v, t) (shown in Table 1), the test bi-modality setting (t, v) of our MMT obtains the comparable 'Acc-2' (84.1) and better 'F1' (84.1) precisions, indicating the great expressive power brought by the proposed multiway attention mechanism. Indeed, the biway cross-modality attention mechanism only concerns the intermodal interactions with the limits of structure, while MMT is able to provide both intermodal and intramodal intercorrelations.
5.5 Effect of the Residual Parameter α
In our work, the residual parameter α is introduced to blend the contribution of modality-aware multiway multimodality message and original modality message. Thus, we attempt to examine how distinct α affects the learning efficiency of the presented model. The α ranges from 0.1 to 0.7. Note that, all the modalities {audio, video, text} share the same α. For simplicity, the related testing are performed on the settings {(a, t), (v, t)}. In Figure 8, we can observe that the MMT can reach the good task performance with respect to the tested α. In particular, the proposed learning model maximizes the prediction results at the relatively low α 0.5 or 0.6 for all the testing settings. Intuitively, the case associated with the lower α mainly attends to the generated multimodal intercorrelations among the multiple modalities, and largely overlooks the intrinsic sentimental attribution of the modality. Thus, this may result in the lack of sufficient comprehensive multimodal sentiment properties, as well as the deterioration of the task performance. Additionally, the cases associated with the too large α are likely to mainly concentrate on the sentimental information of the original modality presentation, which may introduce too much redundancy to the final multimodal fusion message that may lead to the overfitting issue.
6 Conclusion
In this paper, we proposed the tensor-based multiway multimodal transformer for exploring the modality-aware multiway multimodal intercorrelations for each modality in parallel. Indeed, compared to the unidirectional cross-modality attention, MMT is able to accommodate all potential multiway sophisticated interactions from all modalities simultaneously, using the novel multiway multimodal attention. Essentially, the tensor-based network naturally provides us the great flexibility to extend MMT to the case associated with an arbitrary number of modalities. In addition, MMT enjoys great scalability with respect to the number of modalities. In practice, MMT can also serve as the strong baseline to efficiently analyze the relation-extraction tasks, leading to the much more latent and comprehensive relations within the multiway representative space.
Acknowledgments
This work was supported by National Key R&D Program of China for Intergovernmental International Science and Technology Innovation Cooperation Project (No. 2017YFE0116800), National Natural Science Foundation of China (Grant No.U20B2074, U1909202), JSPS KAKENHI (Grant No.20H04249, 20H04208), and supported by Key Laboratory of Brain Machine Collaborative Intelligence of Zhejiang Province (2020E10010).
@inproceedings{ijcai2022p480,
  title     = {MMT: Multi-way Multi-modal Transformer for Multimodal Learning},
  author    = {Tang, Jiajia and Li, Kang and Hou, Ming and Jin, Xuanyu and Kong, Wanzeng and Ding, Yu and Zhao, Qibin},
  booktitle = {Proceedings of the Thirty-First International Joint Conference on
               Artificial Intelligence, {IJCAI-22}},
  publisher = {International Joint Conferences on Artificial Intelligence Organization},
  editor    = {Luc De Raedt},
  pages     = {3458--3465},
  year      = {2022},
  month     = {7},
  note      = {Main Track},
  doi       = {10.24963/ijcai.2022/480},
  url       = {https://doi.org/10.24963/ijcai.2022/480},
}
TY - CPAPER TI - MMT: Multi-way Multi-modal Transformer for Multimodal Learning AU - Tang, Jiajia AU - Li, Kang AU - Hou, Ming AU - Jin, Xuanyu AU - Kong, Wanzeng AU - Ding, Yu AU - Zhao, Qibin T2 - Proceedings of the Thirty-First International Joint Conference on Artificial Intelligence, IJCAI-22 PB - International Joint Conferences on Artificial Intelligence Organization PY - 2022 SP - 3458 EP - 3465 DO - 10.24963/ijcai.2022/480 UR - https://doi.org/10.24963/ijcai.2022/480 ER -Copied
Machine-readable versions of this paper, for tools and AI agents:





