
Why Rumors Spread Fast in Social Networks, and How to Stop It
Proceedings of the Thirty-Second International Joint Conference on Artificial Intelligence. Main Track. Pages 234-242.
https://doi.org/10.24963/ijcai.2023/27
Keywords
- Agent-based and Multi-agent Systems: MAS: Agent theories and models
- Multidisciplinary Topics and Applications: MDA: Web and social networks
- Game Theory and Economic Paradigms: GTEP: Computational social choice
Abstract
We study a rumor spreading model where individuals are connected via a network structure. Initially, only a small subset of the individuals are spreading a rumor. Each individual who is connected to a spreader, starts spreading the rumor with some probability as a function of their trust in the spreader, quantified by the Jaccard similarity index. Furthermore, the probability that a spreader diffuses the rumor decreases over time until they fully lose their interest and stop spreading.
We focus on determining the graph parameters which govern the magnitude and pace that the rumor spreads in this model. We prove that for the rumor to spread to a sizable fraction of the individuals, the network needs to enjoy ``strong'' expansion properties and most nodes should be in ``well-connected'' communities. Both of these characteristics are, arguably, present in real-world social networks up to a certain degree, shedding light on the driving force behind the extremely fast spread of rumors in social networks.
Furthermore, we formulate a large range of countermeasures to cease the spread of a rumor. We introduce four fundamental criteria which a countermeasure ideally should possess. We evaluate all the proposed countermeasures by conducting experiments on real-world social networks such as Facebook and Twitter. We conclude that our novel decentralized countermeasures (which are executed by the individuals) generally outperform the previously studied centralized ones (which need to be imposed by a third entity such as the government).
- [Blondel et al., 2008] Vincent D Blondel, Jean-Loup Guil- laume, Renaud Lambiotte, and Etienne Lefebvre. Fast unfolding of communities in large networks. Jour- nal of Statistical Mechanics: Theory and Experiment, 2008(10):P10008, oct 2008.
- [Bredereck et al., 2021] Robert Bredereck, Lilian Jacobs, and Leon Kellerhals. Maximizing the spread of an opin- ion in few steps: opinion diffusion in non-binary networks. In Proceedings of the Twenty-Ninth International Confer- ence on International Joint Conferences on Artificial In- telligence (IJCAI), pages 1622-1628, 2021. IJCAI
- [Chen et al., 2011] Wei Chen, Alex Collins, Rachel Cum- mings, Te Ke, Zhenming Liu, David Rincon, Xiaorui Sun, Yajun Wang, Wei Wei, and Yifei Yuan. Influence maxi- mization in social networks when negative opinions may emerge and propagate. In Proceedings of the 2011 siam international conference on data mining, pages 379-390.
- [Coro et al., 2020] Federico Coro, Emilio Cruciani, Gian- lorenzo D'Angelo, and Stefano Ponziani. Exploiting so- cial influence to control elections based on scoring rules. In Proceedings of the twenty-Eighth international confer- ence on international joint conferences on artificial intel- ligence (IJCAI), 2020. IJCAI
- [Daley and Kendall, 1965] Daryl J Daley and David G Kendall. Stochastic rumours. IMA Journal of Applied Mathematics, 1(1):42-55, 1965.
- [Ding et al., 2020] Li Ding, Ping Hu, Zhi-Hong Guan, and Tao Li. An efficient hybrid control strategy for restraining rumor spreading. IEEE Transactions on Systems, Man, and Cybernetics: Systems, 51(11):6779-6791, 2020.
- [Dubhashi and Panconesi, 2009] Devdatt P Dubhashi and Alessandro Panconesi. Concentration of measure for the analysis of randomized algorithms. Cambridge University Press, 2009.
- [Feige et al., 1990] Uriel Feige, David Peleg, Prabhakar Raghavan, and Eli Upfal. Randomized broadcast in net- works. Random Structures & Algorithms, 1(4):447-460, 1990.
- [Figeac and Favre, 2021] Julien Figeac and Guillaume Favre. How behavioral homophily on social media in- fluences the perception of tie-strengthening within young adults' personal networks. New Media & Society, page 14614448211020691, 2021.
- [Friedman, 2003] Joel Friedman. A proof of alon's second eigenvalue conjecture. STOC, pages 720-724, 2003.
- [Gausen et al., 2021] Anna Gausen, Wayne Luk, and Ce Guo. Can we stop fake news? using agent-based modelling to evaluate countermeasures for misinforma- tion on social media. Workshop Proceedings of the 15th International AAAI Conference on Web and Social Media, 2021.
- [Giakkoupis and Sauerwald, 2012] George Giakkoupis and Thomas Sauerwald. Rumor spreading and vertex expan- sion. In Proceedings of the Twenty-Third Annual ACM- SIAM Symposium on Discrete Algorithms, SODA '12, page 1623-1641, USA, 2012. Society for Industrial and Applied Mathematics.
- [Giakkoupis, 2011] George Giakkoupis. Tight bounds for rumor spreading in graphs of a given conductance. In Symposium on Theoretical Aspects of Computer Science (STACS2011), volume 9, pages 57-68, 2011.
- [Goldenberg et al., 2001] Jacob Goldenberg, Barak Libai, and Eitan Muller. Talk of the network: A complex systems look at the underlying process of word-of-mouth. Market- ing letters, 12(3):211-223, 2001.
- [Goyal et al., 2010] Amit Goyal, Francesco Bonchi, and Laks VS Lakshmanan. Learning influence probabilities in social networks. In Proceedings of the third ACM inter- national conference on Web search and data mining, pages 241-250, 2010.
- [Granovetter, 1973] Mark S Granovetter. The strength of weak ties. American journal of sociology, 78(6):1360- 1380, 1973.
- [He et al., 2015] Zaobo He, Zhipeng Cai, and Xiaoming Wang. Modeling propagation dynamics and developing optimized countermeasures for rumor spreading in online social networks. In 2015 IEEE 35Th international con- ference on distributed computing systems, pages 205-214. IEEE, 2015.
- [Kempe et al., 2003] David Kempe, Jon Kleinberg, and Éva Tardos. Maximizing the spread of influence through a so- cial network. In Proceedings of the ninth ACM SIGKDD international conference on Knowledge discovery and data mining, pages 137-146, 2003.
- [Kimura et al., 2008] Masahiro Kimura, Kazumi Saito, and Hiroshi Motoda. Minimizing the spread of contamination by blocking links in a network. In AAAI, volume 8, pages 1175-1180, 2008.
- [Le et al., 2017] Can M Le, Elizaveta Levina, and Roman Vershynin. Concentration and regularization of random graphs. Random Structures & Algorithms, 51(3):538-561, 2017.
- [Leskovec and Krevl, 2014] Jure Leskovec and Andrej Krevl. SNAP Datasets: Stanford large network dataset collection. http://snap.stanford.edu/data, June 2014. Link
- [Lewandowsky and Van Der Linden, 2021] Stephan Lewandowsky and Sander Van Der Linden. Coun- tering misinformation and fake news through inoculation and prebunking. European Review of Social Psychology, 32(2):348-384, 2021.
- [Ma et al., 2016] Jing Ma, Wei Gao, Prasenjit Mitra, Sejeong Kwon, Bernard J. Jansen, Kam-Fai Wong, and Meeyoung Cha. Detecting rumors from microblogs with recurrent neural networks. In Proceedings of the Twenty-Fifth In- ternational Joint Conference on Artificial Intelligence, IJ- CAI'16, page 3818-3824. AAAI Press, 2016. IJCAI
- [Mossel and Roch, 2007] Elchanan Mossel and Sebastien Roch. On the submodularity of influence in social net- works. In Proceedings of the thirty-ninth annual ACM symposium on Theory of computing, pages 128-134, 2007.
- [Onnela et al., 2007] J-P Onnela, Jari Saramäki, Jorkki Hyvönen, György Szabó, David Lazer, Kimmo Kaski, János Kertész, and A-L Barabási. Structure and tie strengths in mobile communication networks. Proceed- ings of the national academy of sciences, 104(18):7332- 7336, 2007.
- [Qian et al., 2018] Feng Qian, Chengyue Gong, Karishma Sharma, and Yan Liu. Neural user response generator: Fake news detection with collective user intelligence. In Proceedings of the twenty-seventh international confer- ence on international joint conferences on artificial intel- ligence (IJCAI), volume 18, pages 3834-3840, 2018. IJCAI
- [Staudt et al., 2016] Christian L Staudt, Aleksejs Sazonovs, and Henning Meyerhenke. Networkit: A tool suite for large-scale complex network analysis. Network Science, 4(4):508-530, 2016.
- [Tripathy et al., 2010] Rudra M Tripathy, Amitabha Bagchi, and Sameep Mehta. A study of rumor control strategies on social networks. In Proceedings of the 19th ACM interna- tional conference on Information and knowledge manage- ment, pages 1817-1820, 2010.
- [Vosoughi et al., 2018] Soroush Vosoughi, Deb Roy, and Sinan Aral. The spread of true and false news online. sci- ence, 359(6380):1146-1151, 2018.
- [Wang et al., 2015] Zhefeng Wang, Enhong Chen, Qi Liu, Yu Yang, Yong Ge, and Biao Chang. Maximizing the cov- erage of information propagation in social networks. In Twenty-Fourth International Joint Conference on Artificial Intelligence (IJCAI), 2015. IJCAI
- [Yan et al., 2019] Ruidong Yan, Yi Li, Weili Wu, Deying Li, and Yongcai Wang. Rumor blocking through online link deletion on social networks. ACM Transactions on Knowl- edge Discovery from Data (TKDD), 13(2):1-26, 2019.
- [Yu et al., 2008] Yintao Yu, Tanya Y Berger-Wolf, Jared Saia, et al. Finding spread blockers in dynamic networks. In International Workshop on Social Network Mining and Analysis, pages 55-76. Springer, 2008.
- [Zhao et al., 2012] Laijun Zhao, Jiajia Wang, Yucheng Chen, Qin Wang, Jingjing Cheng, and Hongxin Cui. Sihr rumor spreading model in social networks. Physica A: Statistical Mechanics and its Applications, 391(7):2444-2453, 2012.
- [Zhao et al., 2013] Laijun Zhao, Wanlin Xie, H Oliver Gao, Xiaoyan Qiu, Xiaoli Wang, and Shuhai Zhang. A rumor spreading model with variable forgetting rate. Physica A: Statistical Mechanics and its Applications, 392(23):6146- 6154, 2013.
- [Zheng et al., 2022] Jiaqi Zheng, Xi Zhang, Sanchuan Guo, Quan Wang, Wenyu Zang, and Yongdong Zhang. Rumor detection on social media with graph structured adversarial learning. In Proceedings of the thirty-first international conference on international joint conferences on artificial intelligence (IJCAI), 2022. IJCAI
References were extracted automatically from the PDF and may contain errors.
Full text extracted automatically from the PDF; figures, tables and equations may differ. The PDF is the version of record.
1 Introduction
With the rapid development of the Internet, social media has become a convenient online platform for users to obtain information, express and exchange opinions and stay in touch with friends. However, online social networks also pave the road for the propagation of misinformation, particularly rumors (commonly defined as unverified information or deliberately falsified news). It is usually difficult for the public to recognize the falsehood of a rumor, especially if it is designed skillfully, cf. [Vosoughi et al., 2018]. The spread of rumors can mislead people to behave in irrational ways, which can cause a series of undesirable consequences, such as public panic, virtual assets losses, manipulation of the outcome of political events, and economic damages. Consequently, there has been a growing demand and interest to gain insights into the rumor spreading dynamics and design powerful countermeasures to reduce the threats posed by rumors.
∗All the eliminated proofs are given in the full version: https://arxiv.org/abs/2305.08558
To shed some light on the fundamental characteristics and essential principles of rumor propagation phenomenon, scholars from a vast spectrum of backgrounds have introduced and studied various rumor spreading models, such as SIR model [Zhao et al., 2012], Push-Pull protocol [Giakkoupis, 2011], DK model [Daley and Kendall, 1965] and the Independent Cascade (IC) model [Kempe et al., 2003]. In most of these models, the interactions and influence between the individuals are modelled using a graph structure, which represents a social network (SN). The state of the individuals (e.g., informed/uninformed) is updated following a rumor spreading rule. The updating rules are tailored to capture various properties observed in real-world scenarios, usually conceptualized by social scientists.
One aspect of the rumor spreading dynamics which has attracted a substantial amount of attention is the design of effective countermeasures to stop or slow down the spread of rumors, e.g., blocking users, blocking connections, and spreading an "anti-rumor", cf. [He et al., 2015].
In the present paper, we introduce a rumor spreading model which inherits characteristics of the IC, Push-Pull, and SIR model and additionally captures the well-established sociological concepts of the impact of trust and forgetting mechanism. In an attempt at fighting rumor spreading, we study six countermeasures. We establish four essential criteria that a good countermeasure should possess and evaluate the proposed countermeasures on those. We observe that the decentralized countermeasures perform generally better.
1.1 Preliminaries
Let G = (V,E) be a simple connected undirected graph, where n := |V | and m := |E|. For a node v ∈ V , N (v) := {v′ ∈ V : {v′ , v} ∈ E} is the neighborhood of v. Furthermore, ˆN(v) := N(v)∪{v} is the closed neighborhood of v. Let d (v) := |N (v) | be the degree of v in G. We also define dA(v) := |N(v) ∩ A| for a set A ⊆ V . Furthermore, let ∂(A) := {v ∈ V \ A : {v′ , v} ∈ E, v′ ∈ A} be the node boundary of A ⊂ V .
We define a coloring to be a function C : V → {r, u, o}, where r, u, and o represent red, uncolored, and orange respectively. For a node v ∈ V , the set N C a (v) := {v′ ∈ N (v) : C (v′ ) = a} includes the neighbors of v which have color a ∈ {r, u, o} in coloring C.
Rumor Spreading Model. Consider an initial coloring C0 of a graph G. In each round, all nodes simultaneously update their color according to the following updating rule:
where Ct (v) is the color of node v in the t-th round, integer k is a model parameter, Jt(v) is the number of rounds v has been red until round t, S(v, v′ ) := | ˆN(v) ∩ ˆN(v′ )|/|N(v) ∪ N(v′ )| for v, v′ ∈ V , and p∗ (v) := ∏v′∈N Ct-1 r (v) (1 - S(v,v′ ) 2Jt (v′ ) ). A red node corresponds to an individual who is informed of the rumor. An informed node stops spreading the rumor after k rounds and turns orange (uninterested), which it remains forever. An uncolored node corresponds to an uninformed individual. If an uninformed (uncolored) node v is adjacent to an informed (red) node v′ , then v′ turns v into red w.p. S(v, v′ )/2Jt(v′ ) independently. Thus, v becomes red in the next round w.p. 1-p∗ and remains uncolored w.p. p∗ . The coefficient 1/2J(v′ ) corresponds to the probability that v′ spreads the rumor and S(v, v′ ) is the probability that v accepts it. The value of 1/2J(v′ ) accounts for the fact that v′ might not necessarily spread the rumor w.p. 1 and the probability decreases exponentially in the number of rounds v′ has been informed of the rumor, reflecting the fact that an individual loses interest in a rumor over time, cf. [Zhao et al., 2013]. The coefficient S(v, v′ ) (the Jaccard index) which measures the similarity between two nodes reflects the fact that people are more likely to accept information from their trusted connections [Figeac and Favre, 2021]. In the numerator, we use ˆN(v). This is to ensure that for two adjacent nodes v, u, S(v, u) (the accepting probability) is not zero. We could analogously define S(v, u) = (|N(v) ∩ N(u)| + 2)/|N(v) ∪ N(u)| since we are always concerned about adjacent nodes. We note that we can also view S(v, v′ ) as the weight of the edge {v, v′ }.
Our model is different from the IC model in two ways: In the IC model (i) k is always set to 1 (i.e., a red node becomes orange after one round) (ii) the weights are usually assigned randomly.
Starting from any initial coloring, the process eventually reaches a fixed coloring where all nodes are orange or uncolored. If the process reaches a coloring with a constant fraction of orange nodes, say 10%, then we say that the rumor spreads, and it does not otherwise. (There is nothing unique about 10% and our results hold for similar fixed values.)
Graphs. Let Gn,p denote the Erd˝os-R´enyi (ER) random graph, which is the random graph on n nodes, where each edge is present independently w.p. p. For integers n and r, we define the (n,r)-flower graph in the following way. Consider a cycle CN = v1, · · · , vN for N = n/r. For each node vi, add a distinct clique of size r - 1 to the graph and add an edge between vi and every node in the clique. We refer to each node vi and its clique as a super node and vi is called the boundary node of the super node. We are particularly interested in the case of r = log2 (n), which is simply called the n-flower graph. (Note that (n, 1)-flower graph is simply a cycle graph with n nodes.)
To measure the expansion of a graph, we consider an algebraic characterization of expansion. Let λ(G) be the second-largest absolute eigenvalue of the adjacency matrix of G. Small values of λ(G) imply that G has strong expansion properties (i.e., is well-connected). For integers n, d, we define the (n, d)-moderate expander graph in the following way, where we always assume that n is "significantly" larger than d. Let H be a N-node, D-regular graph such that λ(H) ≤ C√D, where N = n log2 (n) and D = d · log2 (n) and C is a positive constant. Replace every node x in H with a clique of size log2 n and then evenly distribute the D edges of x among these log2 n nodes. The obtained n-node (log2 n+d-1)-regular graph is an (n,d)-moderate expander, which is denoted byMn,d. Similar to the (n, r)-flower graph, the set of log2 n nodes in each of the N cliques is called a super node. (Note that moderate expanders are not meant to mimic real-world SNs. They are solely designed to maximize the spread of rumors and are objects of theoretical interest.)
Experimental Setup. For our experiments, we rely on publicly available graph data from [Leskovec and Krevl, 2014]. Our experiments were conducted on the following SNs: Twitter (81306 nodes and 1342310 edges), Facebook (4039 nodes and 88234 edges), Google+ (107614 nodes and 13673453 edges), Twitch Germany (9498 nodes and 153138 edges), and Twitch France (6549 nodes and 122666 edges). We use shorthand TW, FB, G+, T-GE, T-FR, respectively. We also conducted experiments on ER random graph and Hyperbolic random graph (HRG). The parameters in these graphs were set such that the (expected) number of nodes/edges is comparable to the ones in the aforementioned real-world networks. For HRG, one also needs to provide the exponent of the power-law degree distribution β and the temperature T as the input parameters. We set β = 2.5 and T = 0.6. We used the algorithm of [Staudt et al., 2016] for the generation of HRG random graphs. Furthermore, the experiments which required random choice of edges or colors were executed 100 times. and then the average output was considered. The code for the experiments is available at https://github.com/charlotteout/RumourSpreading.
Assumptions. All logarithms are to base e, unless pointed out otherwise. We let n tend to infinity and say an event E happens with high probability (w.h.p.) if it occurs w.p. 1 o(1). We always assume that initially one randomly chosen node is red, and all other nodes are uncolored, otherwise, it is stated explicitly. Furthermore, we suppose the parameter k is a small integer, say k = 5, but our results would hold for any constant value of k.
1.2 Our Contribution
We study a rumor spreading model which captures fundamental characteristics such as the randomized spreading mechanism and various agent types as introduced in the IC, PushPull and SIR model, as well as sociological concepts such as the impact of homophily on trust [Granovetter, 1973], formulated by the Jaccard index, and the forgetting mechanism [Zhao et al., 2013].
Firstly, we address the question: What are the graph structures for which the rumor spreads (in other words, what graph parameters govern the spread of rumors)? It has previously been argued that that information disseminates quickly when the graph has strong expansion properties (i.e., is wellconnected), cf. [Giakkoupis and Sauerwald, 2012]. However, for our model expansion is not solely sufficient for a rumor to spread, especially if the graph is sparse which is usually the case in the real-world SNs. In particular, we prove that in our model on the ER random graph Gn,p (which enjoys strong expansion properties, cf. [Le et al., 2017]) for p sufficiently smaller than 1/√n, the rumor does not spread with a constant probability.
Additionally, we show that an abundance of very wellconnected local communities (which result in large values of S(v, v′ ) for adjacent nodes v, v′ ) alone also cannot guarantee extensive spread of rumors. In particular, we prove that on an (n, r)-flower graph, where S(v, v′ ) = 1 for almost every two adjacent nodes v, v′ , the rumor does not spread w.h.p. for r ≤ n1-ϵ and ϵ > 0 (even when we start with o(logn) red nodes).
However, we show that the combination of these two properties guarantees an extremely fast spread of rumors. More precisely, we prove for even very sparse moderate expander graphs, the rumor spreads in logarithmically many rounds. Roughly speaking, the strong local communities help the rumor to spread quickly inside a community once it reaches a node in that community and expansion ensures that it breaks out into other communities invasively. (We emphasize that the average degree of moderate expanders in this set-up is in the order of log2 n, which is much smaller than the average degree of √n required in ER graphs for spreading.)
A natural question to ask is whether the rumor spreads on real-world SNs in our model. Our experiments on real-world graph data such as Twitter and Facebook demonstrate that the rumor indeed spreads to a very large body of the network in a short period of time. While the social graphs which emerge in the real world do not have the expansion and community structure tailored for the moderate expanders, they still enjoy a certain level of expansion, and well-connected communities are present in abundance. Note that this is an indication that our model is more realistic than previous models such as Push-Pull models, which advocate strong expansion properties as necessary and sufficient condition for fast spread of rumors, as we know that in real life rumors spread very fast in real-world SNs, and they are not strong expanders.
Moreover, we formulate and investigate several countermeasures. Some of them (e.g., blocking nodes and edges) need to be implemented by a third entity such as the government, and we refer to them as centralized countermeasures. On the other hand, the decentralized ones are executed by the members of the network. It turns out that the proposed decentralized countermeasures not only enjoy several desirable criteria such as not interfering with freedom of expression and not being too intrusive, but also significantly outperform the centralized ones in stopping the spread of the rumor according to our experiments. The prior work has focused on the development of centralized countermeasures, see Section 1.3 (which are also implemented in practice up to some degree, e.g., by blocking accounts). Our work aspires to send out the message that the focus should be shifted towards the development of decentralized countermeasures, which can be achieved for instance through educating the members rather than forceful actions of a third entity.
1.3 PriorWork
A plethora of rumor spreading models have been developed and studied in recent years. Here, we focus on the most fundamental and relevant models, which have inspired our work.
Push-Pull Models. In this set-up, each node is either red or uncolored. In each round, every red node makes a randomly chosen neighbor red (Push model), or every uncolored node adopts the color of a randomly chosen neighbor (Pull model), or both (Push-Pull model). Since there is no forgetting mechanism in place, all nodes eventually become red (i.e., the rumor spreads). Thus, a natural question is how long this takes. For the Push model, the spreading time is known [Feige et al., 1990] to be O(∆ · (Λ + log(n)), where ∆ and Λ are the maximum degree and diameter of the underlying graph. For the Push-Pull model, after a long line of research, the bound O (Φ-1 log(n)), for Φ being the conductance of the graph, was proven [Giakkoupis and Sauerwald, 2012].
Independent Cascade (IC)Model. In the ICmodel [Goldenberg et al., 2001], in each round every red node v makes an uncolored node u in its neighborhood red w.p. pvu. A red node becomes orange after one round, which is similar to setting k = 1 in our model. However, in the IC model, the probabilities pvu are chosen uniformly at random. Motivated by viral marketing, the main focus in this model is developing algorithms for finding subsets of nodes that maximize the spread of the red color, mostly exploiting monotonicity and submodularity properties (cf. [Mossel and Roch, 2007; Chen et al., 2011]).
Weighted Connections. Recall that in the IC model (and other similar models) weights are assigned to the edges randomly. As this is not entirely realistic, it would be relevant to introduce meaningful weight assignment mechanisms. Using the communication information of individuals on various real-world networks, [Onnela et al., 2007] and [Goyal et al., 2010] observed that there is a strong correlation between the number of shared friends of two individuals and their level of communication. Consequently, they proposed the usage of similarity measures, such as Jaccard-like parameters, to approximate the weights of connections between nodes. This is also aligned with the well-studied strength of weak ties hypothesis [Granovetter, 1973]. This line of research has inspired the choice of Jaccard index in our model.
Countermeasures. A large part of the research efforts for developing countermeasures is concentrated around blocking nodes and edges. However, since in most models finding the most "influential" nodes/edges is NP-hard, cf. [Kempe et al., 2003], the focus has been on approximate blocking strategies, which use structural properties. For nodes, various algorithms such as blocking nodes with the highest degree, betweenness, and closeness have been investigated, cf. [He et al., 2015; Wang et al., 2015; Yu et al., 2008]. Furthermore, for different greedy-based edge blocking strategies to minimize the spread in the IC model, see [Kimura et al., 2008; Yan et al., 2019]. Other studied countermeasures are spreading the truth as an anti-rumor, cf. [Tripathy et al., 2010; Ding et al., 2020], inoculation strategies (which rest on the idea that if people are forewarned that they might be misinformed, they become more immune), cf. [Lewandowsky and Van Der Linden, 2021], and accuracy flags, cf. [Gausen et al., 2021]. For more results on countermeasures also see [Coro et al., 2020; Bredereck et al., 2021; Zheng et al., 2022; Qian et al., 2018; Ma et al., 2016].
2 When Does a Rumor Spread?
2.1 Erd˝os-R´enyi RandomGraph
Theorem 1. Consider the coloring where only one node is red (the rest is uncolored) on Gn,p with p ≤ 1 n 12 +ϵ for any constant ϵ > 0. The rumor does not spread with a constant probability.
Proof. Define s := ⌈1/ϵ⌉ + 1. For a pair of distinct nodes v and u, the probability that the inequality |N(v) ∩N(u)| ≥ s holds is upper-bounded by (n-2 s ) p2s . Let X be the number of pairs which satisfy the above inequality. Then, we have E[X] ≤ (n2 ) (n-2 s )p2s ≤ ns+2 p2s ≤ ns+2 ns+2sϵ = o(1), where we used that p ≤ 1/n 1 2 +ϵ and sϵ > 1, respectively. Hence, by Markov's inequality (cf. [Dubhashi and Panconesi, 2009]), Pr[A] = Pr[X ≥ 1] ≤ o(1), where A is the event that X ≥ 1 (and ¯ A is the complement of A).
Let v be the only node which is colored red in C0. For each node u ∈ N(v), we have Pr[C1(u) = r|d(v) = d ∧ ¯ A] = | ˆN(v)∩ ˆN(u)| 2|N(v)∪N(u)| ≤ min ( s+2 2d , 12 ). For (s + 2)/(2d), we used that | ˆN(v) ∩ ˆN(u)| ≤ |N(v) ∩ N(u)| + 2 ≤ s + 2 and |N(v) ∪ N(u)| ≥ d(v) = d. The upper bound of 1/2 holds because | ˆN(v) ∩ ˆN(u)| ≤ |N(v) ∪N(u)|.
Let Ei, for 1 ≤ i ≤ k, denote the event that v does not make any of its neighbors red in the i-th round. Then, Pr[E1|d(v) = d ∧ ¯ A] ≥ (1 - min ( s+2 2d , 12 ))d . If s+2 2d < 1/2 then (1 - s+2 2d )d ≥ ( 14 )(s+2)/2 (which gives a constant lower bound) using the estimate (1 - x) ≥ ( 1 4 )x for x < 1/2. If s+2 2d ≥ 1/2, then d ≤ s + 2, which implies that (1/2)d is a constant. Therefore, in both cases, we can lower bound (1 - min ( s+2 2d , 12 ))d with some constant C > 0.
With a similar argument, we can prove that Pr[Ei|Ei-1 ∧· · ·∧ E1] ≥ C/2 for 2 ≤ i ≤ k. Thus, we have Pr[E1 ∧ · · · ∧ Ek] = Pr[Ek|Ek-1 ∧ · · · ∧ E1] · · · Pr[E2|E1] · Pr[E1] ≥ (C/2)k . This implies that w.p. at least (C/2)k = (C/2)5 , no node becomes red during the first k rounds. In that case, the process ends with one orange node and n-1 uncolored nodes in k rounds. This bound on p turns out to be tight (a full proof is given in the extended version).
2.2 Flower Graph
A super node whose all nodes are uncolored is called uncolored and colored otherwise. And it is said to be red if all its nodes are red.
Theorem 2. Consider an (n,r)-flower graph for r ≤ n1-ϵ and constant ϵ > 0. If initially there are s(n) = o(log n) red super nodes (and the rest is uncolored), the rumor does not spread w.h.p.
Proof Sketch. A path of super nodes is a sequence of super nodes which form a path in the cycle obtained from collapsing each super node into a node. A path is uncolored if all its super nodes are uncolored. In a reddish path, there are no two adjacent uncolored super nodes and the endpoints are colored. We note that for any coloring of the (n,r)-flower graph, there is a set of maximal uncolored and reddish paths which partition the nodes in the graph.
Define a phase to be a sequence of k rounds. Let C be the coloring at the beginning of phase i. Consider all the endpoints of the uncolored paths in the aforementioned partitioning and define U to be their boundary nodes. Let Ei be the event that no node in U becomes red during the whole phase.
We observe that if the event Ei occurs, then all boundary nodes of the reddish paths endpoints become orange. Thus, all nodes which are not on any reddish path remain uncolored forever. Let us define t∗ := (1/C)2s(n) log(n), for a suitably chosen constant 0 < C < 1, then with some relatively straightforward calculations, we can show that Pr[∧t∗ i=1 ¯ Ei] ≤ 1n . Thus, w.h.p. after at most t∗ phases (i.e., kt∗ rounds), we reach a coloring where all nodes which are not on any reddish path remain uncolored forever. Furthermore, we claim that the number of nodes on the reddish paths during the first kt∗ rounds is sub-linear. Hence, the rumor does not spread w.h.p. (A full proof is given in the extended version.)
2.3 Moderate Expander
Theorem 3. Consider an (n, d)-moderate expander Mn,d with d = ω(1). If initially there is a red node (and the rest are uncolored), then the rumor spreads w.h.p. in O(logd n) rounds.
Similar to a flower graph, we call a super node x uncolored if all its nodes are uncolored. We say x is strong red if every node in it has become red at most three rounds before. A super node is weak red if it is neither strong red nor uncolored. Let ut, st and wt denote the number of uncolored, strong red, and weak red super nodes in the t-th round.
Recall that if we contract all N = n/ log2 (n) super nodes in Mn,d, we obtain a D-regular graph for D = d log2 (n). In Lemma 1 (whose proof is given in the extended version), we state that if a node in one of these super nodes is red, then the super node becomes red in 2 rounds. Then, in Lemma 3, we show that the number of strong red super nodes increases by roughly a d factor after every three rounds. Repeated application of Lemma 3 implies that the rumor spreads in O(logd n) rounds. (A more detailed discussion is given in the extended version, where we also argue that the bound d = ω(1) is necessary, i.e., the statement does not hold for constant d).
Lemma 1. Consider a graph G = (V,E) where nodes in K ⊆ V form a clique, κ := |K| ≥ log2 n, and for every v ∈ K d(v) ≤ 2κ. If Ct(v) = r for some v ∈ K and all other nodes in K are uncolored, then there is no uncolored node in K in round t + 2 w.p. 1 - o(1/n).
To prove Lemma 3, we need Lemma 2 and Observation 1. The proof of Lemma 2 is given in the extended version, which relies on the expander mixing lemma, cf. [Friedman, 2003].
Lemma 2. Consider an N-node D-regular graph G, where λ ≤ C√D, for some constant C > 0, and D = ω(1). If a node set A is of size at most N 10 , then there is some constant C ′ > 0 such that |∂(A)| ≥ min (2N/5, |A|C ′D).
Observation 1. Let x and y be two distinct super nodes in a moderate expander graph. Then, there is at most one edge between x and y, by construction.
Lemma 3. Consider an (n, d)-moderate expander Mn,d with d = ω(1). If 1 ≤ st < C1N/D, for a sufficiently small constant C1 > 0, and wt = O(st/d), then after three rounds there are Ω(std) new strong red super nodes w.p. 1 - exp(Ω(-dst)) - o(1/ log n).
Proof. Let E ∗ be the event that every uncolored super node becomes strong red in two rounds once it has at least one red node. Based on Lemma 1, E ∗ holds w.p. at least 1 - N · o(1/n) ≥ 1 - o(1/ log n) since there are N super nodes.
Furthermore, let q∗ denote the probability that a node v, in a strong red super node, makes a node u, in an uncolored super node, red where there is an edge between v and u. Since | ˆN(v) ∩ ˆN(u)| ≥ 2, |N(v) ∪ N(u)| ≤ 2(d + log2 n) ≤ 2.5 log2 n (using the assumption that d is significantly smaller than n), and v has been red for at most three rounds, we get the following upper-bound:
Let S, W, and U be the set of strong red, weak red, and uncolored super nodes in round t. Let us label the nodes in
∂(S) ∩ U from u1 to ub, where b is the size of ∂(S) ∩ U. For each node ui consider one of its neighbors in S. Let Bernoulli random variable yi be 1 if and only if ui is made red by that neighbor in S in the next round (i.e., t + 1). For the random variable Y := ∑bi=1 yi, we have E[Y ] ≥ bq∗ ≥ b/(10 log2 n), where we used Pr[yi = 1] = q∗ and Equation (1). Since yi's are independent, applying Chernoff bound (cf. [Dubhashi and Panconesi, 2009]) yields
Note that wt = O(st/d) = o(st) implies that st + wt ≤ 1.1st. Furthermore, 1.1st ≤ N/10 since st ≤ C1N/D = o(N). Thus, we can apply Lemma 2 for A = S ∪ W and the graph obtained from contracting each super node to a node. Since |A| = st + wt ≤ 1.1st ≤ 1.1C1N/D, we get 2N/5 ≥ |A|C ′D by selecting C1 to be sufficiently small. Thus, |∂(A)| ≥ stC ′D. Furthermore, note that |∂(A)| = |∂(S) ∩ U| + |∂(W) ∩ U| = b + |∂(W) ∩ U| and |∂(W) ∩ U| ≤ wtD. Combining the last two statements gives b ≥ stC ′D - wtD. Using wt = O(st/d) = o(st) implies that b = Ω(Dst). Thus, Equation (2) implies that w.p. 1 - exp(-Ω(Dst/ log2 n)) = 1 - exp(-Ω(dst)), there will be Ω(Dst/ log2 n) = Ω(dst) nodes in U which become red in the next round. Note that all such nodes are in different super nodes (see Observation 1). If event E ∗ holds, then all such super nodes will be strong red in two more rounds. Since E ∗ holds w.p. 1 - o(1/ logn) (as discussed above), there will be Ω(dst) new strong red super nodes after three rounds w.p. 1 - exp(Ω(-dst)) - o(1/ log n).
2.4 Experiments and Real-world Networks
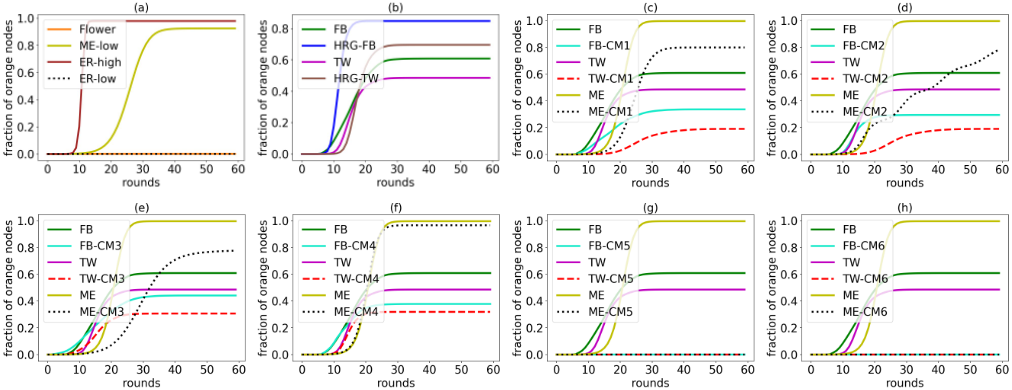
The outcome of our experiments in Figure 1-(a) are consistent with our theoretical findings. In particular, the rumor does not spread in the flower graph and ER-low (i.e., p = 1/(4√n)) while it does for the moderate expander and ER-high (i.e., p = 4/√n). Note that in this set-up, a node in the moderate expander is of degree d + log2 n - 1 ≈ 100 (actually, we observe in the experiments that for D = 64 rather than D = d · 100 = 4 · 100 the rumor already spreads), which indicates the rumor spreads even in very sparse graphs if they possess some level of expansion and community structure. Furthermore, we observe that the process on the moderate expander ends in around 50 rounds, which indeed appears to be logarithmic rather than linear in n = 16000 (this is aligned with the bound O(logd n) proven in Theorem 3).
Figure 1-(b) depicts the extent to which the rumor spreads in Twitter and Facebook graph and random graph model HRG with comparable parameters. (Please refer to Section 1.1 for more details.) The plots for the other three studied SNs are given in the extended version. We observe that the rumor spreads to a large part of the graph very quickly. This can be explained by the fact that all these graphs have a decent level of expansion and community-like structure, which are the necessary properties for a fast and wide spread according to our theoretical results. As a by-product, our experiments also support that HRG is a suitable choice for modeling realworld SNs.
3 How to Stop the Rumor Spreading?
We present six countermeasures (the first four are inspired by prior work as explained in Section 1.3, but the last two are completely novel) and then compare them. The outcome of our experiments on the countermeasures for Twitter and Facebook graphs and moderate expander are given in Figure 1 and for the other three SNs (T-GE, T-FR, and G+) in the extended version.
CM1: BlockingNodes. We assume that the 5%highest degree nodes and 20% randomly chosen nodes are blocked (i.e., do not receive/spread the rumor). As Figure 1-(c) demonstrates, this countermeasure is not very effective. We believe blocking nodes according to the highest betweenness, closeness, or eigencentrality (instead of highest degree) would not improve the countermeasure significantly since in real-world SNs there is a large overlap between the highest degree nodes and nodes chosen by the mentioned parameters due to certain properties such as the power-law degree distribution.
CM2: Blocking Edges. The graph is partitioned into communities using the Louvain algorithm [Blondel et al., 2008]. In each round of the process, if the fraction of red nodes is above a global threshold τg, then we block all the edges which are on the boundary of the "spreader" communities. A community is a spreader if its fraction of red nodes is larger than a local threshold τc. The blocked edges remain blocked until the community is not a spreader anymore. (Both threshold are set to 0.05 in our set-up.) Figure 1-(d) demonstrates while this countermeasure slows down the spread, the rumor still spreads to a large part of the graph. It is worth to mention that around 20 - 30% of edges were blocked during the process in our experiments. (Unlike other experiments, this was executed only 10 times due to its high computational cost.)
CM3: Accuracy Flags. Assume that every time a node is supposed to become red, it rejects the rumor with some reject probability pr, and becomes orange directly. In practice, this countermeasure corresponds to for example accuracy flags in online social platforms, in which posts containing certain keywords (say hot controversial or polarizing topics) are automatically accompanied by a banner warning the user about the trustworthiness of the content. The outcome of our experiments for pr = 0.3, depicted in Figure 1-(e), demonstrates that the rumor still continues to spread to a significant portion of the community.
CM4: Let's Spread the Truth. Let the truth spreading process be the same as the rumor spreading with the following two differences: (i) green and light green are used instead of red and orange, respectively (ii) the probability a node becomes green is one half of the probability of becoming red in the rumor spreading process (this is to account for the observation that rumors spread faster than facts, cf. [Vosoughi et al., 2018]). After τ rounds into the rumor spreading process, we color an uncolored node green and the truth starts spreading simultaneously. (We assume that the rumor and truth spread only to uncolored nodes, that is, a red/orange node does not become green and vice versa.) The outcome of experiments, depicted in Figure 1-(f), indicates that this countermeasure cannot stop the rumor effectively even when
τ = 4 (which implies that there is a strong rumor detection algorithm in place) and the node which starts the truth is the node with the highest degree among the uncolored nodes. We depict the influence of the delay τ on the final fraction of orange nodes in a figure in the extended version.
CM5: Fact Checkers. Consider a set of fact checker nodes, who starts spreading the truth (i.e., anti-rumor) once exposed to the rumor, as the truth spreading process in CM4. These correspond to "good citizens" (e.g., credible news outlets or scientists on the topic) who are educated or incentivized to verify the received information and spread the truth if necessary. (In our experiments, we assume they include 10% of the network and are distributed randomly.) This has some similarities to CM4, but instead of starting the spread of the truth by implementing a green node in the graph (which needs to be executed by a third entity), the fact checkers become green and trigger the spread of the truth once contacted by a rumor spreader. Furthermore, the fact checker spread the truth more aggressively: (i) the forgetting parameter k is much larger for the fact checker nodes (say 20 rather than 5) (ii) fact checkers can make their red neighbors green as well (iii) the fact checkers are three times more active in spreading (you can think of each round as three sub-rounds, where all nodes (red/green) spread in the first sub-round while the green fact checker nodes continue to spread in the second and third subround too). Note that green nodes which are not fact checker behave as in the original truth spreading process. Our experiments (see Figure 1-(g)) demonstrate that this countermeasure is very effective.
CM6: Let's Hear It Twice. We require a node to hear a rumor from at least two of its neighbors before accepting and spreading it (i.e., becoming red), instead of once as in the original process. Figure 1-(h) demonstrates that this countermeasure is immensely effective, where in our experiments, initially two randomly chosen nodes are red. We formalize this observation in Theorem 4, whose proof is given in the extended version.
Theorem 4. Consider the (n,d)-moderate expander Mn,d with d ≤ n 12 -ϵ for a constant ϵ > 0. If initially two super nodes x and y, chosen uniformly at random, have red node(s) (and the rest is uncolored) and CM6 is in place, then w.h.p. the rumor does not spread.
Comparison of Countermeasures. We consider four fundamental criteria that a good countermeasure should possess. To the best of our knowledge, this is the first attempt to formalize such a list of criteria.
C1: Effective. A good countermeasure substantially reduces the extent that a rumor spreads.
C2: Easy To Apply. An acceptable countermeasure should be feasible and easily executable. If implemented by the agents of the network, it should not require full knowledge of the whole network or the complete history of the process. If it is administrated by a third entity, such as the government, it should not postulate a perfect rumor detection strategy or running algorithms which are computationally very costly.
C3: Not Against Freedom of Expression. A countermeasure ideally should not take away the freedom of expression and liberties of the agents.
C4: Not Too Intrusive. A countermeasure which demands fundamental changes in the mechanism of information spreading or the network structure is not desirable.
| C1 | C2 | C3 | C4 | Decentralized | |
|---|---|---|---|---|---|
| CM1 | no | jein | no | no | no |
| CM2 | no | jein | no | no | no |
| CM3 | no | jein | yes | yes | no |
| CM4 | no | jein | yes | yes | jein |
| CM5 | yes | jein | yes | yes | yes |
| CM6 | yes | yes | yes | yes | yes |
Table 1 indicates which criteria each of the proposed countermeasure satisfies. Note that it is inherently difficult to measure the above criteria in a strict quantitative manner. Thus, the entries in the table are relative and up to interpretation. The choices for C1 are according to the results depicted in Figure 1. The entries for C2 are mostly set to jein since while they are not extremely difficult to implement, they need a smart rumor detection strategy or the full knowledge of the network. Furthermore, CM1 and CM2 violate C3 since they clearly intrude the freedom of expression and do not satisfy C4 since they change the network structure radically. The other countermeasures, arguably, satisfy the last two criteria. A more comprehensive discussion on the entries of Table 1 is provided in the extended version of the paper.
We say a countermeasure is decentralized if it is executed by the members of the network rather than being enforced by a third party such as the government or an online social platform management team. Summarizing the entries of Table 1 implies that, interestingly, the decentralized countermeasures, namely CM5 and CM6 (and CM4, up to some degree), satisfy most of the desired criteria while the centralized ones do not. Hence, instead of developing centralized countermeasures which need to be imposed by a forceful third entity, the focus should be devoted to the design and implementation of decentralized countermeasures which can be obtained through educating the members of the network. In short, educating is preferred over regulating.
4 Conclusion
We introduced a rich rumor spreading model and building on our theoretical and experimental findings, we argued that the abundance of community structures and good expansion properties are two of the main driving forces behind the spread of rumors. A potential avenue for future research is to determine other graph parameters which govern the spread of rumors. We also investigated several countermeasures. We observed that the decentralized countermeasures (which do not require a direct and forceful interference of a third entity but rather the education of the network's members) outperform the centralized ones vigorously. Therefore, a natural suggestion for the future studies is the shift of focus from centralized countermeasures to decentralized ones, which have been scarcely investigated by the prior work.
@inproceedings{ijcai2023p27,
  title     = {Why Rumors Spread Fast in Social Networks, and How to Stop It},
  author    = {N. Zehmakan, Ahad and Out, Charlotte and Hesamipour Khelejan, Sajjad},
  booktitle = {Proceedings of the Thirty-Second International Joint Conference on
               Artificial Intelligence, {IJCAI-23}},
  publisher = {International Joint Conferences on Artificial Intelligence Organization},
  editor    = {Edith Elkind},
  pages     = {234--242},
  year      = {2023},
  month     = {8},
  note      = {Main Track},
  doi       = {10.24963/ijcai.2023/27},
  url       = {https://doi.org/10.24963/ijcai.2023/27},
}
TY - CPAPER TI - Why Rumors Spread Fast in Social Networks, and How to Stop It AU - N. Zehmakan, Ahad AU - Out, Charlotte AU - Hesamipour Khelejan, Sajjad T2 - Proceedings of the Thirty-Second International Joint Conference on Artificial Intelligence, IJCAI-23 PB - International Joint Conferences on Artificial Intelligence Organization PY - 2023 SP - 234 EP - 242 DO - 10.24963/ijcai.2023/27 UR - https://doi.org/10.24963/ijcai.2023/27 ER -Copied
Machine-readable versions of this paper, for tools and AI agents:





