
Dynamic Flows on Curved Space Generated by Labeled Data
Proceedings of the Thirty-Second International Joint Conference on Artificial Intelligence. Main Track. Pages 3803-3811.
https://doi.org/10.24963/ijcai.2023/423
Keywords
- Machine Learning: ML: Optimization
- Machine Learning: ML: Multi-task and transfer learning
- Machine Learning: ML: Few-shot learning
- Computer Vision: CV: Machine learning for vision
Abstract
The scarcity of labeled data is a long-standing challenge for many machine learning tasks. We propose our gradient flow method to leverage the existing dataset (i.e., source) to generate new samples that are close to the dataset of interest (i.e., target). We lift both datasets to the space of probability distributions on the feature-Gaussian manifold, and then develop a gradient flow method that minimizes the maximum mean discrepancy loss. To perform the gradient flow of distributions on the curved feature-Gaussian space, we unravel the Riemannian structure of the space and compute explicitly the Riemannian gradient of the loss function induced by the optimal transport metric. For practical applications, we also propose a discretized flow, and provide conditional results guaranteeing the global convergence of the flow to the optimum. We illustrate the results of our proposed gradient flow method on several real-world datasets and show our method can improve the accuracy of classification models in transfer learning settings.
- [Alvarez-Melis and Fusi, 2020] David Alvarez-Melis and Ni- colo Fusi. Geometric dataset distances via optimal transport. In Advances in Neural Information Processing Systems, vol- ume 33, pages 21428-21439, 2020.
- [Alvarez-Melis and Fusi, 2021] David Alvarez-Melis and Nicolò Fusi. Dataset dynamics via gradient flows in prob- ability space. In Proceedings of the 38th International Conference on Machine Learning, volume 139, pages 219- 230, 2021.
- [Ambrosio et al., 2008] L. Ambrosio, N. Gigli, and G. Savaré. Gradient Flows in Metric Spaces and in the Space of Prob- ability Measures. Birkhäuser Verlag, 2008.
- [Arbel et al., 2019] Michael Arbel, Anna Korba, Adil Salim, and Arthur Gretton. Maximum mean discrepancy gradi- ent flow. In Advances in Neural Information Processing Systems, volume 32, pages 6481-6491, 2019.
- [Arbel et al., 2020] M Arbel, A Gretton, W Li, and G Mont- ufar. Kernelized Wasserstein natural gradient. In Interna- tional Conference on Learning Representations, 2020.
- [Bellemare et al., 2017] Marc G. Bellemare, Ivo Danihelka, Will Dabney, Shakir Mohamed, Balaji Lakshminarayanan, Stephan Hoyer, and Remi Munos. The Cramer distance as a solution to biased Wasserstein gradients. arXiv preprint arXiv:1705.10743, 2017.
- [Bhatia et al., 2019] R. Bhatia, T. Jain, and Y. Lim. On the Bures-Wasserstein distance between positive definite matri- ces. Expositiones Mathematicae, 37(2):165-191, 2019.
- [Bhatia, 1997] Rajendra Bhatia. Matrix Analysis. Springer, 1997.
- [Bińkowski et al., 2018] Mikołaj Bińkowski, Danica J. Sutherland, Michael Arbel, and Arthur Gretton. Demystify- ing MMD GANs. In International Conference on Learning Representations, 2018. [Chizat and Bach, 2018] Lénaïc Chizat and Francis Bach. On the global convergence of gradient descent for over- parameterized models using optimal transport. In Advances in Neural Information Processing Systems, volume 31, 2018.
- [Clanuwat et al., 2018] Tarin Clanuwat, Mikel Bober-Irizar, Asanobu Kitamoto, Alex Lamb, Kazuaki Yamamoto, and David Ha. Deep learning for classical Japanese literature. arXiv preprint arXiv:1812.01718, 2018.
- [Courty et al., 2017] Nicolas Courty, Rémi Flamary, Amaury Habrard, and Alain Rakotomamonjy. Joint distribution op- timal transportation for domain adaptation. In Advances in Neural Information Processing Systems, volume 30, 2017.
- [Damodaran et al., 2018] Bharath Bhushan Damodaran, Ben- jamin Kellenberger, Rémi Flamary, Devis Tuia, and Nicolas Courty. DeepJDOT: Deep joint distribution optimal trans- port for unsupervised domain adaptation. In Proceedings of the European Conference on Computer Vision (ECCV), pages 447-463, 2018.
- [Fan and Alvarez-Melis, 2022] Jiaojiao Fan and David Alvarez-Melis. Generating synthetic datasets by inter- polating along generalized geodesics. In NeurIPS 2022 Workshop on Synthetic Data for Empowering ML Research, 2022.
- [Frogner and Poggio, 2020] Charlie Frogner and Tomaso Poggio. Approximate inference with Wasserstein gradient flows. In International Conference on Artificial Intelligence and Statistics, pages 2581-2590. PMLR, 2020.
- [Gao et al., 2018] Hang Gao, Zheng Shou, Alireza Zareian, Hanwang Zhang, and Shih-Fu Chang. Low-shot learning via covariance-preserving adversarial augmentation net- works. Advances in Neural Information Processing Sys- tems, 31, 2018.
- [Gelbrich, 1990] M. Gelbrich. On a formula for the L 2 Wasserstein metric between measures on Euclidean and Hilbert spaces. Mathematische Nachrichten, 147(1):185- 203, 1990.
- [Gretton et al., 2012] Arthur Gretton, Karsten M. Borgwardt, Malte J. Rasch, Bernhard Schölkopf, and Alexander Smola. A kernel two-sample test. Journal of Machine Learning Research, 13(25):723-773, 2012.
- [Gulcehre et al., 2016] Caglar Gulcehre, Marcin Moczulski, Misha Denil, and Yoshua Bengio. Noisy activation func- tions. In Proceedings of The 33rd International Conference on Machine Learning, pages 3059-3068, 2016.
- [Gulcehre et al., 2017] Caglar Gulcehre, Marcin Moczulski, Francesco Visin, and Yoshua Bengio. Mollifying networks. In 5th International Conference on Learning Representa- tions, 2017.
- [Hazan et al., 2016] Elad Hazan, Kfir Yehuda Levy, and Shai Shalev-Shwartz. On graduated optimization for stochastic non-convex problems. In Proceedings of The 33rd Interna- tional Conference on Machine Learning, pages 1833-1841, 2016.
- [Jordan et al., 1998] R. Jordan, D. Kinderlehrer, and F. Otto. The variational formulation of the Fokker-Planck equation. SIAM Journal on Mathematical Analysis, 29:1-17, 1998.
- [LeCun and Cortes, 2010] Yann LeCun and Corinna Cortes. MNIST handwritten digit database. 2010.
- [Lee, 2003] John Lee. Introduction to Smooth Manifolds. Springer-Verlag, 2003.
- [Liu and Wang, 2016] Qiang Liu and Dilin Wang. Stein vari- ational gradient descent: A general purpose Bayesian in- ference algorithm. In Advances in Neural Information Processing Systems, volume 29, 2016.
- [Liu, 2017] Qiang Liu. Stein variational gradient descent as gradient flow. In Advances in Neural Information Process- ing Systems, volume 30, 2017.
- [Liutkus et al., 2019] Antoine Liutkus, Umut Simsekli, Szy- mon Majewski, Alain Durmus, and Fabian-Robert Stöter. Sliced-Wasserstein flows: Nonparametric generative mod- eling via optimal transport and diffusions. In Proceedings of the 36th International Conference on Machine Learning, 2019.
- [Malagò et al., 2018] L. Malagò, L. Montrucchio, and G. Pis- tone. Wasserstein Riemannian geometry of Gaussian densi- ties. Information Geometry, 1(2):137-179, 2018.
- [Moreno-Barea et al., 2018] Francisco J. Moreno-Barea, Fi- ammetta Strazzera, José M. Jerez, Daniel Urda, and Leonardo Franco. Forward noise adjustment scheme for data augmentation. In 2018 IEEE Symposium Series on Computational Intelligence (SSCI), pages 728-734, 2018.
- [Mroueh and Nguyen, 2021] Youssef Mroueh and Truyen Nguyen. On the convergence of gradient descent in GANs: MMD GAN as a gradient flow. In International Conference on Artificial Intelligence and Statistics, 2021.
- [Mroueh et al., 2019] Youssef Mroueh, Tom Sercu, and Anant Raj. Sobolev descent. In Proceedings of the Twenty- Second International Conference on Artificial Intelligence and Statistics, pages 2976-2985, 2019.
- [Netzer et al., 2011] Yuval Netzer, Tao Wang, Adam Coates, Alessandro Bissacco, Bo Wu, and Andrew Y. Ng. Reading digits in natural images with unsupervised feature learning. In NIPS Workshop on Deep Learning and Unsupervised Feature Learning 2011, 2011.
- [Otto, 2001] F. Otto. The geometry of dissipative evolution equations: the porous medium equation. Comm. Partial Differential Equations, 26:101-174, 2001.
- [Rezende et al., 2016] Danilo Rezende, Ivo Danihelka, Karol Gregor, Daan Wierstra, et al. One-shot generalization in deep generative models. In International conference on machine learning, pages 1521-1529. PMLR, 2016.
- [Russakovsky et al., 2015] Olga Russakovsky, Jia Deng, Hao Su, Jonathan Krause, Sanjeev Satheesh, Sean Ma, Zhiheng Huang, Andrej Karpathy, Aditya Khosla, Michael Bern- stein, et al. Imagenet large scale visual recognition chal- lenge. International journal of computer vision, 115(3):211- 252, 2015.
- [Santambrogio, 2015] Filippo Santambrogio. Optimal Trans- port for Applied Mathematicians: Calculus of Variations, PDEs and Modeling. Birkhäuser, 2015.
- [Santambrogio, 2017] Filippo Santambrogio. Euclidean, met- ric, and Wasserstein gradient flows: An overview. Bullentin of Mathematical Sciences, 7:87-154, 2017.
- [Shorten and Khoshgoftaar, 2019] Connor Shorten and Taghi M Khoshgoftaar. A survey on image data augmen- tation for deep learning. Journal of big data, 6(1):1-48, 2019.
- [Szabó and Sriperumbudur, 2018] Zoltán Szabó and Bharath K. Sriperumbudur. Characteristic and universal tensor product kernels. Journal of Machine Learning Research, 18(233):1-29, 2018.
- [Takatsu, 2011] Asuka Takatsu. Wasserstein geometry of Gaussian measures. Osaka Journal of Mathematics, 48(4):1005-1026, 2011.
- [van der Maaten and Hinton, 2008] Laurens van der Maaten and Geoffrey Hinton. Visualizing data using t-SNE. Jour- nal of Machine Learning Research, 9:2579-2605, 2008.
- [Villani, 2008] C. Villani. Optimal Transport: Old and New. Springer Science & Business Media, 2008.
- [Wang et al., 2020] Yaqing Wang, Quanming Yao, James T Kwok, and Lionel M Ni. Generalizing from a few examples: A survey on few-shot learning. ACM computing surveys (csur), 53(3):1-34, 2020.
- [Wang et al., 2021] Gefei Wang, Yuling Jiao, Qian Xu, Yang Wang, and Can Yang. Deep generative learning via Schrödinger bridge. In Marina Meila and Tong Zhang, edi- tors, Proceedings of the 38th International Conference on Machine Learning, volume 139 of Proceedings of Machine Learning Research, pages 10794-10804. PMLR, 2021.
- [Wiatrak et al., 2019] Maciej Wiatrak, Stefano V Albrecht, and Andrew Nystrom. Stabilizing generative adversarial networks: A survey. arXiv preprint arXiv:1910.00927, 2019.
- [Xiao et al., 2017] Han Xiao, Kashif Rasul, and Roland Voll- graf. Fashion-mnist: a novel image dataset for bench- marking machine learning algorithms. arXiv preprint arXiv:1708.07747, 2017.
- [Yi et al., 2019] Xin Yi, Ekta Walia, and Paul Babyn. Gen- erative adversarial network in medical imaging: A review. Medical Image Analysis, 58:101552, 2019.
- [Zhang et al., 2017] Hongyi Zhang, Moustapha Cisse, Yann N Dauphin, and David Lopez-Paz. mixup: Be- yond empirical risk minimization. arXiv preprint arXiv:1710.09412, 2017.
References were extracted automatically from the PDF and may contain errors.
Full text extracted automatically from the PDF; figures, tables and equations may differ. The PDF is the version of record.
1 Introduction
A major challenge in many data science applications is the scarcity of labeled data. Data augmentation methods have been studied in the literature; see for example, the noise injection methods [Moreno-Barea et al., 2018], generative models [Yi et al., 2019], and [Shorten and Khoshgoftaar, 2019] for a survey. We consider a setting where one domain has only a few labeled samples for each class, so we cannot train a well-performing classifier with the available data. To alleviate the data scarcity problem in this setting, we propose to enrich the target dataset by generating additional labeled samples. Using generative models is not possible in our setting because they usually require more than a few samples for each class to learn and generate high-quality new samples [Gao et al., 2018]. In our work, we choose a source dataset with extensive labeled data and then flow the labeled data to the target dataset. Precisely, we introduce a novel data augmentation methodology based on a gradient flow approach that minimizes the maximum mean discrepancy (MMD) distance between the target and the augmented data. Therefore, when minimizing the MMD distance, we are able to obtain an efficient scheme which generates additional labeled data from the target distribution. Our scheme is model-independent and can be applied to any datasets regardless of the number of classes or dimensionality 1 .
Mathematically, we consider a feature space X = Rm and a categorical label space Y. We have a source domain dataset consisting of N samples (xi, yi) ∈ X × Y for i = 1, . . . , N, and a target domain dataset of M samples (¯xj , ¯ yj) ∈ X × Y for j = 1, . . . ,M(M ≪N). The ultimate goal of this paper is to generate new samples in the target domain, and we aim to generate new samples whose distribution is as close as possible to the distribution that governs the target domain.
We here introduce a gradient flow method [Arbel et al., 2019; Mroueh et al., 2019] to synthesize new, unseen data samples. Gradient flow is a continuous flow along the path where a considered loss function decreases its value. Because we have extensive source domain samples, it is possible to flow each source sample towards the target data while minimizing the loss function. The terminal product of the flow will be new samples that can sufficiently approximate the distribution of the target domain. Thus, gradient flow is an approach to synthesize new target domain samples, and is a complement to data augmentation methods, like adding random noise.
Unfortunately, formulating a gradient flow algorithm for labeled data with categorical set Y is problematic. Indeed, there is no clear metric structure on Y in order to define the topological neighborhood, this in turn leads to the difficulty of forming the gradients with respect to the categorical component. To overcome this difficulty, we lift each individual label to a richer structure. For example, a label such as "0" is replaced by a mean vector and a covariance matrix based on the whole distribution of the information associated to this particular label. Then it will be much more natural to apply gradient flow algorithms in the space of the lifted representation. A gradient flow on the dataset space with this idea was recently proposed in [Alvarez-Melis and Fusi, 2021] by leveraging a new notion of distance between datasets in [Alvarez-Melis and Fusi, 2020; Courty et al., 2017; Damodaran et al., 2018]. The main idea behind this approach is to reparametrize the categorical space Y using the conditional distribution of the features, which is assumed to be Gaussian, and then construct a gradient flow on the feature-Gaussian space. Nevertheless, the theoretical analysis in [Alvarez-Melis and Fusi, 2021] focuses solely on the gradients with respect to the feature with no treatment of the flowwith respect to the Gaussian component. In fact, the space of Gaussian distributions is not a (flat) vector space, and extracting gradient information depends on the choice of the metric imposed on this Gaussian space. On the other hand, our method computes the full gradient with respect to the Gaussian component (the mean and covariance matrix component that correspond to the label component).
1 Our code and supplementary are available at https://github.com/ LucyXH/Dynamic Flows Curved Space/
Our gradient flows minimize the MMD loss function, thus it belongs to the family of MMD gradient flows that was pioneered in [Mroueh et al., 2019; Arbel et al., 2019], and further extended in [Mroueh and Nguyen, 2021]. The MMD function compares two distributions via their kernel mean embeddings on a flat reproducing kernel Hilbert space (RKHS). In contrast to the Kullback-Leibler divergence flow, the MMD flow can employ a sample approximation for the target distribution [Liu, 2017]. Further, the squared MMD possesses unbiased sample gradients [Bi´nkowski et al., 2018; Bellemare et al., 2017]. While existing literature on MMD flows focus on distributions on flat Euclidean spaces, the flow developed in our paper is for distributions on a curved Riemannian feature-Gaussian space. Moreover, our approach is distinctive from the flow in [Alvarez-Melis and Fusi, 2021] because we impose a specific metric on the Gaussian component, and we compute explicitly the Riemannian gradient of the MMD loss function with respect to this metric to formulate our flow. Table 1 compares our work with two recent papers on gradient flow in theory and numerical experiments.
Recently, generative models [Rezende et al., 2016; Wang et al., 2021] are successful in generating image samples from given distributions. The most important difference with our method is that generative models learn a prior distribution from massive data that are similar to the target data and generate new target samples conditioning on the prior distribution [Wang et al., 2020; Gao et al., 2018]. Comparatively, our algorithm can transfer between two non-similar and non-related distributions, for example, from random Gaussian noise to MNIST in Supplementary B.8. Another benefit of our method is that we provide conditions for global convergence of our algorithms in Section 4, whereas generative models or more specific, generative adversarial networks (GANs), currently do not guarantee global convergence [Wiatrak et al., 2019].
The application of our gradient flow is few-shot transfer learning, where we want to train classifiers with limited labeled data in the target domain. The numerical experiments in Section 5 demonstrate that our gradient flows can effectively augment the target data, and thus can significantly boost the accuracy in the classification task in the few-shot learning setting. Moreover, we run experiments on Tiny ImageNet datasets to highlight that our algorithm is scalable to higher-dimensional image data, that is higher than recent gradient flow works [Alvarez-Melis and Fusi, 2021; Fan and Alvarez-Melis, 2022]. We also compare our method with [Alvarez-Melis and Fusi, 2021], mixup method [Zhang et al., 2017], and traditional data augmentation methods in Supplementary B.7, which show that our method improves the accuracy in transfer learning more than these methods.
Some works study nonparametric gradient flows using the 2-Wasserstein distance between distributions [Ambrosio et al., 2008; Jordan et al., 1998; Otto, 2001; Villani, 2008; Santambrogio, 2015; Santambrogio, 2017; Frogner and Poggio, 2020], but only for distributions on Euclidean spaces and different metrics. Nonparametric gradient flows with other metrics include Sliced-Wasserstein Descent [Liutkus et al., 2019], Stein Descent [Liu, 2017; Liu and Wang, 2016], and Sobolev Descent [Mroueh et al., 2019], but only for distributions on Euclidean spaces. In particular, [Liu, 2017] introduce Riemannian structures for the Stein geometry on flat spaces, while ours is on a curved space. Parametric flows for training GANs are studied in [Chizat and Bach, 2018; Arbel et al., 2020; Mroueh and Nguyen, 2021].
Contributions. We study a gradient flow approach to synthesize new labeled samples related to the target domain. To construct this flow, we consider the space of probability distributions on the feature-Gaussian manifold, and we are metrizing this space with an optimal transport distance. We summarize the contributions of this paper as follows.
- We study in details the Riemannian structure of the featureGaussian manifold in Section 3, as well as the Riemannian structure of the space of probability measures supported on this manifold in Supplementary A.1.
- We consider a gradient flow that minimizes the squared MMD loss function to the target distribution. We describe explicitly the (Riemannian) gradient of the squared MMD in Lemma 5, and we provide a partial differential equation describing the evolution of the gradient flow that follows the (Riemannian) steepest descent direction.
- We propose two discretized schemes to approximate the continuous gradient flow equation in Section 4.1 and 4.2. We provide conditions guaranteeing the global convergence of our gradient flows to the optimum in both schemes.
- In Section 5, we demonstrate numerical results with our method on real-world image datasets. We show that our method can generate high-fidelity images and improve the classification accuracy in transfer learning settings.
Notations. We use Sn to denote the set of n × n real and symmetric matrices, and Sn++ ⊂ Sn consists of all positive definite matrices. For A ∈ Sn , tr(A) := ∑i Aii. We use ⟨·, ·⟩ and ∥ · ∥2 to denote the standard inner product and norm on Euclidean spaces. Let P(X) be the collection of all probability distributions with finite second moment on metric space X. If φ : X → Y is a Borel map and ν ∈ P(X), then the pushforward φ#ν is the distribution on Y given by φ#ν(E) = ν(φ-1 (E)) for all Borel sets E ⊂ Y . For a function f of the continuous time variable t, ft denotes the value of f at t while ∂tf denotes the standard derivative of f w.r.t. t. Also, δz denotes the Dirac delta measure at z.
All proofs are provided in the Supplementary material.
| Paper | Dataset | On curved Riemannian space | Gradient has mean and covariance component |
|---|---|---|---|
| [Alvarez-Melis and Fusi, 2021] | synthetic, *NIST, and CIFAR10 | ||
| [Arbel et al., 2019] | synthetic | ||
| Ours | synthetic, *NIST, and TinyImageNet | ✓ | ✓ |
2 Labeled Data Synthesis via Gradient Flows of Lifted Distributions
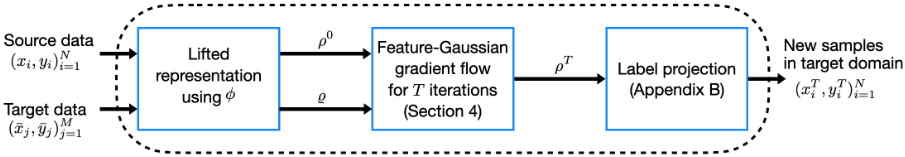
In this section, we describe our approach to synthesize target domain samples using gradient flows. A holistic view of our method is presented in Fig. 1.
In the first step, we would need to lift the feature-label space X × Y to a higher dimensional space where a metric can be defined. Consider momentarily the source data samples (xi, yi)Ni=1 . Notice that this data can be represented as an empirical distribution ν on X × Y. More precisely, we have ν = N -1 ∑Ni=1 δ(xi,yi). As Y is discrete, the law of conditional probabilities allows us to dis-integrate ν into the conditional distributions νy of X|Y = y satisfying ν(E × F) = ∫F νy(E)ν 2 (dy) for every E ⊂ X and F ⊂ Y, where ν 2 := N -1 ∑Ni=1 δyi is the second marginal of ν [Ambrosio et al., 2008, Theorem 5.3.1]. The lifting procedure is obtained by employing a pre-determined mapping ϕ : X → Rn , and any categorical value y ∈ Y can now be represented as an n-dimensional distribution ϕ#νy. Using this lifting, any source sample (xi, yi) ∈ X × Y is lifted to a point (xi, ϕ#νyi ) ∈ X × P(Rn ) and the source dataset is representable as an empirical distribution of the form N -1 ∑Ni=1 δ(xi,ϕ#νyi ).
The lifted representation of a categorical value y ∈ Y as an n-dimensional distribution ϕ#νy ∈ P(Rn ) is advantageous because P(Rn ) is metrizable, for example, using the 2-Wasserstein distance. The downside is that P(Rn ) is infinite dimensional, and encoding the datasets in this lifted representation is not efficient. To resolve this issue, we assume that ϕ#νy is Gaussian for all y ∈ Y, and thus any distribution ϕ#νy can be characterized by the mean vector µy ∈ Rn and covariance matrix Σy ∈ Sn++ defined as µy = ∫X ϕ(x)νy(dx) and Σy = ∫X [ϕ(x) - µy ][ϕ(x) - µy ]⊤νy(dx) for all y ∈ Y, where ⊤ denotes the transposition of a vector. In real-world settings, the conditional moments of ϕ(X)|Y are sufficiently different for y ̸= y′ , and thus the representations using (µy,Σy) will unlikely lead to any loss of label information. With this lifting, the source data thus can be represented as an empirical distribution ρ0 on Rm × Rn × Sn++ via ρ0 = N -1 ∑Ni=1 δ(xi,µyi ,Σyi ). By an analogous construction to compute ¯µy and ¯Σy using the target data, the target domain data (¯xj, ¯ yj)Mj=1 can be represented as another empirical distribution ϱ = M -1 ∑Mj=1 δ(¯xj ,¯µ¯ yj , ¯Σ¯ yj ). Let us denote the shorthand Z = Rm × Rn × Sn++, then ρ0 and ϱ are both probability measures on Z. We refer to ρ0 and ϱ as the feature- Gaussian representations of the source and target datasets.
We now consider the gradient flow associated with the optimization problem
under the initialization ρ = ρ0 . The objective function F(ρ) quantifies how far an incumbent solution ρ is from the target distribution ϱ, measured using the MMD distance. In Sections 3 and 4, we will provide the necessary ingredients to construct this flow.
Suppose that after T iterations of the discretized gradient flow algorithm, we obtain a distribution ρT ∈ P(Z) that is sufficiently close to ϱ, i.e., F(ρT ) is close to zero. Then we can recover new target labels by projecting the samples of the distribution ρT to the locations on X × Y. This projection can be computed efficiently by solving a linear optimization problem, as discussed in Supplementary B.3.
Remark 1 (Reduction of dimensions). If m= n and ϕ is the identity map, then our lifting procedure coincides with that proposed in [Alvarez-Melis and Fusi, 2020]. However, a large n is redundant, especially when the cardinality of Y is low. If n ≪ m, then ϕ offers significant reduction in the number of dimensions, and will speed up the gradient flow algorithms.
Remark 2 (Generalization to elliptical distributions). Our framework can be extended to the symmetric elliptical distributions because the Bures distance for elliptical distributions admits the same closed-form as for the Gaussian distributions [Gelbrich, 1990]. In this paper, we use ϕ as the t-SNE embedding. According to [van der Maaten and Hinton, 2008], t-SNE's low-dimensional embedded space forms a Student-t distribution, which is an elliptical distribution.
3 Riemannian Geometry of Z and P(Z)
If we opt to measure the distance between two Gaussian distributions using the 2-Wasserstein metric, then this choice would induce a natural distance d on the space Z = Rm ×Rn ×Sn++ prescribed as
As B is a metric on Sn+ [Bhatia et al., 2019, p.167], d is hence a product metric on Z. In this section, first, we study the non-Euclidean geometry of Z under the ground metric d. Second, we investigate the Riemannian structure on P(Z), the space of all distributions supported on Z and with finite second moment, that is induced by the optimal transport distance. These Riemannian structures are required to define the Riemannian gradients of any loss functionals on P(Z), and will remain important in our development of the gradient flow for the squared MMD.
The space Z is not a linear vector space. In this section, we reveal the Riemannian structure on Z associated to the ground metric d. As we shall see, Z is a curved space as its geodesics are not straight lines and involve solutions to the Lyapunov equation. For any positive definite matrix Σ ∈ Sn++ and any symmetric matrix V ∈ Sn , the Lyapunov equation
has a unique solution H ∈ Sn [Bhatia, 1997, Theorem VII.2.1]. Let LΣ[V ] denote this unique solution H.
The space Sn++ is a Riemannian manifold with the Bures metric B as the associated distance function, see [Takatsu, 2011, Proposition A]. Since Z is the product of two Euclidean spaces and Sn++, this gives rise to the following geometric structure for Z.
Proposition 3 (Geometry of Z). The space Z is a Riemannian manifold: at each point z = (x, µ, Σ) ∈ Z, the tangent space is TzZ = Rm × Rn × Sn and the Riemannian metric is
for two tangent vectors (w1, v1, V1) and (w2, v2, V2) in Rm × Rn × Sn , where ⟨V1, V2⟩Σ := tr(LΣ[V1]ΣLΣ[V2]). Moreover, the distance function corresponding to this Riemannian metric coincides with the distance d given by (3.1).
As Z is a product Riemannian manifold, any geodesic in Z is of the form (θ, γ, Γ) with θ, γ being the Euclidean geodesics (straight lines) and Γ being a geodesic in the Riemannian manifold Sn++. More precisely, for each Σ ∈ Sn++ and each tangent vector V ∈ Sn , the geodesic in the manifold Sn++ emanating from Σ with direction V is given by
where J ∗ is the open interval about the origin given by J ∗ = {t ∈ R : I + tLΣ[V ] ∈ Sn++} [Malag`o et al., 2018]. As a consequence, for each point (x, µ, Σ) ∈ Z and each tangent vector (w, v, V ) ∈ Rm×Rn×Sn , the Riemannian exponential map in Z for t ∈ J ∗ is given by
where θ(t) := x + tw, γ(t) := µ + tv, and Γ(t) is defined by (3.4). By definition, t ↦→ exp(x,µ,Σ)(t(w, v, V )) is the geodesic emanating from (x, µ, Σ) with direction (w, v, V ).
Given the Riemannian metric (3.3), one can define the corresponding notion of gradient and divergence [Lee, 2003]. For a differentiable function φ : Z → R, its gradient ˜∇dφ(z) w.r.t. the metric d defined by (3.1) is the unique element in the tangent space Rm × Rn × Sn satisfying
for all (w, v, V ) ∈ Rm×Rn×Sn with Dφz(w, v, V ) denoting the standard directional derivative of φ at z in the direction (w, v, V ). By exploiting the special form of ⟨·, ·⟩z in (3.3), we can compute ˜∇dφ(z) explicitly:
Lemma 4 (Gradients). For a differentiable function φ : Z → R, we have for z = (x, µ, Σ) that
where (∇x,∇µ,∇Σ) are the standard (Euclidean) gradients of the respective components.
The last component in formula (3.6) for ˜∇dφ reflects the curved geometry of Z, and can be interpreted as the Riemannian gradient of the function Σ ↦→ φ(x, µ, Σ) w.r.t. the Bures distance B.
For a continuous vector field Φ : Z → Rm ×Rn ×Sn and a distribution ρ ∈ P(Z), the divergence divd(ρΦ) is the signed measure on Z satisfying the integration by parts formula
for every differentiable function φ : Z → R with compact support. In case ρ has a density w.r.t. the Riemannian volume form on Z, then this definition coincides with the standard divergence operator induced by Riemannian metric (3.3). The optimal transport distance and its induced Riemannian metric on the space P(Z) are relegated to Supplementary A.1.
4 Gradient Flow for MaximumMean Discrepancy
As P(Z) is an infinite dimensional curved space, many machine learning methods based on finite dimensional or linear structure cannot be directly applied to this manifold. To circumvent this problem, we use a positive definite kernel to map P(Z) to a RKHS and then perform our analysis on it. Let k be a positive definite kernel on Z, and let H be the RKHS generated by k. The inner product on H is denoted by ⟨·, ·⟩H, and the kernel mean embedding ρ ∈ P(Z) ↦-→ mρ(·) ∈ H is given by mρ(z) := ∫Z k(z, w) ρ(dw) for z in Z. The MMD [Gretton et al., 2012] between ρ ∈ P(Z) and the target ϱ is defined as the maximum of the mean difference between the two distributions over all test functions in the unit ball of H (see Supplementary A.3). Moreover, it can be expressed by MMD(ρ, ϱ) = ∥mρ -mϱ∥H. When k is characteristic, the kernel mean embedding ρ ↦→ mρ is injective and therefore, MMD(ρ, ϱ) = 0 if and only if ρ = ϱ.
Consider the loss function F[ρ] := 1 2 MMD(ρ, ϱ)2 = 1 2 ∥mρ - mϱ∥2H. As explained in the introduction, there are three advantages of MMD over Kullback-Leibler divergence: its associated gradient flow can employ a sample approximation for the target distribution, the input distribution ρ does not have to be absolutely continuous w.r.t. the target distribution ϱ, and the squared MMD possesses unbiased sample gradients. For each ρ, the Riemannian gradient gradF[ρ] is defined as the unique element in TρP(Z) satisfying gρ(gradF[ρ], ζ) = d dt ∣∣∣t=0F[ρt] for every differentiable curve t ↦→ ρt ∈ P(Z) passing through ρ at t = 0 with tangent vector ∂tρt|t=0 = ζ. By using the Riemannian metric tensor (eq. A.3), we can compute explicitly this gradient.
The Riemannian gradient gradF on P(Z) depends not only on the gradient operator ˜∇d but also on the divergence operator. Using Lemma 5, we can rewrite the gradient flow equation ∂tρt = -gradF[ρt] explicitly as
The next result exhibits the rate at which F decreases its value along the flow.
Proposition 6 (Rate of decrease). Along the gradient flow t ↦→ ρt ∈ P(Z) given by (4.1), we have
Proposition 6 implies that d dt F[ρt] = 0 if and only if ˜∇d[mρt - mϱ](z) = 0 for every z in the support of the distribution ρt. Thus, the objective function will decrease whenever the gradient ˜∇d[mρt -mϱ] is not identically zero.
4.1 Riemannian Forward Euler Scheme
We propose the Riemannian version of the forward Euler scheme to discretize continuous flow (4.1):
where sτ > 0 is the step size. Here, for a vector field Φ = (Φ1,Φ2,Φ3) : Z → Rm × Rn × Sn and for ε ≥ 0, exp(εΦ) : Z → Z is the Riemannian exponential map induced by (3.5), i.e., for z = (x, µ, Σ) ∈ Z:
Notice in the above equation that the input z affects simultaneously the bases of the exponential map expz as well as the direction Φ(z). This map is the ε-perturbation of the identity map along geodesics with directions Φ. When ρτ = N -1 ∑Ni=1 δzτ i is an empirical distribution, scheme (4.2) flows each particle zτ i to the new position zτ+1 i = expzτ i (sτΦ(zτ i )). The next lemma shows that Φτ is the steepest descent direction for F w.r.t. the exponential map among all directions in the space L2 (ρτ ), which is the collection of all vector fields Φ on Z satisfying ∥Φ∥2L2 (ρτ ) :=
Lemma 7 (Steepest descent direction). Fix a distribution ρτ ∈ P(Z). For any vector field Φ : Z → Rm × Rn × Sn , we have
If ˆΦτ is the unit vector field (w.r.t. the ∥ · ∥L2 (ρτ ) norm) in the direction of Φτ given in (4.2), then
and this is the fastest decay rate among all unit directions Φ in L2 (ρτ ).
It follows from Lemma 7 that the discrete scheme (4.2) satisfies the Riemannian gradient descent property: if ˜∇d[mρτ - mϱ] is nonzero and if sτ > 0 is chosen sufficiently small, then F[ρτ+1 ] < F[ρτ ]. In Proposition 14 in the Supplementary, we quantify the amount of decrease of F at each iteration. Algorithm 1 implements the flow (4.2) iteratively. Each iteration in Algorithm 1 has complexity O(N(Nm + n3 )), where m is the feature's dimension, n is the reduced dimension (n ≪m), N is the number of particles.
Convergence. We now study the (weak) convergence of the solution ρt of the continuous gradient flow (4.1), as well as the discretized counterpart ρτ of flow (4.2), to the target distribution ϱ. When the kernel k is characteristic, this convergence is equivalent to limt→∞MMD(ρt, ϱ) = 0. Because the objective function F is not displacement convex [Arbel et al., 2019, Section 3.1], the convergent theory for gradient flows in [Ambrosio et al., 2008] does not apply even in the case of Euclidean spaces. In general, there is a possibility that MMD(ρt, ϱ) does not decrease to zero as t → ∞. In view of Proposition 6, this happens if the solutions ρt are trapped inside the set {ρ : ∫Z ∥∥˜∇d[mρ -mϱ]∥∥2z ρ(dz) = 0}. For each distribution ρ on Z, we define in Supplementary A.3 a symmetric linear and positive operator Kρ : H → H with the property that ⟨Kρ[mρ -mϱ],mρ -mϱ⟩H = ∫Z ∥∥ ˜∇d[mρ - Algorithm 1 Discretized Gradient Flow Algorithm for Scheme (4.2)
- 1: Input: a source distribution ρ0 = N -1 ∑Ni=1 δz0 i , a target distribution ϱ = M -1 ∑Mj=1 δ¯ zj , a number of iterations T , a sequence of step sizes sτ > 0 with τ = 0, 1, ..., T and a kernel k
- 2: Initialization: Compute ¯Ψ(z)=M -1 ∑Mj=1 ˜∇1dk(z, ¯ zj ) with ˜∇1dk(z, ¯ zj) is ˜∇d of z ↦→ k(z, ¯ zj )
- 3: repeat for each τ = 0, . . . , T -1:
- 4: Compute Ψτ (z) = N -1 ∑Ni=1 ˜∇1dk(z, zτ i )
- 5: for i = 1, . . . ,N
- 6: do zτ+1 i ← expzτ i (sτ ( ¯Ψ - Ψτ )(zτ i ))
- 7: end for
- 8: Output: ρT = N -1 ∑Ni=1 δzT i
mϱ]∥∥2z ρ(dz). We further show in Proposition 16 that ρt globally converges in MMD if the minimum eigenvalue λt of the operator Kρt satisfies an integrability condition.
4.2 Noisy Riemannian Forward Euler Scheme
The analysis in Section 4.1 reveals that the gradient flows suffer from convergence issues if the residual mρt - mϱ belongs to the null space of the operator Kρt . To resolve this, we employ graduated optimization [Arbel et al., 2019; Gulcehre et al., 2016; Gulcehre et al., 2017; Hazan et al., 2016] used for non-convex optimization in Euclidean spaces. Specifically, we modify algorithm (4.2) by injecting Gaussian noise into the exponential map at each iteration τ to obtain
Here g is a Gaussian measure with distribution NRm(0, 1)⊗ NRn(0, 1) ⊗ NSn(0, 1) on the tangent space and NSn(0, 1) denotes an n-by-n symmetric matrix whose upper triangular elements are i.i.d. standard Gaussian random variables. When ρτ = N -1 ∑Ni=1 δzτ i , scheme (4.3) flows each particle zτ i first to zτ,βτ i := expzτ i (βτU) with noise U ∼ g and then to zτ+1 i = expzτ,βτ i (sτΦ(zτ,βτ i )). Our next result extends Proposition 8 in [Arbel et al., 2019] for the standard quadratic cost on the Euclidean space to the nonstandard cost function d2 on the curved Riemannian manifold Z++. It demonstrates that scheme (4.3) achieves the global minimum of F provided that k is a Lipschitz-gradient kernel and both the noise level βτ and the step size sτ are well controlled. The proof of Proposition 8 is given in Supplementary A.3 and relies on arguments that are different from that of [Arbel et al., 2019].
Proposition 8 (Objective value decay for noisy scheme). Suppose that k is a Lipschitz-gradient kernel 2 with constant L, and the noise level βτ satisfies
2 See Definition A.3 for the technical definition
for some constant λ > 0. Then for ρτ+1 obtained from scheme (4.3), we have
In particular, F[ρτ ] tends to zero if the sequence ∑τi=0 si (1 - 2Lsi )β2 i goes to positive infinity. For an adaptive step size sτ ≤ 1/4L, this condition is met if, for example, βτ is chosen of the form (τsτ)- 1 2 while still satisfying (4.4). The noise perturbs the direction of descent, whereas the step size determines how far to move along this perturbed direction. The noise level needs to be adjusted so that the gradient is not too blurred, but it does not necessarily decrease at each iteration. When the incumbent distribution ρτ is close to a local optimum, it is helpful to increase the noise level to escape the local optimum. We demonstrate in Lemma 13 in the Supplementary that any positive definite kernel k with bounded Hessian w.r.t. distance d is a Lipschitz-gradient kernel. Algorithm 2 in the Supplementary describes (4.3) in details.
5 Numerical Experiments
We evaluate the proposed gradient flow on real-world datasets and then illustrate its applications in transfer learning. We augment samples for the target dataset, where only a few samples in the dataset are available. We consider three datasets: the MNIST (M) [LeCun and Cortes, 2010], Fashion-MNIST (F) [Xiao et al., 2017], Kuzushiji-MNIST (K) [Clanuwat et al., 2018]. To satisfy the Gaussianity assumption of the conditional distributions, we cluster all the images from each class of the datasets and keep the largest cluster for each class. To demonstrate the scalability of our algorithm to higherdimensional images, we run experiments on Tiny ImageNet (TIN) [Russakovsky et al., 2015] and upscaled SVHN [Netzer et al., 2011] datasets, where images are of 3 × 64 × 64 size.
Our mapping ϕ is from Rm to R2 in the lifting procedure. To compute the MMD distance using kernel embeddings, we use a tensor kernel k on Z composed from three standard Gaussian kernels corresponding for each component of the feature space Rm, the mean space R2 and the covariance matrix space S2++. As a consequence, k is a characteristic kernel by [Szab´o and Sriperumbudur, 2018, Theorem 4].
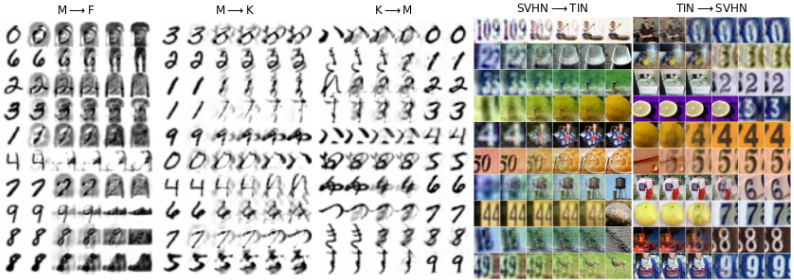
Experiment: Gradient Flow between Datasets. We visualize the path travelled by each sample from the source domain to the target domain, as depicted in Fig. 2. We draw randomly N = 200 images equally for 10 classes of the source domain, and M = 50 images equally for 10 classes of the target domain (M = 10 for the TIN and SVHN datasets). In each subfigure, each column represents a snapshot of a certain timestep and the samples flow from the source (left) to the target (right) as the number of steps increases. The first column in Fig. 2 are the images from the source domain, where the gradient flows start. Empirically, the algorithm converges after step 140 for *NIST datasets and step 6000 for TIN and SVHN. The experiments are run on a C5.4xlarge AWS instance (a CPU instance) and all finish in about one hour.
5.1 Application in Transfer Learning
Our gradient flow can alleviate the problem of insufficient labeled data by synthesizing new samples to augment the target dataset. In this section, we demonstrate that the generated target domain samples can improve the accuracy in one-shot and five-shot transfer learning tasks.
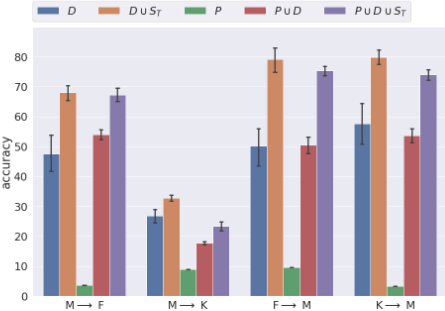
First, we fix a source domain and pretrain a classifier P on this domain. We draw randomly N samples from the source domain to form the source dataset (xi, yi)Ni=1 . Next, we pick a target domain and draw randomly a few samples from this target domain: for example, in 1-shot learning, only 1 image per class from the target domain is selected to form the target dataset D = (¯xj , ¯ yj)Mj=1 . We then perform a noisy gradient flow scheme (4.3) from the source dataset to the target dataset to get N new samples ST = (xTi , yT i )Ni=1 . With the target dataset D and new samples ST , we can retrain the classifier P. Similarly, we can also train new classifiers from scratch using datasets D and D ∪ ST . Finally, we test the classifiers on the test set of the target domain.
Fig. 3 presents the accuracy of five transfer learning strategies on four pairs of source and target domain. For the labels above the plot, labels without P mean training a new classifier from scratch, whereas labels with P mean transferring the pretrained classifier. D and ST represent the samples in the target domain and our flowed samples. We observe a common trend that the addition of the flowed samples ST always improves the accuracy of the classifiers, as we compare D ∪ ST with D and compare P ∪ D ∪ ST with P ∪ D. Moreover, the data augmentation with ST leads to a higher increase of accuracy for the 1-shot learning, where the data scarcity problem is more severe. The transfer learning results for SVHN and TIN datasets are provided in the Supplementary B.6. Although few-shot learning is more challenging due to the high complexity of the datasets, the addition of ST always improves the accuracy. We also compare with baseline 3 , mixup method and image augmentation methods in Supplementary B.7.
Conclusions. This paper focuses on a gradient flow approach to generate new labeled data samples in the target domain. To overcome the discrete nature of the labels, we represent datasets as distributions on the feature-Gaussian space, and the flow is formulated to minimize the MMD loss function under an optimal transport metric. Contrary to existing gradient flows on linear structure, our flows are developed on the curved Riemannian manifold of Gaussian distributions. We provide explicit formula for the Riemannian gradient of MMD, and analyze in details the flow equations and the convergence properties of both continuous and discretized forms. The numerical experiments demonstrate that our method can efficiently generate high-fidelity labeled training data for realworld datasets, and improve the classification accuracy in fewshot learning. The main limitation exists in the assumption that the data of one label forms an elliptical distribution.
3 The only gradient flow work that has experiments on *NIST datasets, but it does not run experiments on TIN and SVHN.
Ethical Statement
Our work has positive societal impacts. Our work can enlarge the number of labelled data on any domains, so it alleviates the data scarcity problem in supervised learning settings. As a result, it can help reduce repetitive data collection and labeling work. It does not have possible negative societal impacts in the current stage.
Acknowledgements
We thank the anonymous reviewers for their comments. XH is supported by the Air Force Office of Scientific Research under award number FA9550-20-1-0397. Additional support from NSF 1915967, NSF 2118199, and the Ford-Stanford alliance is gratefully acknowledged. The research of TN is supported in part by a grant from the Simons Foundation (#318995). TL gratefully acknowledges the support of JSPS KAKENHI Grants 20K19873 and 23K11243. VAN acknowledges the generous support from the CUHK's Improvement on Competitiveness in Hiring New Faculties Funding Scheme.
@inproceedings{ijcai2023p423,
  title     = {Dynamic Flows on Curved Space Generated by Labeled Data},
  author    = {Hua, Xinru and Nguyen, Truyen and Le, Tam and Blanchet, Jose and Nguyen, Viet Anh},
  booktitle = {Proceedings of the Thirty-Second International Joint Conference on
               Artificial Intelligence, {IJCAI-23}},
  publisher = {International Joint Conferences on Artificial Intelligence Organization},
  editor    = {Edith Elkind},
  pages     = {3803--3811},
  year      = {2023},
  month     = {8},
  note      = {Main Track},
  doi       = {10.24963/ijcai.2023/423},
  url       = {https://doi.org/10.24963/ijcai.2023/423},
}
TY - CPAPER TI - Dynamic Flows on Curved Space Generated by Labeled Data AU - Hua, Xinru AU - Nguyen, Truyen AU - Le, Tam AU - Blanchet, Jose AU - Nguyen, Viet Anh T2 - Proceedings of the Thirty-Second International Joint Conference on Artificial Intelligence, IJCAI-23 PB - International Joint Conferences on Artificial Intelligence Organization PY - 2023 SP - 3803 EP - 3811 DO - 10.24963/ijcai.2023/423 UR - https://doi.org/10.24963/ijcai.2023/423 ER -Copied
Machine-readable versions of this paper, for tools and AI agents:





