
Most General Explanations of Tree Ensembles
Proceedings of the Thirty-Fourth International Joint Conference on Artificial Intelligence. Main Track. Pages 5463-5471.
https://doi.org/10.24963/ijcai.2025/608
Keywords
- Knowledge Representation and Reasoning: KRR: Diagnosis and abductive reasoning
- Constraint Satisfaction and Optimization: CSO: Constraint satisfaction
- Constraint Satisfaction and Optimization: CSO: Constraint optimization problems
- Machine Learning: ML: Explainable/Interpretable machine learning
Abstract
Explainable Artificial Intelligence (XAI) is critical for attaining trust in the operation of AI systems. A key question of an AI system is ``why was this decision made this way''. Formal approaches to XAI use a formal model of the AI system to identify abductive explanations. While abductive explanations may be applicable to a large number of inputs sharing the same concrete values, more general explanations may be preferred for numeric inputs.
So-called inflated abductive explanations give intervals for each feature ensuring that any input whose values fall withing these intervals is still guaranteed to make the same prediction. Inflated explanations cover a larger portion of the input space, and hence are deemed more general explanations. But there can be many (inflated) abductive explanations for an instance. Which is the best? In this paper, we show how to find a most general abductive explanation for an AI decision. This explanation covers as much of the input space as possible, while still being a correct formal explanation of the model's behaviour. Given that we only want to give a human one explanation for a decision, the most general explanation gives us the explanation with the broadest applicability, and hence the one most likely to seem sensible.
- [Bailey and Stuckey, 2005] James Bailey and Peter J. Stuckey. Discovery of minimal unsatisfiable subsets of constraints using hitting set dualization. In PADL, pages 174-186, 2005.
- [Bassan and Katz, 2023] Shahaf Bassan and Guy Katz. To- wards formal XAI: formally approximate minimal expla- nations of neural networks. In TACAS, pages 187-207, 2023.
- [Biere et al., 2021] Armin Biere, Marijn Heule, Hans van Maaren, and Toby Walsh, editors. Handbook of Satisfi- ability -Second Edition. 2021.
- [Biradar et al., 2024] Gagan Biradar, Yacine Izza, Elita A. Lobo, Vignesh Viswanathan, and Yair Zick. Axiomatic aggregations of abductive explanations. In AAAI, pages 11096-11104, 2024.
- [Breiman, 2001] Leo Breiman. Random forests. Mach. Learn., 45(1):5-32, 2001.
- [Chandrasekaran et al., 2011] Karthekeyan Chandrasekaran, Richard M. Karp, Erick Moreno-Centeno, and Santosh S. Vempala. Algorithms for implicit hitting set problems. In SODA, pages 614-629, 2011.
- [Chen and Guestrin, 2016] Tianqi Chen and Carlos Guestrin. XGBoost: A scalable tree boosting system. In KDD, pages 785-794, 2016.
- [Clarke et al., 2003] Edmund M. Clarke, Orna Grum- berg, Somesh Jha, Yuan Lu, and Helmut Veith. Counterexample-guided abstraction refinement for sym- bolic model checking. J. ACM, 50(5):752-794, 2003.
- [Darwiche, 2023] Adnan Darwiche. Logic for explainable AI. In LICS, pages 1-11, 2023.
- [Davies and Bacchus, 2011] Jessica Davies and Fahiem Bac- chus. Solving MAXSAT by solving a sequence of simpler SAT instances. In CP, pages 225-239, 2011.
- [Friedman, 2001] Jerome H. Friedman. Greedy function ap- proximation: A gradient boosting machine. The Annals of Statistics, 29(5):1189-1232, 2001.
- [Gorji and Rubin, 2022] Niku Gorji and Sasha Rubin. Suf- ficient reasons for classifier decisions in the presence of domain constraints. In AAAI, pages 5660-5667, 2022.
- Gurobi Optimization, LLC. Gurobi Optimizer Reference Manual, 2023.
- [Huang et al., 2023] Xuanxiang Huang, Yacine Izza, and João Marques-Silva. Solving explainability queries with quantification: The case of feature relevancy. In AAAI, pages 3996-4006, 2023.
- [Ignatiev et al., 2015] Alexey Ignatiev, Alessandro Previti, Mark H. Liffiton, and Joao Marques-Silva. Smallest MUS extraction with minimal hitting set dualization. In CP, pages 173-182, 2015.
- [Ignatiev et al., 2018] Alexey Ignatiev, António Morgado, and Joao Marques-Silva. PySAT: A python toolkit for pro- totyping with SAT oracles. In SAT, pages 428-437, 2018.
- [Ignatiev et al., 2019a] Alexey Ignatiev, Antonio Morgado, and Joao Marques-Silva. RC2: an efficient MaxSAT solver. J. Satisf. Boolean Model. Comput., 11(1):53-64, 2019.
- [Ignatiev et al., 2019b] Alexey Ignatiev, Nina Narodytska, and Joao Marques-Silva. Abduction-based explanations for machine learning models. In AAAI, pages 1511-1519, 2019.
- [Ignatiev et al., 2020] Alexey Ignatiev, Nina Narodytska, Nicholas Asher, and Joao Marques-Silva. From con- trastive to abductive explanations and back again. In AIxIA, pages 335-355, 2020.
- [Ignatiev et al., 2022] Alexey Ignatiev, Yacine Izza, Peter J. Stuckey, and João Marques-Silva. Using MaxSAT for ef- ficient explanations of tree ensembles. In AAAI, pages 3776-3785, 2022.
- [Ignatiev et al., 2024] Alexey Ignatiev, Zi Li Tan, and Chris- tos Karamanos. Towards universally accessible SAT tech- nology. In SAT, pages 4:1-4:11, 2024.
- [Ignatiev, 2020] Alexey Ignatiev. Towards trustable explain- able AI. In IJCAI, pages 5154-5158, 2020. IJCAI
- [Izza and Marques-Silva, 2021] Yacine Izza and Joao Marques-Silva. On explaining random forests with SAT. In IJCAI, pages 2584-2591, 2021. IJCAI
- [Izza and Marques-Silva, 2024] Yacine Izza and Joao Marques-Silva. Efficient contrastive explanations on demand. CoRR, abs/2412.18262, 2024.
- [Izza et al., 2022] Yacine Izza, Alexey Ignatiev, and João Marques-Silva. On tackling explanation redundancy in de- cision trees. J. Artif. Intell. Res., 75:261-321, 2022.
- [Izza et al., 2023a] Yacine Izza, Xuanxiang Huang, Alexey Ignatiev, Nina Narodytska, Martin C. Cooper, and João Marques-Silva. On computing probabilistic abductive ex- planations. Int. J. Approx. Reason., 159:108939, 2023.
- [Izza et al., 2023b] Yacine Izza, Alexey Ignatiev, Peter J. Stuckey, and João Marques-Silva. Delivering inflated ex- planations. CoRR, 2023.
- [Izza et al., 2024a] Yacine Izza, Xuanxiang Huang, Anto- nio Morgado, Jordi Planes, Alexey Ignatiev, and Joao Marques-Silva. Distance-Restricted Explanations: Theo- retical Underpinnings & Efficient Implementation. In KR, pages 475-486, 2024.
- [Izza et al., 2024b] Yacine Izza, Alexey Ignatiev, Peter J. Stuckey, and João Marques-Silva. Delivering inflated ex- planations. In AAAI, pages 12744-12753, 2024.
- [Izza et al., 2025] Yacine Izza, Alexey Ignatiev, Sasha Ru- bin, Joao Marques-Silva, and Peter J. Stuckey. Most gen- eral explanations of tree ensembles (extended version). CoRR, abs/2505.10991, 2025.
- [Ji and Darwiche, 2023] Chunxi Ji and Adnan Darwiche. A new class of explanations for classifiers with non-binary features. In JELIA, pages 106-122, 2023.
- [Létoffé et al., 2025] Olivier Létoffé, Xuanxiang Huang, and João Marques-Silva. Towards trustable SHAP scores. In AAAI, pages 18198-18208, 2025.
- [Liffiton and Malik, 2013] Mark H. Liffiton and Ammar Ma- lik. Enumerating infeasibility: Finding multiple muses quickly. In CPAIOR, pages 160-175, 2013.
- [Liffiton et al., 2016] Mark H. Liffiton, Alessandro Previti, Ammar Malik, and João Marques-Silva. Fast, flexible MUS enumeration. Constraints An Int. J., 21(2):223-250, 2016.
- [Lundberg and Lee, 2017] Scott M. Lundberg and Su-In Lee. A unified approach to interpreting model predictions. In NeurIPS, pages 4765-4774, 2017.
- [Marques-Silva and Huang, 2024] João Marques-Silva and Xuanxiang Huang. Explainability is not a game. Com- mun. ACM, 67(7):66-75, 2024.
- [Marques-Silva and Ignatiev, 2022] João Marques-Silva and Alexey Ignatiev. Delivering trustworthy AI through formal XAI. In AAAI, pages 12342-12350, 2022.
- [Marques-Silva, 2022] João Marques-Silva. Logic-based ex- plainability in machine learning. In Reasoning Web, pages 24-104, 2022.
- [Marques-Silva, 2024] João Marques-Silva. Logic-based ex- plainability: Past, present and future. In ISoLA, volume 15222, pages 181-204, 2024.
- [Miller, 2019] Tim Miller. Explanation in artificial intelli- gence: Insights from the social sciences. Artif. Intell., 267:1-38, 2019.
- [Molnar, 2020] Christoph Molnar. Interpretable machine learning. 2020.
- [Olson et al., 2017] Randal S. Olson, William La Cava, Pa- tryk Orzechowski, Ryan J. Urbanowicz, and Jason H. Moore. PMLB: a large benchmark suite for machine learn- ing evaluation and comparison. BioData Mining, 10(1):36, 2017.
- [Pedregosa and et al., 2011] Fabian Pedregosa and et al. Scikit-learn: Machine learning in Python. Journal of Ma- chine Learning Research, 12:2825-2830, 2011.
- [Previti and Marques-Silva, 2013] Alessandro Previti and Joao Marques-Silva. Partial MUS enumeration. In AAAI, pages 818-825, 2013.
- [Ribeiro et al., 2016] Marco Túlio Ribeiro, Sameer Singh, and Carlos Guestrin. "why should I trust you?": Explain- ing the predictions of any classifier. In KDD, pages 1135- 1144, 2016.
- [Ribeiro et al., 2018] Marco Túlio Ribeiro, Sameer Singh, and Carlos Guestrin. Anchors: High-precision model- agnostic explanations. In AAAI, pages 1527-1535, 2018.
- [Rudin et al., 2022] Cynthia Rudin, Chaofan Chen, Zhi Chen, Haiyang Huang, Lesia Semenova, and Chudi Zhong. Interpretable machine learning: Fundamental prin- ciples and 10 grand challenges. Statistics Surveys, 16:1- 85, 2022.
- [Rudin, 2019] Cynthia Rudin. Stop explaining black box machine learning models for high stakes decisions and use interpretable models instead. Nature Machine Intelligence, 1(5):206-215, 2019.
- [Saikko et al., 2016] Paul Saikko, Johannes Peter Wallner, and Matti Jarvisalo. Implicit hitting set algorithms for rea- soning beyond NP. In KR, pages 104-113, 2016.
- [Samek et al., 2019] Wojciech Samek, Grégoire Montavon, Andrea Vedaldi, Lars Kai Hansen, and Klaus-Robert Müller, editors. Explainable AI: Interpreting, Explaining and Visualizing Deep Learning. Springer, 2019.
- [Samek et al., 2021] Wojciech Samek, Grégoire Montavon, Sebastian Lapuschkin, Christopher J. Anders, and Klaus- Robert Müller. Explaining deep neural networks and be- yond: A review of methods and applications. Proc. IEEE, 109(3):247-278, 2021.
- [Shanahan, 1989] Murray Shanahan. Prediction is deduction but explanation is abduction. In IJCAI, pages 1055-1060, 1989. IJCAI
- [Shih et al., 2018] Andy Shih, Arthur Choi, and Adnan Dar- wiche. A symbolic approach to explaining bayesian net- work classifiers. In IJCAI, pages 5103-5111, 2018. IJCAI
- [Slack et al., 2020] Dylan Slack, Sophie Hilgard, Emily Jia, Sameer Singh, and Himabindu Lakkaraju. Fooling LIME and SHAP: adversarial attacks on post hoc explanation methods. In AIES, pages 180-186, 2020.
- [Swartout, 1977] William R. Swartout. A digitalis therapy advisor with explanations. In IJCAI, pages 819-825, 1977. IJCAI
- [Swartout, 1983] William R. Swartout. XPLAIN: A system for creating and explaining expert consulting programs. Artif. Intell., 21(3):285-325, 1983.
- [UCI, 2020] UCI Machine Learning Repository. https:// archive.ics.uci.edu/ml, 2020. Link
- [Wäldchen et al., 2021] Stephan Wäldchen, Jan MacDonald, Sascha Hauch, and Gitta Kutyniok. The computational complexity of understanding binary classifier decisions. J. Artif. Intell. Res., 70:351-387, 2021.
- [Wu et al., 2023] Min Wu, Haoze Wu, and Clark W. Barrett. Verix: Towards verified explainability of deep neural net- works. In NeurIPS, 2023.
- [Yu et al., 2023a] Jinqiang Yu, Alexey Ignatiev, and Peter J. Stuckey. From formal boosted tree explanations to inter- pretable rule sets. In CP, pages 38:1-38:21, 2023.
- [Yu et al., 2023b] Jinqiang Yu, Alexey Ignatiev, and Peter J. Stuckey. On formal feature attribution and its approxima- tion. CoRR, abs/2307.03380, 2023.
- [Yu et al., 2023c] Jinqiang Yu, Alexey Ignatiev, Peter J. Stuckey, Nina Narodytska, and Joao Marques-Silva. Elim- inating the impossible, whatever remains must be true: On extracting and applying background knowledge in the con- text of formal explanations. In AAAI, 2023.
- [Yu et al., 2024] Jinqiang Yu, Graham Farr, Alexey Ignatiev, and Peter J. Stuckey. Anytime approximate formal feature attribution. In SAT, pages 30:1-30:23, 2024.
References were extracted automatically from the PDF and may contain errors.
Full text extracted automatically from the PDF; figures, tables and equations may differ. The PDF is the version of record.
1 Introduction
The widespread use of artificial intelligence to make or support decisions effecting humans has led to the need for these systems to be able to explain their decisions. The field of eXplainable AI (XAI) has emerged in response to this need. Its generally accepted that XAI is required to deliver trustworthy AI systems. Unfortunately the bulk of work in XAI offers no formal guarantees, or even clear definitions of the "meaning" of an explanation. Examples of non-formal XAI include model-agnostic methods [Ribeiro et al., 2016; Lundberg and Lee, 2017; Ribeiro et al., 2018], heuristic learning of saliency maps (and their variants) [Samek et al., 2019; Samek et al., 2021], but also proposals of intrinsic interpretability [Rudin, 2019; Molnar, 2020; Rudin et al., 2022]. In recent years, comprehensive evidence has been gathered that attests to the lack of rigor of these (non-formal) XAI approaches [Slack et al., 2020; Ignatiev, 2020; Wu et al., 2023; Marques-Silva and Huang, 2024].
Formal XAI [Shih et al., 2018; Ignatiev et al., 2019b; Marques-Silva and Ignatiev, 2022] in contrast provides rigorous definitions of explanations which have desirable properties as well as practical algorithms to compute them. But formal XAI methods also have limitations: they may not scale and hence may be unable to provide explanations for some complex AI models.
Abductive explanations [Shih et al., 2018; Ignatiev et al., 2019b] are the most commonly used formal XAI approach. An abductive explanation is a subset-minimal set of features, which guarantee that if the values of the instance being explained are used for these features, then the decision of the AI system will remain the same. Hence these feature values of the instance are "sufficient" to ensure the decision. For example if a male patient with O+ blood type, height 1.82m and weight 90kg is found to be at risk of a disease by an AI system, an abductive explanation might be that the height and weight are the only required features: thus anyone with height 1.82m and weight 90kg would also be at risk.
While abductive explanations have nice properties and are a valuable tool, they are quite restrictive. The abductive explanation above says nothing about a person with height 1.81m. Recently, inflated formal explanations have been proposed [Izza et al., 2024b], which extend abductive explanations to include maximal ranges for features that still guarantee the same decision. An inflated abductive explanation for the disease example may be that any person with height in the range 1.80-2.50m and weight 90-150kg also has the same risk.
When explaining the reason for an AI system decision for a particular instance, there can exist many possible formal abductive explanations; similarly there can exist many possible inflated abductive explanations. Ideally when explaining a decision to a human we would like to give a single explanation. In this work we show how we can compute the most general abductive explanation, in some sense the most general explanation of the AI systems behaviour. More precisely, the contributions of this paper are:
- An implicit hitting set approach to compute most general inflated abductive explanations;
- Two Boolean Satisfiability (SAT) encodings and an Integer Linear Program (ILP) encoding for generating candidate maximal abductive explanations;
- Experiments showing that we can in practice create most
general abductive explanations.
2 Preliminaries
2.1 Classification Problems
Let F be a set of variables called features, say F = [m]. Each feature i is equipped with a finite domain Di. In general, when referring to the value of a feature i ∈ F, we will use a variable xi, with xi taking values from Di. Domains are ordinal that can be integer or real-valued. The feature space is defined as F = ∏i∈F Di. The notation x = (x1, . . . , xm) denotes an arbitrary point in feature space, whilst the notation v = (v1, . . . , vm) represents a specific point in feature space. A region is a set E = E1 × · · · × Em consisting of, for each feature i, a non-empty set Ei ⊆ Di of values (it can also be viewed as a function that maps feature i to Ei). A total classification function κ : F → K where K = {c1, . . . , cK} is a set of classes for some K ≥ 2. For technical reasons, we also require κ not to be a constant function, i.e. there exists at least two points in feature space with differing predictions. An instance denotes a pair (v, c), where v ∈ F and c ∈ K. We represent a classifier by a tuple M = (F, F, K, κ). Given the above, an explanation problem is a tuple E = (M, (v, c)).
2.2 Formal Explainability
Two types of formal explanations have been predominantly studied: abductive [Shih et al., 2018; Ignatiev et al., 2019b] and contrastive [Miller, 2019; Ignatiev et al., 2020]. Abductive explanations (AXps) broadly answer a Why question, i.e. Why the prediction?, whereas contrastive explanations (CXps) broadly answer a Why Not question, i.e. Why not some other prediction?. Intuitively, an AXp is a subsetminimal set of feature values (xi = vi), at most one for each feature i ∈ F, that is sufficient to trigger a particular class and satisfy the instance being explained. Similarly, a CXp is a subset-minimal set of features by changing the values of which one can trigger a class different from the target one. More formally, AXps and CXps are defined below.
Given an explanation problem E = (M, (v, c)), an abductive explanation (AXp) of E is a subset-minimal set X ⊆ F of features which, if assigned the values dictated by the instance (v, c), are sufficient for the prediction. The latter condition is formally stated, for a set X, as follows:
Any subset X ⊆ F that satisfies (1), but is not subsetminimal (i.e. there exists X ′ ⊂ X that satisfies (1)), is referred to as a weak abductive explanation (Weak AXp).
Given an explanation problem, a contrastive explanation (CXp) is a subset-minimal set of features Y ⊆ F which, if the features in F \ Y are assigned the values dictated by the instance (v, c), then there is an assignment to the features in Y that changes the prediction. This is stated as follows, for a chosen set Y ⊆ F:
AXp's and CXp's respect a minimal-hitting set (MHS) duality relationship [Ignatiev et al., 2020]. Concretely, each AXp is an MHS of the CXp's and each CXp is an MHS of the AXp's. MHS duality is a stepping stone for the enumeration of explanations.
Inflated Formal Explanations. An inflated abductive explanation (iAXp) of E = (M, (v, c)) is a tuple (X , E), where X ⊆ F is an AXp, and E is a region where (i) Ei ⊂ Di for each i ∈ X and Ei = Di for each i ∈ (F \ X), (ii) vi ∈ Ei for each i ∈ X, such that
and E is a maximal set with properties (i), (ii), and (3), i.e. if E′ is any range that satisfies (i), (ii) and (3), then it is not the case that E′ ⊃ E.
A size measure s is a mononotic function that maps a region E ⊆ F to a real number. Consider an iAXp (X, E) and a size measure s, then (X , E) is called a maximum iAXp if its size score s(E) is a maximum amongst all iAXp's, i.e., if E′ is an iAXp, then s(E′ ) ≤ s(E).
Later, when dealing with tree ensemble models, we will instantiate s to a specific coverage measure on ranges consisting of intervals.
Example 1. Consider 3 features xi, i ∈ [3], representing an individual's blood type, their age, and weight with the domains D1 = {A,B,AB,O}, D2 = [20, 80], and D3 = [50, 150]. Assume the classifier κ(x) predicts a high risk of a disease if x2 ≥ 60 and x3 ≥ 80; otherwise, κ(x) predicts the individual to be at low risk of a disease. (Observe that the blood type x1 is ignored in the decision making process.) Consider an instance v = (A, 65, 85), which is classified as high risk. The only AXp for this instance is X = {2, 3}. Now, consider a simple size measure s(Ei) = |Ei|/|Di|. While there are multiple ways to inflate X using this size measure, the maximum and, intuitively, the most general iAXp consists of the intervals E2 = [60, 80] and E3 = [80, 150].
An inflated contrastive explanation (iCXp) is a pair (Y, G) s.t. Y is a CXp of E, and vi ̸∈ Gi for each feature i ∈ Y and Gi = {vi} for any i ∈ (F \Y), such that the following holds:
Example 2. Consider again Example 1 and v = (A, 65, 85) classified as a high risk. If a user is interested in answering why not a low risk, a possible CXp to extract is Y1 = {2}. This means that by suitably changing the value of x2 to some value taken from its entire domain [20, 80], the prediction can be changed to low risk even if features x1 and x3 are fixed, resp., to values A and 85. Observe that the freedom of selecting the entire domain D2 although perfectly valid provides a user with little to no insight on how the prediction can be changed, as it contains values, namely those in [60, 80], that if chosen do not lead to a misclassification. Inflating the CXp Y1 can be done differently and may result in a valid shrunk interval, say, G2 = [20, 65]. Intuitively, the most informative iCXp shrinks the domain D2 into the set G′2 = [20, 60), while ensuring a misclassification is still achievable. Similarly, another CXp for instance v is Y2 = {3}, with the most sensible inflation being G3 = [50, 80).
Let us denote the set of all iAXp's for a particular explanation problem E as A(E) while the set of all iCXp's will be denoted as C(E). Similar to the case of traditional abductive and contrastive explanations, minimal hitting set (MHS) duality between iAXp 's and iCXp 's was established in earlier work [Izza et al., 2024b].
Proposition 1. Given an explanation problem E, each iAXp (X , E) ∈ A(E) minimally "hits" each iCXp (Y, G) ∈ C(E) s.t. if feature i ∈ F is selected to "hit" iAXp (X, E) then Gi ∩ Ei = ∅, and vice versa.
Remark 1. As the previous two examples demonstrate, inflation of an AXp or a CXp can be done in multiple ways resulting in different inflated AXps or CXps, respectively. While many of those inflated explanations are valid, some may have a high degree of redundancy, which is often undesirable in practice. Therefore, the goal of explanation inflation is (i) to expand the intervals included in an iAXp as much as possible and (ii) to shrink the intervals included in an iCXp as much as possible, providing the most general way of (i) ensuring the prediction and (ii) breaking it, respectively. The above proposition establishes a duality between inflated AXps and CXps assuming they are inflated in the most sensible way, with no redundancy involved, hence the requirement Gi ∩ Ei = ∅.
Proposition 1 forms the foundation of the algorithm proposed in this work for computing a maximum size inflated abductive explanations inspired by the earlier work in the area of implicit hitting set enumeration [Davies and Bacchus, 2011; Ignatiev et al., 2015; Saikko et al., 2016].
2.3 SAT andMaxSAT
We assume standard definitions for propositional satisfiability (SAT) and maximum satisfiability (MaxSAT) solving [Biere et al., 2021]. The maximum satisfiability (MaxSAT) problem is to find a truth assignment that maximizes the number of satisfied propositional formulas in a clausal form (i.e. CNF formula). There are a number of variants of MaxSAT [Biere et al., 2021, Chapters 23 and 24]. We will be mostly interested in Partial Weighted MaxSAT, which can be formulated as follows. The input WCNF formula φ is of the form 〈H, S〉 where H is a set of hard clauses, which must be satisfied, and S is a set of soft clauses, each with a weight, which represent a preference to satisfy those clauses. Whenever convenient, a soft clause c with weight w will be denoted by (c, w). The Partial Weighted MaxSAT problem consists in finding an assignment that satisfies all the hard clauses and maximizes the sum of the weights of the satisfied soft clauses.
2.4 RelatedWork
Logic-based explanations of ML models have been studied since 2018 [Shih et al., 2018], with recent surveys summarizing the observed progress [Marques-Silva and Ignatiev, 2022; Marques-Silva, 2022; Darwiche, 2023; Marques-Silva, 2024]. However, the study of logic-explanations in AI can at least be traced to the late 1970s and 1980s [Swartout, 1977; Swartout, 1983; Shanahan, 1989].
Inflated explanations are more general explanations than AXps. This has been recognized in the earlier work in modelagnostic explainability (Anchor [Ribeiro et al., 2018]) and in the formal explainability [Izza et al., 2022; Ji and Darwiche, 2023; Yu et al., 2023a; Izza et al., 2023b; Izza et al., 2024b].
Implicit hitting-set algorithms have been used in a wide range of practical domains [Bailey and Stuckey, 2005; Chandrasekaran et al., 2011; Davies and Bacchus, 2011; Previti and Marques-Silva, 2013; Liffiton and Malik, 2013; Ignatiev et al., 2015; Liffiton et al., 2016; Saikko et al., 2016]. In the case of XAI, implicit hitting-set algorithms, mimicking MARCO [Liffiton et al., 2016], have been applied in the enumeration of abductive explanations [Marques-Silva, 2022]
but also for deciding feature relevancy [Huang et al., 2023]. Implicit hitting-set algorithms can be viewed as a variant of the general paradigm of counterexample-guided abstraction refinement (CEGAR), which was originally devised in the context of model-checking [Clarke et al., 2003].
Additional recent works on formal explainability for large scale ML models include [Wu et al., 2023; Bassan and Katz, 2023; Izza et al., 2024a; Izza and Marques-Silva, 2024]. Probabilistic explanations are investigated in [W¨aldchen et al., 2021; Izza et al., 2023a]. There exist proposals to account for constraints on the inputs [Gorji and Rubin, 2022; Yu et al., 2023c]. Moreover, formal feature attribution explanations are proposed in [Yu et al., 2023b; Biradar et al., 2024; Yu et al., 2024; L´etoff´e et al., 2025].
3 Tree Ensembles
General TEmodel. We propose a general model for a tree ensemble (TE) predictor. As shown below, the proposed model serves to represent boosted trees [Friedman, 2001], random forests with majority voting [Breiman, 2001], and random forests with weighted voting (Scikit-learn [Pedregosa and et al., 2011]).
A decision tree T on features F for classes K is a binarybranching rooted-tree whose internal nodes are labeled by split conditions which are predicates of the form xi < d for some feature i ∈ F and d ∈ Di, and leaf nodes labelled by a class c ∈ K. A path Rn to a leaf node n can be considered as the set of split conditions of nodes visited on the path from root to n.
A tree ensemble T has n decision trees, T1, . . . , Tn. Each path Rl in each decision tree Tt is assigned a class cl(l) (corresponding to the class of the leaf node it reaches) and a weight wl. Given a point v in feature space, and for each decision tree Tt, with 1 ≤ t ≤ n, there is a single path Rkv,t that is consistent with v in tree Tt. The index kv,t denotes which path of Tt is consistent with v.
For decision tree Tt, and given v, the picked class is denoted cl(kv,t) and the picked weight wkv,t . For each class c ∈ K, the class weight will be computed by,
Finally, the picked class is given by,
Boosted trees. In a boosted tree (BT), and given a point in feature space, class selection works as follows: each tree is pre-assigned a class c (all leaves have the same class c) and returns a weight; the weights of each class are summed up over all trees, and the class with the largest weight is picked.
Random forests with majority voting. In a random forest (RF) with majority voting (RFmv), and given a point in feature space, each decision tree picks a class; the final picked class is the one picked by most trees. Note that to represent an RFmv in our general TE model, we set the weights of the leaf nodes to 1.
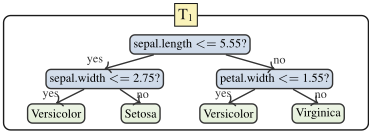
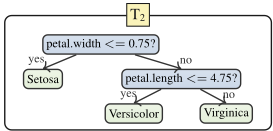
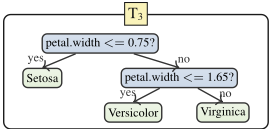
Example 3. Figure 1 shows an example of a RFmv of 3 trees, trained with Scikit-learn on Iris dataset. Consider a sample v = (6.0, 3.5, 1.4, 0.2) then the counts of votes for classes 13 are, resp., W(c1, v) = 2 (votes of T2 and T3), W(c2, v) = 1 (vote of T1), and W(c3, v) = 0. Hence, the predicted class is c1 ("Setosa") as it has the highest score.
Random forests with weighted voting. In an RF with weighted voting (RFwv), and given a point in feature space, each tree picks a weight for a chosen selected class; the final picked class is the class with the largest weight.
Explanation encoding for TEs. Recent advances have applied logic-based approaches to explain tree ensembles (BTs and RFs), where a primary challenge lies in reasoning efficiently over the aggregate output of a large ensemble of decision trees. Hereinafter, we build on the recent propositional encodings of RFs [Izza and Marques-Silva, 2021] and BTs [Ignatiev et al., 2022], which translate the ensemble voting to a SAT formula with cardinality constraints for RFmv or a set of MaxSAT queries expressing pseudo-Boolean constraints for BT.
Roughly, given a tree ensemble T defining classifier κ, for each feature i ∈ F we can define the set of split points Si ⊂ Di that appear for that feature in all trees, i.e. Si = {d | xi < d appears in some tree T1, . . . Tn}. Suppose [si,1, si,2, . . . , si,|Si|] are the split points in Si sorted in increasing order. Using this we can define set of disjoint intervals for feature i: I i1 ≡ [min(Di), si,1), I i2 ≡ [si,1, si,2), . . . , I i |Si|+1 ≡ [si,|Si|, max(Di)] where Di = I i1∪I i2∪· · ·∪I i |Si|+1 . Later, we utilize Boolean variables [[xi < d]], d ∈ Si for each feature i ∈ F. The key property of a TE is that ∀x ∈ I 1 e1 × I 2 e2 ×· · ·×I m em s.t. ei is defined as the interval index for feature i which includes the value of v, i.e. vi ∈ I iei , then we have κ(x) = κ(v) = c. That is we only need to reason about intervals rather than particular values to explain the behaviour of a tree ensemble. As a result, the AXp (resp. CXp) extraction boils down to finding a subset-minimal subset X ∈ F s.t. (1) holds (resp. (2) holds).
(A unified MaxSAT encoding of TE models - capturing RFwv, RFmv and BT - is outlined in [Izza et al., 2025].)
4 Most General Explanations
Let us assume a tree ensemble T and features i ∈ F are numerical. Hence, for each feature we obtain a set of intervals {I1, . . . , In} such that (⋃nj=1 Ij ) = Di. Assuming the domain Di is finite, we can define the proportion size of an interval Ij for feature i as propi(Ij) = |Ij|/|Di|. For infinite domains Di we treat its size as |Di| = max{vi | v ∈ T}-min{vi | v ∈ T} where T is the training set used to train the TE. We can alternatively define the data proportion size of an interval Ij for feature i as datai(Ij) = |{v∈T | vi∈Ij}|/|T| which give the proportion of the training data that appears in the interval. We can extend both size definitions to work on interval Ei for feature i in the natural manner: propi(Ei) = ∑Ij∈Ei propi(Ij), and datai(Ei) = ∑Ij∈Ei datai(Ij).
We can now compute the size of a region E covered by an inflated explanation (X, E) as either prop(E) = Πi∈Fpropi(Ei) or data(E) = Πi∈Fdatai(Ei). Either of these can be used to define the size measure s(E).
Note that in the context of explanation inflation, excluding a feature i ∈ F from an explanation (X , E) can be seen as either removing it from X or, equivalently, as setting Ei = Di. For this reason, hereinafter we denote iAXp's as (X, E) or E interchangeably. In order to compute maximal size explanations, it will be convenient to compute instead the logarithm of the size of an explanation, thus replacing product by sum. Namely, We define the feature space coverage of an explanation E, FSCs(E) as the log of the size of the explanation using size function s:
One key observation is that (5) assumes a uniform distribution over E. However, we emphasize that the (training) data distribution can be seamlessly incorporated into FSCs by weighting the interval scores Ei according to their probability distribution.
Maximum inflated explanation (Max-iAXp). Given an explanation problem (M, (v, c)) and a size metric s, a maximum inflated abductive explanation (X, E) defines the intervals for all the features i ∈ X, such that the following conditions hold,
In other words, (X , E) is a correct inflated AXp for the explanation problem E, and there is no other correct inflated AXp, which has a region E′ with a larger size under FSCs.
Implicit hitting dualization algorithm. We devise an algorithm inspired by the implicit hitting set dualization paradigm [Bailey and Stuckey, 2005; Chandrasekaran et al., 2011; Davies and Bacchus, 2011; Liffiton and Malik, 2013; Ignatiev et al., 2015; Saikko et al., 2016] for computing maximum inflated AXps. The idea is to use an oracle that searches for explanation candidates E and a second oracle that checks if E is an iAXp. The latter solver deals with the encoding of the prediction function of the TE and checks if (3) holds for the candidate E (in which case it is indeed an iAXp), and reports a counterexample otherwise. The former oracle, i.e., guessing candidate E, encodes a MaxSAT problem where the objective function to maximize is (5) and the hard constraints are representing the intervals Ei. Next, we will describe in detail the encoding that allows computing a minimum hitting set E of all iCXp's maximizing FSCs(E).
At each iteration of the algorithm, we obtain a range E where for each feature i, Ei ⊆ Di, Ei = ⋃l≤j≤u I i j ( s.t.
Algorithm 1 Computing maximum inflated AXp for TE
Input: Expl. prob. E = (M, (v, c)); WCNF 〈H, S〉
Output: One Max-iAXp (X , E)
1: repeat
- 2: (µ, s) ← MaxSAT(H, S)
- 3: E← {⋃l≤j≤u I i j | ∀(yi l,u ∈ S).µ(yi l,u ) = 1}
- 4: X ← {i ∈ F | |Ei| < |Di|}
- 5: hasCEx ←¬WiAXp(E;X, E)
- 6: if hasCEx = true then
7:
(Y, G) ← FindiCXp(E ; F , E)
- 8: H ← H ∪ newBlockCl(Y, G)
- 9: until hasCEx = false
10: return (X, E)
I i j ≡ [si,l, si,u) ) and vi ∈ Ei. We construct E and check if it is an iAXp, i.e. there is no adversarial example.
Observe that it is sufficient to show E is not a Weak iAXp to prove the existence of a CXp in E - (4) holds - by using any encoding of the TE to find a solution in x ∈ E where κ(x) ̸= c. This is achieved by fixing the Booleans of the TE encoding implied by the candidate explanation E, i.e. [[xi < d]] = ⊤ when d ≤ sup(Ei) and [[xi < d]] = ⊥ when d ≥ inf(Ei), and maximizing Sc,c′ for all c′ ̸= c. If we find a solution with Sc,c′ > 0 this is an adversarial example. If the oracle encoding the TE decides (3) to be false, that is it finds an adversarial example, then we reduce the adversarial example into a CXp Y ⊆ F (or inflated CXp (Y, G) and block it in the hitting set oracle such that the next candidate hits this CXp. Otherwise, the oracle reports (3) to be true, subsequently we conclude that E meets the conditions (6)-(7). Pseudo-code for the algorithm is shown in Algorithm 1.
A consequence of the MHS duality between iAXp's and iCXp's [Izza et al., 2024b] is that the checker oracle reports a new candidate to be an iAXp and the algorithm terminates before the hitting set oracle exhausts hitting sets to enumerate. Moreover, it is clear that the hitting set oracle finds the largest unblocked interval for each iteration that maximizes the score of the objective function FSCs(E). Also, note that at the first iteration, as the oracle does not know anything about the model (no blocked subdomains yet), it will cover all the feature space (all features are free). Finally, as a simple improvement of the approach, one can compute initially iCXp's of size 1 and block those adversarial regions at the beginning, before entering the hitting set enumeration loop.
Generally, as Algorithm 1 exploits the ideas of implicit hitting set dualization, it shares the worst-case exponential number of iterations with the rest of this paradigm's instantiations. Note that the number of iterations here grows exponentially not only with respect to the number of features as in the standard smallest-size AXp extraction [Ignatiev et al., 2019b; Ignatiev et al., 2020] but also on the feature domain size.
Naive MaxSAT encoding. What remains to explain is how we encode the candidate enumeration process as a MaxSAT problem 〈H, S〉, and how we create the blocking clauses.
We create Boolean variables yi l,u to represent the interval Ei = ∪l≤j≤uI i j . Note that we can restrict to cases where l ≤ ei ≤ u since any iAXp must include the interval of the example being explained ei for each feature i. Importantly, we can define the log of the weight of each interval wi l,u =
log(∑l≤j≤u s(I ik )). In order to use MaxSAT we need to fix the entire interval for feature i so that the resulting objective is a sum. Hence we generate O(|Si|2 ) Booleans for each feature i.
| Notation | Role |
|---|---|
| yi l,u [[Ei ̸⊇ I iai,bi ]] [[li ≥ si,j]] [[ui ≤ si,j]] | Boolean variable encoding an interval Ei = ∪l≤j≤uI i j of feature i Boolean variable to test if a sub-interval I iai,bi is (not) in Ei Boolean variable encoding the lower bound of an interval Ei Boolean variable encoding the upper bound of an interval Ei |
| wi l,u FSCs(E) | Denotes the weight of an interval Ei = ∪l≤j≤uI i j of feature i Explanation coverage function FSCs(E) = ∑i∈F wi l,u yi l,u to maximize |
The only hard clauses H of the MaxSAT model encode the cardinality constraints
enforcing that for each feature at most one interval covering the instance to be explained is selected. The soft clauses S of the MaxSat model are (yi l,u , wi l,u ), indicating our objective is to maximise ∑i∈F wi l,u yi l,u = FSCs(E).
Example 4. Consider the feature i = 4, petal.width of the RF of Figure 1, then S4 = {0.75, 1.55, 1.65} and we assume D4 = [0, 3]. This defines 4 intervals I 4 1 = [0, 0.75), I 4 2 = [0.75, 1.55), I 4 3 = [1.55, 1.65), I 4 4 = [1.65, 3]. If we are explaining the instance from Example 3 then the interval where the instance sits is e4 = 1 since petal.width = 0.2. We construct Booleans y4 1,1 , y4 1,2 , y4 1,3 , y4 1,4 representing E4 as one of [0, 0.75), [0, 1.55), [0, 1.65), [0, 3]. We require at most one y4 l,u to be true, and give them weights defined by the interval weight FSCs(I 4 l,u ).
A solution to the MaxSAT model assigns exactly one interval to each feature, thus defining a candidate explanation E. Optimality of the MaxSAT solution means it will be the candidate explanation of largest total size.
We use the TE MaxSAT model to determine if E include a counterexample. If this fails then E is an iAXp, and by the maximality of size it is the maximum inflated AXp. Otherwise, we have a counterexample which we need to exclude from future intervals.
Assume the TE model, given a candidate explanation E returns a counterexample, then we have a solution on the [[xi < d]] variables, falling within E where κ(w) ̸= c for all w which satisfy these bounds. We can extract a counterexample range G from the solution, where Gi = I iai,bi given by ai = max({j + 1 | j ∈ 1..|Si|, [[xi < si,j ]] = ⊥} ∪ {1}) and bi = min({j | j ∈ 1..|Si| | [[xi < si,j]] = ⊤} ∪ {|Si| + 1}). We now add clauses to the MaxSAT model to prevent selecting candidate explanations that would cover this adversarial example. Note that if ai ≤ ei ≤ bi then we cannot differentiate the counterexample from the instance being explained using feature i. Hence we want to express the constraint that Ei ̸⊇ I iai,bi for at least one i ∈ F where it is not the case that ai ≤ ei ≤ bi.
We can express the condition Ei ̸⊇ I iai,bi as the conjunction ∧l≤ai∧bi≤u ¬yi l,u , since we can no longer choose an interval, which covers the interval of the counterexample. The
"blocking clause" we add to the MaxSAT model is then the disjunction ∨i∈Y,¬(ai≤ei≤bi) ∧l≤ai∧bi≤u ¬yi l,u . To translate this into clausal form, we add auxiliary Boolean variables [[Ei ̸⊇ I iai,bi ]] and the clausal encoding of: [[Ei ̸⊇ I iai,bi ]] ↔ ∧l≤ai∧bi≤u ¬yi l,u and ∨i∈Y,¬(ai≤ei≤bi) [[Ei ̸⊇ I iai,bi ]] to the MaxSAT model.
Example 5. Suppose for explaining the instance of Example 3 we find counterexample G corresponding to sample w = (6.0, 3.5, 1.4, 0.8) which is predicted as Versicolor and only differs in the petal.width value. For this example [[x4 < 0.75]] = ⊥ and [[x4 < 1.55]] = ⊤, so G4 = I 4 2,2 . We enforce new variable [[E4 ̸⊇ I 4 2,2 ]] ↔ (¬y4 1,2 ∧¬y4 1,3 ∧¬y4 1,4 ), and add the blocking clause [[E4 ̸⊇ I 4 2,2 ]] forcing it to hold. We can no longer choose these intervals when searching for iAXp candidate E.
Note that we only add definitions for Booleans [[Ei ̸⊇ I iai,bi ]] on demand, that is when they occur in a counterexample. This prevents us creating a large initial model, where many of these auxiliary Booleans may never be required.
Bounds-based MaxSAT encoding. The above MaxSAT encoding creates large cardinality encodings (8), and may generate many Booleans of the form [[Ei ̸⊇ I iai,bi ]] in order to block counterexamples. We can do this much more succinctly using a bounds representation.
Here we introduce Boolean variables to represent the lower and upper bounds of the interval Ei: {[[li ≥ d]] | d ∈ Si, d ≤ min(I iei )} and {[[ui < d]] | d ∈ Si, d ≥ max(I iei )}. Note that we do not need to represent bounds which exclude the explained instance value for this feature i, vi. We add to H the implications [[li ≥ si,j+1]] → [[li ≥ si,j ]], 1 ≤ j < ei and [[ui < si,j ]] → [[ui < si,j+1]], ei ≤ j ≤ |Si|.
We define the interval variables yi l,u using clauses in H encoding
where [[li ≥ si,0]] and [[ui < si,|Si|+1]] are both treated as ⊤. We use the same soft clauses to define the objective as in the Naive encoding.
Example 6. Encoding feature petal.width we generate only the bounds [[u4 < 0.75]], [[u4 < 1.55]], [[u4 < 1.65]] and implications [[u4 < 0.75]] → [[u4 < 1.55]] and [[u4 < 1.55]] → [[u4 < 1.65]], and y4 1,1 ↔ [[u4 < 0.75]], y4 1,2 ↔ ¬[[u4 < 0.75]] ∧ [[u4 < 1.55]], y4 1,3 ↔ ¬[[u4 < 1.55]] ∧ [[u4 < 1.65]], and y4 1,4 ↔ ¬[[u4 < 1.65]].
If the test whether E is an iAXp fails, we are given an (inflated) CXp (Y,G). Adding a blocking clause to the bounds-based MaxSAT encoding is much simpler. Suppose Gi = I iai,bi where ei ̸∈ [ai, bi] then if ei < ai we can hit the iCXp for feature i by enforcing [[ui ≤ si,ai-1]], similarly if ei > bi we can hit the iCXp for feature i by enforcing [[li ≥ si,bi ]]. The blocking clause is the disjunction of these literals for all i ∈ F where ei ̸∈ [ai, bi].
Example 7. Given the same counter example as in Example 5 we have a4 = b4 = 2 and e4 = 1, so the blocking clause we add for the bounds model is simply [[u4 < 0.75]].
MIP encoding. We can easily rewrite the bounds based MaxSAT encoding to a mixed integer linear program (MIP model). All the Boolean variables become 0-1-integer variables. The implications become simple inequalities, e.g. [[li ≥ si,j+1]] → [[li ≥ si,j]] becomes [[li ≥ si,j+1]] ≤ [[li ≥ si,j]]. The definitions of the interval variables yi l,u become a series of inequalities where negation ¬l is modelled by 1 - l. For example the definition of yi l,u becomes
The objective in the MIP model is to maximize ∑i∈F,1≤l≤ei≤u≤|Si |+1 wi l,u · yi l,u , which is completely analogous to the MaxSAT encoding. The blocking clauses are also representable as a simple linear inequality.
5 Experiments
This section presents a summary of empirical assessment of computing maximum inflated abductive explanations for tree ensembles - the case study of RFmv and BT - trained on some of the widely studied datasets. Our evaluation aims to investigate the following research questions:
- RQ1: Are hypercubes representing Max-iAXp explanations much larger than iAXp's on real world benchmarks?
- RQ2: Are the proposed logical encodings scale for practical RFs and BTs?
- RQ3: Does our algorithm converge quickly to deliver the optimal explanation?
Experimental Setting. The experiments are conducted on Intel Core i5-10500 3.1GHz CPU with 16GByte RAM running Ubuntu 22.04 LTS. A time limit for each tested instance is fixed to 900 seconds (i.e. 15 minutes); whilst the memory limit is set to 4 GByte.
The assessment of TEs (RFs and BTs) is performed on a selection of publicly available datasets, which originate from UCI ML Repository [UCI, 2020] and Penn ML Benchmarks [Olson et al., 2017] - in total 12 datasets. Note that datasets are fully numerical as we are interested in assessing the proposed FSC coverage metric, which discriminate the intervals given their size. For categorical data, the FSC scores are the same for all domain values, then it is pointless in our empirical evaluation to include them. When training RFs, we used Scikit-learn [Pedregosa and et al., 2011] and for BTs we applied XGBoost [Chen and Guestrin, 2016].
The proposed approach is implemented in RFxpl 1 and XReason 2 Python packages. The PySAT toolkit [Ignatiev et al., 2018; Ignatiev et al., 2024] is used to instrument SAT or/and MaxSAT oracle calls. RC2 [Ignatiev et al., 2019a] MaxSAT solver, which is implemented in PySAT, is applied to all MaxSAT encodings (for the TE operation and hitting set dualization). Moreover, Gurobi [Gurobi Optimization, LLC, 2023] is applied to instrument MIP oracle calls using its Python interface.
1 https://github.com/izzayacine/RFxpl
2 https://github.com/alexeyignatiev/xreason
| Dataset | (m, K) | iAXp | Max-iAXp | Naive MxS | Bnd MxS | Bnd MIP | Cov. Ratio | |||||||||
|---|---|---|---|---|---|---|---|---|---|---|---|---|---|---|---|---|
| Len | Cov% | Time | Len | Cov% | calls | Timerc2 | TOrc2 | Timerc2 | TOrc2 | Timegrb | TOgrb | avg | max | |||
| ann-thyroid | (21 | 3) | 1.9 | 2.59 | 0.41 | 1.9 | 8.94 | 7.3 | 23.21 | 0 | 10.28 | 0 | 2.19 | 0 | 3.446 | 524.711 |
| appendicitis | (7 | 2) | 5.2 | 5.30 | 0.16 | 4.2 | 18.44 | 62.7 | 282.10 | 19 | 172.11 | 11 | 97.23 | 0 | 3.478 | 4676.519 |
| banknote | (4 | 2) | 2.3 | 11.84 | 0.12 | 2.2 | 24.11 | 8.3 | 428.67 | 13 | 266.35 | 1 | 20.98 | 0 | 2.037 | 786.040 |
| breast-cancer | (9 | 2) | 3.6 | 15.39 | 0.12 | 3.7 | 23.27 | 12.0 | 0.22 | 0 | 0.19 | 0 | 0.32 | 0 | 1.512 | 5.500 |
| bupa | (6 | 2) | 4.7 | 0.39 | 0.15 | 4.6 | 4.20 | 18.6 | 58.62 | 2 | 38.54 | 0 | 13.02 | 0 | 10.662 | 3128.349 |
| car | (6 | 4) | 1.6 | 52.42 | 0.21 | 1.6 | 53.61 | 1.9 | 0.14 | 0 | 0.21 | 0 | 0.14 | 0 | 1.023 | 4.167 |
| ecoli | (7 | 5) | 3.9 | 3.19 | 0.87 | 3.8 | 7.15 | 19.7 | 229.92 | 10 | 170.17 | 2 | 54.23 | 0 | 2.238 | 6350.058 |
| haberman | (3 | 2) | 1.6 | 6.54 | 0.08 | 1.7 | 8.70 | 5.0 | 0.46 | 0 | 0.41 | 0 | 0.89 | 0 | 1.330 | 11.011 |
| iris | (4 | 3) | 2.1 | 9.65 | 0.20 | 2.1 | 9.85 | 8.1 | 0.45 | 0 | 0.65 | 0 | 0.63 | 0 | 1.021 | 2.302 |
| lupus | (3 | 2) | 1.4 | 19.93 | 0.08 | 1.8 | 26.58 | 6.4 | 5.99 | 0 | 0.69 | 0 | 0.94 | 0 | 1.334 | 114.821 |
| new-thyroid | (3 | 2) | 3.1 | 9.98 | 0.28 | 3.2 | 12.62 | 16.6 | 199.28 | 2 | 26.35 | 0 | 8.56 | 0 | 1.263 | 6048.512 |
| wine-recog | (13 | 3) | 11.2 | 1.51 | 0.27 | 4.3 | 3.49 | 140.7 | 88.03 | 22 | 366.51 | 20 | 196.06 | 0 | 2.318 | 364.379 |
RQ1. Table 2 shows the coverage size of Max-iAXp and baseline iAXp explanations, for the case study of RFmv tree ensembles. For a more fine-grained evaluation, we compare the scalability of the proposed logical encodings, i.e. naive and bound-based MaxSAT encodings as well as MIP encoding in Table 2. As can be observed from Table 2, the average domain coverage of Max-iAXp's is at least twice and up to 10 times, larger than the average coverage of iAXp's for a half of datasets while it is fairly superior for the remaining datasets.
Interestingly, we observe that the maximum ratio between feature space coverage offered by Max-iAXp and iAXp can be extremely high for the majority of benchmarks (e.g. 3128 to 6048 times wider in appendicitis, ecoli, bupa and newthyroid) with a few exceptions on smaller datasets (e.g. breast-cancer, car and iris, resp. showing a ratio of 5.5, 4.1 and 2.3). Furthermore, the average lengths of iAXp and MaxiAXp remain consistently close, even when there is a large gap in coverage scores, and very succinct w.r.t. input data (e.g. ∼ 6.6% in ann-thyroid).
RQ2 & RQ3. Performance-wise, we observe a substantial advantage of MIP oracle (Gurobi) over MaxSAT (RC2) despite the fact they use essentially the same formulation of the problem. Although there may be various reasons for this phenomenon, the hitting set problem seems to be more amenable to MIP solvers as they can take advantage of multiple efficient optimization procedures, including linear relaxation, branchand-bound methods augmented with cutting planes resolution as well as both primal and dual reasoning. On the contrary, RC2 is a core-guided MaxSAT solver designed to handle optimization problems that are inherently Boolean, which is the case for the TE encoding we used in our work where RC2 shines. As the results demonstrate, our approach empowered with Gurobi is able to deliver explanations within ∼33 sec for the average runtime for all the considered datasets (and a min. (resp. max.) of 0.14 sec (∼3 min)), and able to terminate on all tests, whilst RC2 gets timed out on 4 datasets (particularly for wine-recog in 20 out of 25 instances).
Although computing iAXp's in general tends to be faster than Max-iAXp (which is not surprising), applying our approach to computing Max-iAXp is worthwhile when most general explanations are of concern. This is underscored by the fact that the approach is shown to scale. Finally, the improved bounds-based variant of the approach (both with MaxSAT and MIP) is clearly superior to the naive propositional encoding in terms of the overall performance.
| Dataset | iAXp | Max-iAXp | Cov. Ratio | ||||
|---|---|---|---|---|---|---|---|
| Cov% | Time | Cov% | calls | Timegrb | avg | max | |
| ann-thyroid | 1.34 | 0.27 | 17.77 | 2.0 | 1.56 | 13.27 | 59.4 |
| appendicitis | 6.59 | 0.09 | 24.26 | 10.4 | 0.90 | 3.68 | 587.7 |
| banknote | 18.21 | 1.13 | 21.33 | 5.5 | 15.86 | 1.17 | 22.3 |
| breast-cancer | 0.38 | 1.14 | 2.21 | 17.9 | 10.61 | 5.81 | 131.6 |
| bupa | 0.49 | 1.26 | 2.78 | 20.6 | 18.92 | 5.63 | 98379.4 |
| car | 26.54 | 0.14 | 26.91 | 2.2 | 0.18 | 1.01 | 22.5 |
| ecoli | 2.92 | 6.88 | 5.29 | 17.8 | 83.84 | 1.81 | 743.8 |
| haberman | 1.40 | 0.56 | 2.71 | 6.0 | 3.30 | 1.93 | 36.2 |
| iris | 20.63 | 0.13 | 22.29 | 3.2 | 0.38 | 1.08 | 22.5 |
| lupus | 16.56 | 0.07 | 19.47 | 3.6 | 0.28 | 1.18 | 7.7 |
| new-thyroid | 4.63 | 0.41 | 7.39 | 9.7 | 2.73 | 1.60 | 246.7 |
| wine-recog | 6.18 | 0.26 | 14.02 | 16.1 | 3.80 | 2.27 | 212.8 |
Table 3 reports the results of Max-iAXp for BTs focusing solely on MIP encoding. Similarly to RFs, we observe large Max-iAXp explanation coverage for most of the benchmarks, where 8/12 datasets show 12% to 53% coverage of the total input space. Additionally, we observe a net superiority of average coverage of Max-iAXp over iAXp with a factor of 2 up to 13 for 5/12 datasets. Overall, these empirical results validate the effectiveness and explanatory wide-ranging of our framework in explaining TEs.
6 Conclusions
This paper takes a step further in the quest of finding most succinct and general explanations for (complex) ML models. This is achieved by formalizing the concept of maximum inflated abductive explanation (Max-iAXp), which can be considered as the most general abductive explanations. Furthermore, the paper proposes an elegant approach for the rigorous computation of maximum inflated explanations, and demonstrates the broader coverage of such explanations in comparison with maximal (subset) inflated abductive explanations. The experimental results validate the practical interest of computing maximum iAXp explanations.
Acknowledgments
This work was supported in part by the National Research Foundation, Prime Minister's Office, Singapore under its Campus for Research Excellence and Technological Enterprise (CREATE) programme, by the Spanish Government under grant PID2023-152814OB-I00 and ICREA starting funds, and by the Australian Research Council through the OPTIMA ITTC IC200100009.
Finally, we thank Rayman Tang for the discussions at an early stage of this work and the reviewers for their constructive feedbacks.
@inproceedings{ijcai2025p608,
  title     = {Most General Explanations of Tree Ensembles},
  author    = {Izza, Yacine and Ignatiev, Akexey and Rubin, Sasha and Marques-Silva, Joao and Stuckey, Peter J.},
  booktitle = {Proceedings of the Thirty-Fourth International Joint Conference on
               Artificial Intelligence, {IJCAI-25}},
  publisher = {International Joint Conferences on Artificial Intelligence Organization},
  editor    = {James Kwok},
  pages     = {5463--5471},
  year      = {2025},
  month     = {8},
  note      = {Main Track},
  doi       = {10.24963/ijcai.2025/608},
  url       = {https://doi.org/10.24963/ijcai.2025/608},
}
TY - CPAPER TI - Most General Explanations of Tree Ensembles AU - Izza, Yacine AU - Ignatiev, Akexey AU - Rubin, Sasha AU - Marques-Silva, Joao AU - Stuckey, Peter J. T2 - Proceedings of the Thirty-Fourth International Joint Conference on Artificial Intelligence, IJCAI-25 PB - International Joint Conferences on Artificial Intelligence Organization PY - 2025 SP - 5463 EP - 5471 DO - 10.24963/ijcai.2025/608 UR - https://doi.org/10.24963/ijcai.2025/608 ER -Copied
Machine-readable versions of this paper, for tools and AI agents:





