
Declaration-based Prompt Tuning for Visual Question Answering
Proceedings of the Thirty-First International Joint Conference on Artificial Intelligence. Main Track. Pages 3264-3270.
https://doi.org/10.24963/ijcai.2022/453
Keywords
- Computer Vision: Transfer, low-shot, semi- and un- supervised learning
- Computer Vision: Vision and language
- Machine Learning: Multi-modal learning
- Natural Language Processing: Question Answering
Abstract
In recent years, the pre-training-then-fine-tuning paradigm has yielded immense success on a wide spectrum of cross-modal tasks, such as visual question answering (VQA), in which a visual-language (VL) model is first optimized via self-supervised task objectives, e.g., masked language modeling (MLM) and image-text matching (ITM), and then fine-tuned to adapt to downstream task (e.g., VQA) via a brand-new objective function, e.g., answer prediction. However, the inconsistency of the objective forms not only severely limits the generalization of pre-trained VL models to downstream tasks, but also requires a large amount of labeled data for fine-tuning. To alleviate the problem, we propose an innovative VL fine-tuning paradigm (named Declaration-based Prompt Tuning, abbreviated as DPT), which fine-tunes the model for downstream VQA using the pre-training objectives, boosting the effective adaptation of pre-trained
models to the downstream task. Specifically, DPT reformulates the VQA task via (1) textual adaptation, which converts the given questions into declarative sentence form for prompt-tuning, and (2) task adaptation, which optimizes the objective function of VQA problem in the manner of pre-training phase. Experimental results on GQA dataset show that DPT outperforms the fine-tuned counterpart by a large margin regarding accuracy in both fully-supervised (2.68%) and zero-shot/fewshot (over 31%) settings. All the data and codes will be available to facilitate future research.
- [Agrawal et al., 2015] Aishwarya Agrawal, Jiasen Lu, Stanislaw Antol, Margaret Mitchell, C. Lawrence Zitnick, Devi Parikh, and Dhruv Batra. Vqa: Visual question answering. IJCV, pages 4-31, 2015.
- [Chen et al., 2020] Yen-Chun Chen, Linjie Li, Licheng Yu, Ahmed El Kholy, Faisal Ahmed, Zhe Gan, Yu Cheng, and Jingjing Liu. Uniter: Universal image-text representation learning. In ECCV, pages 104-120. Springer, 2020.
- [Chen et al., 2021] Wenhu Chen, Zhe Gan, Linjie Li, Yu Cheng, William Wang, and Jingjing Liu. Meta mod- ule network for compositional visual reasoning. In WACV, pages 655-664, 2021.
- [Cheng et al., 2020] Ling Cheng, Wei Wei, Xianling Mao, Yong Liu, and Chunyan Miao. Stack-vs: Stacked visual- semantic attention for image caption generation. IEEE Ac- cess, 8:154953-154965, 2020.
- [Cho et al., 2021] Jaemin Cho, Jie Lei, Hao Tan, and Mohit Bansal. Unifying vision-and-language tasks via text gen- eration. In ICML, pages 1931-1942, 2021.
- [Devlin et al., 2018] Jacob Devlin, Ming-Wei Chang, Ken- ton Lee, and Kristina Toutanova. Bert: Pre-training of deep bidirectional transformers for language understand- ing. arXiv preprint arXiv:1810.04805, 2018.
- [Gan et al., 2020] Zhe Gan, Yen-Chun Chen, Linjie Li, Chen Zhu, Yu Cheng, and Jingjing Liu. Large-scale adversarial training for vision-and-language representation learning. NIPS, pages 6616-6628, 2020.
- [Hudson and Manning, 2019a] Drew A Hudson and Christo- pher D Manning. Gqa: A new dataset for real-world vi- sual reasoning and compositional question answering. In CVPR, pages 6700-6709, 2019.
- [Hudson and Manning, 2019b] Drew A Hudson and Christo- pher D Manning. Learning by abstraction: the neural state machine. In NIPS, pages 5903-5916, 2019.
- [Jin et al., 2021] Woojeong Jin, Yu Cheng, Yelong Shen, Weizhu Chen, and Xiang Ren. A good prompt is worth millions of parameters? low-resource prompt- based learning for vision-language models. arXiv preprint arXiv:2110.08484, 2021.
- [Kamath et al., 2021] Aishwarya Kamath, Mannat Singh, Yann LeCun, Gabriel Synnaeve, Ishan Misra, and Nicolas Carion. Mdetr-modulated detection for end-to-end multi- modal understanding. In ICCV, pages 1780-1790, 2021.
- [Kim et al., 2021] Wonjae Kim, Bokyung Son, and Ildoo Kim. Vilt: Vision-and-language transformer without con- volution or region supervision. In ICML, pages 5583- 5594, 2021.
- [Li et al., 2020] Xiujun Li, Xi Yin, Chunyuan Li, Pengchuan Zhang, Xiaowei Hu, Lei Zhang, Lijuan Wang, Houdong Hu, Li Dong, Furu Wei, et al. Oscar: Object-semantics aligned pre-training for vision-language tasks. In ECCV, pages 121-137, 2020.
- [Liu et al., 2021a] Daizong Liu, Shuangjie Xu, Xiao-Yang Liu, Zichuan Xu, Wei Wei, and Pan Zhou. Spatiotemporal graph neural network based mask reconstruction for video object segmentation. In AAAI, pages 2100-2108, 2021.
- [Liu et al., 2021b] Pengfei Liu, Weizhe Yuan, Jinlan Fu, Zhengbao Jiang, Hiroaki Hayashi, and Graham Neubig. Pre-train, prompt, and predict: A systematic survey of prompting methods in natural language processing. arXiv preprint arXiv:2107.13586, 2021.
- [Lu et al., 2019] Jiasen Lu, Dhruv Batra, Devi Parikh, and Stefan Lee. Vilbert: pretraining task-agnostic visiolinguis- tic representations for vision-and-language tasks. In NIPS, pages 13-23, 2019.
- [Radford et al., 2021] Alec Radford, Jong Wook Kim, Chris Hallacy, Aditya Ramesh, Gabriel Goh, Sandhini Agar- wal, Girish Sastry, Amanda Askell, Pamela Mishkin, Jack Clark, et al. Learning transferable visual models from nat- ural language supervision. In ICML, pages 8748-8763, 2021.
- [Raffel et al., 2019] Colin Raffel, Noam Shazeer, Adam Roberts, Katherine Lee, Sharan Narang, Michael Matena, Yanqi Zhou, Wei Li, and Peter J Liu. Exploring the limits of transfer learning with a unified text-to-text transformer. arXiv preprint arXiv:1910.10683, 2019.
- [Su et al., 2019] Weijie Su, Xizhou Zhu, Yue Cao, Bin Li, Lewei Lu, Furu Wei, and Jifeng Dai. Vl-bert: Pre-training of generic visual-linguistic representations. arXiv preprint arXiv:1908.08530, 2019.
- [Tan and Bansal, 2019] Hao Tan and Mohit Bansal. Lxmert: Learning cross-modality encoder representations from transformers. In EMNLP-IJCNLP, pages 5100-5111, 2019.
- [Tsimpoukelli et al., 2021] Maria Tsimpoukelli, Jacob L Menick, Serkan Cabi, SM Eslami, Oriol Vinyals, and Felix Hill. Multimodal few-shot learning with frozen language models. NIPS, 34:200-212, 2021.
- [Vaswani et al., 2017] Ashish Vaswani, Noam Shazeer, Niki Parmar, Jakob Uszkoreit, Llion Jones, Aidan N Gomez, Łukasz Kaiser, and Illia Polosukhin. Attention is all you need. In NIPS, pages 6000-6010, 2017.
- [Yao et al., 2021] Yuan Yao, Ao Zhang, Zhengyan Zhang, Zhiyuan Liu, Tat-Seng Chua, and Maosong Sun. Cpt: Col- orful prompt tuning for pre-trained vision-language mod- els. arXiv preprint arXiv:2109.11797, 2021.
- [Zhang et al., 2021] Pengchuan Zhang, Xiujun Li, Xiaowei Hu, Jianwei Yang, Lei Zhang, Lijuan Wang, Yejin Choi, and Jianfeng Gao. Vinvl: Revisiting visual representa- tions in vision-language models. CVPR, pages 5575-5584, 2021.
- [Zhou et al., 2021] Kaiyang Zhou, Jingkang Yang, Chen Change Loy, and Ziwei Liu. Learning to prompt for vision-language models. arXiv preprint arXiv:2109.01134, 2021.
References were extracted automatically from the PDF and may contain errors.
Full text extracted automatically from the PDF; figures, tables and equations may differ. The PDF is the version of record.
1 Introduction
Recently, large-scale vision-language pre-training has been an emerging topic in the multi-modal community, and delivered strong performance in numerous vision-language tasks [Yao et al., 2021; Li et al., 2020; Zhang et al., 2021; Chen et al., 2020; Lu et al., 2019; Su et al., 2019]. Typically, a commonly-used practice is to follow the pre-training-thenfine-tuning paradigm [Liu et al., 2021b], in which a generic Transformer [Vaswani et al., 2017] is pre-trained on largescale image-text datasets in a self-supervised manner, and then adapted to different downstream tasks by introducing additional parameters and fine-tuning using task-specific objectives, e.g., auxiliary fully-connected layer for answer classification in visual question answering. This paradigm has greatly pushed forward the state-of-the-art of VQA task.
∗Corresponding author.
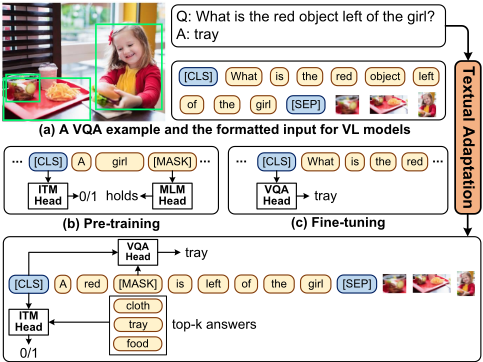
Figure 1: Illustration of (a) a VQA example and the formatted input for VL models, (b) pre-training VL models with masked language model (MLM) and image-text matching (ITM) tasks, (c) vanilla finetuning for VQA with a new classification head, and (d) our proposed declaration-based prompt tuning (DPT) framework that reformulates VQA task into fill-in-the-blank and image-text matching problems via textual and task adaptation. Only parts of the relevant image regions are shown for illustration.
Despite the promising performance achieved, it's worth noting that there exists a natural gap in objective forms between pre-training and fine-tuning stages. As illustrated by Figure 1(b-c), most VL models are pre-trained via masked language modeling and image-text matching objectives, i.e., recovering the masked token on the cross-modal contexts and predicting the matching scores of image-text pairs. However, in the fine-tuning stage, VQA problem is usually conducted and optimized using a brand-new task objective, i.e., classifying [CLS] token into the semantic labels (i.e., answers), where additional parameters are typically introduced. As a result, there exist great disparities in the task forms between pre-training and fine-tuning. This gap hinders the generalization of pre-trained VL models to downstream VQA task, which leads to suboptimal performance and a demand for large amount of labeled data for fine-tuning.
Inspired by the recent progress of vision-language pretrained models (VL-PTM) [Li et al., 2020; Zhang et al., 2021] and prompt tuning paradigms in cross-modal domain [Yao et al., 2021; Tsimpoukelli et al., 2021; Radford et al., 2021], in this paper we propose Declaration-based Prompt Tuning (DPT), a novel paradigm of fine-tuning VL-PTM for VQA problem. Our core insight is to reformulate the objective form of downstream VQA task into the format of pre-training phase, maximally mitigating the gap between two stages. To achieve this goal, we reformulate the VQA task from two aspects (refer to Figure 1(d)): (1) textual adaptation that converts the textual input (i.e., questions) into declarative sentence form, and (2) task adaptation that solves VQA by recovering the masked token from the declarative sentences, and selecting the one that best matches the image. In this way, answer prediction can be achieved via cloze-filling and image-text matching, imitating the behavior of MLM and ITM tasks in the pre-training phase.
By mitigating the gap between pre-training and finetuning, DPT enables strong performance over various VL models and VQA datasets in both fully-supervised and zero/few-shot settings. For example, with respect to the accuracy, our method achieves 2.68% absolute improvement in the fully-supervised setting, and 31.8%∼37.4% absolute improvement in the zero-shot/few-shot settings in GQA evaluation. Furthermore, the generalization experiment on VQA v2.0 equipped with recently proposed VL models shows 0.45%∼1.01% absolute improvement compared to the vanilla fine-tuning approach.
In summary, the main contributions are the following,
- We introduce Declaration-based Prompt Tuning (DPT), a novel fine-tuning paradigm that solves VQA via adapting downstream problem to pre-training task format. To the best of our knowledge, this is the first attempt in the prompt tuning using declaration sentences for visual question answering.
- We propose novel textual and task adaptation approaches to reformulate VQA into cloze-filling and image-text matching problems, i.e., MLM and ITM. The adapted tasks significantly outperform the fine-tuning counterparts in fully-supervised and few-shot settings.
- We conduct comprehensive experiments over various VL-PTMs and VQA datasets, which demonstrates the effectiveness and generalizability of DPT.
2 RelatedWork
2.1 Pre-trained Vision-language Models
Recently, there exists numerous work on training generic models for various downstream cross-modal tasks [Liu et al., 2021a], such as visual question answering (VQA) or image caption [Cho et al., 2021; Radford et al., 2021; Kim et al.,
2021; Zhang et al., 2021; Li et al., 2020; Cheng et al., 2020; Tan and Bansal, 2019]. Typically, a commonly-used practice is to follow a paradigm from model pre-training to model fine-tuning. In specific, in pre-training stage, a BERTlike architecture [Devlin et al., 2018] is first built for pretraining in learning multi-modal representations via a variety of self-supervised tasks, for instance, a mask language model (MLM) task of recovering the masked textual tokens in the multi-modal context [Tan and Bansal, 2019; Li et al., 2020], or an image-text matching (ITM) task to verify the alignment of an image to a given text [Tan and Bansal, 2019; Zhang et al., 2021]. Next, in the fine-tuning stage, the pretrained model is then fine-tuned to adapt to downstream tasks using totally different task-specific objectives, such as predicting the answer for the VQA task. In this work, instead of optimizing brand-new task objectives in the fine-tune stage, we attempt to reformulate VQA into the pre-training format, boosting the effective generalization of pre-trained VL models to the downstream task.
2.2 Cross-modal Prompt Tuning
Recently, prompt tuning has increasingly received attentions due to its powerful capability in keeping the optimization objectives of the pre-trained model and the downstream task consistent [Liu et al., 2021b; Radford et al., 2021; Yao et al., 2021; Tsimpoukelli et al., 2021], which enables pretrained models generalize to downstream tasks with few/zero samples for fine-tuning. Indeed, there already exist many attempts on this topic, for example, [Radford et al., 2021; Zhou et al., 2021] make use of crafted templates and learnable continuous representations to reformulate the objective forms of downstream tasks. [Cho et al., 2021; Jin et al., 2021; Tsimpoukelli et al., 2021] take account of utilizing an unified text generation framework to uniformly optimize with autoregressive objective. However, the fixed templates or predefined unified generation paradigm may be inadequacy in designing a suitable prompt model owing to the complex semantics in the given questions. To overcome the problem, in this paper we propose an innovative declaration-based prompt model, which exploits question-adaptive declarative sentence as prompt template so that the textual format for VQA task is more consistent with the pre-training phase, diminishing the textual gap between pre-train and fine-tune stages.
3 Methodology
In the following sections, we first present the problem statement of the VQA task (Section 3.1). Then, we describe our proposed DPT method (Section 3.2). The overall framework is depicted in Figure 2. Specifically, the image and question are converted into the input form and fed to the pre-trained VL model for multi-modal fusion, in which the declaration is typically introduced for prompt tuning. After that, the outputs of the model are exploited to perform the adapted MLM and ITM tasks for model fine-tuning and deciding the answer.
3.1 Preliminary
In this paper, we follow the problem definition in [Agrawal et al., 2015], and thus the VQA problem is formulated as a multi-class classification problem. Formally, the VQA task aims to select a correct answer a from a candidate answer set when given an image I and a question Q. To this end, we present the classical paradigm for VQA, namely, pretraining-then-fine-tuning paradigm.
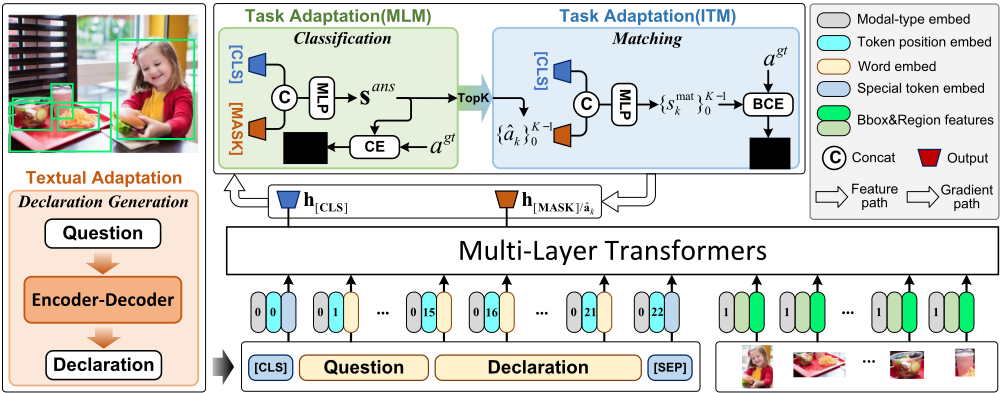
Pre-training-then-fine-tuning paradigm. Given a generic architecture, e.g., Transformer, the model is first pretrained on large-scale image-text corpus via manually designed self-supervised tasks, e.g., MLM and ITM. To this end, a set of region proposals extracted from the image I, {o1, o2, ..., on} and word embeddings of the question Q, {e1, e2, ..., em} are converted to the input format, i.e., {e[CLS], e1, e2, ..., em, e[SEP], o1, o2, ..., on}, which is fed to the model and fused to produce the hidden representations {hi}m+n+2 i=0 , where e[CLS], e[SEP] are embeddings of special tokens. The model is further optimized using self-supervised objectives. Then, in the fine-tuning stage for VQA task, the output [CLS] is exploited to performmulti-class classification and optimized via cross-entropy loss. This paradigm introduces a brand-new task for fine-tuning, which requires a large amount of labeled data to generalize in downstream task.
3.2 Declaration-based Prompt Tuning
To facilitate the generalization of pre-trained VL models to downstream VQA tasks, we propose a declaration-based prompt tuning (DPT) paradigm that reformulates VQA into pre-training task format. As illustrated in Figure 1(b-d), there exist two challenges, i.e., different forms of textual input (question vs. declaration) and different task objectives (MLM&ITM vs. answer classification). To address these issues, we present (1) Textual Adaptation module to convert questions into their corresponding declarative sentences, and (2) Task Adaptation module to reformulate answer prediction into MLM and ITM tasks. The two adapted tasks are combined to decide the final answer.
Textual Adaptation via Declaration Generation
Textual adaptation aims to convert the textual input (i.e., questions) into the pre-training form (i.e., declarative sentences), e.g., the declaration form of "What is the red object left of the girl?" is "A red [MASK] is left of the girl.". To this end, we introduce declaration generation which formulates this procedure as a translation problem, where the source and target texts are question and corresponding declaration, respectively. Formally, we first construct a declaration dataset using the annotations from GQA dataset [Hudson and Manning, 2019a], where the "fullAnswer" is regarded as the declaration and the short answer word/phrase in "fullAnswer" is replaced with a [MASK] token. Then, an encoderdecoder network (T5 [Raffel et al., 2019]) is trained on this dataset and optimized using the standard auto-regressive cross-entropy loss. Finally, the model can be used to convert questions into declarative sentences for various VQA datasets, e.g., GQA [Hudson and Manning, 2019a] and VQA [Agrawal et al., 2015]. More details are provided in Section 4.1 and Appendix.
Task Adaptation
Equipped with declarative sentences, VQA can be reformulated into pre-training task format, i.e., MLM and ITM. The adaptations mainly involve two aspects: textual input format and task objectives. Specifically, MLM reserves a [MASK] token in the textual input, and predicts the answer via multiclass classification. ITM replaces [MASK] with the topk candidate answers predicted from MLM, and predicts the matching scores using binary classification.
Adaptation toMLMtask. To reformulateVQA intoMLM task, the question and declaration sentence are concatenated to form as the textual input:
where T MLM represents the conversion function that converts the question Q to the input format. D denotes the declaration sentence. In Equation (1), we reserve the question in the textual input, because we find declaration sentence alone drops performance due to the lack of reasoning contexts (refer to Appendix for details). It's worth noting that D reserves a [MASK] token, e.g., a red [MASK] is left of the girl. In this way, the model is prompted to decide the token to fill in the mask, which exactly indicates the answer word/phrase.
On the basis of the adapted textual input, a pre-trained VL model is exploited to fuse the text and image features, producing a set of hidden representations. The outputs from [CLS] and [MASK] tokens (i.e., h[CLS] and h[MASK]) are concatenated to predict the answer:
where sans ∈ R|C| denotes the scores over the answer set C. The model is optimized using cross-entropy loss, defined as:
where agt is the ground-truth answer. D denotes the VQA dataset.
Adaptation to ITM task. To reformulate VQA into ITM task, the [MASK] token in the declaration sentence D is replaced by the top-k answers {ˆa0, ˆa1, ..., ˆaK-1} predicted from Equation (2), resulting in K candidate declarations:
Based on the candidates, the textual input can be formed via concatenation of the question Q and the declaration sentence Dans k , defined as follows:
where T ITM represents the conversion function. Dans k denotes the declaration sentence, in which the [MASK] token is replaced by the k-th candidate answer ˆak, e.g., a red tray/food/cloth is left of the girl.
In this way, pre-trained VL models are prompted to determine whether the image-text is matched. To achieve this, the image and textual inputs are fed to the VL model, and the outputs from [CLS] and answer token (i.e., h[CLS] and hˆak ) are concatenated to predict the matching score:
where smat k denotes the matching score of the image and the k-th candidate answer. Intuitively, the image-text pair with ground-truth answer should have higher matching score. Therefore, the model is optimized using binary cross-entropy loss, defined as follows:
where I[x] : X → {0, 1} denotes the indicator function, which takes value 1 if x is positive and zero otherwise.
Training and inference. On the top of task adaptation, VQA has been reformulated into MLM and ITM problems. During training, we integrate the loss terms from Eq. (4) and (9) to fine-tune VL models. The total loss of DPT is defined as:
During inference, the normalized scores predicted by MLM and ITM are combined via simple summation, and the answer ˆa with the highest score is chosen as the final prediction result, defined as follows:
Zero-shot and few-shot learning. Equipped with DPT, previous pre-trained VL models can also be easily transformed for zero-shot or few-shot learning based VQA tasks, only if reformulating Equation (2) and (7) into the same form as the one in pre-trained phrase, and is initialized with the pre-trained weights, which can be rewritten as follows,
where MLPpt ∗ denotes the MLP layer initialized with pretrained weights. Since the number of answers is less than that of vocabulary tokens, only the weights corresponding to answer words are taken to initialize MLPptMLM .
4 Experiments
4.1 Implementation Details
Datasets. GQA [Hudson and Manning, 2019a] and VQA v2.0 [Agrawal et al., 2015] are used to build declaration generation dataset and evaluate our proposed methods on VQA task. More details are provided in the Appendix.
Model training. T5-small [Raffel et al., 2019] is chosen for declaration generation. As for VQA, VinVL [Zhang et al., 2021] is selected as our base architecture. Our proposed DPT is applied to VinVL via textual and task adaptation. The model is fine-tuned using the adapted task objectives, resulting in two variants regarding the tasks for training, i.e., DPT(MLM) and DPT(MLM&ITM). The number of answers used for ITM K is set to 8. For fair comparison, we follow the same training settings as reported in the previous works in the following experiments. The details of hyper-parameters are reported in Appendix.
4.2 Experimental Results
For online evaluation of GQA dataset, we compare our method with the state-of-the-art models, including nonpretrained models i.e., MMN [Chen et al., 2021], NSM [Hudson and Manning, 2019b], and pre-trained VL models i.e., LXMERT [Tan and Bansal, 2019], VILLA [Gan et al., 2020], OSCAR [Li et al., 2020], VinVL [Zhang et al., 2021], MDETR [Kamath et al., 2021], VL-T5 [Cho et al., 2021]. The results are reported in Table 1. When only exploiting balanced split for training, our method achieves 63.55%
| Accuracy (%) | |||
|---|---|---|---|
| Method | Pre-trained | Test-dev | Test-std |
| MMN [2021] | � | - - | 60.83 |
| NSM [2019b] | � | 63.17 60.33 | |
| LXMERT [2019] | 60.00 | ||
| VILLA [2020] | 60.98 | 61.12 | |
| OSCAR [2020] | 61.58 | 61.62 | |
| VL-T5 [2021] | - | 60.80 | |
| MDETR [2021] | 62.95 | 62.45 | |
| VinVL†bal [2021] | 60.76 | 60.89 | |
| VinVL [2021] | 65.05 | 64.65 | |
| DPTbal | � | 63.55 | 63.57 |
| DPT | 65.20 | 64.92 | |
| Accuracy (%) | ||||
|---|---|---|---|---|
| Prompt | Output | Task | GQA | VQA |
| Base | [C] | Baseline | 60.26 | 74.05 |
| Fixed | [C]&[M] | MLM | 60.88 | 74.30 |
| Dynamic | [C]&[M] | MLM | 62.09 | 74.39 |
| Declare | [M] | MLM | 60.03 | 73.90 |
| [C]&[M] | MLM | 62.71 | 74.39 | |
| [C]&[M] | MLM&ITM | 63.13 | 74.50 | |
and 63.57% overall accuracy on test-dev and test-std, respectively, outperforming the state-of-the-art non-pretrained/pretrained models. Specifically, our method (DPTbal) surpasses the fine-tuned counterpart (VinVLbal) by a significant margin of 2.68% on test-std. When using all split to bootstrap our model similar to [Chen et al., 2021; Zhang et al., 2021], our method (DPT) still ranks the top regarding overall accuracy, and outperforms the counterpart (VinVL) by 0.27% on test-std. Among the compared models, MMN and NSM also achieve competitive results even if no pre-training is performed, which is thanks to the usage of deliberately generated scene graphs or supervision of execution programs.
4.3 Ablation Study
For a deeper understanding of DPT, we further conduct the ablation studies on the local validation split of GQA and VQA v2.0 datasets (textdev on GQA and val on VQA v2.0).
Different prompts. To illustrate the effectiveness of declarative sentences for prompt tuning, several prompt variants are proposed for comparison in Table 2, defined as follows:
- Base: Vanilla fine-tuning VinVL [Zhang et al., 2021] without prompt.
- Fixed: "Answer: [MASK]".
- Dynamic: "Answer: [V1] [V2] ... [V16] [MASK]".
- Declare (Ours): "Answer: [DECLARATION]".
| Model | Task | Accuracy (%) | ∆ (%) |
|---|---|---|---|
| VinVL[2021] | Baseline MLM MLM&ITM | 74.05 74.39 74.50 | 0.00 0.34 0.45 |
| ViLT[2021] | Baseline MLM MLM&ITM | 70.71 71.01 71.17 | 0.00 0.30 0.46 |
| UNITER[2020] | Baseline MLM MLM&ITM | 67.72 68.69 68.73 | 0.00 0.97 1.01 |
where '[V1]'-'[V16]' denote the learnable tokens which are jointly trained during fine-tuning. As Table 2 shows, on GQA dataset, our proposed declaration-based prompt is more effective than manually designed templates (i.e., Fixed and Dynamic). For example, DPT with MLM task (row 5) surpasses the Fixed and Dynamic with 1.83% and 0.62%, respectively. Equipped with both MLM and ITM tasks, our full model (row 6) surpasses Baseline by 2.87%. To measure the confidence of the results, we have performed additional 3 runs for our best-performing model on GQA and VQA v2.0 datasets, getting standard deviations of 0.10% and 0.06%, respectively.
Generalizability over different datasets. Table 2 shows the ablation results on VQA v2.0 with respect to different prompts. Consistent with the results on GQA, our proposed DPT surpasses the fine-tuning using fixed templates, i.e., Fixed or Dynamic. Specifically, our model with DPT outperforms Baseline by 0.45%. The difference in accuracy gain between GQA and VQA (2.87% vs. 0.45%) is mainly due to the question complexity and the quality of the generated declaration sentences (refer to Appendix for details).
Generalizability over different VL models. To illustrate the generalizability of our proposed method over different pre-trained VL models, we apply our DPT to the recently proposed VL models that have been pre-trained via MLM and ITM tasks, e.g., UNITER [Chen et al., 2020] and ViLT [Kim et al., 2021]. As shown in Table 3, for all the three baselines, equipped with our DPT method, a consistent performance improvement (0.64% on average) can be observed. For example, ViLT+DPT and UNITER+DPT achieve absolute performance gains of 0.46% and 1.01% compared with the fine-tuning counterparts, respectively.
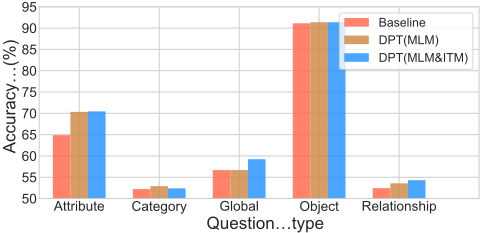
Accuracy over different question types. Figure 3 shows the accuracy breakdown on different question semantic types. It can be observed that the adapted MLM task achieves large accuracy improvement in attribute questions against Baseline (70.46% vs. 64.87%). This shows the strength of declarationbased prompt in capturing the object attributes. Moreover, the adapted ITM task brings more performance improvement in global questions (59.24% vs. 56.69%), indicating its superior ability in the understanding of global semantics.
4.4 Zero-shot and Few-shot Results
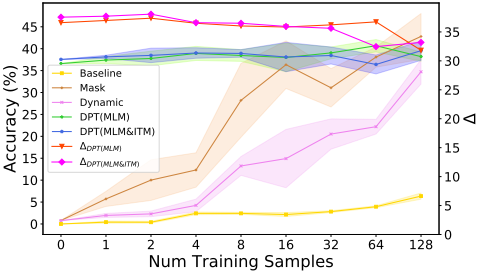
Figure 4 shows the accuracy in zero-shot and few-shot settings on GQA dataset. We remove yes/no questions in the sampled splits in advance since the large proportion of yes/no questions (18.81% and 17.47% questions have yes and no answers, respectively) will cause large variance (∼8%) in Baseline evaluation. As shown in Figure 4, it can be observed that DPT outperforms the vanilla fine-tuning counterparts and other prompt variants (i.e., Mask and Dynamic) by a significant margin. For example, with no samples for training, our DPT achieves a strong accuracy of 36.6% while the fine-tuning counterpart can not predict correct answers due to random guessing. When provided 1∼128 samples, our DPT method achieves 31.8%∼37.4% absolute accuracy improvement compared to Baseline.
4.5 Case Study
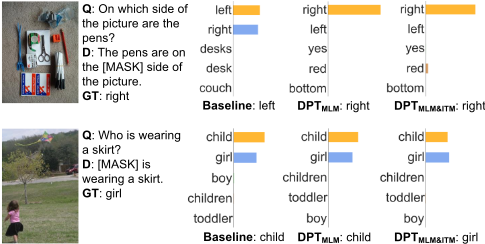
In Figure 5, we visualize two successful cases from our proposed DPT method. Regarding the first case, the baseline yields almost the same probabilities for 'left' and 'right', indicates its weakness in solving such direction-related questions. In contrast, equipped with the ability of masked language model, our DPT confidently predicts the correct answer 'right'. As for the second case, the baseline model and DPTMLM both wrongly predict the answer 'child' mainly attribute to 'child' being a more frequent object that occurs in the train set. Besides, 'child' is a hypernym of 'girl' and 'boy', making it a universal answer to many questions. On the contrary, DPT with the adapted ITM task takes account of the semantics of answers, and gives a higher score to the answer 'girl', leading to the correct answer.
5 Conclusion
We propose to reformulate the VQA task into masked language model (MLM) and image-text matching (ITM) problems, maximally mitigating the gap between vision-language (VL) pre-training and fine-tuning stages. To achieve this, we first convert questions into declarative sentences with reserved [MASK] or candidate answers, mitigating the discrepancies regarding the textual input. Then, VQA problem is reformulated into pre-training format via task adaptation, which solves VQA in the manner of MLM and ITM tasks. Extensive experiments on two benchmarks validate the effectiveness and generalizability of our proposed DPT paradigm over different pre-trained VL models in both fully-supervised and zero-shot/few-shot settings.
Acknowledgements
This work was supported in part by the National Natural Science Foundation of China under Grant No.61602197, Grant No.L1924068, Grant No.61772076, in part by CCF-AFSG Research Fund under Grant No.RF20210005, in part by the fund of Joint Laboratory of HUST and Pingan Property & Casualty Research (HPL), and in part by the National Research Foundation (NRF) of Singapore under its AI Singapore Programme (AISG Award No: AISG-GC-2019-003). Any opinions, findings and conclusions or recommendations expressed in this material are those of the authors and do not reflect the views of National Research Foundation, Singapore. The authors would also like to thank the anonymous reviewers for their comments on improving the quality of this paper.
@inproceedings{ijcai2022p453,
  title     = {Declaration-based Prompt Tuning for Visual Question Answering},
  author    = {Liu, Yuhang and Wei, Wei and Peng, Daowan and Zhu, Feida},
  booktitle = {Proceedings of the Thirty-First International Joint Conference on
               Artificial Intelligence, {IJCAI-22}},
  publisher = {International Joint Conferences on Artificial Intelligence Organization},
  editor    = {Luc De Raedt},
  pages     = {3264--3270},
  year      = {2022},
  month     = {7},
  note      = {Main Track},
  doi       = {10.24963/ijcai.2022/453},
  url       = {https://doi.org/10.24963/ijcai.2022/453},
}
TY - CPAPER TI - Declaration-based Prompt Tuning for Visual Question Answering AU - Liu, Yuhang AU - Wei, Wei AU - Peng, Daowan AU - Zhu, Feida T2 - Proceedings of the Thirty-First International Joint Conference on Artificial Intelligence, IJCAI-22 PB - International Joint Conferences on Artificial Intelligence Organization PY - 2022 SP - 3264 EP - 3270 DO - 10.24963/ijcai.2022/453 UR - https://doi.org/10.24963/ijcai.2022/453 ER -Copied
Machine-readable versions of this paper, for tools and AI agents:





