
Motion Planning Under Uncertainty with Complex Agents and Environments via Hybrid Search (Extended Abstract)
Proceedings of the Thirty-Second International Joint Conference on Artificial Intelligence. Journal Track. Pages 6969-6973.
https://doi.org/10.24963/ijcai.2023/792
Keywords
- Planning and Scheduling: PS: Robot planning
- Robotics: ROB: Motion and path planning
- Planning and Scheduling: PS: Planning under uncertainty
Abstract
As autonomous systems tackle more real-world situations, mission success oftentimes cannot be guaranteed and the planner must reason about the probability of failure. Unfortunately, computing a trajectory that satisfies mission goals while constraining the probability of failure is difficult because of the need to reason about complex, multidimensional probability distributions. Recent methods have seen success using chance-constrained, model-based planning. We argue there are two main drawbacks to these approaches. First, current methods suffer from an inability to deal with expressive environment models such as 3D non-convex obstacles. Second, most planners rely on considerable simplifications when computing trajectory risk including approximating the agent's dynamics, geometry, and uncertainty. We apply hybrid search to the risk-bound, goal-directed planning problem. The hybrid search consists of a region planner and a trajectory planner. The region planner makes discrete choices by reasoning about geometric regions that the agent should visit in order to accomplish its mission. In formulating the region planner, we propose landmark regions that help produce obstacle-free paths. The region planner passes paths through the environment to a trajectory planner; the task of the trajectory planner is to optimize trajectories that respect the agent's dynamics and the user's desired risk of mission failure. We discuss three approaches to modeling trajectory risk: a CDF-based approach, a sampling-based collocation method, and an algorithm named Shooting Method Monte Carlo. A variety of 2D and 3D test cases are presented in the full paper including a linear case, a Dubins car model, and an underwater autonomous vehicle. The method is shown to outperform other methods in terms of speed and utility of the solution. Additionally, the models of trajectory risk are shown to better approximate risk in simulation.
- [Blackmore et al., 2011] Lars Blackmore, Masahiro Ono, and Brian C. Williams. Chance-constrained optimal path planning with obstacles. IEEE Trans. Robotics, 27(6):1080-1094, 2011.
- [Deits and Tedrake, 2015] Robin Deits and Russ Tedrake. Computing Large Convex Regions of Obstacle-Free Space Through Semidefinite Programming, pages 109-124. Springer International Publishing, Cham, 2015.
- [Faust et al., 2018] Aleksandra Faust, Oscar Ramirez, Marek Fiser, Ken Oslund, Anthony Francis, James Davidson, and Lydia Tapia. PRM-RL: Long-range robotic navigation tasks by combining reinforcement learning and sampling- based planning. In 2018 IEEE International Conference on Robotics and Automation, ICRA 2018, Brisbane, pages 5113-5120, Brisbane, Australia, 2018.
- [Fernandez-Gonzalez et al., 2018] Enrique Fernandez- Gonzalez, Brian C. Williams, and Erez Karpas. Scotty- Activity: Mixed Discrete-Continuous Planning with Convex Optimization. Journal of Artificial Intelligence Resesearch (JAIR), 62:579-664, 2018.
- [Luders et al., 2010] Brandon Luders, Mangal Kothari, and Jonathan P. How. Chance-constrained RRT for proba- bilistic robustness to environmental uncertainty. In AIAA Guidance, Navigation, and Control Conference (GNC), Toronto, Canada, August 2010.
- [Ono et al., 2013] Masahiro Ono, Brian C. Williams, and Lars Blackmore. Probabilistic Planning for Continuous Dynamic Systems under Bounded Risk. Journal of Artifi- cial Intelligence Research (JAIR), 46:511-577, 2013.
- [Patil et al., 2012] Sachin Patil, Jur van den Berg, and Ron Alterovitz. Estimating probability of collision for safe mo- tion planning under Gaussian motion and sensing uncer- tainty. In IEEE International Conference on Robotics and Automation, ICRA 2012, St.
- Paul, Minnesota, USA, 2012.
- [Strawser and Williams, 2022] Daniel Strawser and Brian C. Williams. Motion Planning Under Uncertainty with Com- plex Agents and Environments via Hybrid Search. Journal of Artificial Intelligence Research (JAIR), 75:1-81, 2022.
References were extracted automatically from the PDF and may contain errors.
Full text extracted automatically from the PDF; figures, tables and equations may differ. The PDF is the version of record.
1 Introduction
As they become more commonplace, autonomous systems must deal with increasingly uncertain surroundings. Autonomous cars quickly make decisions while navigating dynamic urban settings. Similarly, autonomous underwater vehicles accomplish a range of scientific and exploratory tasks while dealing with stochastic ocean currents.
Such widespread applicability has inspired a vast amount of prior work into motion planning under uncertainty. A common method of approximating trajectory risk is to assume a state distribution for which there is a quick-to-evaluate cumulative distribution function (CDF), such as the Gaussian distribution. In one such approach the authors combine a disjunctive program with a CDF-based evaluation of trajectory risk [Blackmore et al., 2011]. Chance-constrained RRT proposes an extension of the popular rapidly-exploring random tree (RRT) algorithm [Luders et al., 2010]. Probabilistic constraints are added to the basic RRT formulation; the path must avoid collisions with a predetermined probability. Another approach does not directly assume Gaussian uncertainty but models the state distribution of an agent that collides with an obstacle as a truncated Gaussian [Patil et al., 2012].
Hybrid search has seen promise solving problems with discrete and continuous decision variables. ScottyActivity combines activity and trajectory planning over long horizons [Fernandez-Gonzalez et al., 2018]. The Scotty planner decomposes the workspace into convex subregions and performs graph search over the subregions. Another example of hybrid search is the pSulu planner [Ono et al., 2013]. pSulu solves a Chance-Constrained Qualitative State Plan (CCQSP) using branch and bound and convex optimization. Learning has seen success in a hybrid approach to motion planning. In one instance, a probabilistic roadmap (PRM) planner is combined with reinforcement learning to generate long trajectories for nonlinear systems [Faust et al., 2018]. Our work builds on these and relies on hybrid search for more sophisticated models of risk than previous approaches.
1.1 Problem Statement
We consider the problem of an agent navigating from an initial state I to a sequence of goal states G while avoiding obstacles with probability 1 - ϵ. The purpose of the algorithm is to output an open loop control trajectory u. The control outputs u represent inputs to the agent's actuators. The navigation problem can be framed as the optimal control problem:
Constraint (3) is important to this work; it models the probability that the trajectory is in the free region of the workspace, Wfree, and is termed the chance constraint.
We solve the risk-bound motion planning problem using hybrid search. The search consists of a region planner and a trajectory planner. The region planner passes candidate paths to the trajectory planner; the trajectory planner then optimizes a trajectory constrained to a specific path and determines if the chance constraint can be satisfied. The components are introduced in the following sections.
2 The Region Planner
The purpose of the region planner is to determine an appropriate set of active geometric constraints that allow the agent to accomplish its mission. To do this, the region planner reasons about geometric regions of the agent workspace, termed regions. The regions are used to model obstacle-avoidance constraints, goal constraints, and other geometric constraints on the agent's trajectory. The region planner connects sequences of regions into paths. Each path can be compiled into a set of constraints on the agent's continuous state trajectory.
The region planner receives as inputs an agent and a sequence of goals that the agent must accomplish. The output of the region planner is an ordered set of regions, a path, that represents a sequence of geometric constraints on the agent's position. This path is then passed to the trajectory planner.
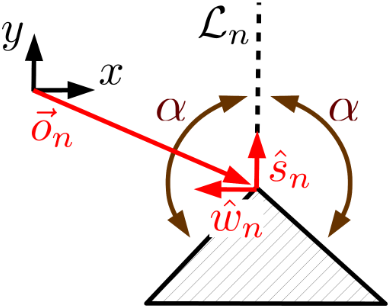
Figure 2: The ray that represents a landmark region Ln for a 2D workspace
2.1 Landmark Regions
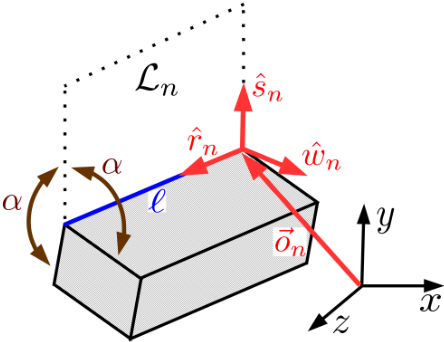
Our work proposes landmark regions to model obstacleavoidance constraints and facilitate modeling the collision probability. Geometrically, landmark regions are bounded hyperplanes. In three dimensions, this hyperplane is a bounded plane and in two dimensions, the constraint is a ray. The plane is bounded because it is bordered by a line ℓn incident to an obstacle sub-facet. For each sub-facet S in an environment, there is a corresponding implied landmark constraint L. The geometry is illustrated in Figs. 1 and 2. The bounded hyperplane extends upwards and in all directions from the blue line in Fig. 1. The hyperplane's orientation divides the angle between the two neighboring obstacle facets. If the angle between the facets is 2α (measured on the side of the obstacle surface with outward pointing normal vectors), then the hyperplane is positioned α from each neighboring facet.
An advantage of using a hyperplane is that it is straightforward to generate convex constraints that force the trajectory to pass through each landmark region. Additionally, landmark regions are implicitly defined for any polytope surface and do not require additional calculation such as other convex decomposition methods [Deits and Tedrake, 2015].
2.2 First Feasible Hybrid Search
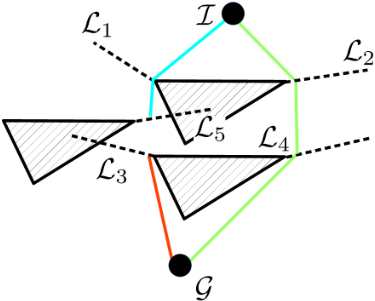
First Feasible Hybrid Search (FFHS) specifies how the region planner determines which paths to pass to the trajectory planner. It has the objective of generating good, feasible paths quickly in complex environments. Because trajectory optimization calls are expensive, the search seeks to minimize them. To do this, FFHS only passes mission complete paths to the trajectory planner where mission complete paths are paths that include all goals in G. This idea is illustrated in Fig. 3. The green path includes I and G; its implied constraints are passed to the trajectory planner for trajectory optimization. The cyan and red path violated the chance constraint and is separated into prefix and suffix paths.
3 The Trajectory Planner
The task of the trajectory planner is to optimize a trajectory that respects the path's implied geometric constraints as well as other constraints such as the agent's dynamics. Importantly, the trajectory planner models trajectory risk, Constraint (3). It uses techniques from trajectory optimization and off-the-shelf optimization libraries.
The trajectory planner receives as inputs a sequence of region constraints from the region planner. It requires a model of the agent's dynamics and a predetermined bound on mission failure, i.e. the chance constraint. The full article details three models of trajectory risk, which we briefly summarize here.
3.1 CDF-Based Chance Constraints
The chance constraint models the probability that the trajectory fails in execution. The constraint is difficult to compute because it involves the integration of a probability distribution over many dimensions as the state evolves in time. Our first and simplest model of risk involves CDF-based chance constraints. This simplification is appropriate to agents with linear dynamics whose geometry is unimportant when computing collision risk, i.e. point robots. First, an independence assumption is used to simplify the joint chance constraint, Constraint (3), into a product of probabilities:
Each term on the right-hand side of Eq. (6) models the probability of success at a specific point in time. Mathematically, it is given by the integral:
where f (xn) is a distribution of the agent's state at region n and ℓ represents the limits of integration. In general, Eq. (7) must be computed using numerical methods; however, the central assumption of this section is that we have access to a subroutine that can quickly evaluate the integral. What must be specified are the limits of integration ℓ.
An advantage of Section 2.1's landmark regions is that they form not only constraints on the trajectory but also enable a geometric simplification when computing CDF-based chance constraints. Instead of calculating the integral with respect to the non-convex space, it is simplified by projecting the distribution onto the landmark region. For example, in Fig. 1, state uncertainty is projected onto Ln and the resulting bivariate distribution integrated from coordinate ˆ sn = 0 to ∞. For a complete description of the calculation, the reader is referred to the full article [Strawser and Williams, 2022].
3.2 Approximating Trajectory Risk via Intersecting Region
The downside of CDF-based chance constraints is they require modeling uncertainty with a distribution for which there is an easily-evaluated CDF. Our second method approximates risk via samples drawn from the nominal trajectory. If Wobs represents the workspace occupied by the obstacles, let Wint,s be the intersecting region between the agent's body, Wk,s, and obstacles summed over the entire trajectory scenario s. Specifically:
To model the collision probability, an indicator variable is set to one if the intersecting region is greater than zero, and zero otherwise:
where |Wint,s| is the size of the intersecting region of scenario s and S is the total number of scenarios. The Jacobian of the indicator function is a Dirac delta function; Eq. (9) has a non-zero gradient only at the point of collision between the agent and the obstacle. This provides the trajectory optimizer with little information about how to satisfy the constraint and would likely prevent it from succeeding. Instead, the paper approximates the indicator variable through a sigmoid function. The overall chance constraint is then written:
where α controls the sigmoid's steepness, i.e. how well it approximates the indicator function. An advantage of the sigmoid function is that it is straightforward to differentiate when computing the Jacobian matrix. Specifically,
The chain rule is used to derive the gradients with respect to the decision variables. The Jacobian of the chance constraint Ccc with respect to a decision variable state xn is:
| FFHS | Lawnmower Pattern (Trajectory Cost) 924 | Lawnmower Pattern (Time) 556 |
|---|---|---|
| CC-RRT | 50,750 | 992 |
| CC-RRT-Connect | 5,306 | 754 |
| Interleaved | Timeout | Timeout |
Computing gradient ∂Wint ∂xn is possible through the use of vector calculus and considering the flux of incremental area (or volume) entering or leaving Wint due to an incremental change in one of the states. The journal paper details this calculation more fully.
3.3 ShootingMethodMonte Carlo
The previous section's sampling-based chance constraint has the drawback that it requires a nominal trajectory fromwhich to draw samples. Stochastic systems do not have a deterministic nominal trajectory. In this section, we propose a method that computes the joint chance constraint by forward simulating realizations of entire trajectories. We then determine which scenarios fail and use this information to compute the overall trajectory risk. To do this, we incorporate a shooting method trajectory optimization. In the deterministic case, the shooting method works by forward simulating a trajectory and updating the control inputs until the final simulated state matches the goal state. The insight underlying this section is that the shooting method of trajectory optimization is similar to a single Monte Carlo simulation of a stochastic process. We combine the two strategies into the Shooting Method Monte Carlo (SMMC) algorithm.
The vanilla deterministic shooting method first simulates the agent's dynamics. Given the results of the simulations, a defect di is calculated for each constraint Ci. The defect is measured as:
where Ci is the desired value of constraint i, and Ci (u, h) is the value of the constraint resulting from simulating the dynamics using decision variables (u, h). The task of the trajectory optimization routine is to reduce defects to some small tolerance.
Shooting Method Monte Carlo differs from the traditional shooting method by first sampling from the underlying stochastic process's distribution. The trajectory is then simulated S times and there is no single Ci (u, h). Instead, SMMC approximates the expected value of each constraint Ci that results from simulating the trajectory with respect to decision variables (u, h) and samples Zs. SMMC's defect is expressed as:
where ˆ f is the trajectory's simulated empirical distribution. The expected value in Eq. (14) is:
Approximating the objective function follows a similar scheme. Its value is computed for each scenario, Js, and the expected cost is approximated as:
Given the sampled trajectory, the chance constraint is computed via (10). The chief difference between Shooting Method Monte Carlo and the second method described in Section 3.2 is that SMMC relies on sampled trajectories rather than a nominal trajectory. This allows it to better approximate the true underlying distribution.
4 Results
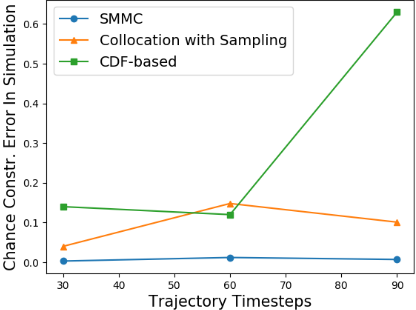
The paper includes a number of test cases. The first set of tests benchmark FFHS against other approaches on agents with linear dynamics and Gaussian uncertainty. One task requires an undersea glider to perform seafloor exploration via a lawnmower pattern. These results are depicted in Table 4; FFHS is able to outperform the other approaches by generating trajectories with lower cost in less time. We also benchmark the various chance constraint models against one another. CDF-based chance constraints are easiest to compute; however, they exhibit error if the dynamics are nonlinear and state distribution non-Gaussian. This is shown in Fig. 5 where SMMC more accurately approximates trajectory risk in simulation for a Dubins car. The reader is referred to the full paper for complete results and discussion.
Acknowledgments
This work was partially supported by the Exxon Mobil Corporation and the Toyota Motor Corporation. We would like to thank Richard Camilli for his invaluable advice regarding the undersea use case. We would also like to thank the members of the MIT MERS lab and in particular the Scouts Team for their support developing this work. Finally, the journal reviewers' feedback was essential to help focus the article
@inproceedings{ijcai2023p792,
  title     = {Motion Planning Under Uncertainty with Complex Agents and Environments via Hybrid Search (Extended Abstract)},
  author    = {Strawser, Daniel and Williams, Brian},
  booktitle = {Proceedings of the Thirty-Second International Joint Conference on
               Artificial Intelligence, {IJCAI-23}},
  publisher = {International Joint Conferences on Artificial Intelligence Organization},
  editor    = {Edith Elkind},
  pages     = {6969--6973},
  year      = {2023},
  month     = {8},
  note      = {Journal Track},
  doi       = {10.24963/ijcai.2023/792},
  url       = {https://doi.org/10.24963/ijcai.2023/792},
}
TY - CPAPER TI - Motion Planning Under Uncertainty with Complex Agents and Environments via Hybrid Search (Extended Abstract) AU - Strawser, Daniel AU - Williams, Brian T2 - Proceedings of the Thirty-Second International Joint Conference on Artificial Intelligence, IJCAI-23 PB - International Joint Conferences on Artificial Intelligence Organization PY - 2023 SP - 6969 EP - 6973 DO - 10.24963/ijcai.2023/792 UR - https://doi.org/10.24963/ijcai.2023/792 ER -Copied
Machine-readable versions of this paper, for tools and AI agents:





